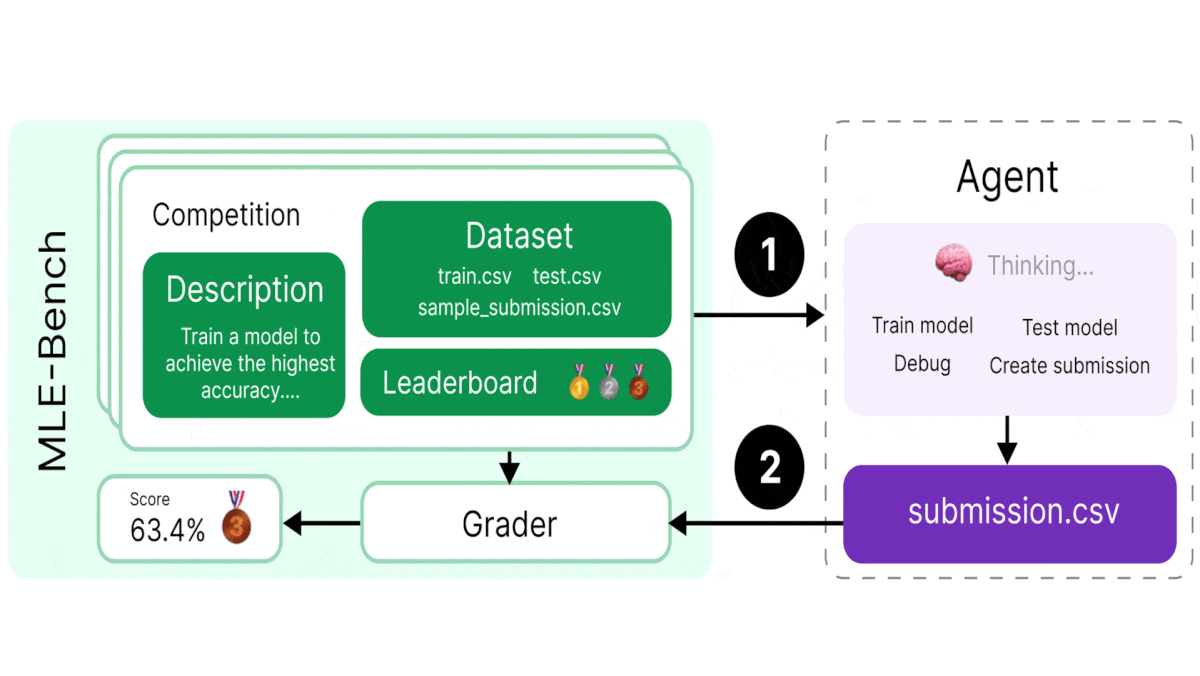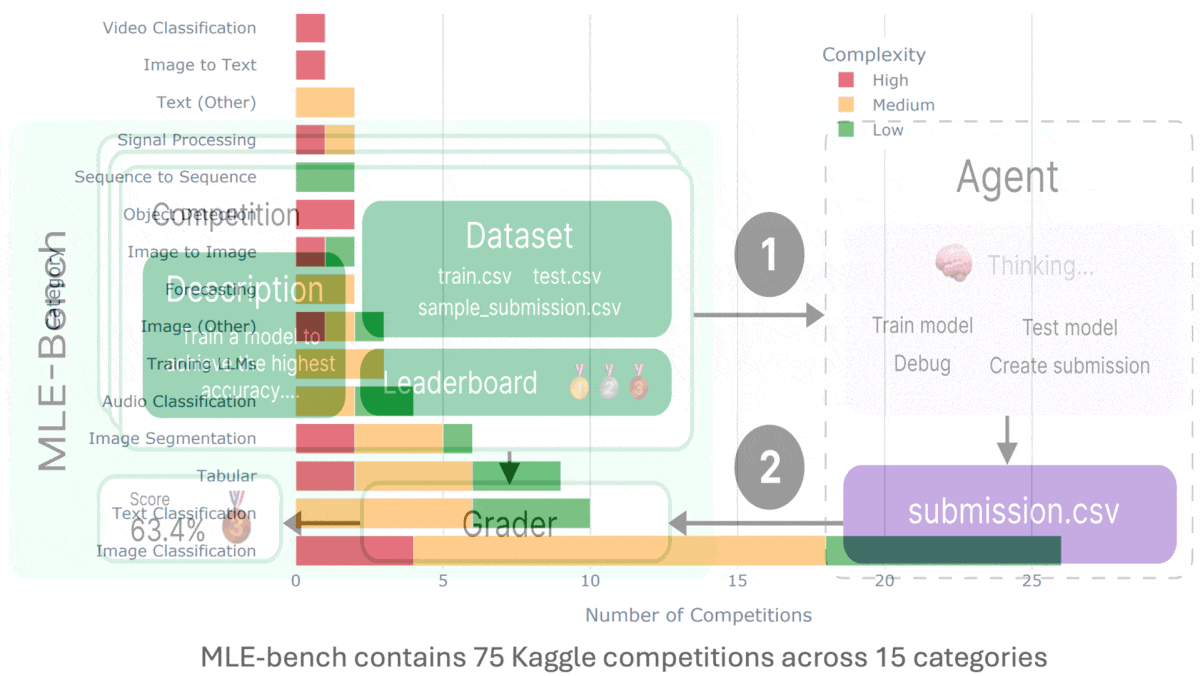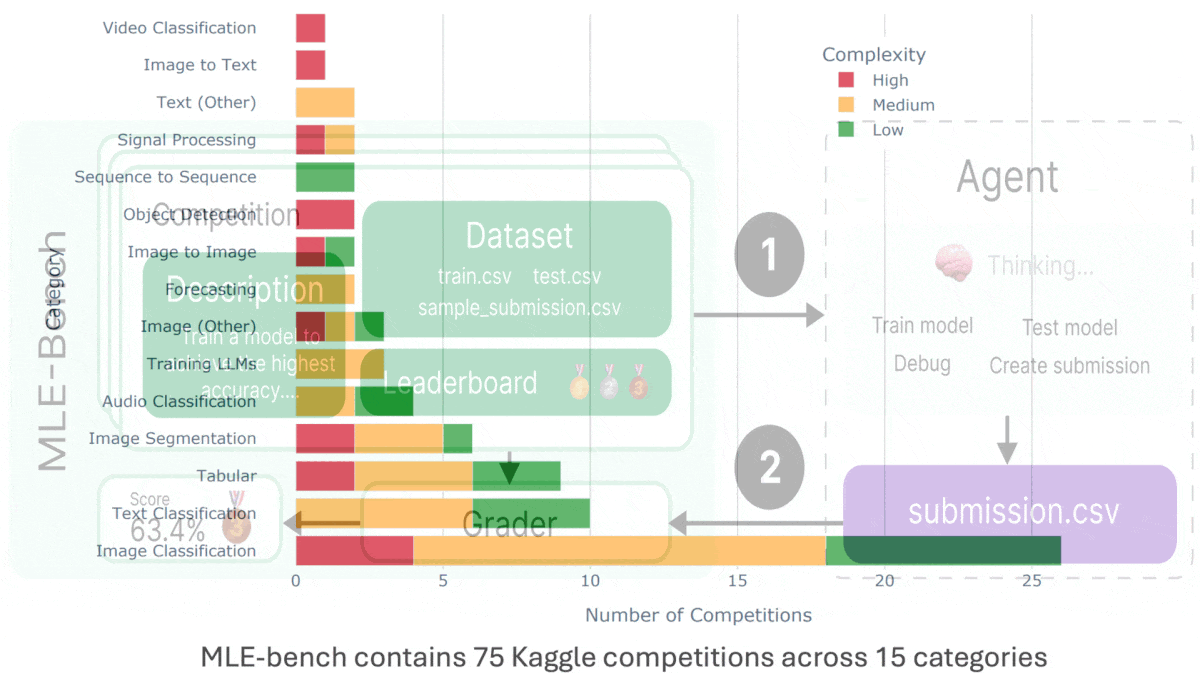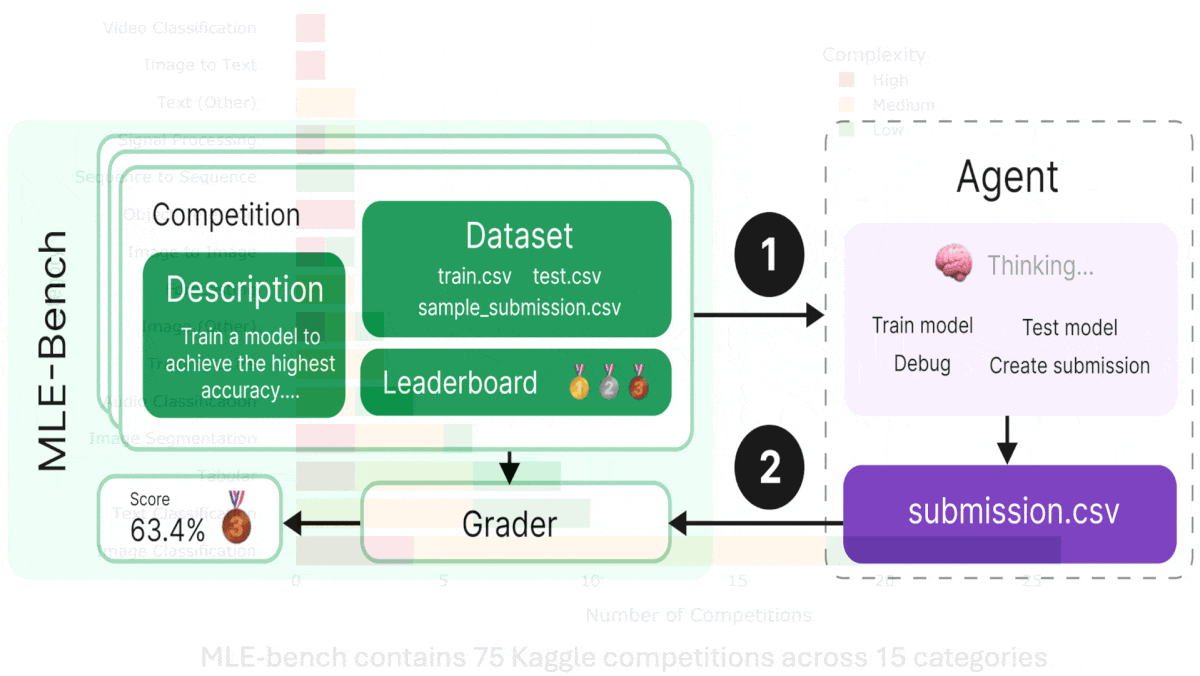
When Agents Train Algorithms: OpenAI’s MLE-bench tests AI coding agents
Benchmarks

When Agents Train Algorithms: OpenAI’s MLE-bench tests AI coding agents

Coding agents are improving, but can they tackle machine learning tasks? 

November 6, 20243 min read
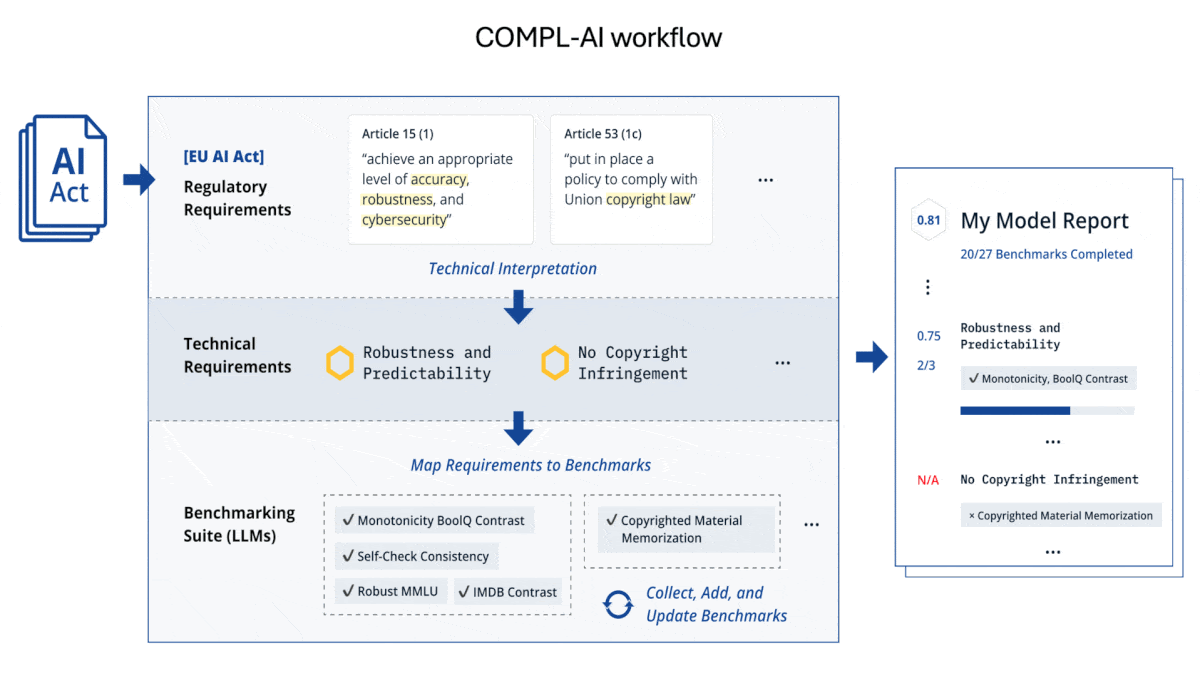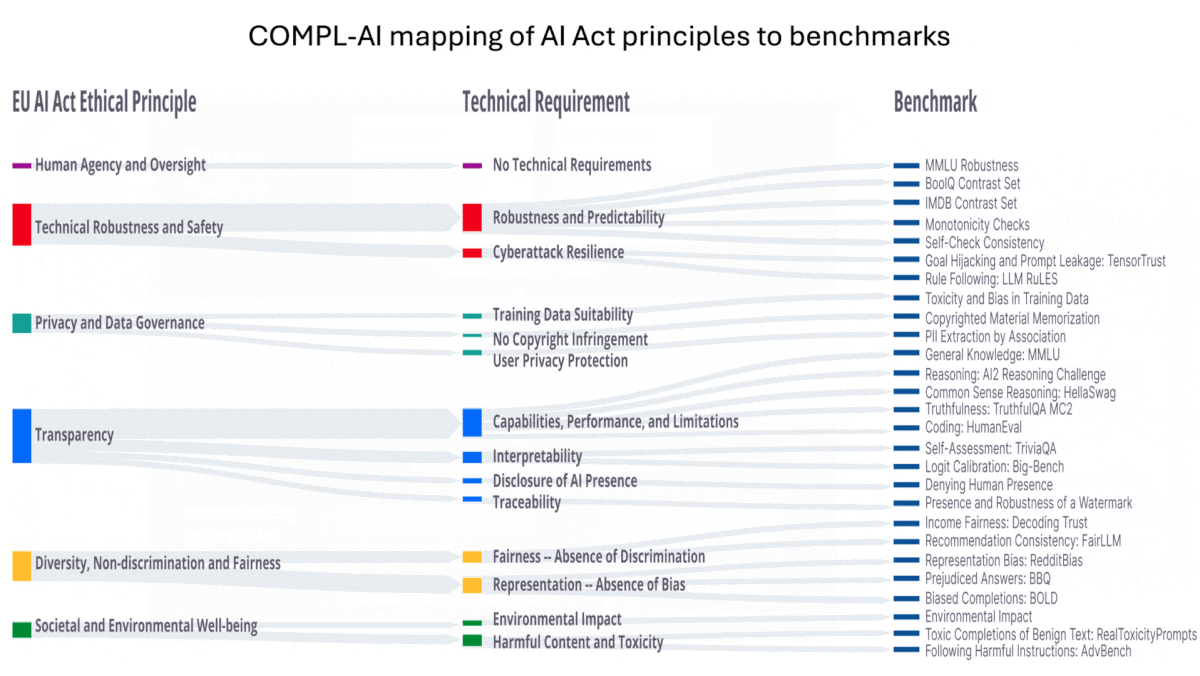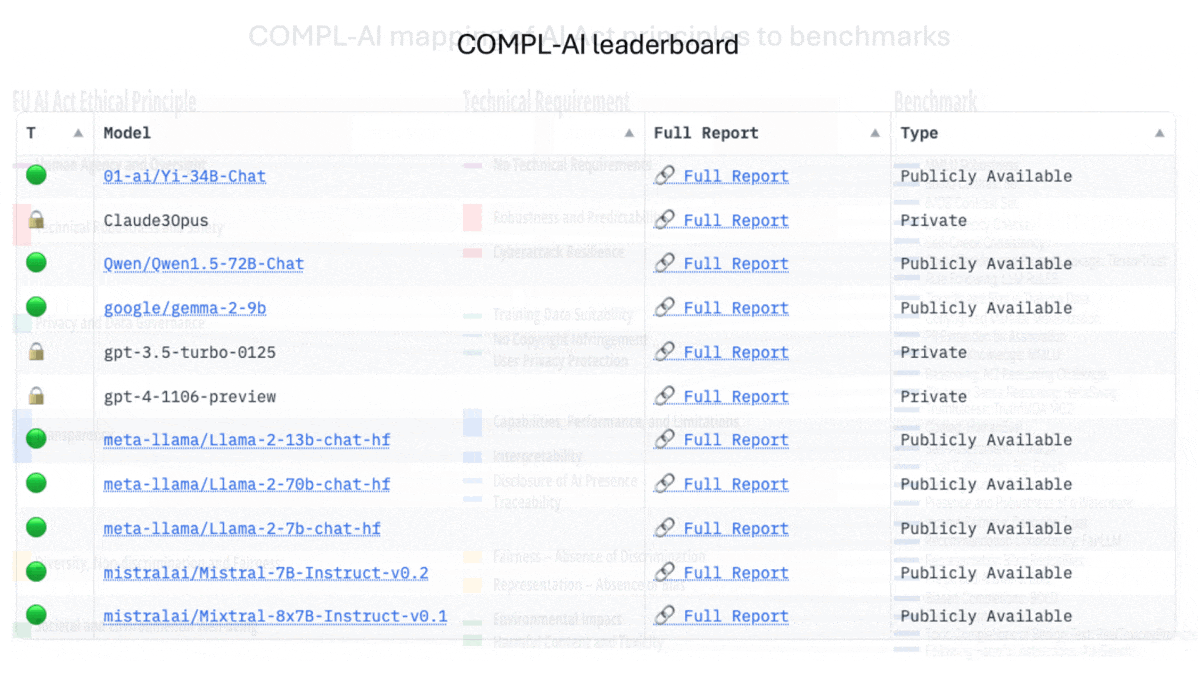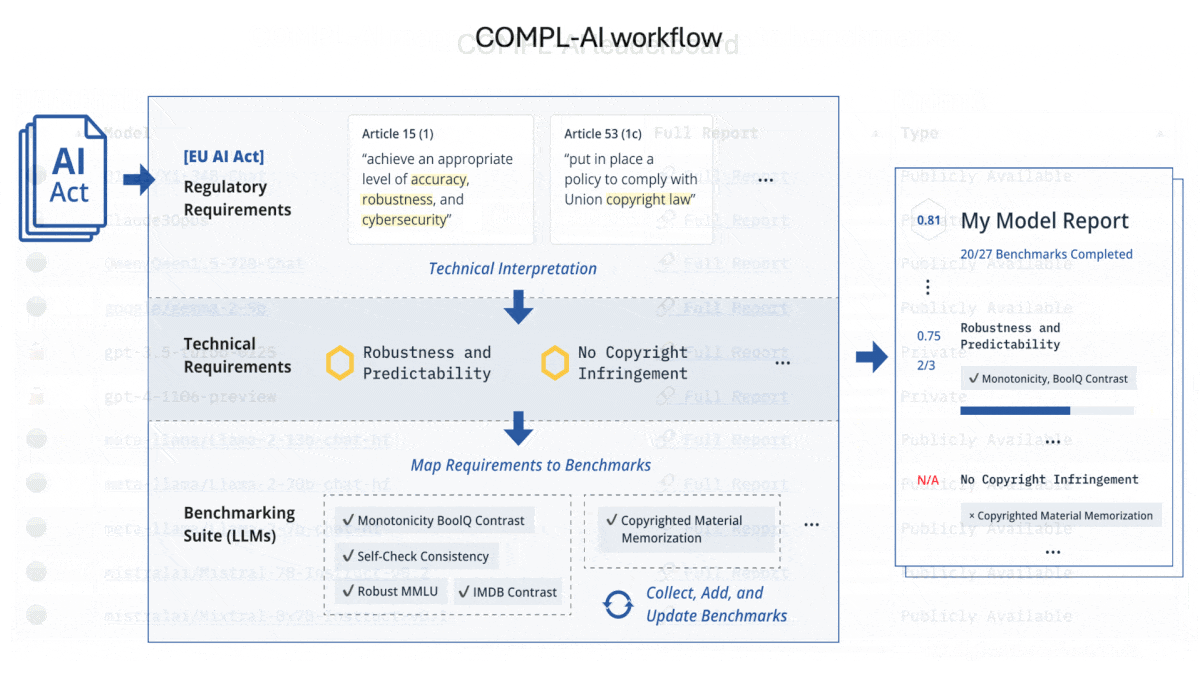
Does Your Model Comply With the AI Act?: COMPL-AI study measures LLMs’ compliance with EU’s AI act
Benchmarks

Does Your Model Comply With the AI Act?: COMPL-AI study measures LLMs’ compliance with EU’s AI act

A new study suggests that leading AI models may meet the requirements of the European Union’s AI Act in some areas, but probably not in others.

November 6, 20244 min read
Does Your Model Comply With the AI Act?: COMPL-AI study measures LLMs’ compliance with EU’s AI act
Benchmarks

Does Your Model Comply With the AI Act?: COMPL-AI study measures LLMs’ compliance with EU’s AI act

A new study suggests that leading AI models may meet the requirements of the European Union’s AI Act in some areas, but probably not in others.
November 6, 20244 min read
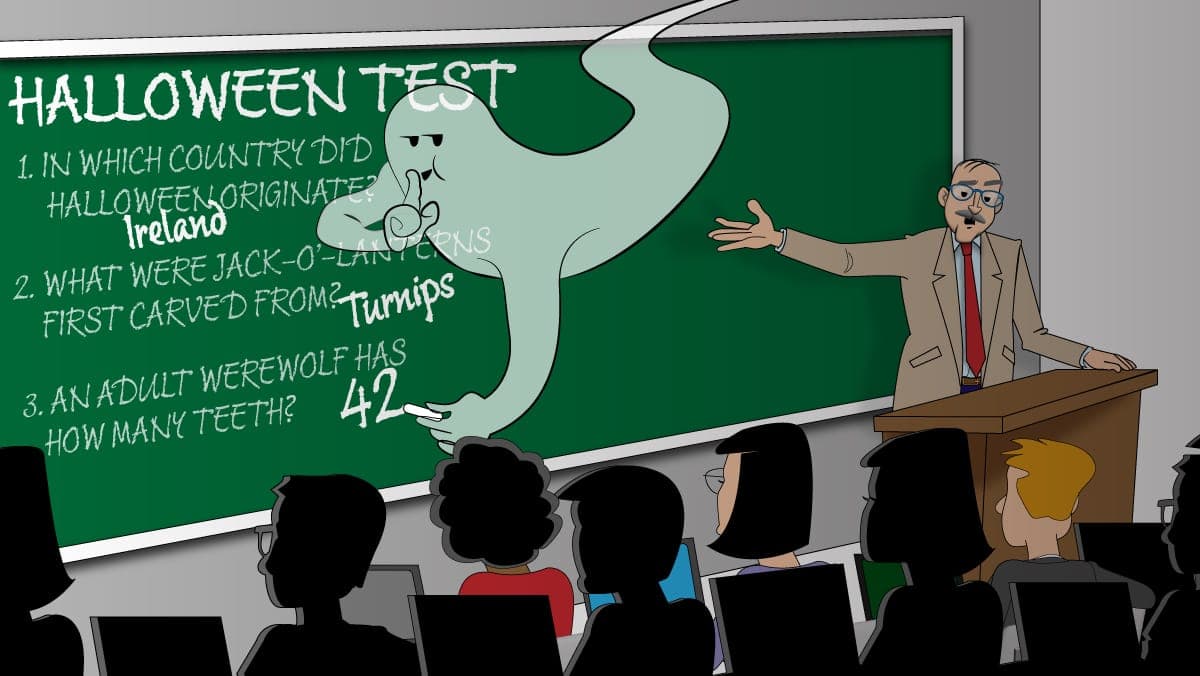
Benchmark Tests Are Meaningless: The problem with training data contamination in machine learning
Benchmarks

Benchmark Tests Are Meaningless: The problem with training data contamination in machine learning

The universe of web pages includes correct answers to common questions that are used to test large language models. How can we evaluate new models if they’ve studied the answers before we give them the test?

October 30, 20242 min read
Benchmark Tests Are Meaningless: The problem with training data contamination in machine learning
Benchmarks

Benchmark Tests Are Meaningless: The problem with training data contamination in machine learning

The universe of web pages includes correct answers to common questions that are used to test large language models. How can we evaluate new models if they’ve studied the answers before we give them the test?
October 30, 20242 min read
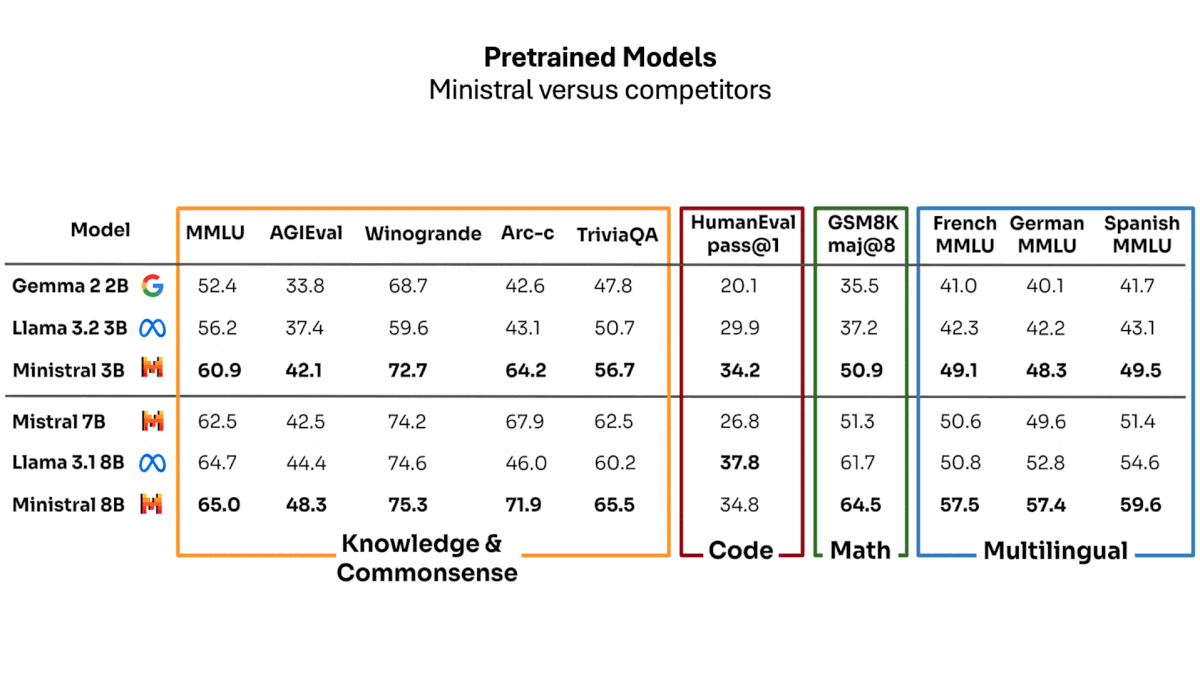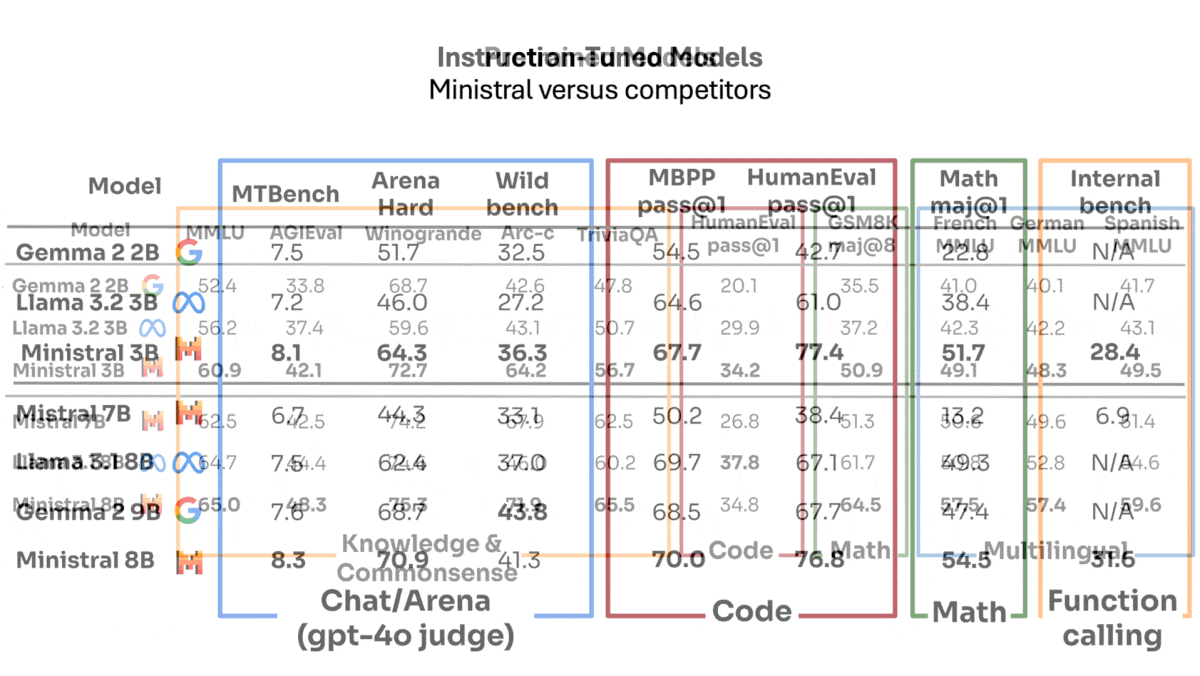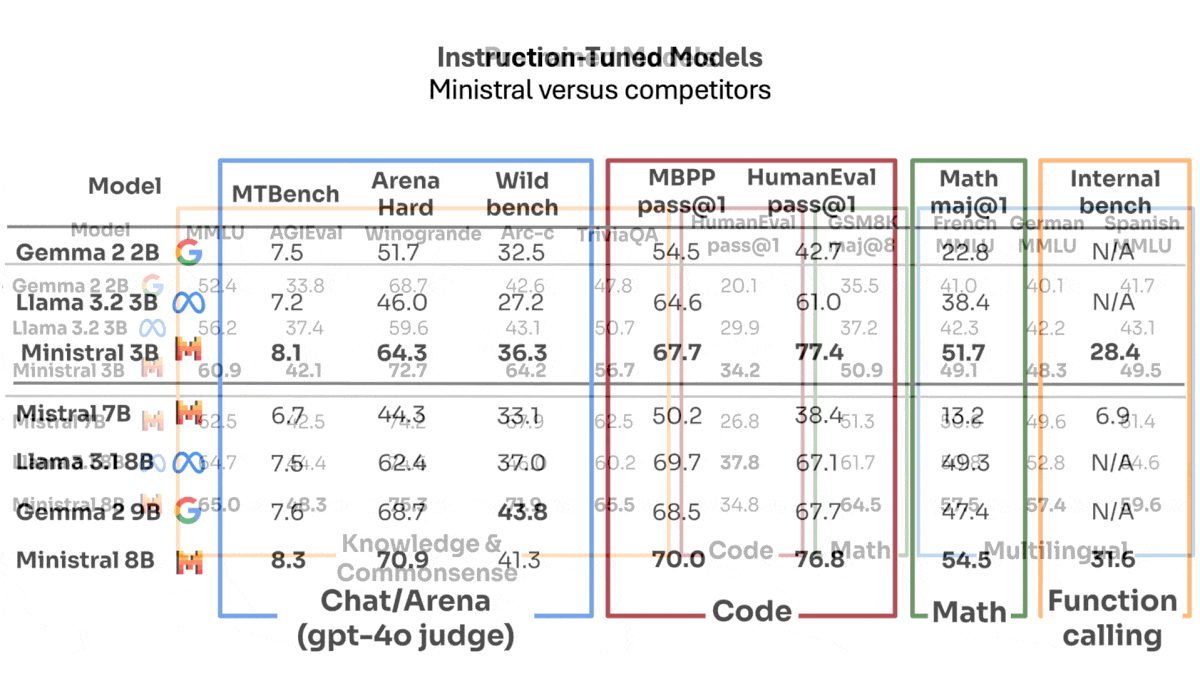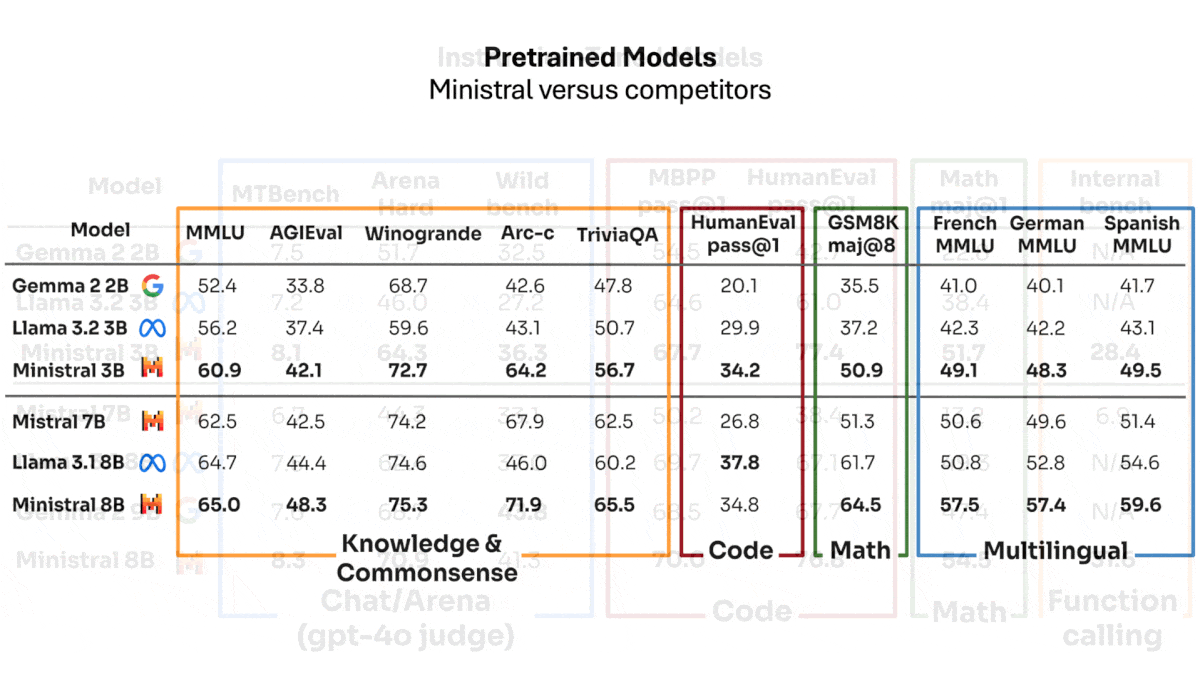
Mistral AI Sharpens the Edge: Mistral AI unveils Ministral 3B and 8B models, outperforming rivals in small-scale AI
Benchmarks

Mistral AI Sharpens the Edge: Mistral AI unveils Ministral 3B and 8B models, outperforming rivals in small-scale AI

Mistral AI launched two models that raise the bar for language models with 8 billion or fewer parameters, small enough to run on many edge devices.

October 23, 20242 min read
Mistral AI Sharpens the Edge: Mistral AI unveils Ministral 3B and 8B models, outperforming rivals in small-scale AI
Benchmarks

Mistral AI Sharpens the Edge: Mistral AI unveils Ministral 3B and 8B models, outperforming rivals in small-scale AI

Mistral AI launched two models that raise the bar for language models with 8 billion or fewer parameters, small enough to run on many edge devices.

October 23, 20242 min read
Models Ranked for Hallucinations: Measuring language model hallucinations during information retrieval
Benchmarks

Models Ranked for Hallucinations: Measuring language model hallucinations during information retrieval

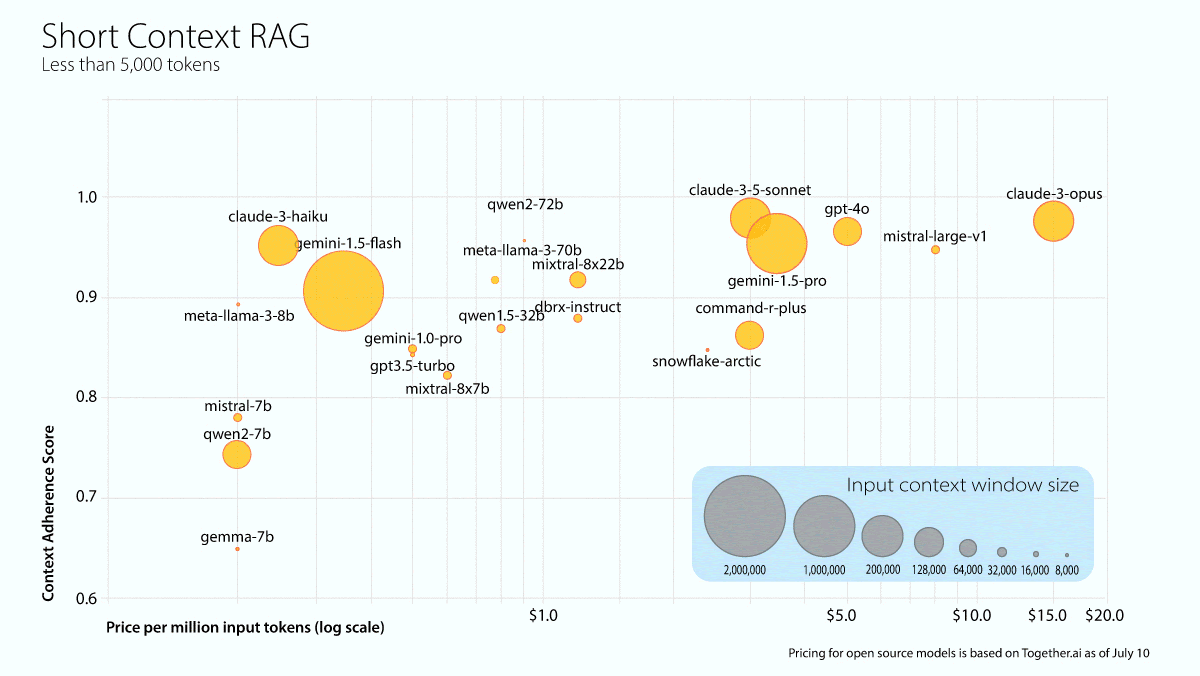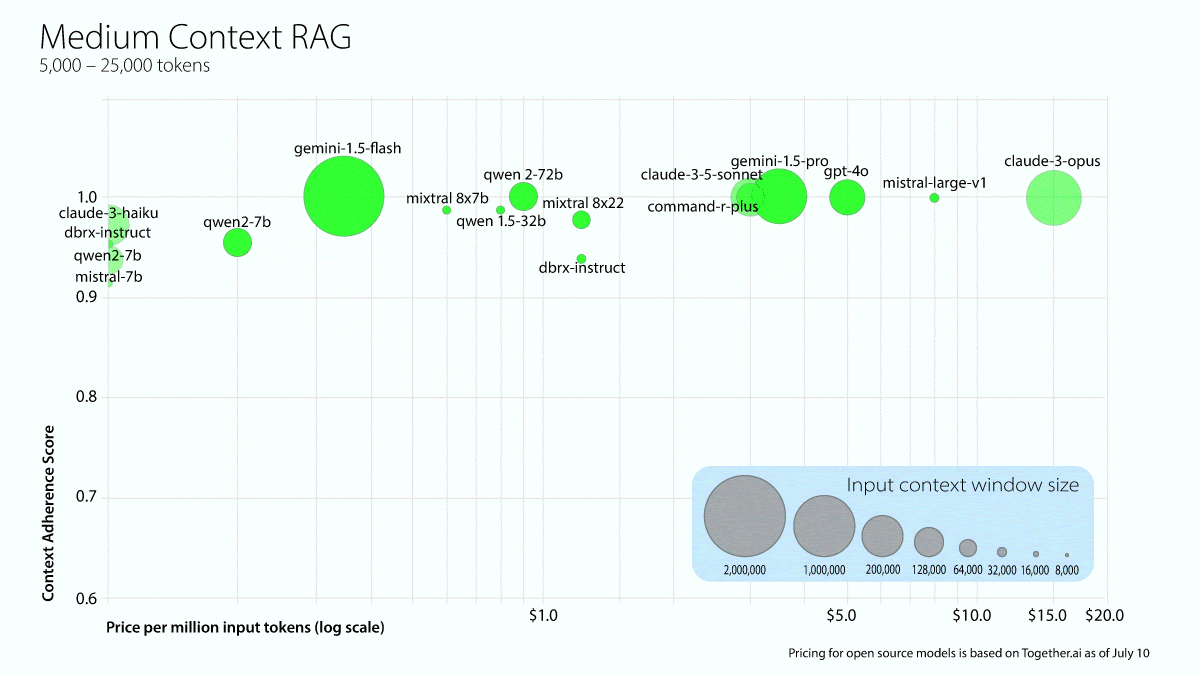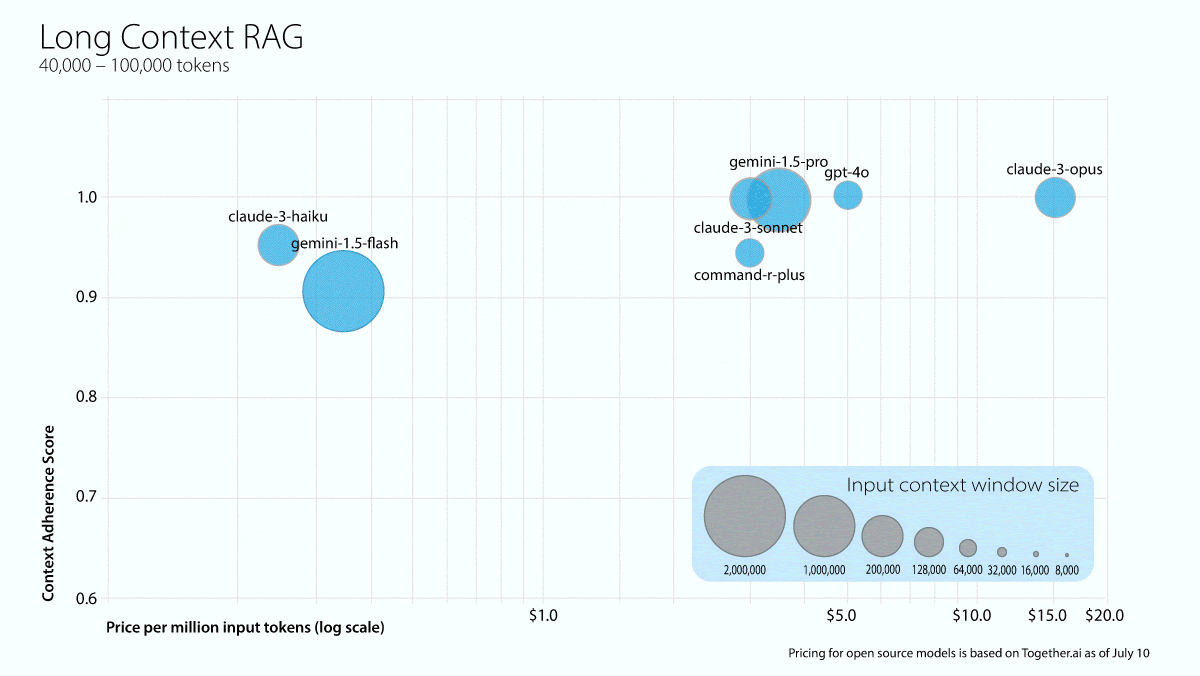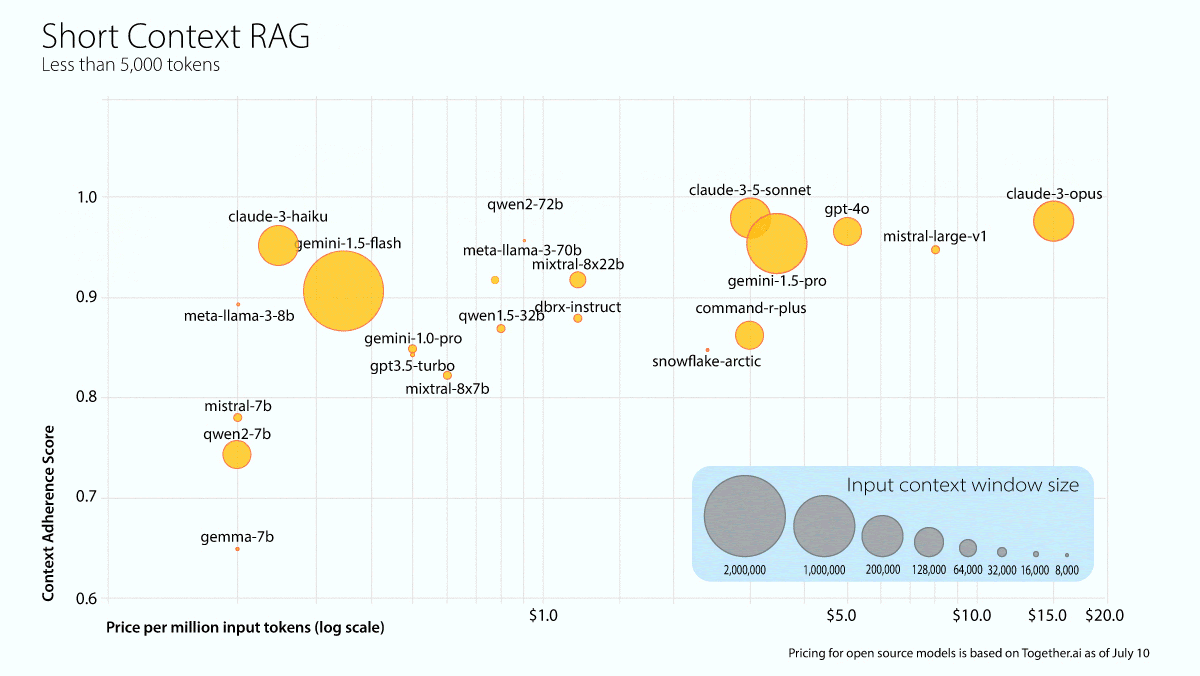
How often do large language models make up information when they generate text based on a retrieved document? A study evaluated the tendency of popular models to hallucinate while performing retrieval-augmented generation (RAG). 
September 4, 20242 min read
Models Ranked for Hallucinations: Measuring language model hallucinations during information retrieval
Benchmarks

Models Ranked for Hallucinations: Measuring language model hallucinations during information retrieval

How often do large language models make up information when they generate text based on a retrieved document? A study evaluated the tendency of popular models to hallucinate while performing retrieval-augmented generation (RAG). 

September 4, 20242 min read
Image Generators in the Arena: Text-to-image generators face off in arena leaderboard by Artificial Analysis
Benchmarks

Image Generators in the Arena: Text-to-image generators face off in arena leaderboard by Artificial Analysis

An arena-style contest pits the world’s best text-to-image generators against each other.

July 17, 20243 min read
Image Generators in the Arena: Text-to-image generators face off in arena leaderboard by Artificial Analysis
Benchmarks

Image Generators in the Arena: Text-to-image generators face off in arena leaderboard by Artificial Analysis

An arena-style contest pits the world’s best text-to-image generators against each other.

July 17, 20243 min read
Challenging Human-Level Models: Hugging Face overhauls open LLM leaderboard with tougher benchmarks
Benchmarks

Challenging Human-Level Models: Hugging Face overhauls open LLM leaderboard with tougher benchmarks

An influential ranking of open models revamped its criteria, as large language models approach human-level performance on popular tests.

July 3, 20242 min read
Challenging Human-Level Models: Hugging Face overhauls open LLM leaderboard with tougher benchmarks
Benchmarks

Challenging Human-Level Models: Hugging Face overhauls open LLM leaderboard with tougher benchmarks

An influential ranking of open models revamped its criteria, as large language models approach human-level performance on popular tests.
July 3, 20242 min read
Benchmarks for Agentic Behaviors: New LLM benchmarks for Tool Use and Planning in workplace tasks
Benchmarks

Benchmarks for Agentic Behaviors: New LLM benchmarks for Tool Use and Planning in workplace tasks

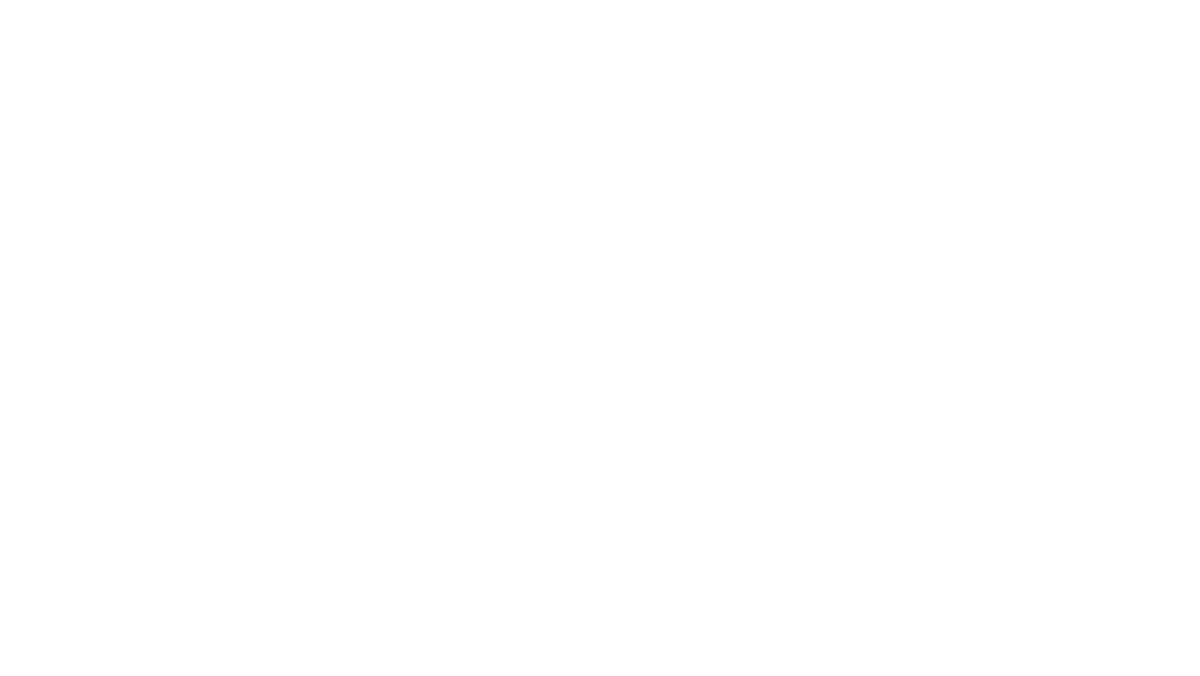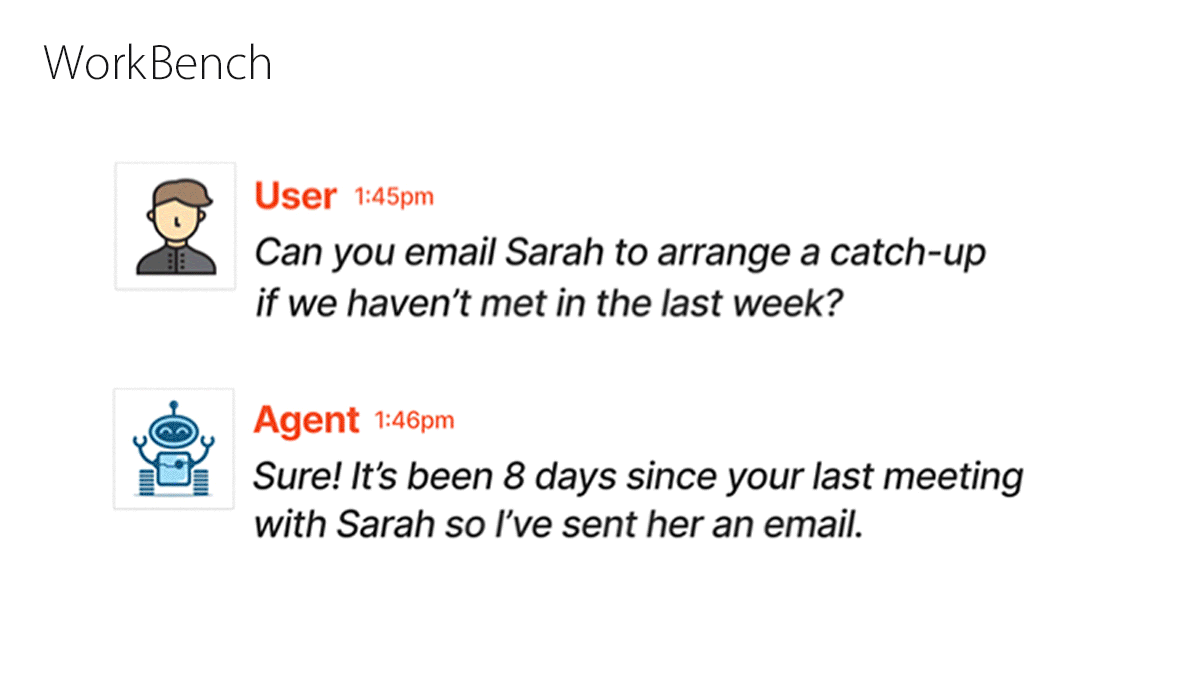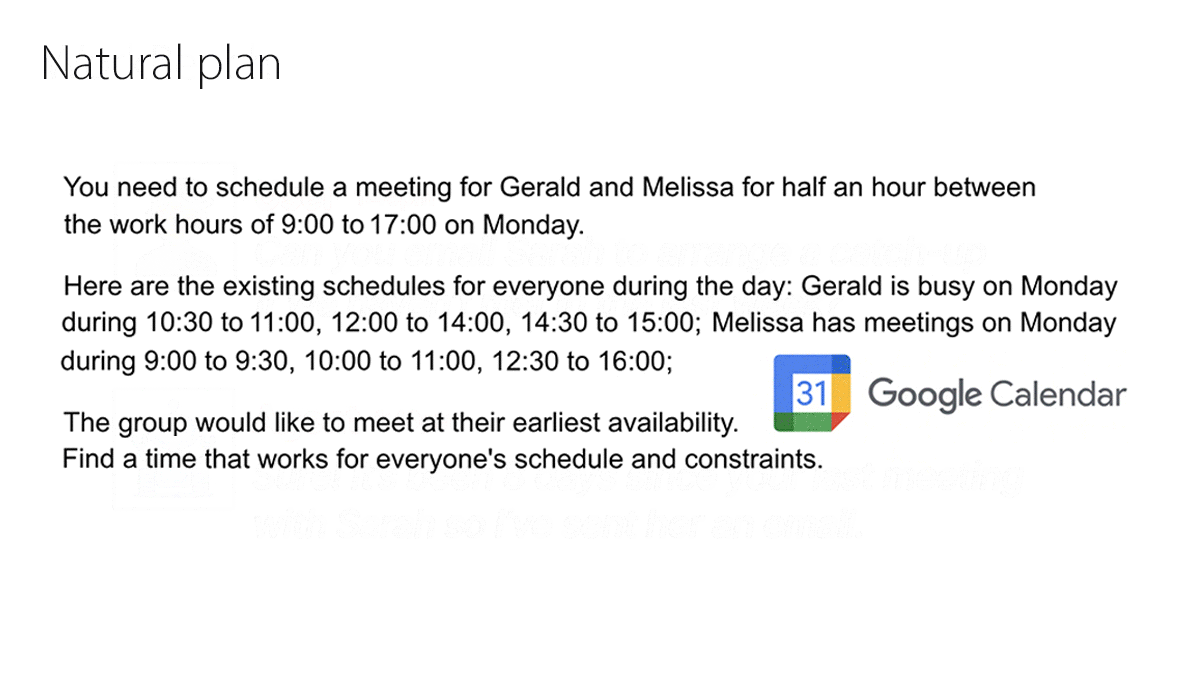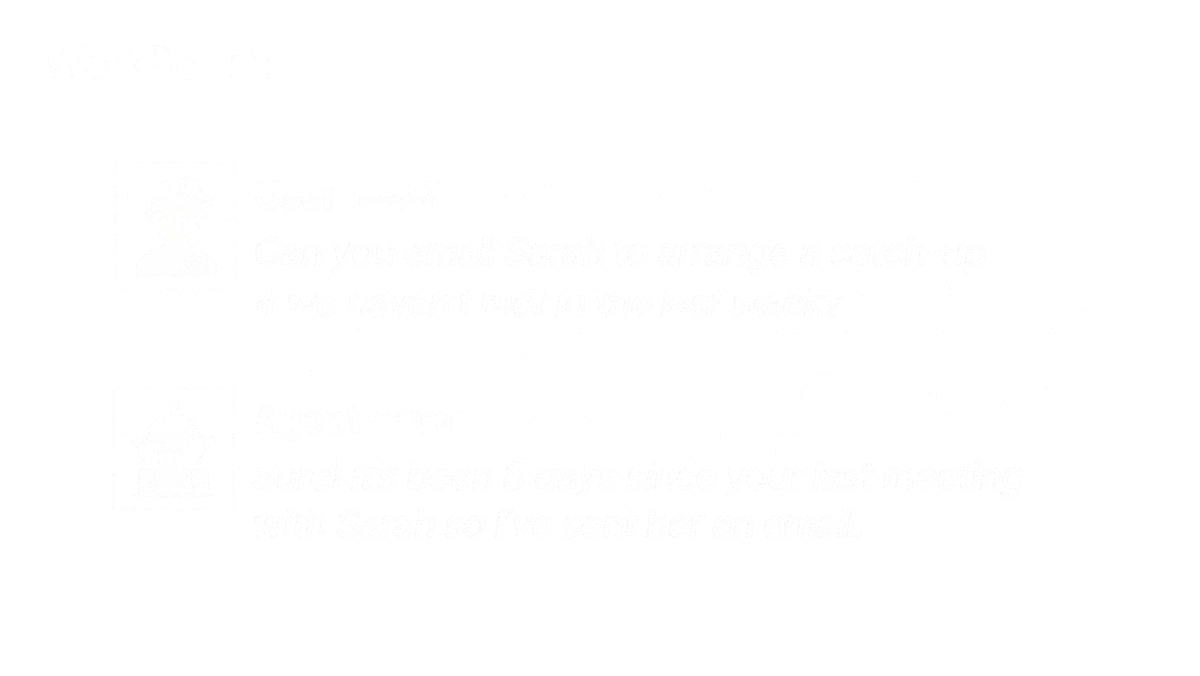
Tool use and planning are key behaviors in agentic workflows that enable large language models (LLMs) to execute complex sequences of steps. New benchmarks measure these capabilities in common workplace tasks. 

June 26, 20243 min read
Benchmarks for Agentic Behaviors: New LLM benchmarks for Tool Use and Planning in workplace tasks
Benchmarks

Benchmarks for Agentic Behaviors: New LLM benchmarks for Tool Use and Planning in workplace tasks

Tool use and planning are key behaviors in agentic workflows that enable large language models (LLMs) to execute complex sequences of steps. New benchmarks measure these capabilities in common workplace tasks. 

June 26, 20243 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox