
Benchmarks
Private Benchmarks for Fairer Tests: Scale AI launches SEAL leaderboards to benchmark model performance
Scale AI offers new leaderboards based on its own benchmarks.

Scale AI offers new leaderboards based on its own benchmarks.
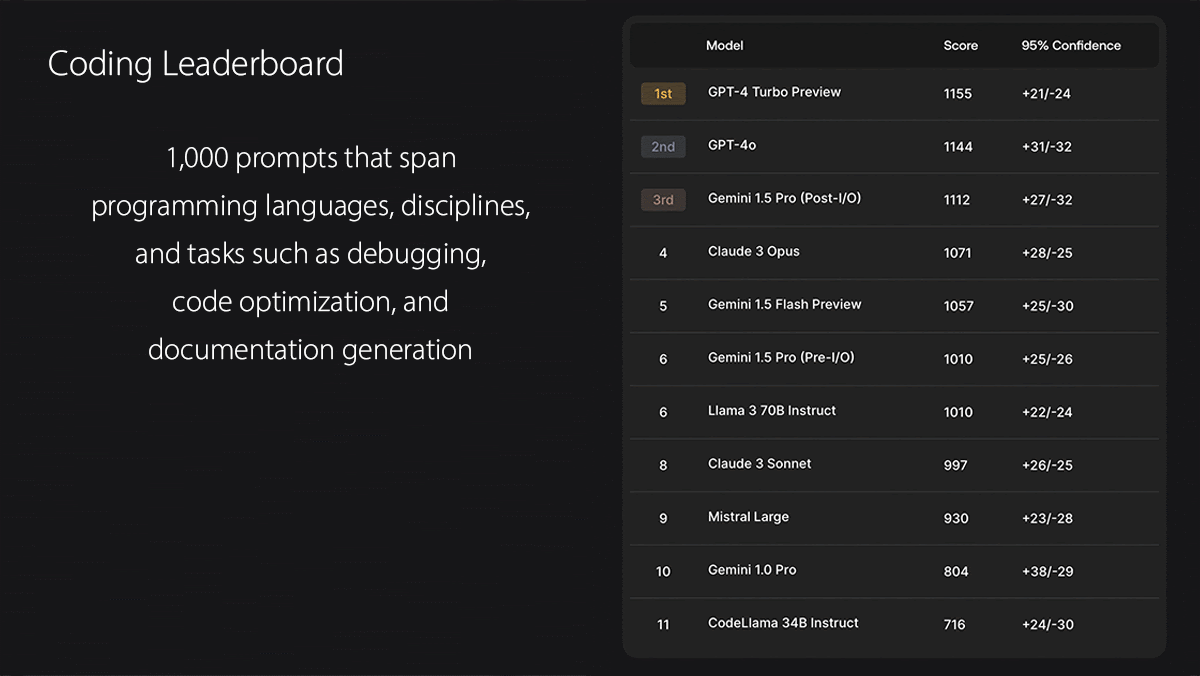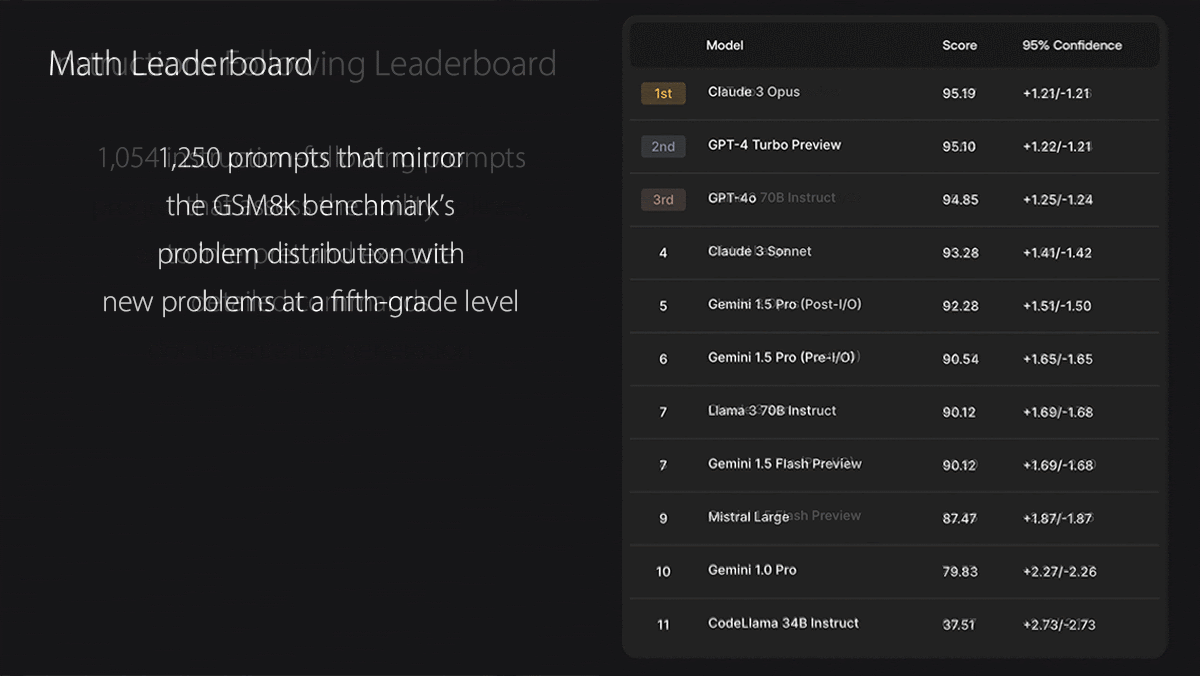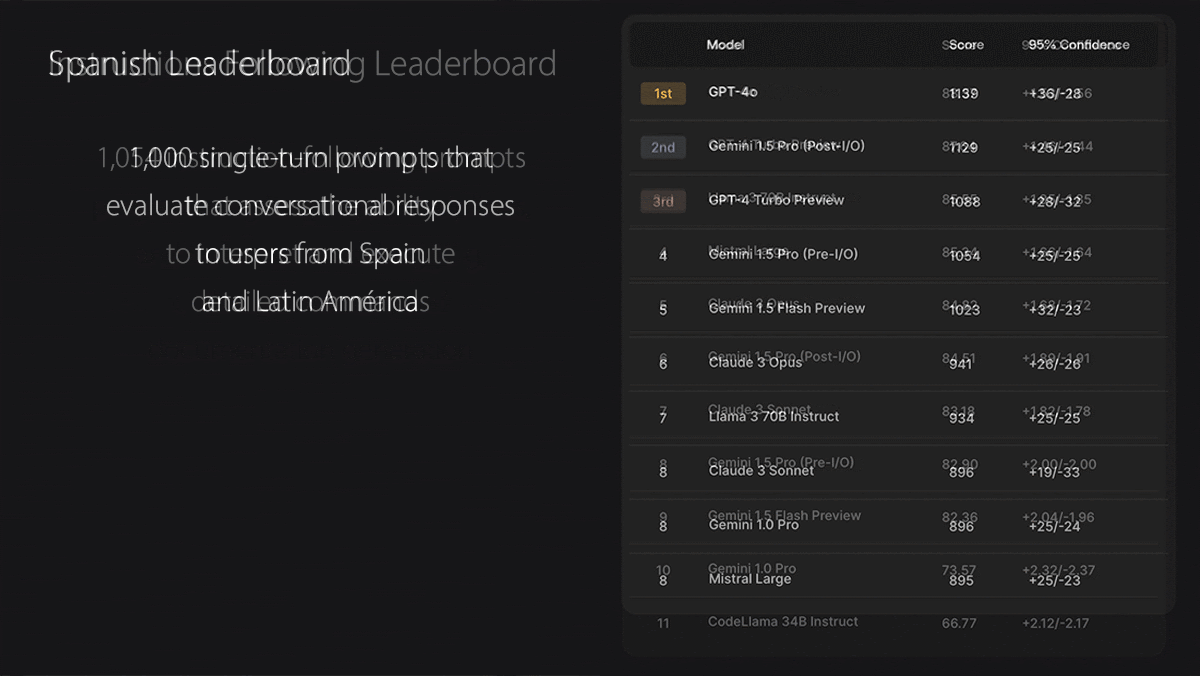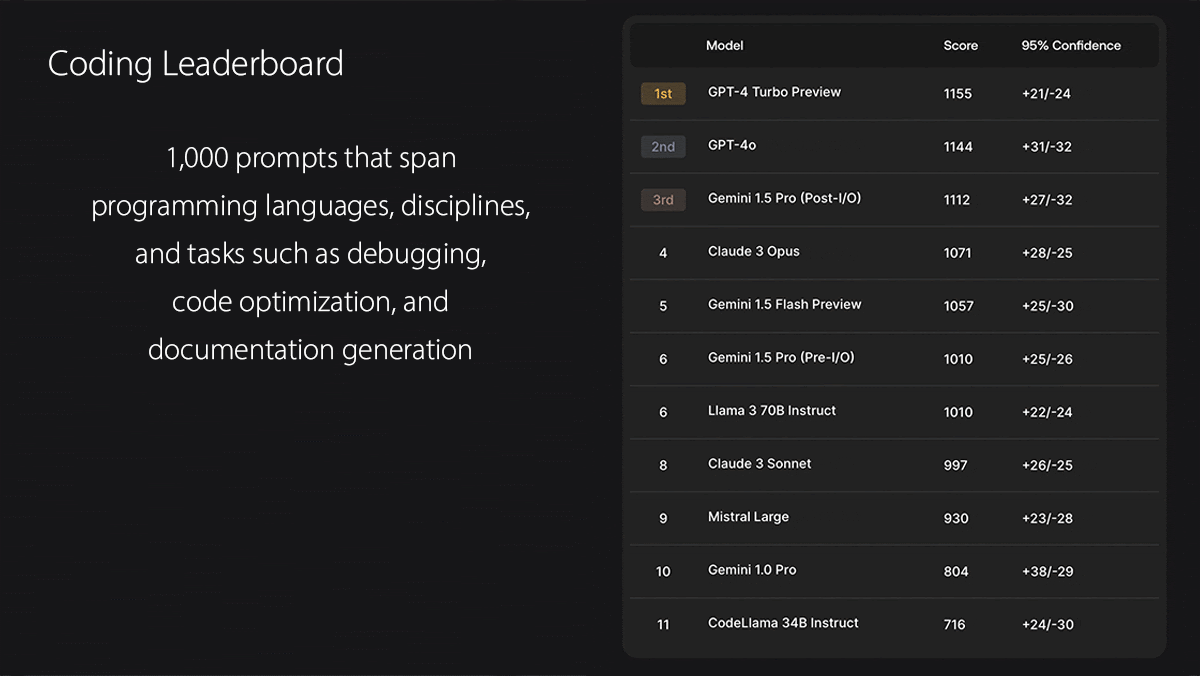
Scale AI offers new leaderboards based on its own benchmarks.

How well do large language models respond to professional-level queries in various industry domains? A new company aims to find out.

How well do large language models respond to professional-level queries in various industry domains? A new company aims to find out.

Training an agent that controls a robot arm to perform a task — say, opening a door — that involves a sequence of motions (reach, grasp, turn, pull, release) can take from tens of thousands to millions of examples...

Training an agent that controls a robot arm to perform a task — say, opening a door — that involves a sequence of motions (reach, grasp, turn, pull, release) can take from tens of thousands to millions of examples...
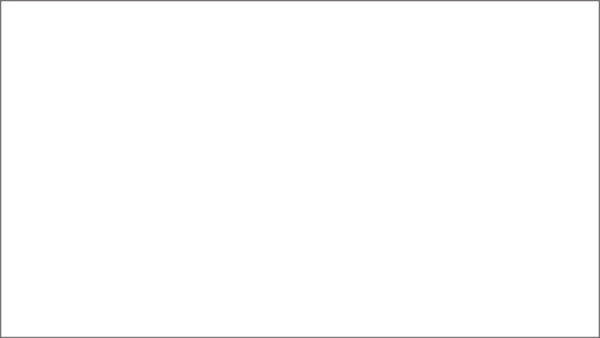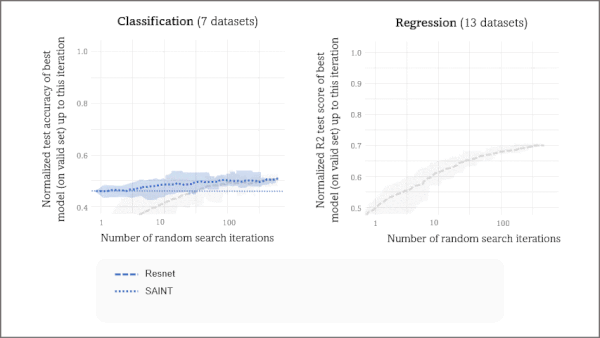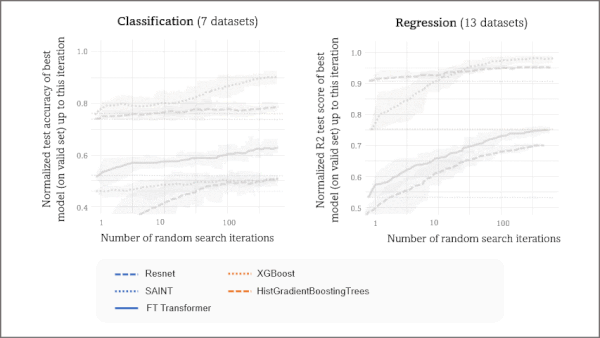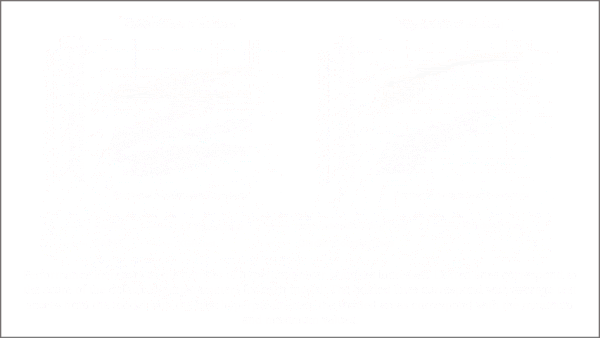
While neural networks perform well on image, text, and audio datasets, they fall behind decision trees and their variations for tabular datasets. New research looked into why.
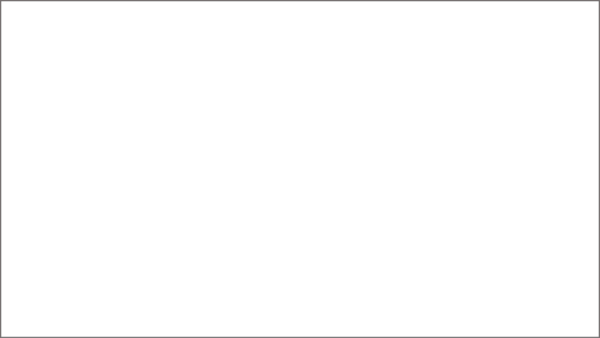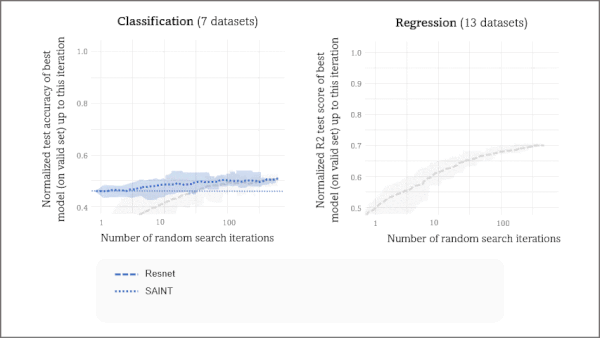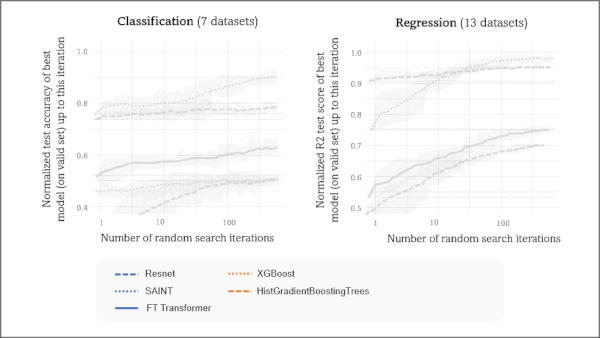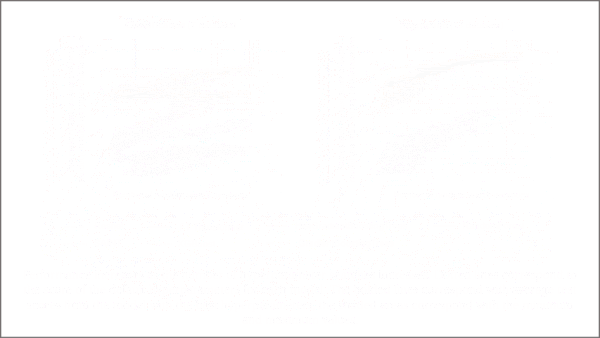
While neural networks perform well on image, text, and audio datasets, they fall behind decision trees and their variations for tabular datasets. New research looked into why.

Robots trained via reinforcement learning usually study videos of robots performing the task at hand. A new approach used videos of humans to pre-train robotic arms.

Robots trained via reinforcement learning usually study videos of robots performing the task at hand. A new approach used videos of humans to pre-train robotic arms.

A new benchmark aims to raise the bar for large language models. Researchers at 132 institutions worldwide introduced the Beyond the Imitation Game benchmark (BIG-bench), which includes tasks that humans perform well but current state-of-the-art models don’t.
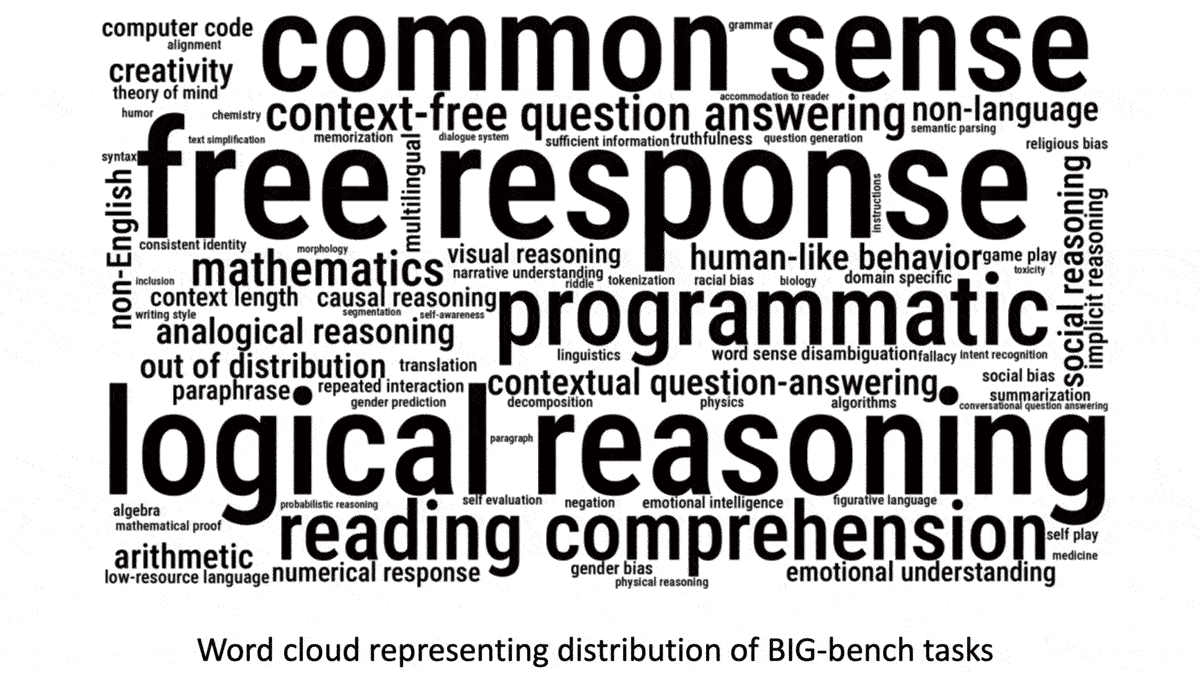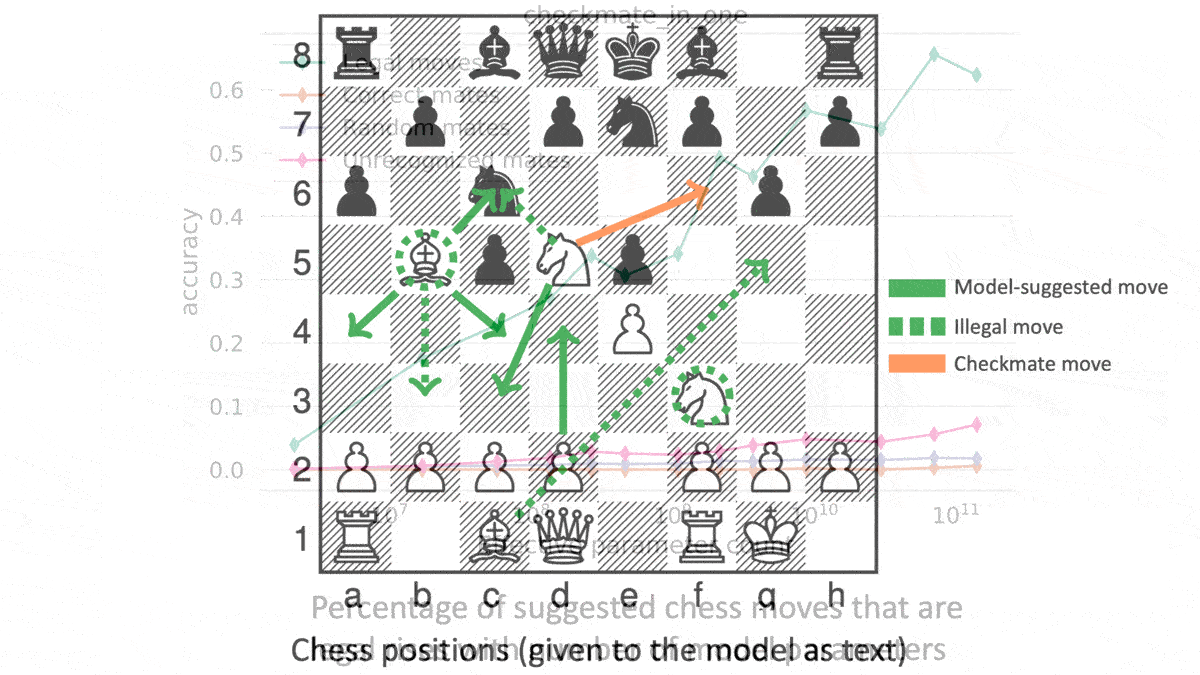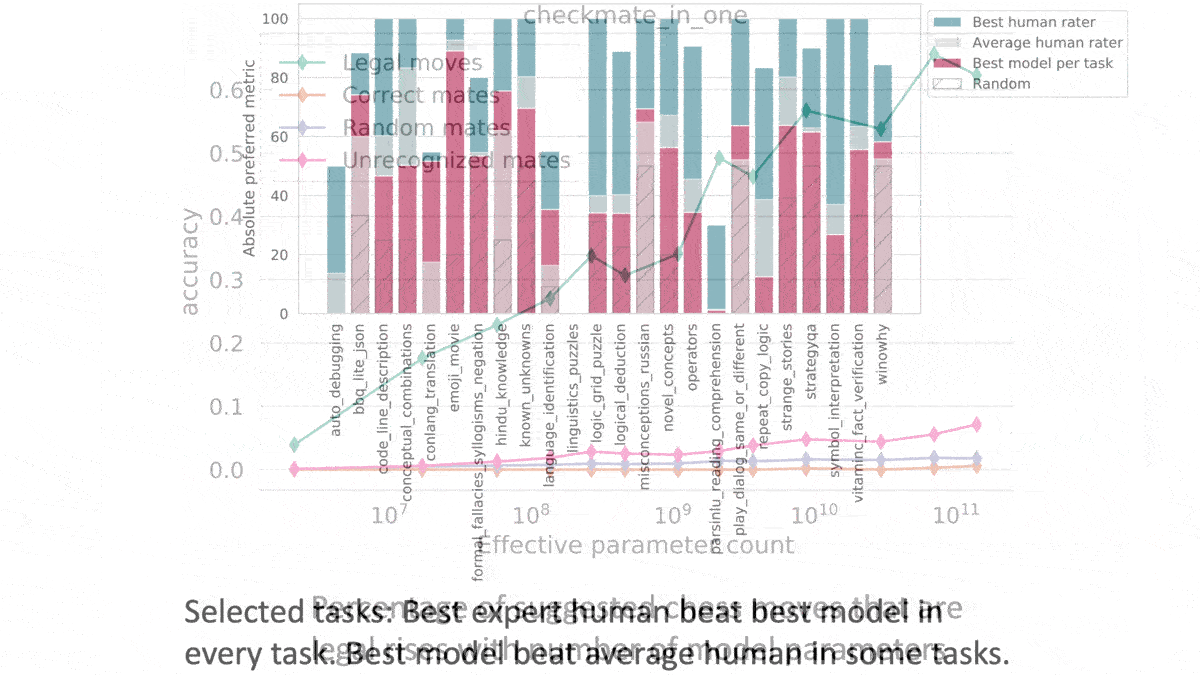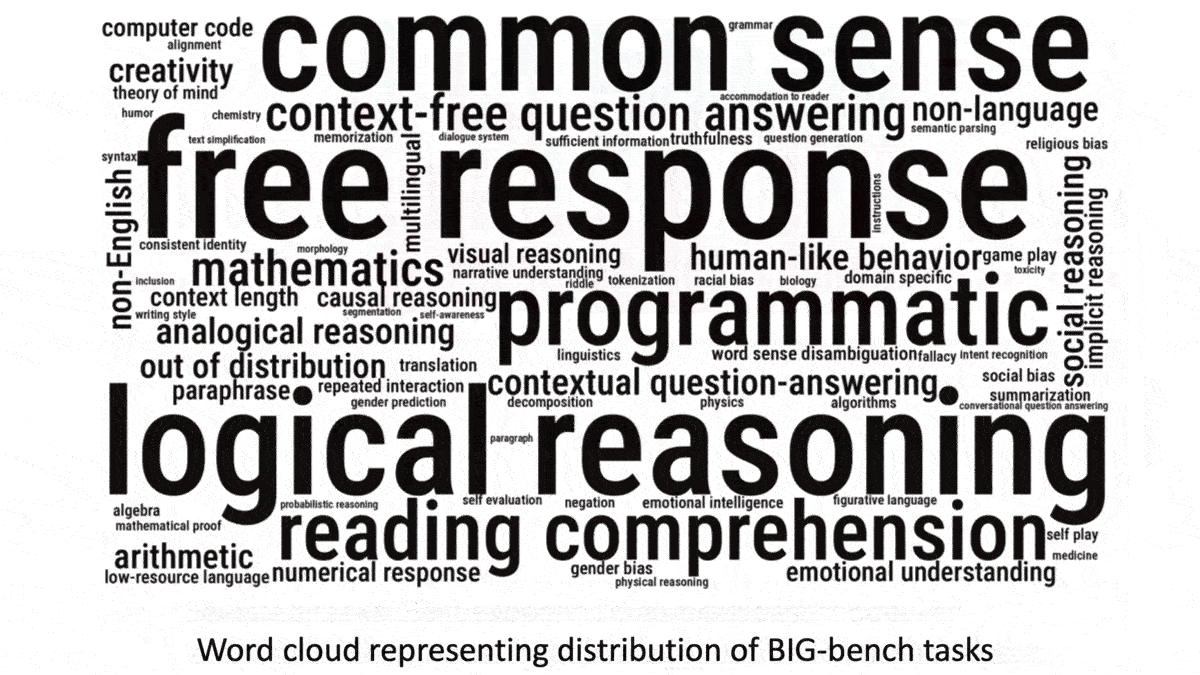
A new benchmark aims to raise the bar for large language models. Researchers at 132 institutions worldwide introduced the Beyond the Imitation Game benchmark (BIG-bench), which includes tasks that humans perform well but current state-of-the-art models don’t.

A new study showcases AI’s growing importance worldwide. What’s new: The fifth annual AI Index from Stanford University’s Institute for Human-Centered AI documents rises in funding, regulation, and performance.
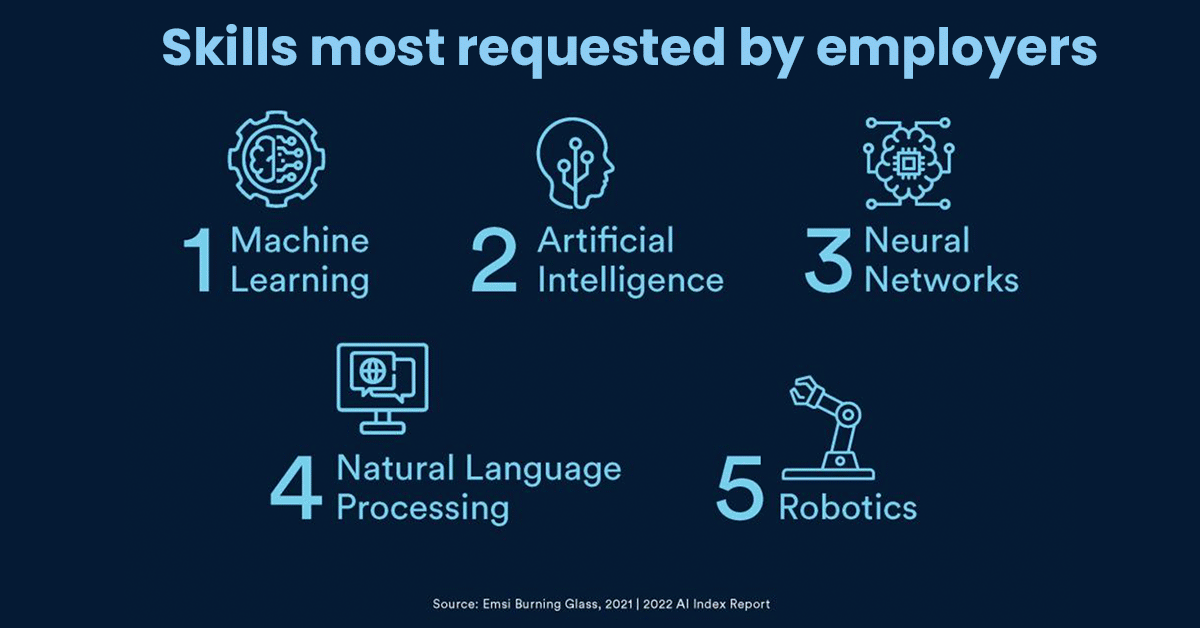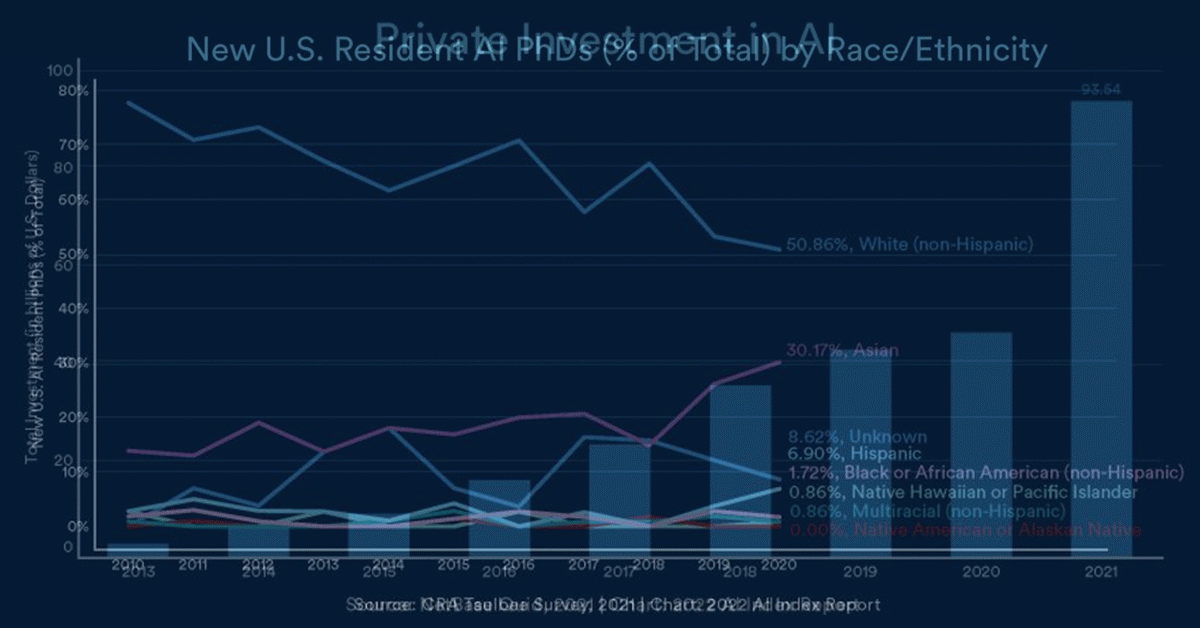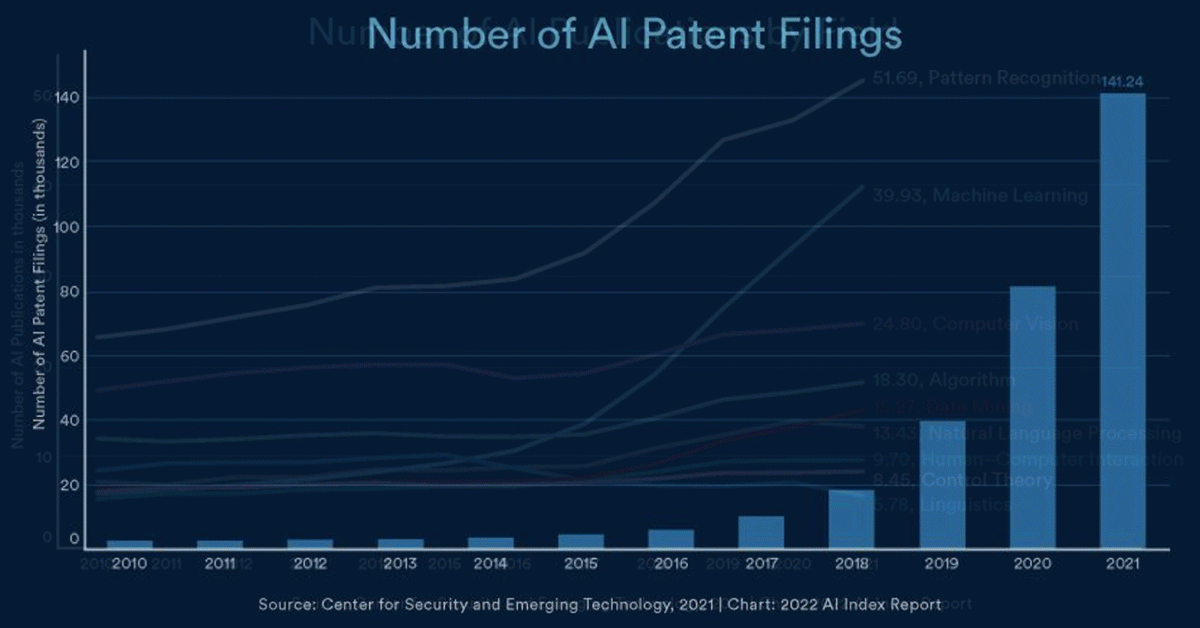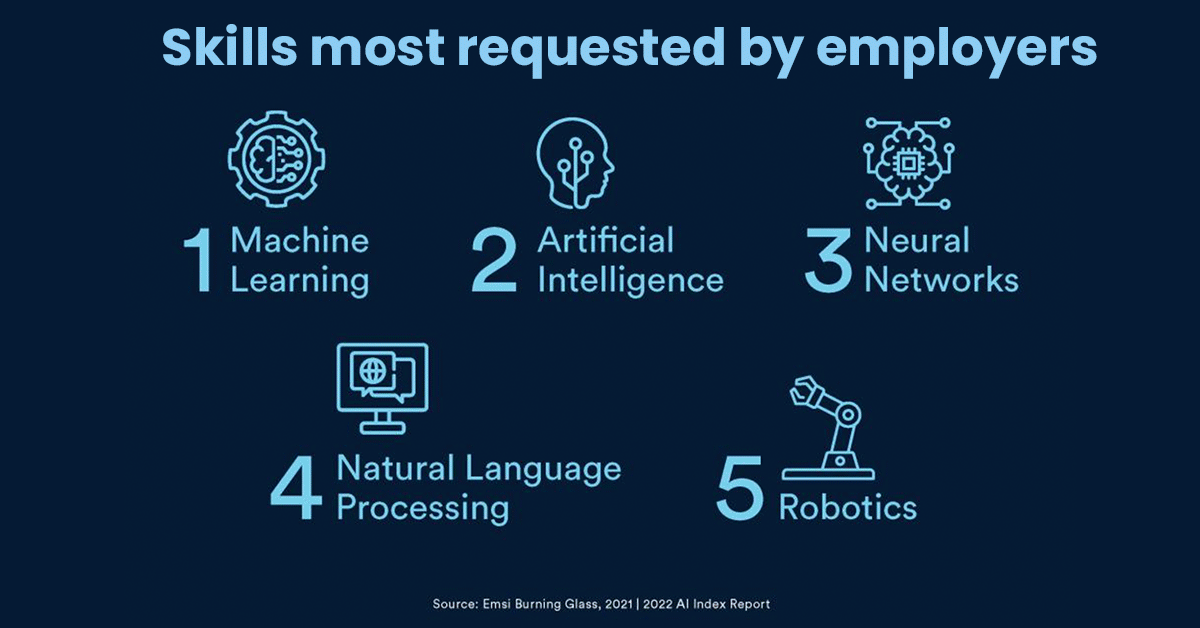
A new study showcases AI’s growing importance worldwide. What’s new: The fifth annual AI Index from Stanford University’s Institute for Human-Centered AI documents rises in funding, regulation, and performance.
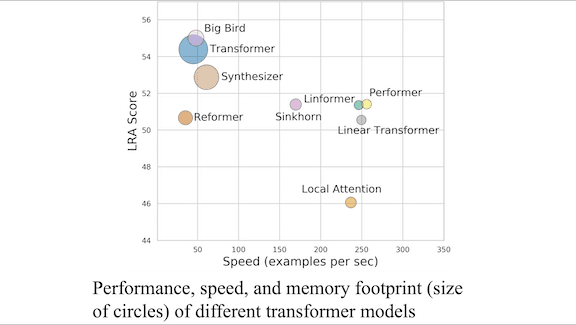
The transformer architecture has inspired a plethora of variations. Yet researchers have used a patchwork of metrics to evaluate their performance, making them hard to compare. New work aims to level the playing field.
Stay updated with weekly AI News and Insights delivered to your inbox