Benchmarking Costs Climb: Reasoning LLMs Are Pricey to Test
Benchmarks

Benchmarking Costs Climb: Reasoning LLMs Are Pricey to Test

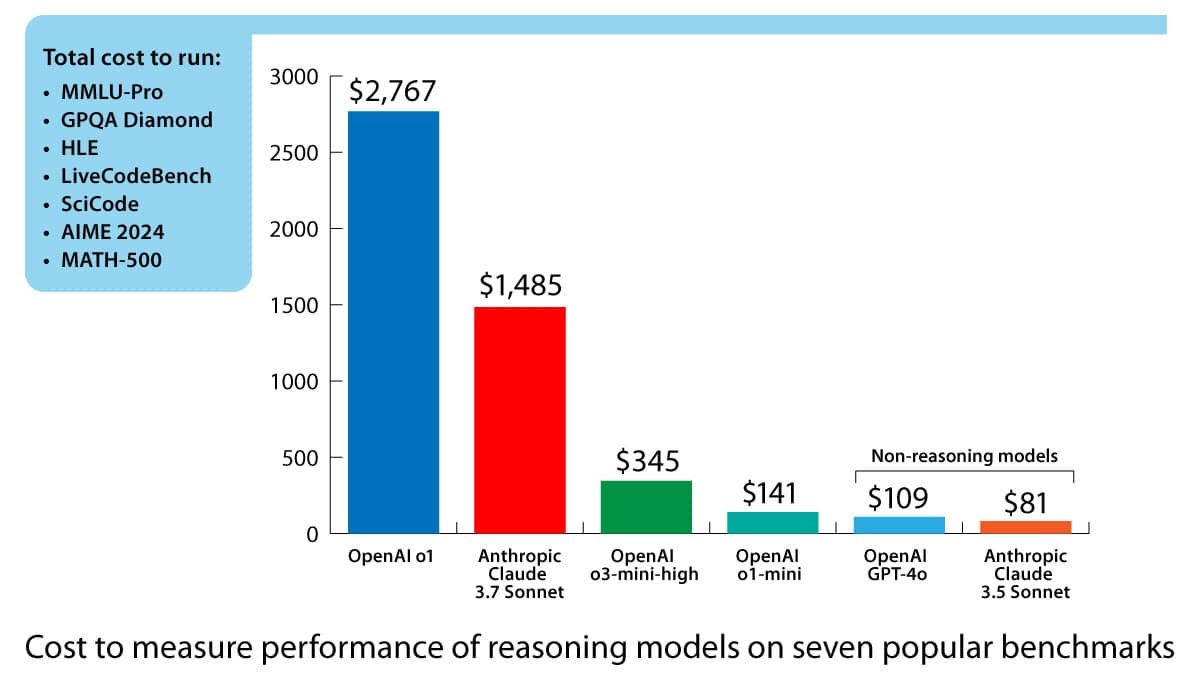
An independent AI test lab detailed the rising cost of benchmarking reasoning models.

June 11, 20252 min read
4-Bit Efficiency, 16-Bit Accuracy: Microsoft researchers show that heavily quantized versions of Llama can perform as well as near-full-precision
Benchmarks

4-Bit Efficiency, 16-Bit Accuracy: Microsoft researchers show that heavily quantized versions of Llama can perform as well as near-full-precision

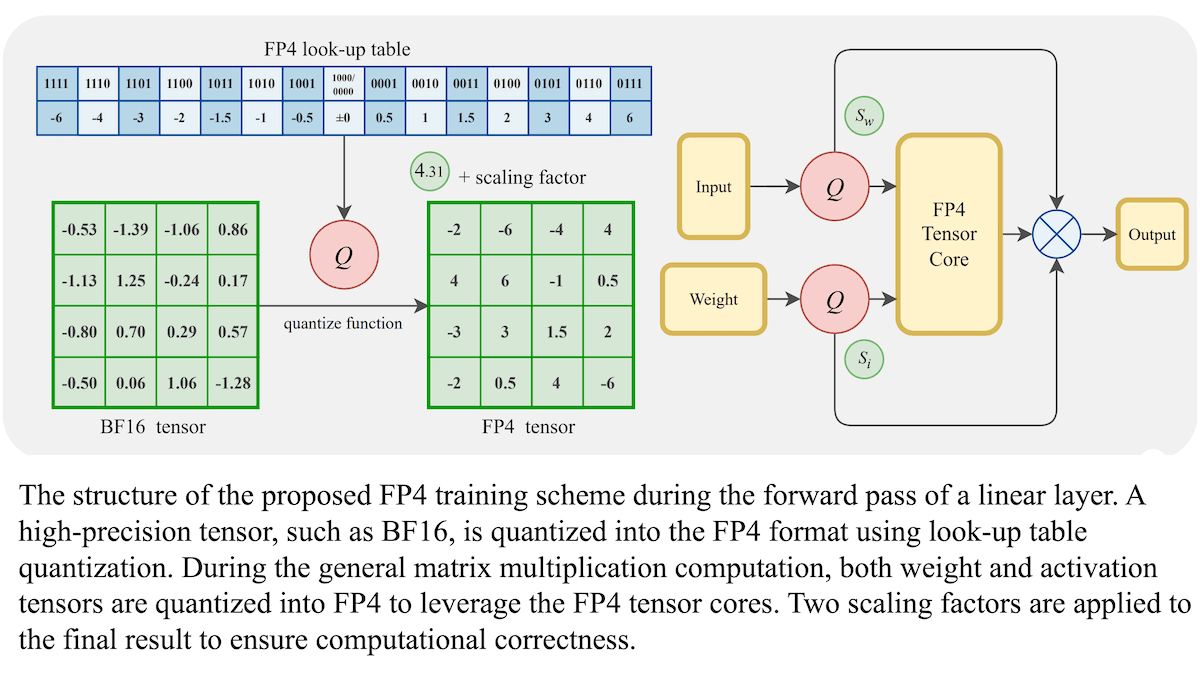
Using an 8-bit number format like FP8 during training saves computation compared to 16- or 32-bit formats, but it can yield less-accurate results. Researchers trained models using 4-bit numbers without sacrificing accuracy.
May 21, 20252 min read
Text-Only LLM Goes Multimodal: LLMs learn to caption images, video, and audio without further training
Benchmarks

Text-Only LLM Goes Multimodal: LLMs learn to caption images, video, and audio without further training

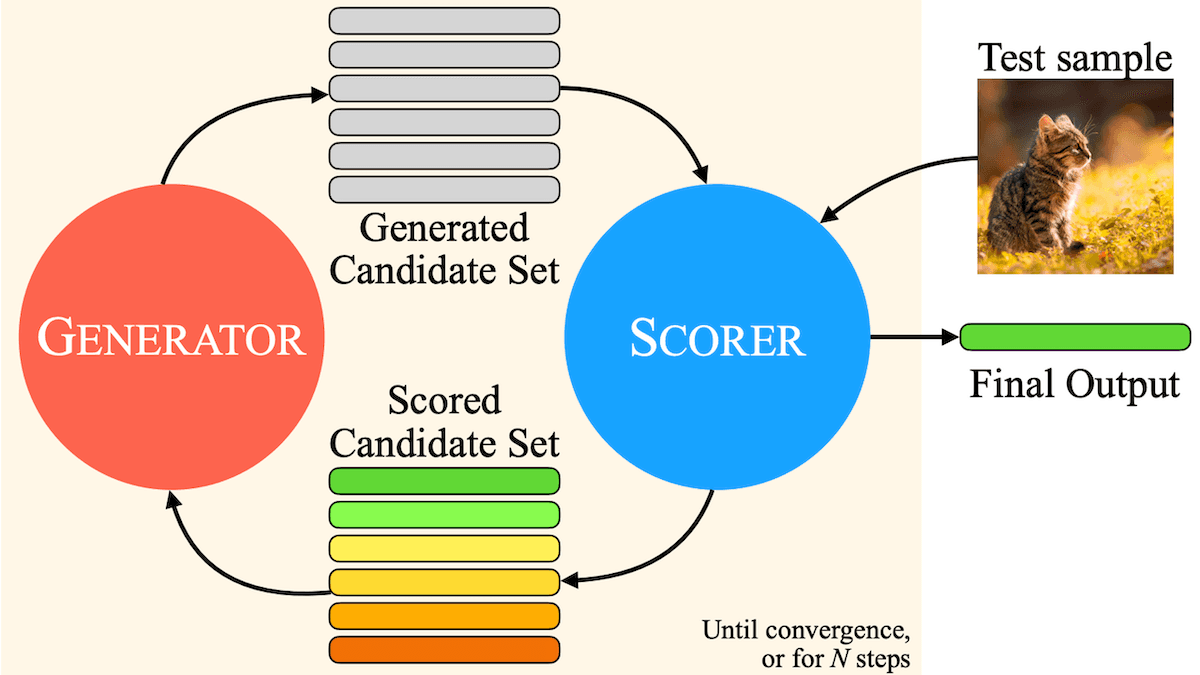
Large language models excel at processing text but can’t interpret images, video, or audio directly without further training on those media types. Researchers devised a way to overcome this limitation.
April 23, 20252 min read
OpenAI Launches Cost-Effective Alternatives: OpenAI replaces GPT-4.5 with GPT-4.1 Family, plus o3 and o4-mini, new models focused on reasoning and coding
Benchmarks

OpenAI Launches Cost-Effective Alternatives: OpenAI replaces GPT-4.5 with GPT-4.1 Family, plus o3 and o4-mini, new models focused on reasoning and coding

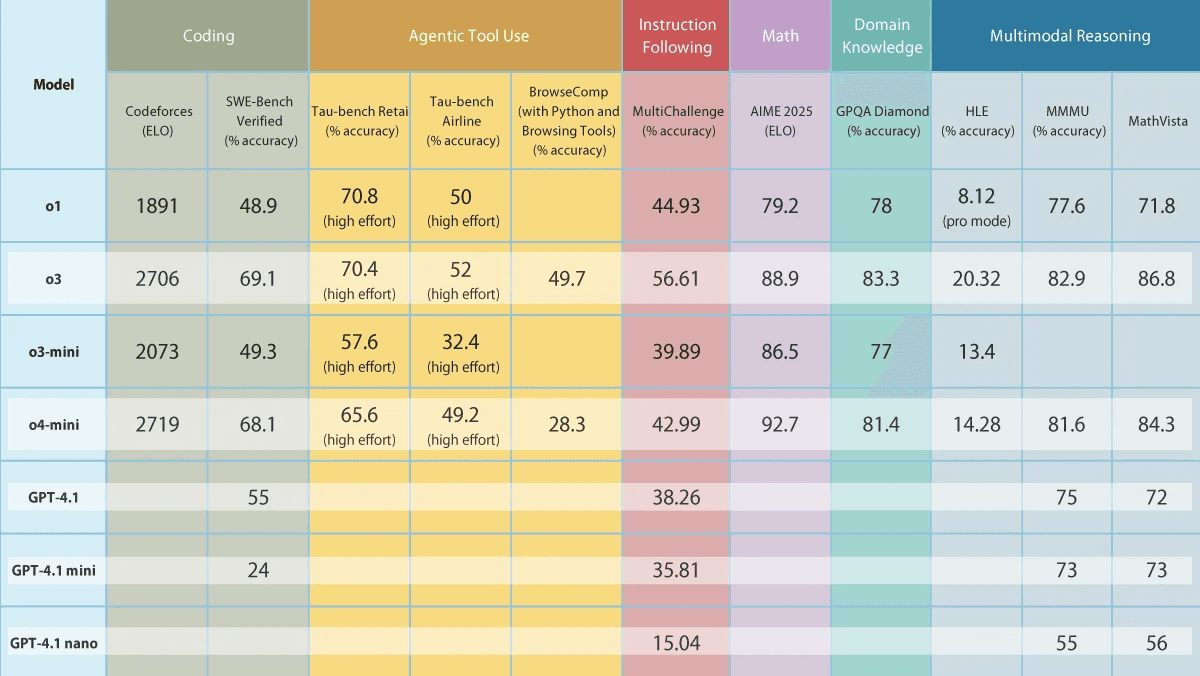
OpenAI refreshed its roster of models and scheduled the largest, most costly one for removal.
April 23, 20253 min read
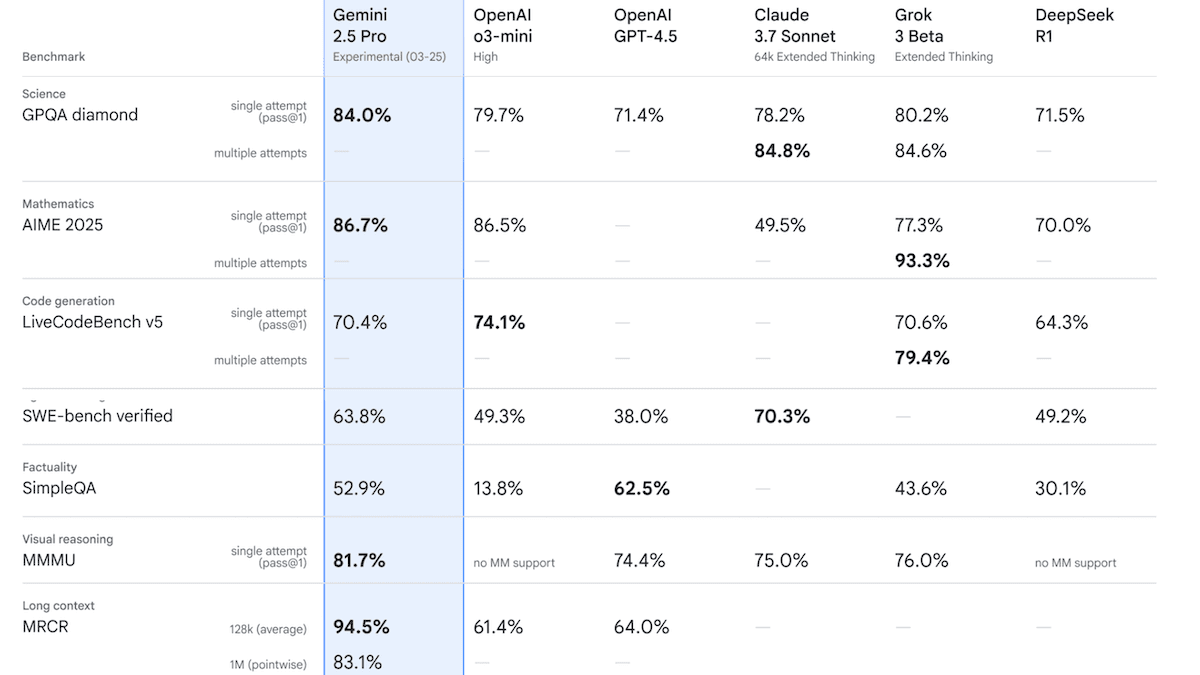
Google Unveils Gemini 2.5: Google’s Gemini 2.5 Pro Experimental outperforms top AI models
Benchmarks

Google Unveils Gemini 2.5: Google’s Gemini 2.5 Pro Experimental outperforms top AI models

Google’s new flagship model raised the state of the art in a variety of subjective and objective tests.
April 16, 20252 min read
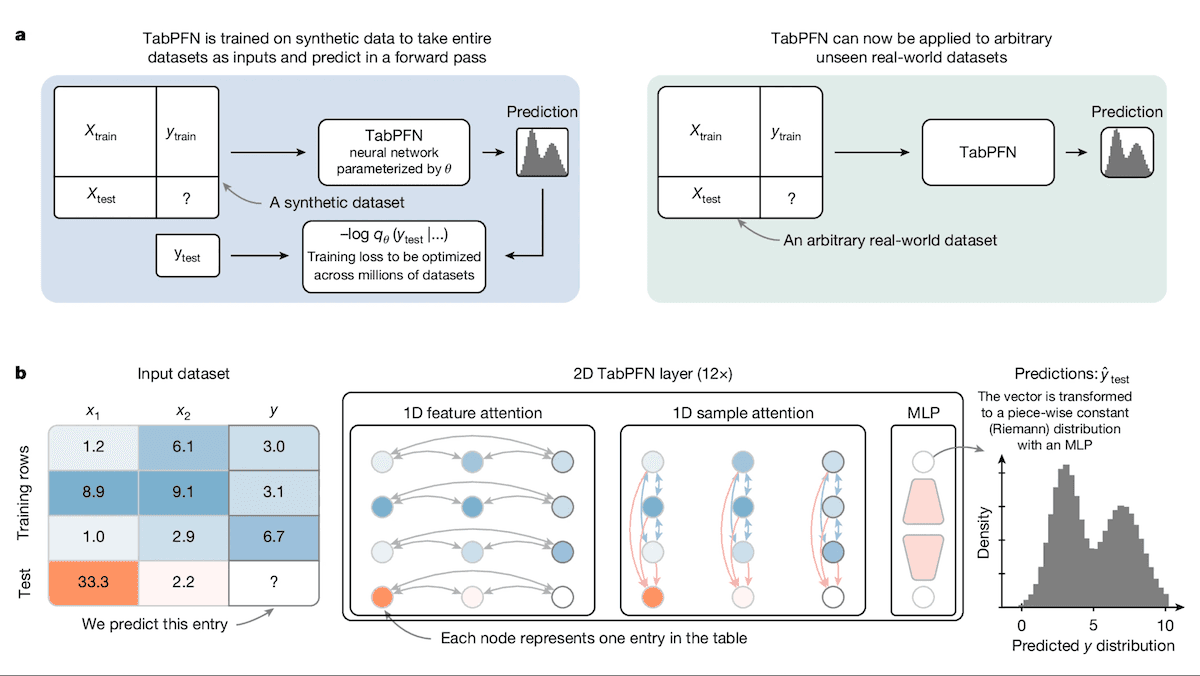
Better Than Trees for Tabular Data: Transformers can outperform decision trees at predicting unlabeled spreadsheet cells
Benchmarks

Better Than Trees for Tabular Data: Transformers can outperform decision trees at predicting unlabeled spreadsheet cells

If you have a collection of variables that represent, say, a cancer patient and you want to classify the patient’s illness as likely cancer or not, algorithms based on decision trees, such as gradient-boosted trees, typically perform better than neural networks.
April 9, 20253 min read
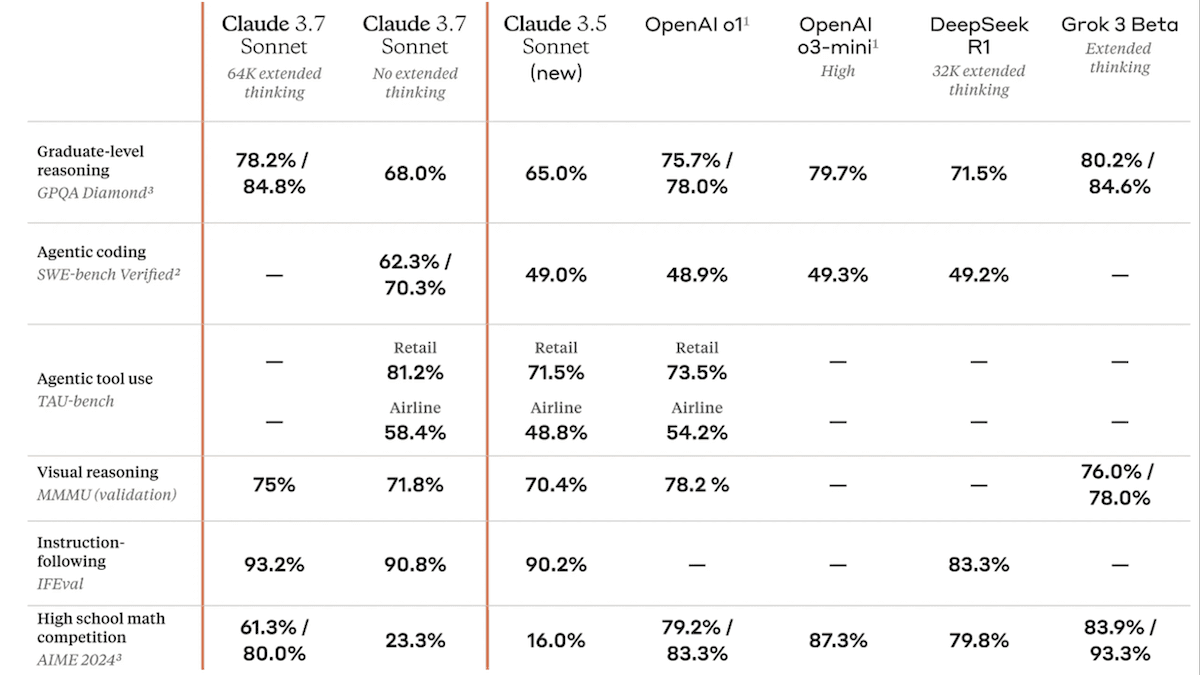
Budget for Reasoning to the Token: Claude 3.7 Sonnet adds extended thinking mode
Benchmarks

Budget for Reasoning to the Token: Claude 3.7 Sonnet adds extended thinking mode

Anthropic’s Claude 3.7 Sonnet implements a hybrid reasoning approach that lets users decide how much thinking they want the model to do before it renders a response.

March 5, 20253 min read
Budget for Reasoning to the Token: Claude 3.7 Sonnet adds extended thinking mode
Benchmarks

Budget for Reasoning to the Token: Claude 3.7 Sonnet adds extended thinking mode

Anthropic’s Claude 3.7 Sonnet implements a hybrid reasoning approach that lets users decide how much thinking they want the model to do before it renders a response.

March 5, 20253 min read
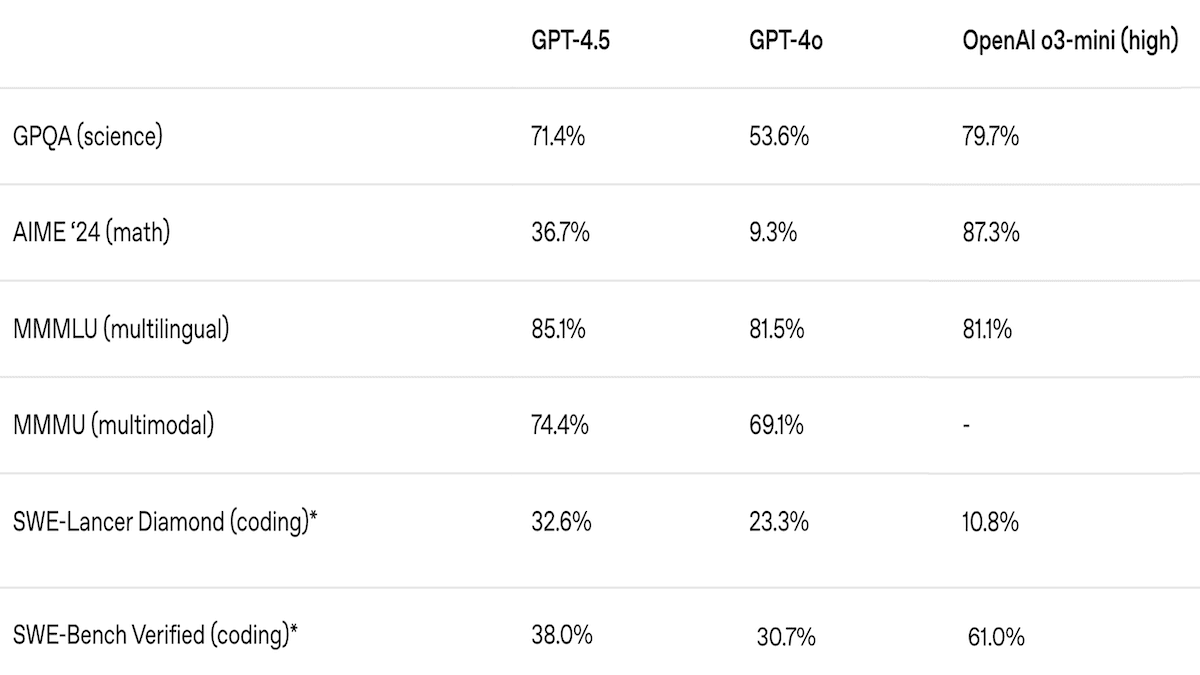
OpenAI’s GPT-4.5 Goes Big: OpenAI releases GPT-4.5, its most powerful non-reasoning model and maybe its last
Benchmarks

OpenAI’s GPT-4.5 Goes Big: OpenAI releases GPT-4.5, its most powerful non-reasoning model and maybe its last

OpenAI launched GPT-4.5, which may be its last non-reasoning model.
March 5, 20253 min read
OpenAI’s GPT-4.5 Goes Big: OpenAI releases GPT-4.5, its most powerful non-reasoning model and maybe its last
Benchmarks

OpenAI’s GPT-4.5 Goes Big: OpenAI releases GPT-4.5, its most powerful non-reasoning model and maybe its last

OpenAI launched GPT-4.5, which may be its last non-reasoning model.
March 5, 20253 min read
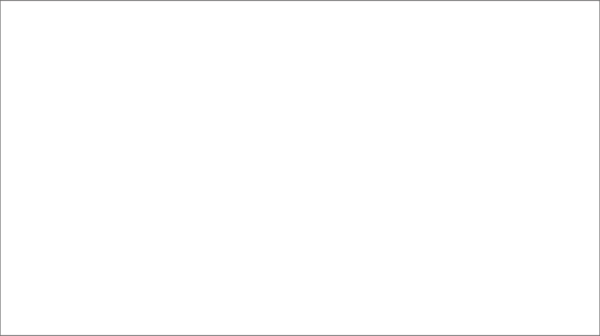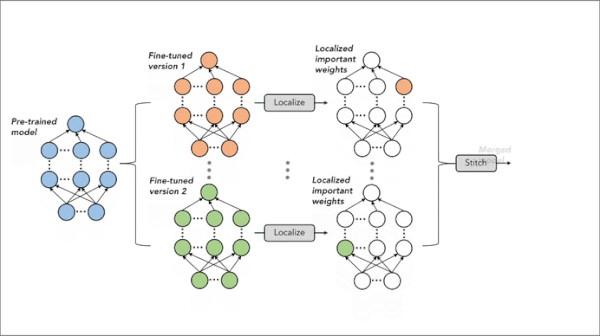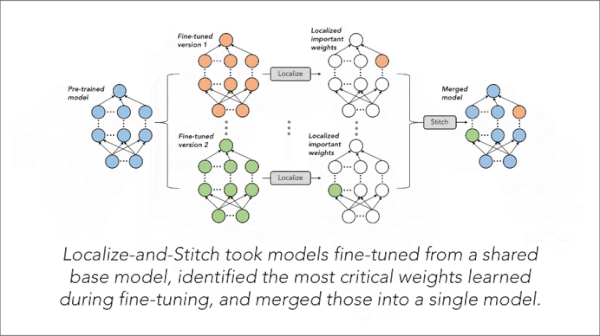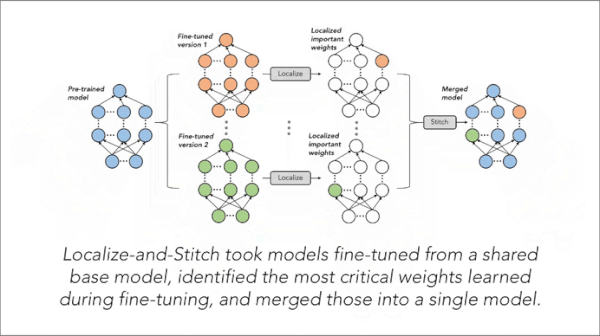
Better Performance From Merged Models: Localize-and-Stitch improves methods for merging and fine-tuning multiple models
Benchmarks

Better Performance From Merged Models: Localize-and-Stitch improves methods for merging and fine-tuning multiple models

Merging multiple fine-tuned models is a less expensive alternative to hosting multiple specialized models. But, while model merging can deliver higher average performance across several tasks, it often results in lower performance on specific tasks. New work addresses this issue.

January 8, 20253 min read
Better Performance From Merged Models: Localize-and-Stitch improves methods for merging and fine-tuning multiple models
Benchmarks

Better Performance From Merged Models: Localize-and-Stitch improves methods for merging and fine-tuning multiple models

Merging multiple fine-tuned models is a less expensive alternative to hosting multiple specialized models. But, while model merging can deliver higher average performance across several tasks, it often results in lower performance on specific tasks. New work addresses this issue.
January 8, 20253 min read
Higher Reasoning: OpenAI debuts o1 and pro mode for $200/month
Benchmarks

Higher Reasoning: OpenAI debuts o1 and pro mode for $200/month

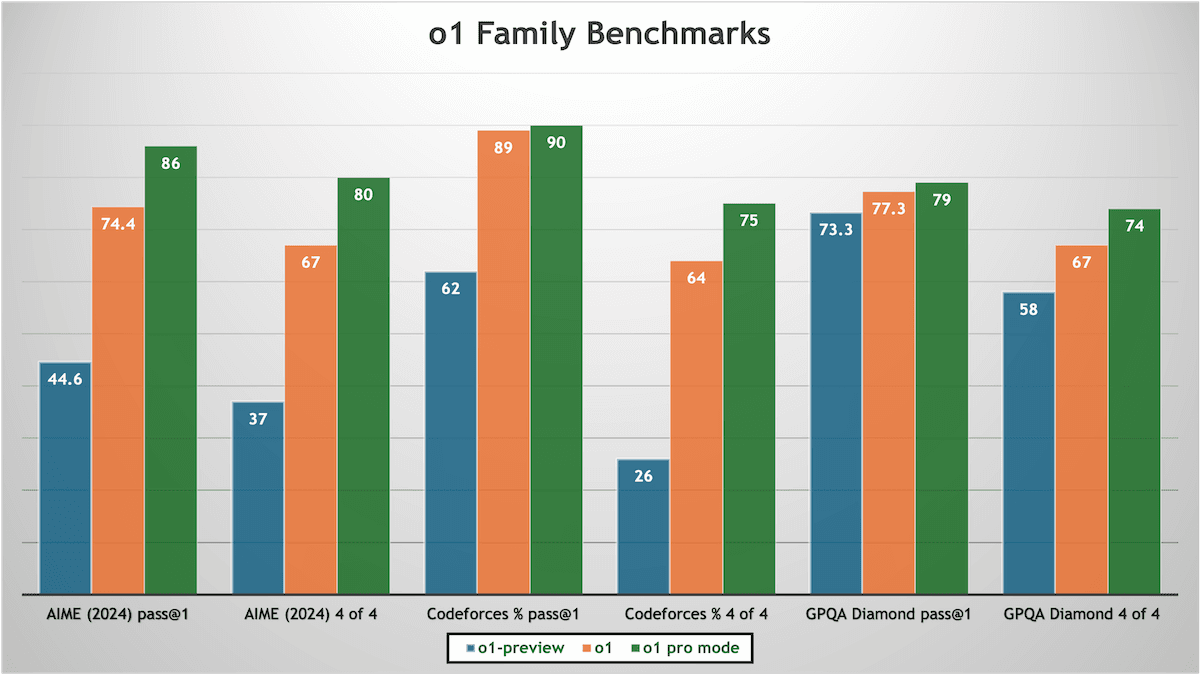
OpenAI launched not only its highly anticipated o1 model but also an operating mode that enables the model to deliver higher performance — at a hefty price.

December 11, 20243 min read
Higher Reasoning: OpenAI debuts o1 and pro mode for $200/month
Benchmarks

Higher Reasoning: OpenAI debuts o1 and pro mode for $200/month

OpenAI launched not only its highly anticipated o1 model but also an operating mode that enables the model to deliver higher performance — at a hefty price.

December 11, 20243 min read
When Agents Train Algorithms: OpenAI’s MLE-bench tests AI coding agents
Benchmarks

When Agents Train Algorithms: OpenAI’s MLE-bench tests AI coding agents

Coding agents are improving, but can they tackle machine learning tasks? 

November 6, 20243 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox