Benchmarks

83 Posts

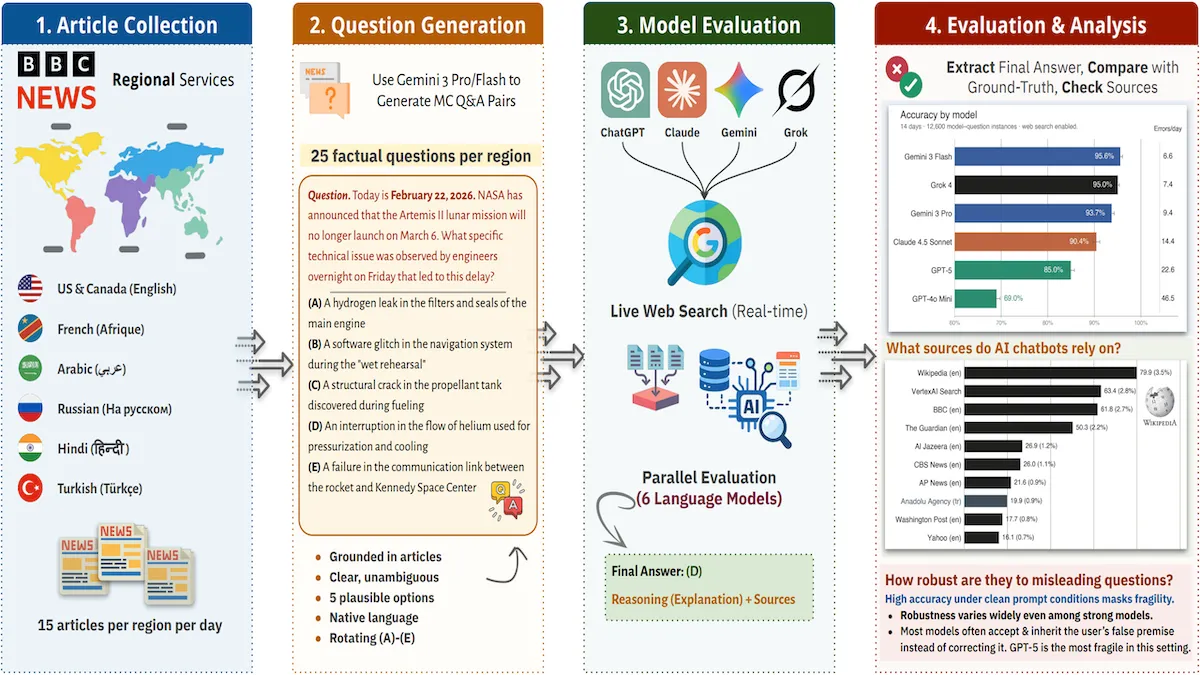
Web Retrieval Flusters LLMs: AI agents searching online can struggle to retrieve correct info, researchers find
Benchmarks

Web Retrieval Flusters LLMs: AI agents searching online can struggle to retrieve correct info, researchers find

Large language models often are called upon to gather news. In this task, researchers found, their ability to find relevant reports is the weakest link.
July 24, 20263 min read
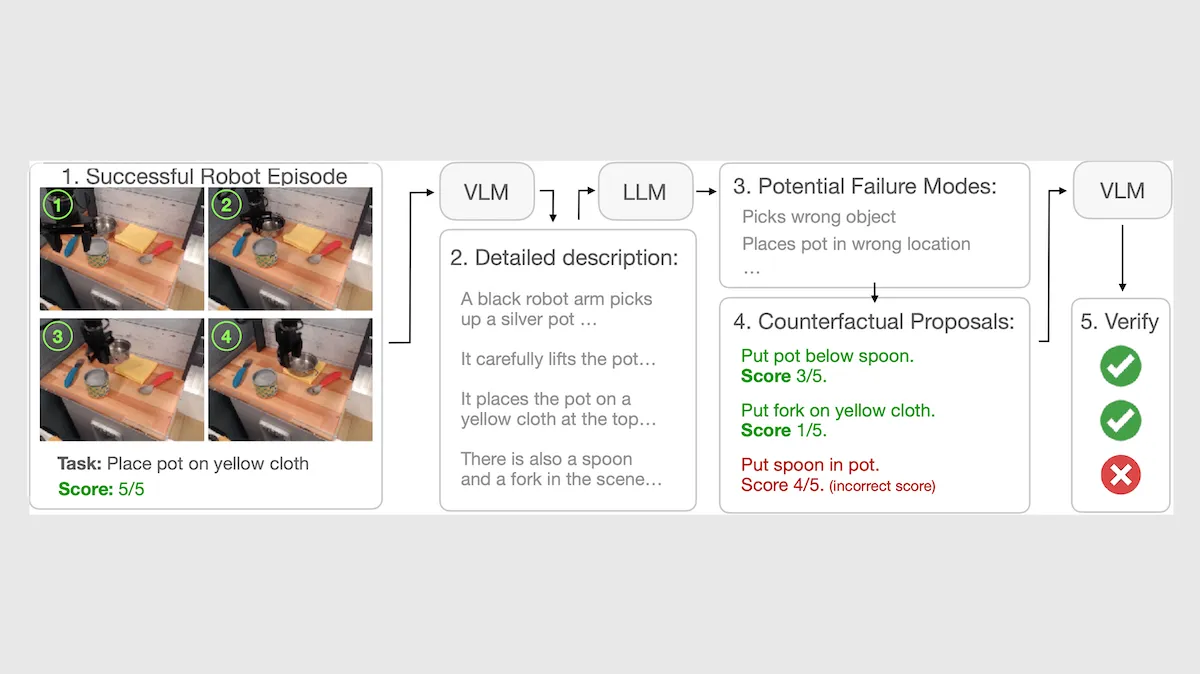
Better Reward Models for Robots: Inside RoboReward, a family of vision-language reward models that train robots to take action
Benchmarks

Better Reward Models for Robots: Inside RoboReward, a family of vision-language reward models that train robots to take action

When you’re training a robot via reinforcement learning, a handcrafted reward function is labor-intensive to build but often dispenses rewards more effectively than a general-purpose reward model based on a vision-language model. Researchers built reward models that narrowed the gap.

July 3, 20263 min read
Agentic Tests Beyond the Bug Hunt: DeepSWE, ProgramBench, and ITBench-AA push agents harder than SWE-bench
Benchmarks

Agentic Tests Beyond the Bug Hunt: DeepSWE, ProgramBench, and ITBench-AA push agents harder than SWE-bench

SWE-bench, a family of benchmarks that focuses on an LLM’s ability to fix software bugs, is giving way to new tests that evaluate agent software-engineering performance in more challenging ways.

June 19, 20264 min read
Claude Fable 5’s Benchmark Problems: Independent tests of Claude Fable 5 run into Anthropic's protective policies
Benchmarks

Claude Fable 5’s Benchmark Problems: Independent tests of Claude Fable 5 run into Anthropic's protective policies

Before Anthropic pulled its latest Claude models from circulation, even professional testers couldn’t readily tell whether they were getting a Mythos-class model or a lesser version under the same name.

June 19, 20264 min read
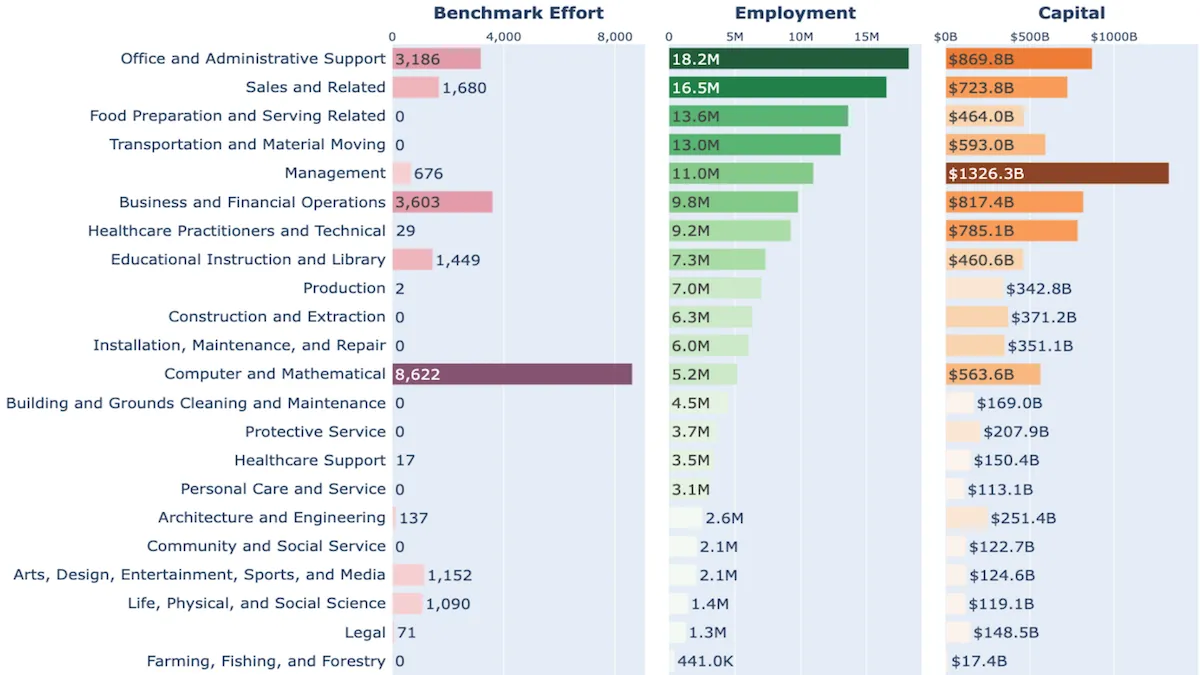
Toward Agent Benchmarks That Reflect Human Work: AI agents may not be getting better at full range of economically valuable labor
Benchmarks

Toward Agent Benchmarks That Reflect Human Work: AI agents may not be getting better at full range of economically valuable labor

AI agents seem to be increasingly capable of performing economically valuable tasks, but current benchmarks measure this capability only narrowly.

May 22, 20263 min read
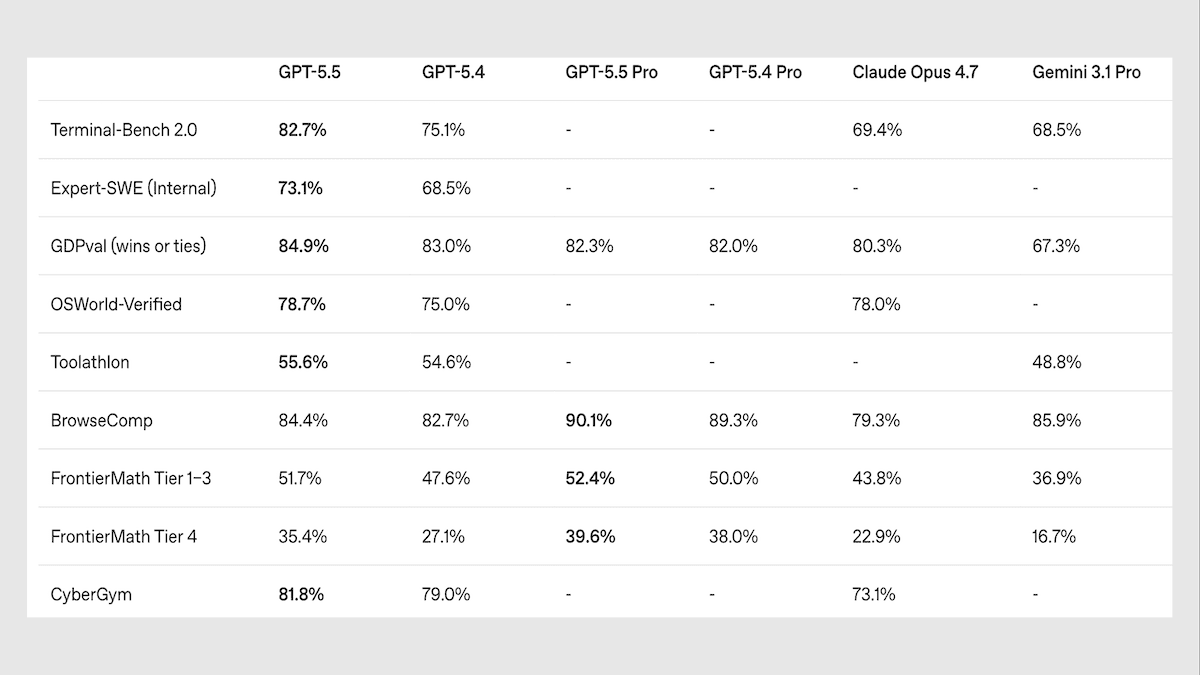
GPT-5.5 Outperforms, Hallucinates: OpenAI’s latest model tops leaderboards for coding, visual puzzles, and overall intelligence
Benchmarks

GPT-5.5 Outperforms, Hallucinates: OpenAI’s latest model tops leaderboards for coding, visual puzzles, and overall intelligence

The latest update of OpenAI’s flagship model sets new states of the art in important benchmarks but has difficulty distinguishing between what it does and doesn't know.

May 1, 20264 min read
Qwen3.5 Outperforms Bigger Models, Leads Vision Benchmarks: Alibaba’s latest flagship models are open-weights MoE performers in sizes from less than 1B parameters
Benchmarks

Qwen3.5 Outperforms Bigger Models, Leads Vision Benchmarks: Alibaba’s latest flagship models are open-weights MoE performers in sizes from less than 1B parameters

The Qwen3.5 family of open-weights vision-language models includes impressive larger models as well as a smaller one that outperforms an OpenAI open-weights model 10 times its size.

March 20, 20263 min read
Artificial Analysis Revamps Intelligence Index: Independent AI testing authority turns from saturated knowledge benchmarks to harder business tests
Benchmarks

Artificial Analysis Revamps Intelligence Index: Independent AI testing authority turns from saturated knowledge benchmarks to harder business tests

Artificial Analysis, which tests AI systems, updated the component evaluations in its Intelligence Index to better reflect large language models’ performance in real-world use cases.

January 30, 20263 min read
OpenAI’s Answer to Gemini 3: GPT-5.2 arrives, touting variable reasoning and coding performance
Benchmarks

OpenAI’s Answer to Gemini 3: GPT-5.2 arrives, touting variable reasoning and coding performance

OpenAI launched GPT-5.2 only weeks after its CEO Sam Altman reportedly issued a “code red” alarm in response to Google's Gemini 3.

December 17, 20253 min read
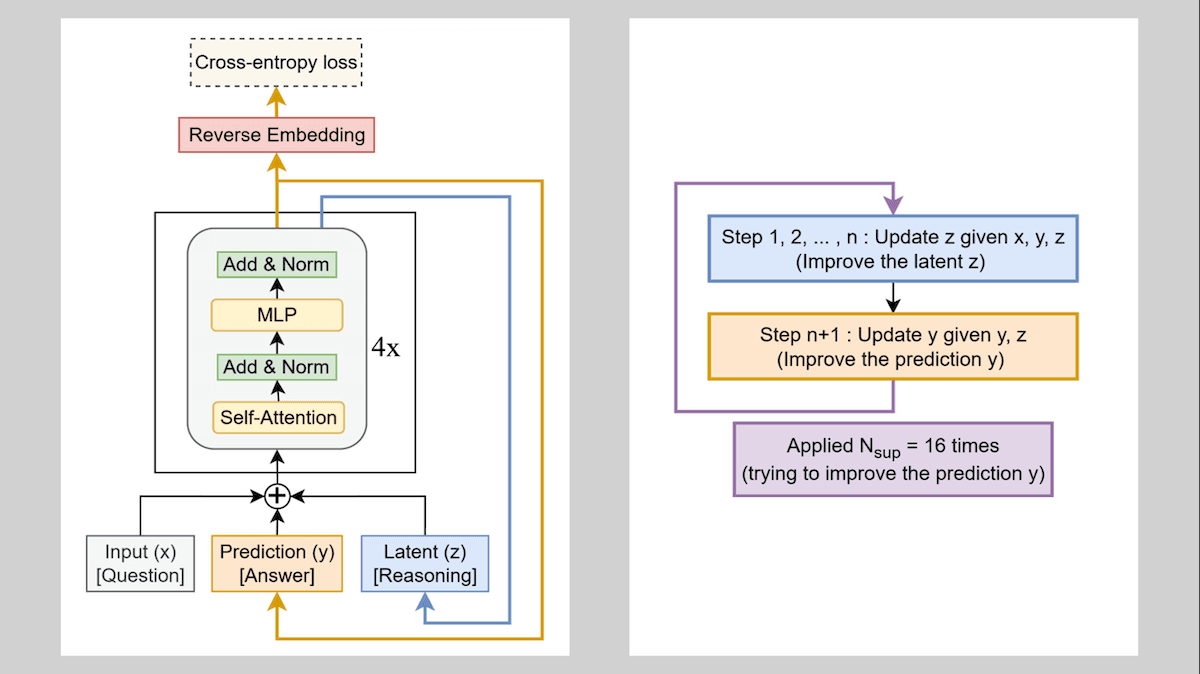
Small Models Solve Hard Puzzles: Tiny Recursive Model beats larger competitors at games like Sudoku and Maze
Benchmarks

Small Models Solve Hard Puzzles: Tiny Recursive Model beats larger competitors at games like Sudoku and Maze

Large language models often fail at puzzles like Sudoku, for which a solution includes multiple elements and a single mistake invalidates all of them. Researchers showed that a tiny network, by repeatedly refining its solution, can solve this sort of puzzle well.

December 10, 20253 min read
Claude Does More With Fewer Tokens: Claude Opus 4.5 retakes the coding crown at one-third the price of its predecessor
Benchmarks

Claude Does More With Fewer Tokens: Claude Opus 4.5 retakes the coding crown at one-third the price of its predecessor

Claude Opus 4.5, the latest version of Anthropic’s flagship model, extends the earlier version’s strengths in coding, computer use, and agentic workflows while generating fewer tokens.

December 10, 20253 min read
Google Dominates Arena Leaderboards (For the Moment): Gemini 3 Pro and Nano Banana Pro boast best-in-class multimodal reasoning and image generation
Benchmarks

Google Dominates Arena Leaderboards (For the Moment): Gemini 3 Pro and Nano Banana Pro boast best-in-class multimodal reasoning and image generation

Google introduced Gemini 3 Pro and Nano Banana Pro, its flagship vision-language and image-generation models, and deployed them to billions of users worldwide.

November 26, 20254 min read
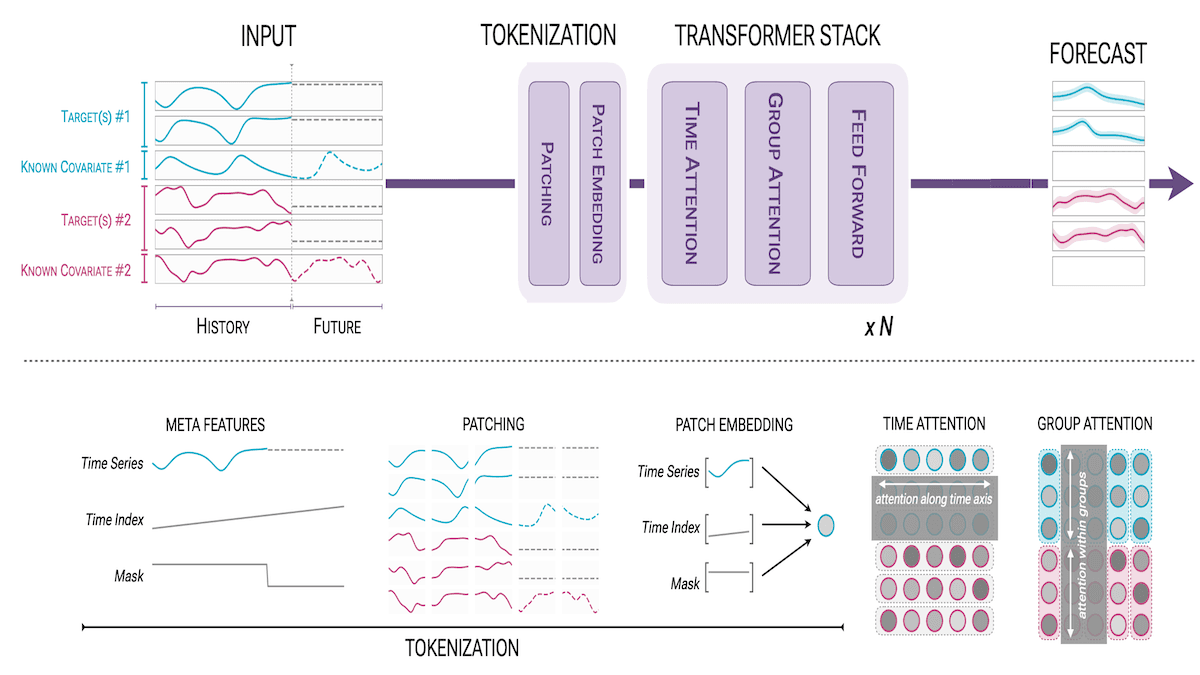
Forecasting Multiple Time Series: Amazon’s Chronos-2 sorts out tangled variables to make better predictions
Benchmarks

Forecasting Multiple Time Series: Amazon’s Chronos-2 sorts out tangled variables to make better predictions

Transformers are well suited to predicting future values of time series like energy prices, wages, or weather, but often — as in those examples — multiple time series often influence one another. Researchers built a model that can forecast multiple time series simultaneously.

November 12, 20253 min read
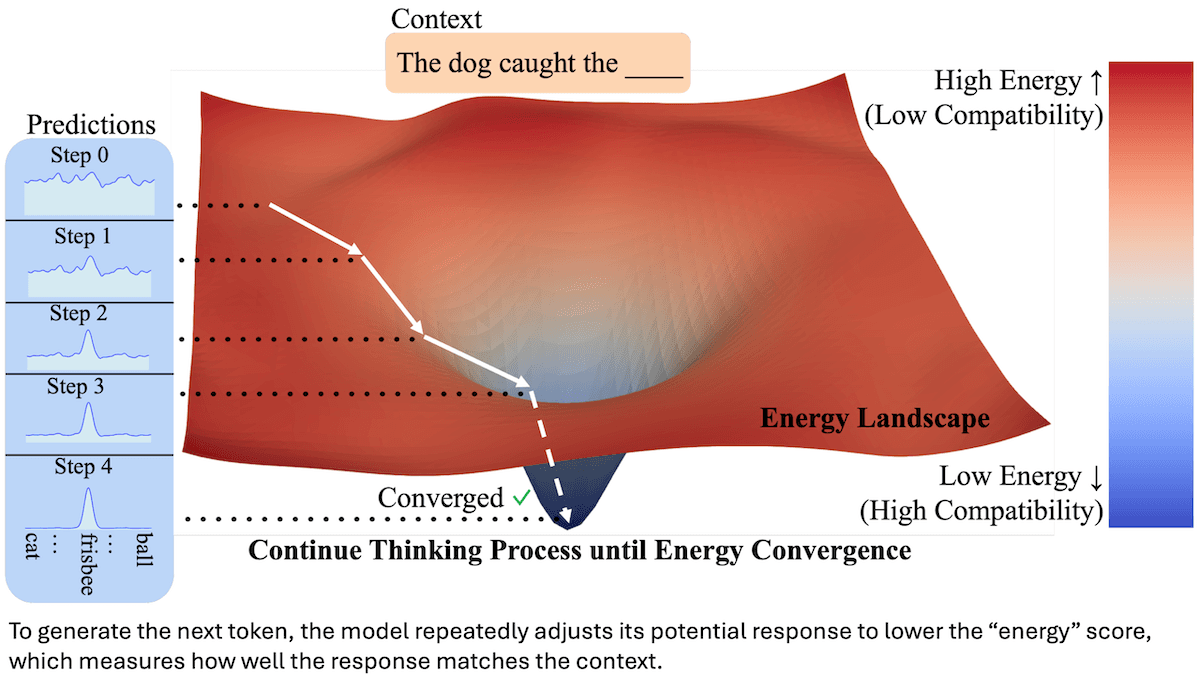
Transformers Energized: Energy-Based Transformers (EBTs) use gradient descent to gradually predict the next token
Benchmarks

Transformers Energized: Energy-Based Transformers (EBTs) use gradient descent to gradually predict the next token

A new type of transformer can check its work. Instead of guessing the next output token in one shot like a typical transformer, it starts with a rough version of the token and improves it step by step.

September 17, 20253 min read
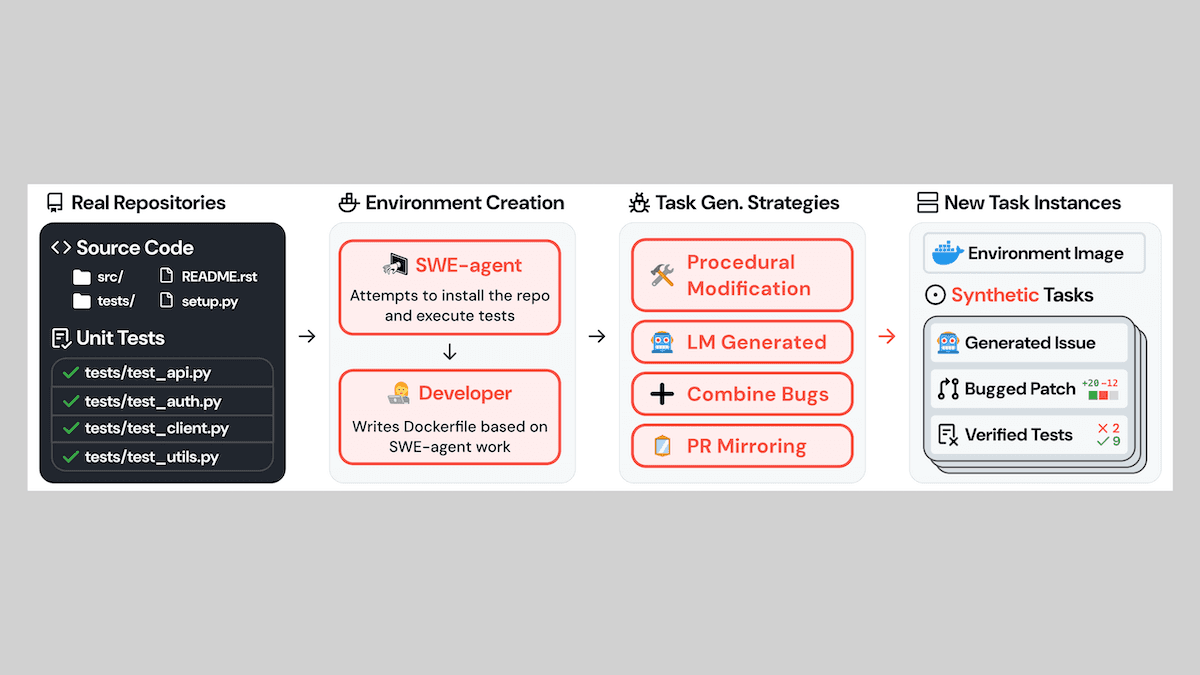
Training Data for Coding Assistants: Stanford and Alibaba build bug fixing dataset and pipeline to train AI
Benchmarks

Training Data for Coding Assistants: Stanford and Alibaba build bug fixing dataset and pipeline to train AI

A bottleneck in fine-tuning large language models for software engineering is building a dataset that can show them how to edit code, search for subroutines, write test scripts, control a terminal, manage a file system, and so on. Researchers built a pipeline that produces such data automatically.

August 13, 20252 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox