Speech Recognition

70 Posts

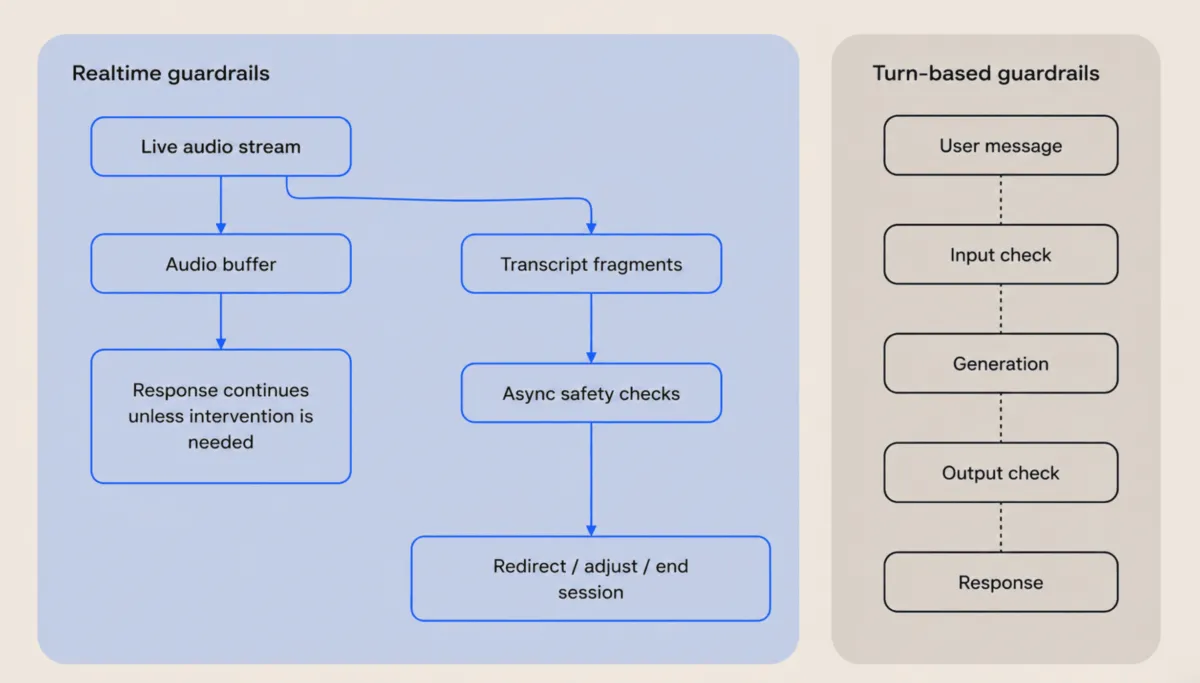
One Model Talks, Another One Thinks: GPT-Live pairs full-duplex voice models with a reasoning model (GPT-5.5) on the backend
Speech Recognition

One Model Talks, Another One Thinks: GPT-Live pairs full-duplex voice models with a reasoning model (GPT-5.5) on the backend

ChatGPT’s voice mode now listens and speaks at the same time, passing harder questions posed to the conversational model to a reasoning model in the background.
July 17, 20265 min read
OpenAI Challenges Speech-to-Speech Leaders: RealTime API updates audio models that reason, transcribe, and translate
Speech Recognition

OpenAI Challenges Speech-to-Speech Leaders: RealTime API updates audio models that reason, transcribe, and translate

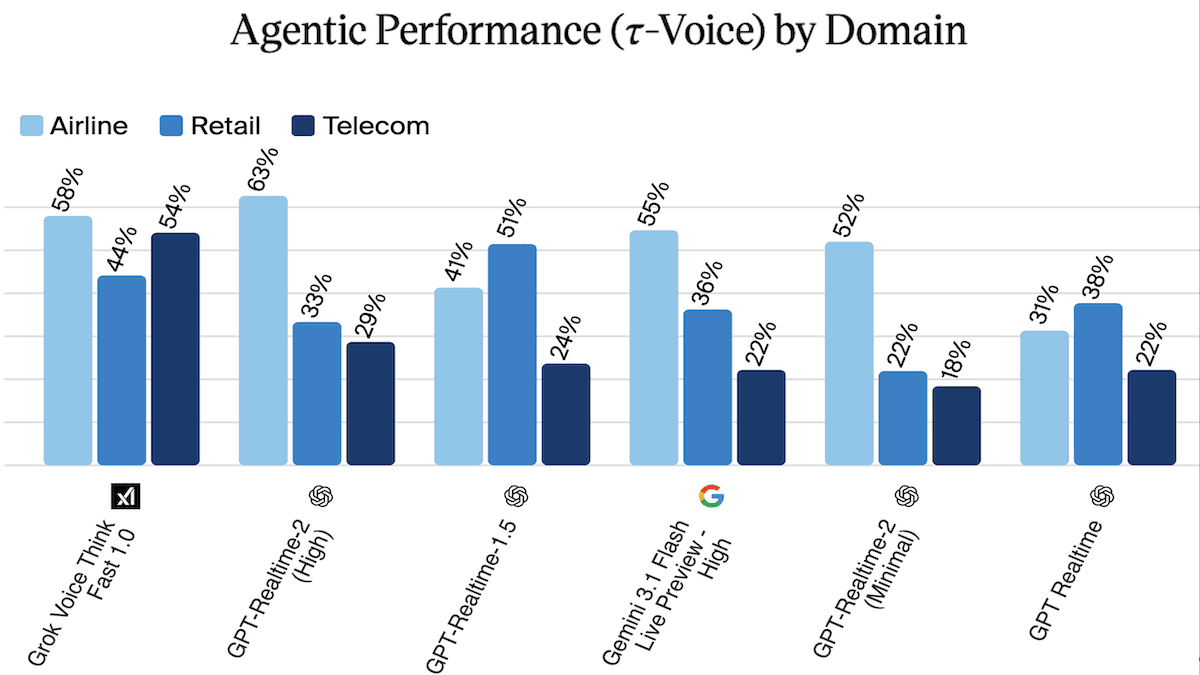
An update of OpenAI’s speech-to-speech model lets developers tune the tradeoff between speed and reasoning.

May 15, 20264 min read
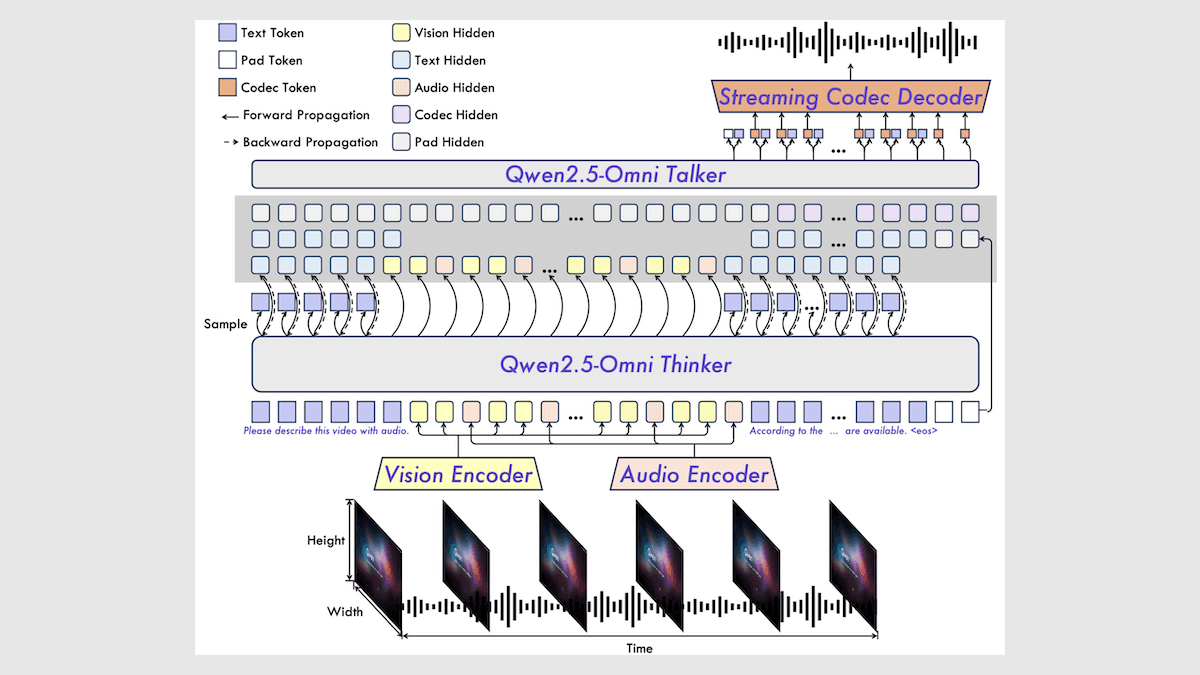
Better Multimodal Performance With Open Weights: Qwen2.5-Omni 7B raises the bar for small multimodal models
Speech Recognition

Better Multimodal Performance With Open Weights: Qwen2.5-Omni 7B raises the bar for small multimodal models

Alibaba’s latest open-weights system raises the bar for multimodal tasks in a relatively small model.

April 9, 20253 min read
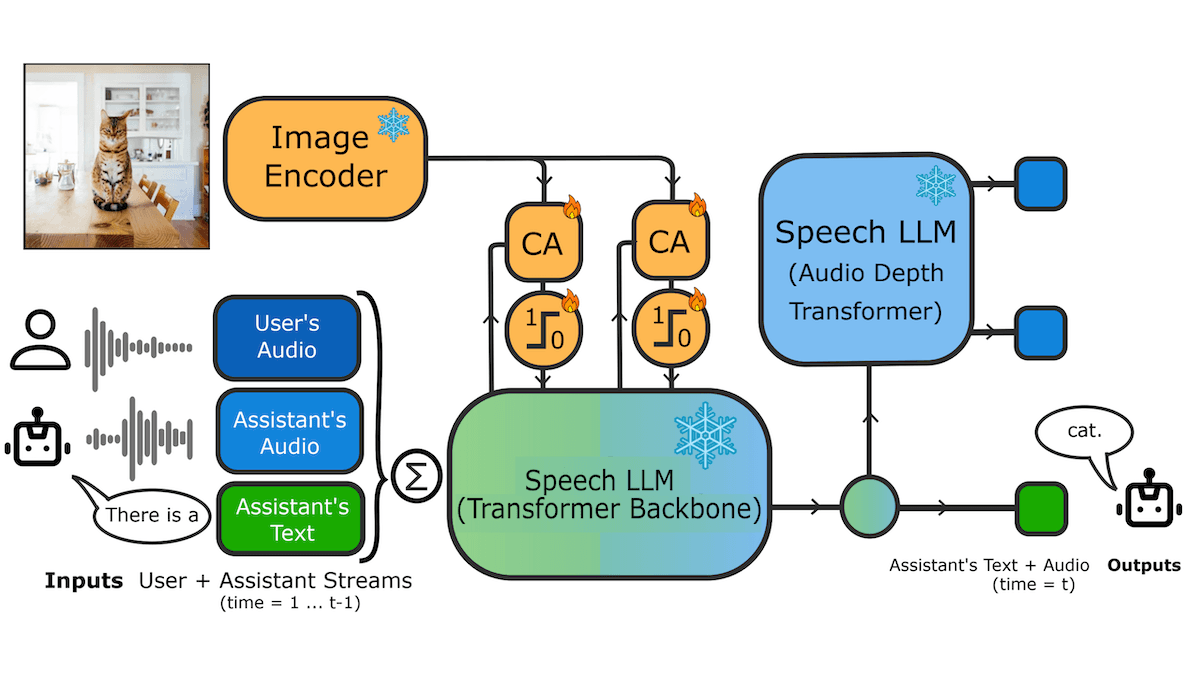
Interactive Voice-to-Voice With Vision: MoshiVis adds image understanding to voice-first conversations
Speech Recognition

Interactive Voice-to-Voice With Vision: MoshiVis adds image understanding to voice-first conversations

Researchers updated the highly responsive Moshi voice-to-voice model to discuss visual input.

April 2, 20253 min read
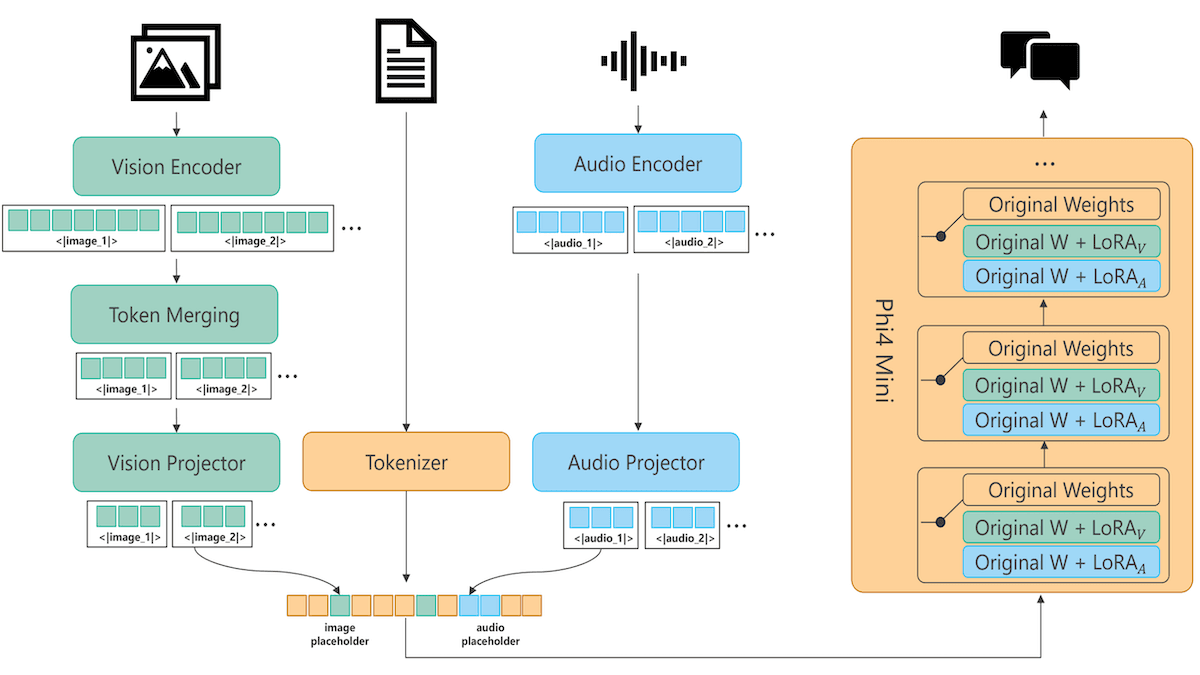
Microsoft Tackles Voice-In, Text-Out: Microsoft’s Phi-4 Multimodal model can process text, images, and speech simultaneously
Speech Recognition

Microsoft Tackles Voice-In, Text-Out: Microsoft’s Phi-4 Multimodal model can process text, images, and speech simultaneously

Microsoft debuted its first official large language model that responds to spoken input.

March 12, 20253 min read
Microsoft Tackles Voice-In, Text-Out: Microsoft’s Phi-4 Multimodal model can process text, images, and speech simultaneously
Speech Recognition

Microsoft Tackles Voice-In, Text-Out: Microsoft’s Phi-4 Multimodal model can process text, images, and speech simultaneously

Microsoft debuted its first official large language model that responds to spoken input.

March 12, 20253 min read
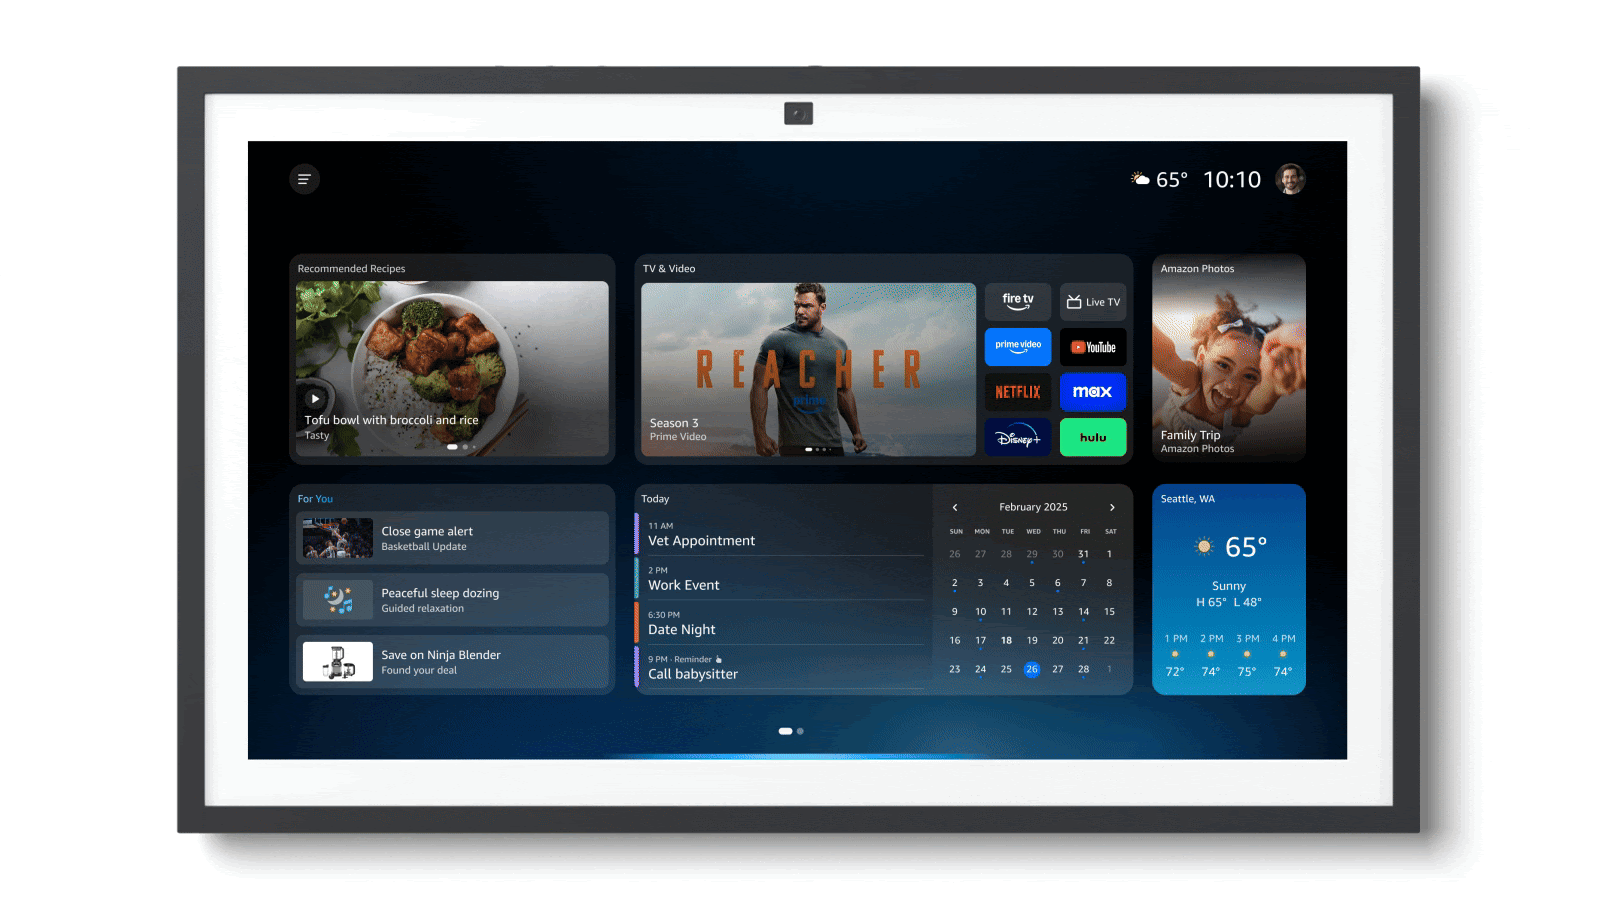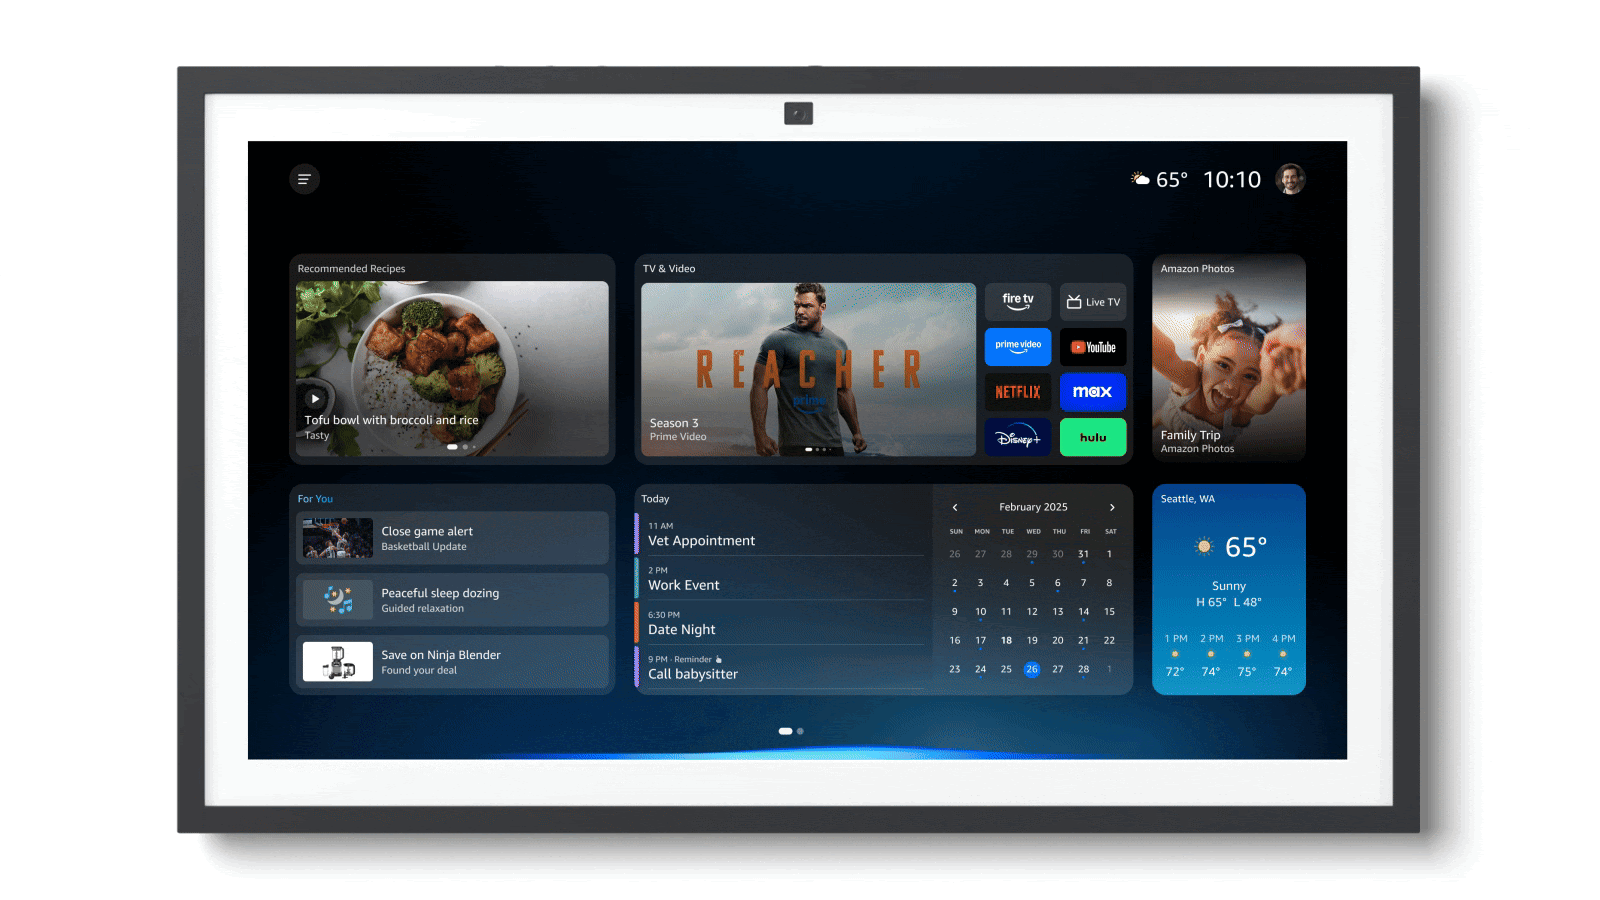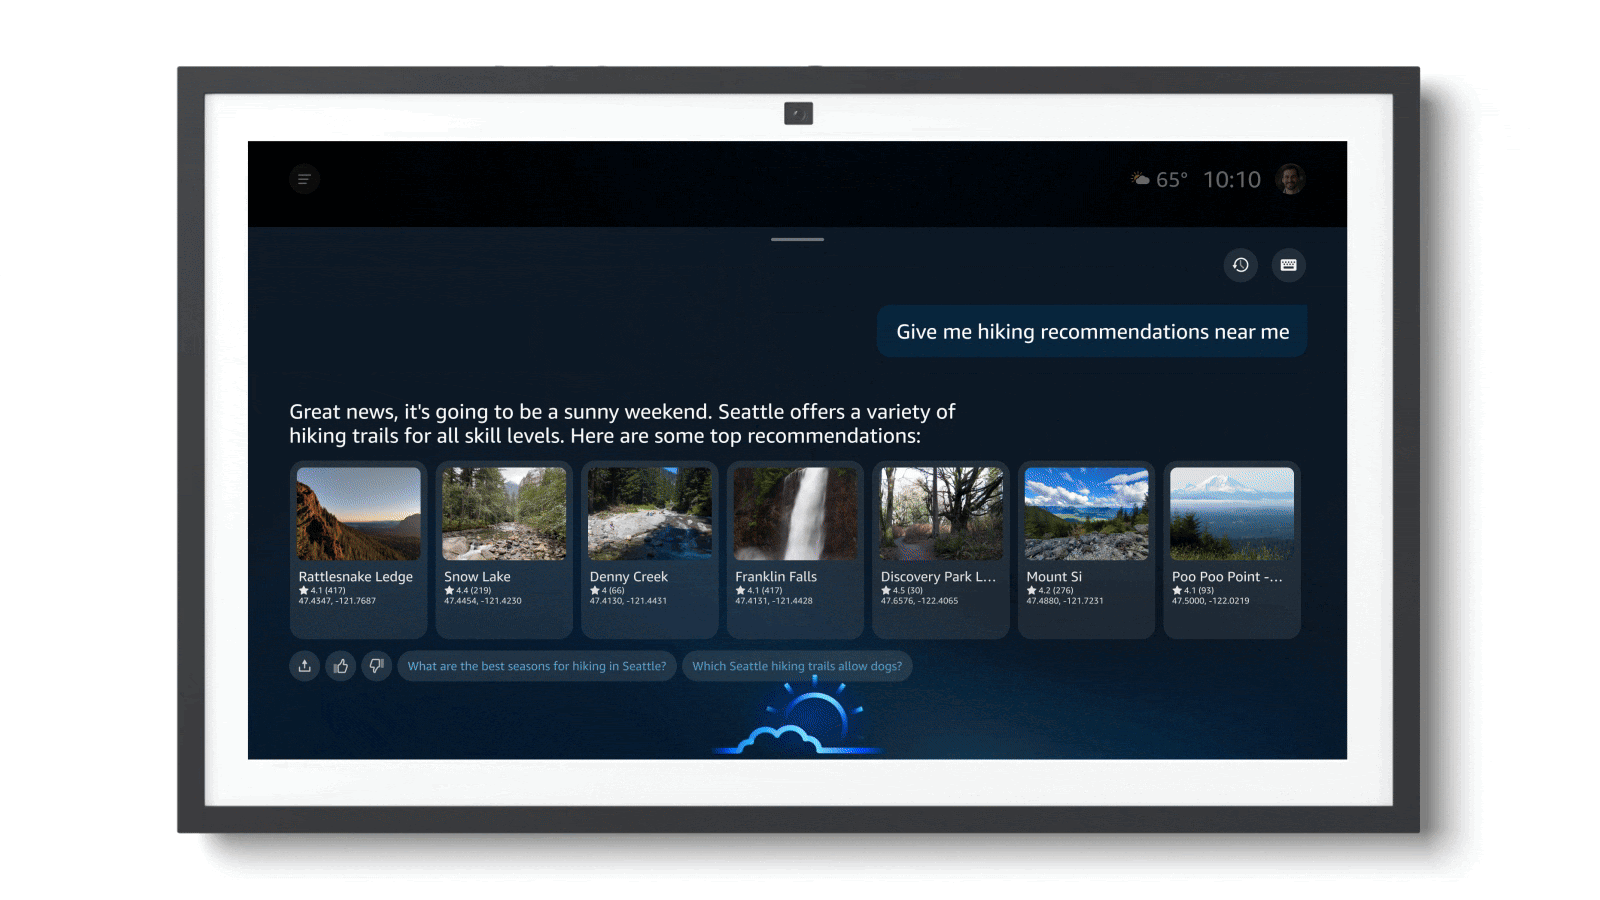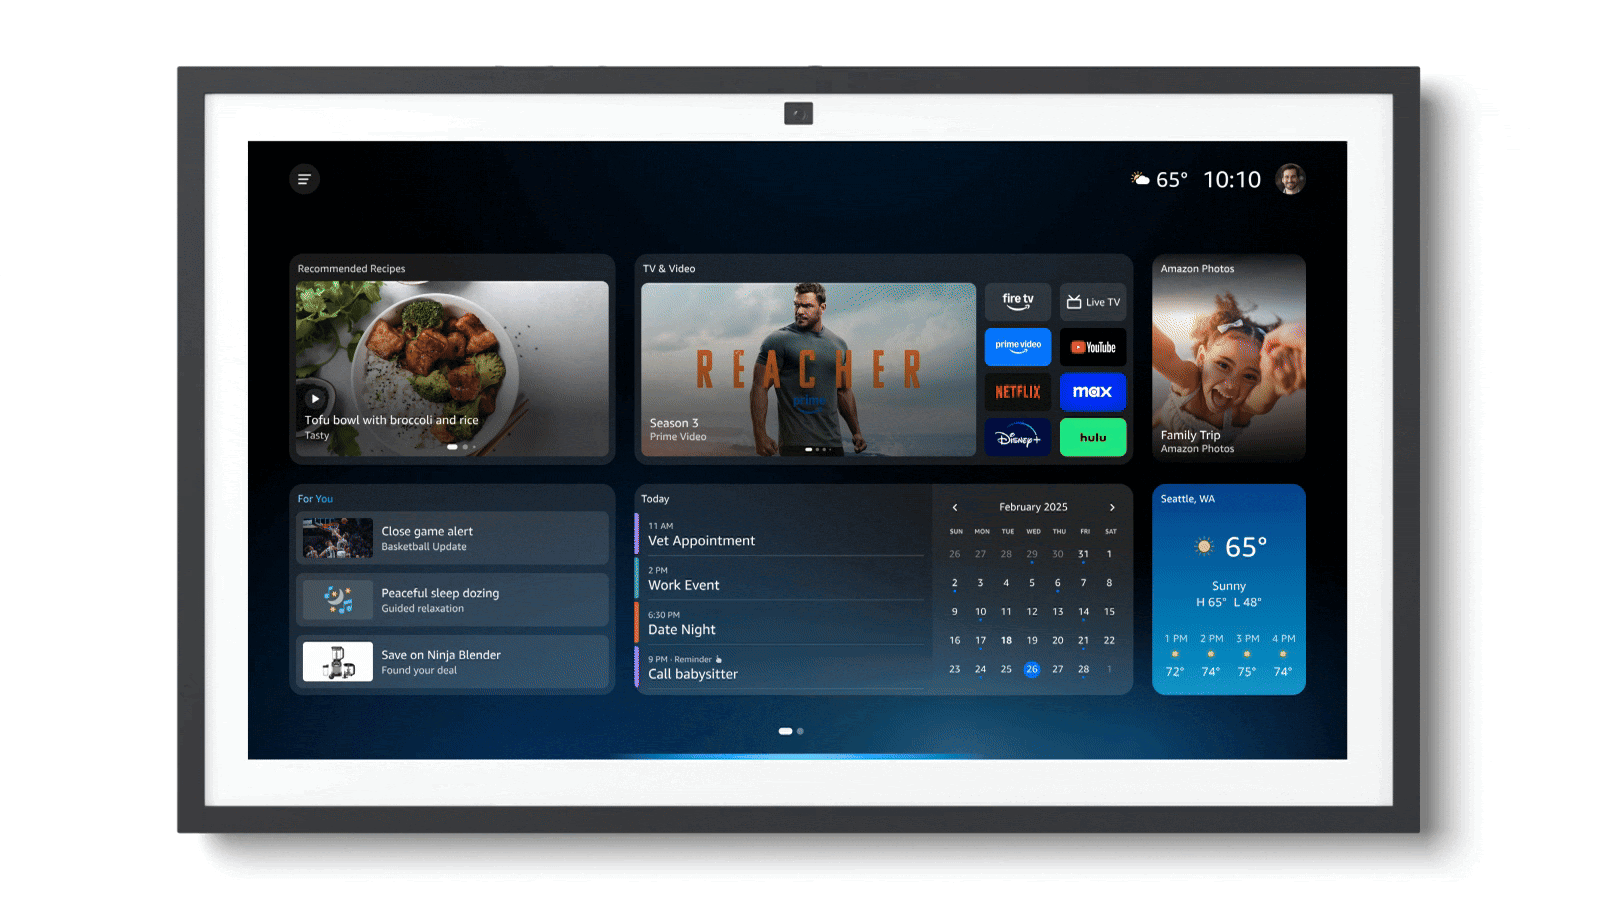
Amazon’s Next-Gen Voice Assistant: Alexa+ adds generative AI and agents, using Claude and other models
Speech Recognition

Amazon’s Next-Gen Voice Assistant: Alexa+ adds generative AI and agents, using Claude and other models

Amazon announced Alexa+, a major upgrade to its long-running voice assistant.

March 5, 20252 min read
Amazon’s Next-Gen Voice Assistant: Alexa+ adds generative AI and agents, using Claude and other models
Speech Recognition

Amazon’s Next-Gen Voice Assistant: Alexa+ adds generative AI and agents, using Claude and other models

Amazon announced Alexa+, a major upgrade to its long-running voice assistant.

March 5, 20252 min read
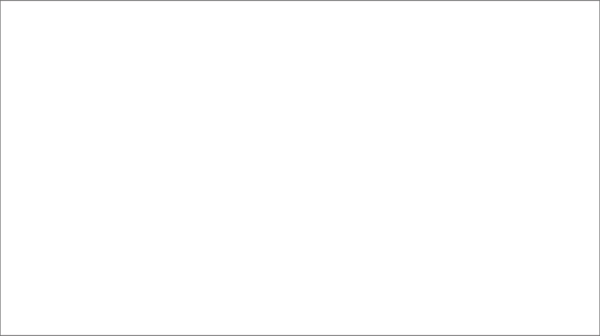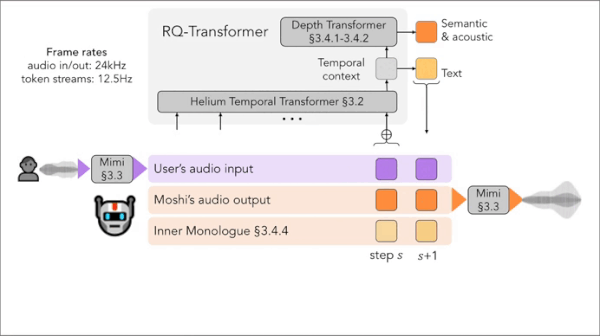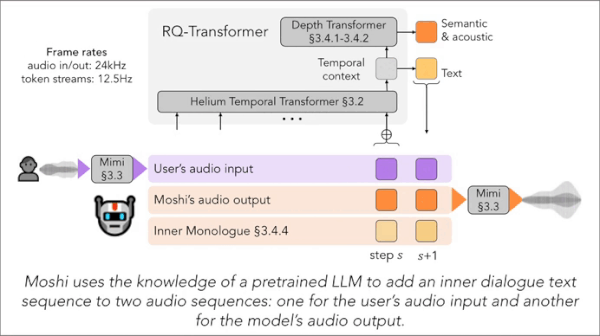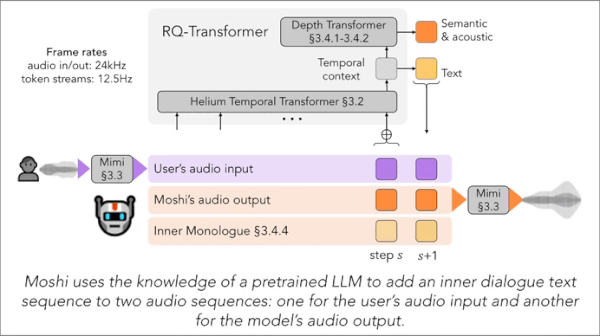
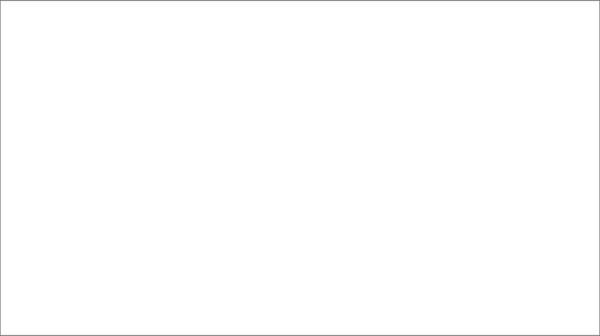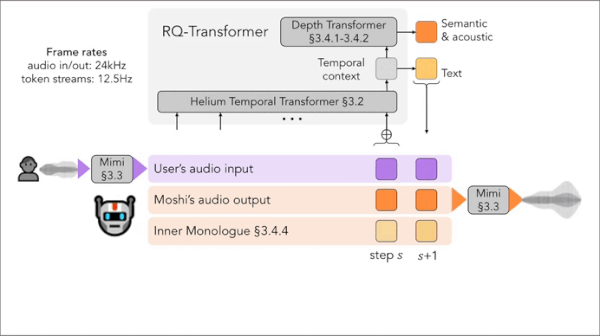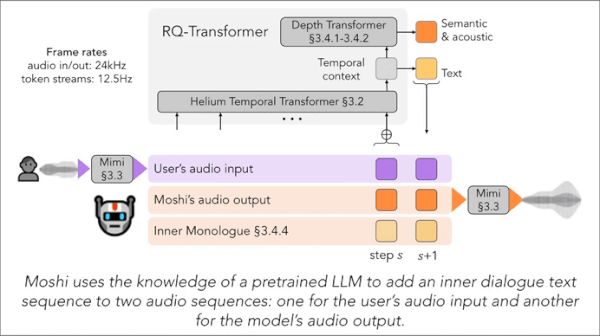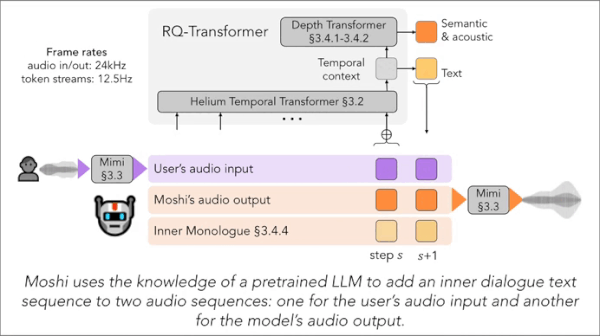
Okay, But Please Don’t Stop Talking: Moshi, an open alternative to OpenAI’s Realtime models for speech
Speech Recognition

Okay, But Please Don’t Stop Talking: Moshi, an open alternative to OpenAI’s Realtime models for speech

Even cutting-edge, end-to-end, speech-to-speech systems like ChatGPT’s Advanced Voice Mode tend to get interrupted by interjections like “I see” and “uh-huh” that keep human conversations going. Researchers built an open alternative that’s designed to go with the flow of overlapping speech.

February 5, 20253 min read
Okay, But Please Don’t Stop Talking: Moshi, an open alternative to OpenAI’s Realtime API for Speech
Speech Recognition

Okay, But Please Don’t Stop Talking: Moshi, an open alternative to OpenAI’s Realtime API for Speech

Even cutting-edge, end-to-end, speech-to-speech systems like ChatGPT’s Advanced Voice Mode tend to get interrupted by interjections like “I see” and “uh-huh” that keep human conversations going. Researchers built an open alternative that’s designed to go with the flow of overlapping speech.

February 5, 20253 min read
Your Personal Deepfaked Agent: This GPT-powered voice tool will talk to customer service for you.
Speech Recognition

Your Personal Deepfaked Agent: This GPT-powered voice tool will talk to customer service for you.

Hate talking to customer service? An AI-powered tool may soon do it for you. Joshua Browder, chief executive of the consumer advocacy organization DoNotPay, demonstrated a system that autonomously navigates phone menus and converses...

January 11, 20231 min read
Your Personal Deepfaked Agent: This GPT-powered voice tool will talk to customer service for you.
Speech Recognition

Your Personal Deepfaked Agent: This GPT-powered voice tool will talk to customer service for you.

Hate talking to customer service? An AI-powered tool may soon do it for you. Joshua Browder, chief executive of the consumer advocacy organization DoNotPay, demonstrated a system that autonomously navigates phone menus and converses...

January 11, 20231 min read
Transparency for AI as a Service: Amazon introduces service cards to enhance responsible AI.
Speech Recognition

Transparency for AI as a Service: Amazon introduces service cards to enhance responsible AI.

Amazon published a series of web pages designed to help people use AI responsibly. Amazon Web Services introduced so-called AI service cards that describe the uses and limitations of some models it serves.

January 4, 20232 min read
Transparency for AI as a Service: Amazon introduces service cards to enhance responsible AI.
Speech Recognition

Transparency for AI as a Service: Amazon introduces service cards to enhance responsible AI.

Amazon published a series of web pages designed to help people use AI responsibly. Amazon Web Services introduced so-called AI service cards that describe the uses and limitations of some models it serves.

January 4, 20232 min read
Translating a Mostly Oral Language: How Meta Trained an NLP Model to Translate Hokkein
Speech Recognition

Translating a Mostly Oral Language: How Meta Trained an NLP Model to Translate Hokkein

Most speech-to-speech translation systems use text as an intermediate mode. So how do you build an automated translator for a language that has no standard written form? A new approach trained neural networks to translate a primarily oral language.

November 30, 20223 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox