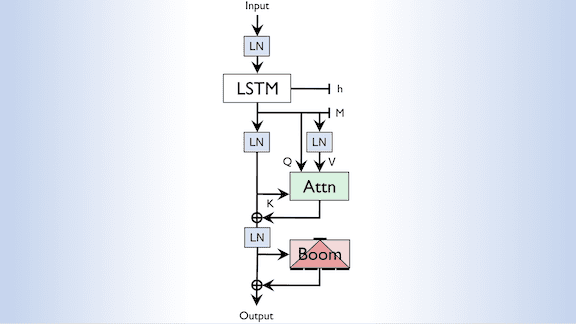
Single Headed Attention RNN (SHA-RNN)

2 Posts

Language Modeling on One GPU: Single-headed attention competes with transformers.
Single Headed Attention RNN (SHA-RNN)

Language Modeling on One GPU: Single-headed attention competes with transformers.

The latest large, pretrained language models rely on trendy layers based on transformer networks. New research shows that these newfangled layers may not be necessary.
January 8, 20202 min read
Language Modeling on One GPU: Single-headed attention competes with transformers.
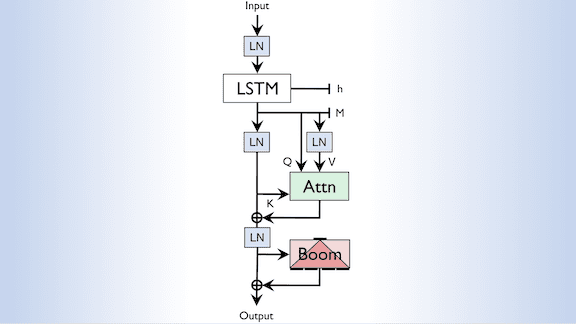
Single Headed Attention RNN (SHA-RNN)

Language Modeling on One GPU: Single-headed attention competes with transformers.

The latest large, pretrained language models rely on trendy layers based on transformer networks. New research shows that these newfangled layers may not be necessary.

January 8, 20202 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox