Shapley Additive Explanations (SHAP)

2 Posts

Bias Goes Undercover: Adversarial attacks can fool explainable AI techniques.
Shapley Additive Explanations (SHAP)

Bias Goes Undercover: Adversarial attacks can fool explainable AI techniques.

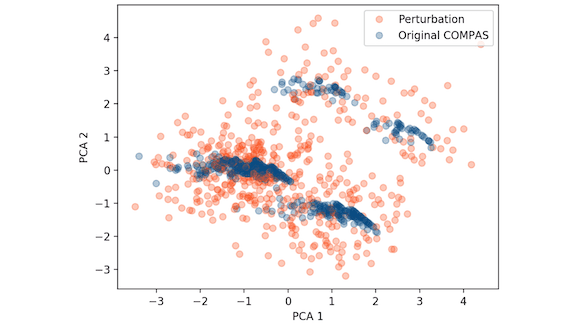
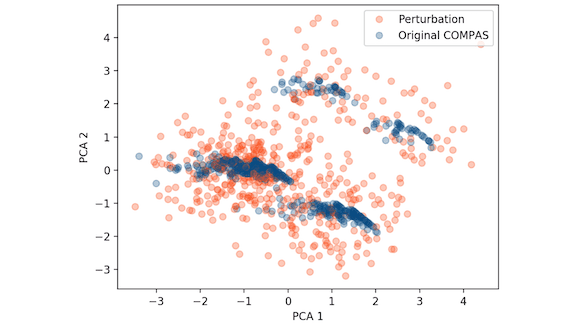
As black-box algorithms like neural networks find their way into high-stakes fields such as transportation, healthcare, and finance, researchers have developed techniques to help explain models’ decisions. New findings show that some of these methods can be fooled.
November 27, 20192 min read
Bias Goes Undercover: Adversarial attacks can fool explainable AI techniques.
Shapley Additive Explanations (SHAP)

Bias Goes Undercover: Adversarial attacks can fool explainable AI techniques.

As black-box algorithms like neural networks find their way into high-stakes fields such as transportation, healthcare, and finance, researchers have developed techniques to help explain models’ decisions. New findings show that some of these methods can be fooled.

November 27, 20192 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox