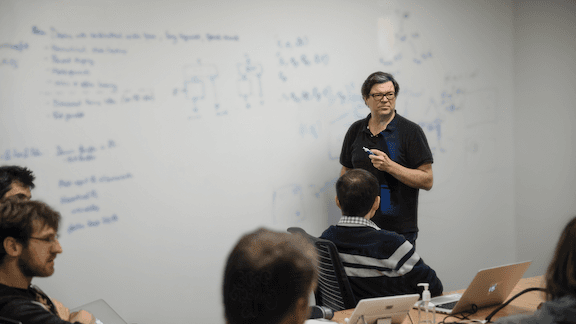
Yann LeCun — Learning From Observation: The power of self-supervised learning
Reinforcement Learning

Yann LeCun — Learning From Observation: The power of self-supervised learning

How is it that many people learn to drive a car fairly safely in 20 hours of practice, while current imitation learning algorithms take hundreds of thousands of hours, and reinforcement learning algorithms take millions of hours? Clearly we’re missing something big.

January 1, 20202 min read
Chelsea Finn — Robots That Generalize: Generalization for robotics through reinforcement learning
Reinforcement Learning

Chelsea Finn — Robots That Generalize: Generalization for robotics through reinforcement learning

Many people in the AI community focus on achieving flashy results, like building an agent that can win at Go or Jeopardy. This kind of work is impressive in terms of complexity.

January 1, 20202 min read
Chelsea Finn — Robots That Generalize: Generalization for robotics through reinforcement learning
Reinforcement Learning

Chelsea Finn — Robots That Generalize: Generalization for robotics through reinforcement learning

Many people in the AI community focus on achieving flashy results, like building an agent that can win at Go or Jeopardy. This kind of work is impressive in terms of complexity.

January 1, 20202 min read
Anima Anandkumar — The Power of Simulation: How simulation can be useful for supervised learning
Reinforcement Learning

Anima Anandkumar — The Power of Simulation: How simulation can be useful for supervised learning

We’ve had great success with supervised deep learning on labeled data. Now it’s time to explore other ways to learn: training on unlabeled data, lifelong learning, and especially letting models explore a simulated environment before transferring what they learn to the real world.

January 1, 20202 min read
Anima Anandkumar — The Power of Simulation: How simulation can be useful for supervised learning
Reinforcement Learning

Anima Anandkumar — The Power of Simulation: How simulation can be useful for supervised learning

We’ve had great success with supervised deep learning on labeled data. Now it’s time to explore other ways to learn: training on unlabeled data, lifelong learning, and especially letting models explore a simulated environment before transferring what they learn to the real world.

January 1, 20202 min read
Simulation Substitutes for Data: When simulation works wonders with deep learning
Reinforcement Learning

Simulation Substitutes for Data: When simulation works wonders with deep learning

The future of machine learning may depend less on amassing ground-truth data than simulating the environment in which a model will operate. Deep learning works like magic with enough high-quality data. When examples are scarce, though, researchers are using simulation to fill the gap.

December 24, 20191 min read
Simulation Substitutes for Data: When simulation works wonders with deep learning
Reinforcement Learning

Simulation Substitutes for Data: When simulation works wonders with deep learning

The future of machine learning may depend less on amassing ground-truth data than simulating the environment in which a model will operate. Deep learning works like magic with enough high-quality data. When examples are scarce, though, researchers are using simulation to fill the gap.

December 24, 20191 min read
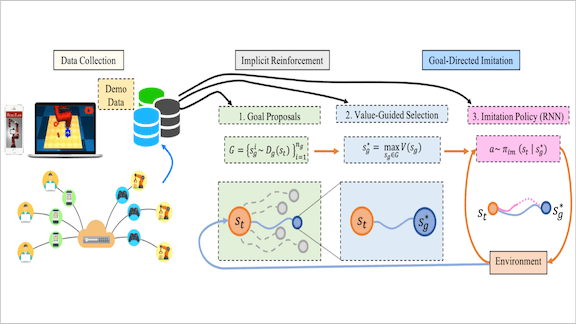
Different Skills From Different Demos: Implicit reinforcement without interaction at scale, explained
Reinforcement Learning

Different Skills From Different Demos: Implicit reinforcement without interaction at scale, explained

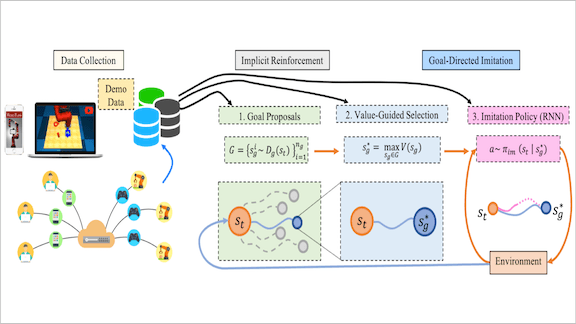
Reinforcement learning trains models by trial and error. In batch reinforcement learning (BRL), models learn by observing many demonstrations by a variety of actors. But what if one doctor is handier with a scalpel while another excels at suturing?

December 18, 20192 min read
Different Skills From Different Demos: Implicit reinforcement without interaction at scale, explained
Reinforcement Learning

Different Skills From Different Demos: Implicit reinforcement without interaction at scale, explained

Reinforcement learning trains models by trial and error. In batch reinforcement learning (BRL), models learn by observing many demonstrations by a variety of actors. But what if one doctor is handier with a scalpel while another excels at suturing?

December 18, 20192 min read
Seeing the World Blindfolded: The observational dropout technique, explained
Reinforcement Learning

Seeing the World Blindfolded: The observational dropout technique, explained

In reinforcement learning, if researchers want an agent to have an internal representation of its environment, they’ll build and train a world model that it can refer to. New research shows that world models can emerge from standard training, rather than needing to be built separately.

December 11, 20192 min read
Seeing the World Blindfolded: The observational dropout technique, explained
Reinforcement Learning

Seeing the World Blindfolded: The observational dropout technique, explained

In reinforcement learning, if researchers want an agent to have an internal representation of its environment, they’ll build and train a world model that it can refer to. New research shows that world models can emerge from standard training, rather than needing to be built separately.

December 11, 20192 min read
Is AI Making Mastery Obsolete?: How human chess and go masters cope with being beaten by AI
Reinforcement Learning

Is AI Making Mastery Obsolete?: How human chess and go masters cope with being beaten by AI

Is there any reason to continue playing games that AI has mastered? Ask the former champions who have been toppled by machines.

December 4, 20191 min read
Is AI Making Mastery Obsolete?: How human chess and go masters cope with being beaten by AI
Reinforcement Learning

Is AI Making Mastery Obsolete?: How human chess and go masters cope with being beaten by AI

Is there any reason to continue playing games that AI has mastered? Ask the former champions who have been toppled by machines.

December 4, 20191 min read
Melding Transformers with RL: GTrXL combines transformers and reinforcement learning.
Reinforcement Learning

Melding Transformers with RL: GTrXL combines transformers and reinforcement learning.

Large NLP models like BERT can answer questions about a document thanks to the transformer network, a sequence-processing architecture that retains information across much longer sequences than previous methods. But transformers have had little success in reinforcement learning — until now.

November 27, 20192 min read
Melding Transformers with RL: GTrXL combines transformers and reinforcement learning.
Reinforcement Learning

Melding Transformers with RL: GTrXL combines transformers and reinforcement learning.

Large NLP models like BERT can answer questions about a document thanks to the transformer network, a sequence-processing architecture that retains information across much longer sequences than previous methods. But transformers have had little success in reinforcement learning — until now.

November 27, 20192 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox