Reinforcement Learning

155 Posts

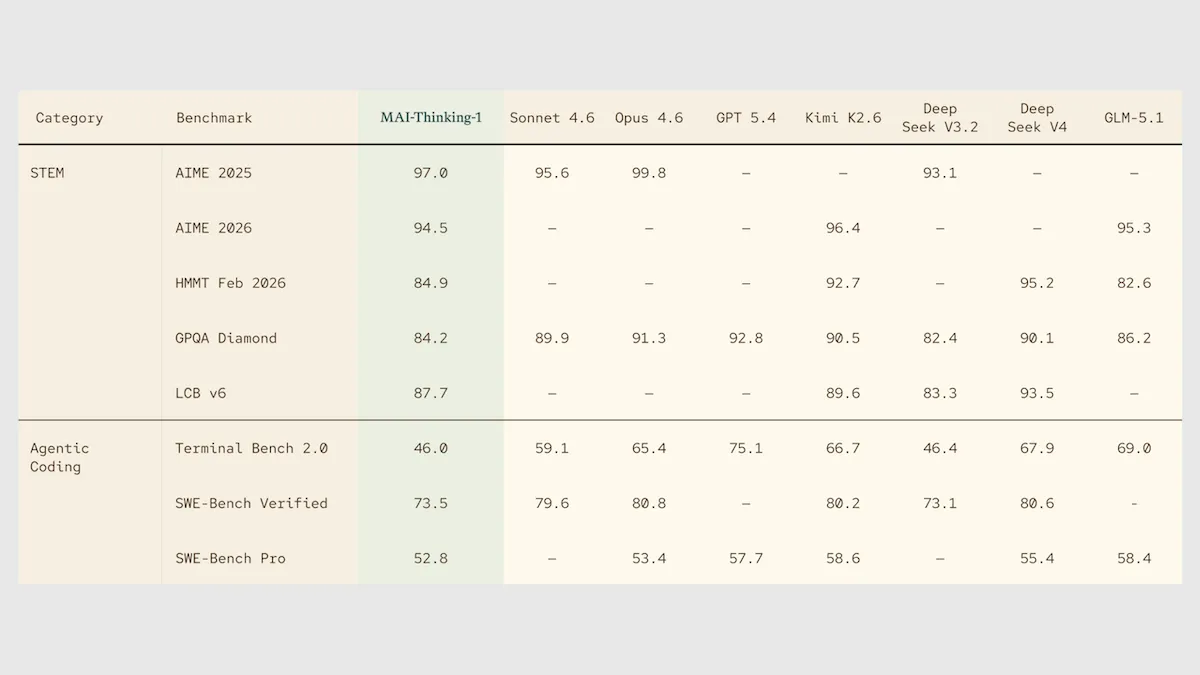
Microsoft Strikes Out on Its Own: Microsoft revealed MAI-Thinking-1, a Claude Sonnet 4.6-sized reasoning model developed without distillation
Reinforcement Learning

Microsoft Strikes Out on Its Own: Microsoft revealed MAI-Thinking-1, a Claude Sonnet 4.6-sized reasoning model developed without distillation

Microsoft, once OpenAI’s exclusive partner and still a major reseller of other companies’ AI models, built its own reasoning model from scratch.
July 3, 20263 min read
Reinforcement Learning With Hints: Privileged On-Policy Exploration (POPE) trains models to expand on partial solutions
Reinforcement Learning

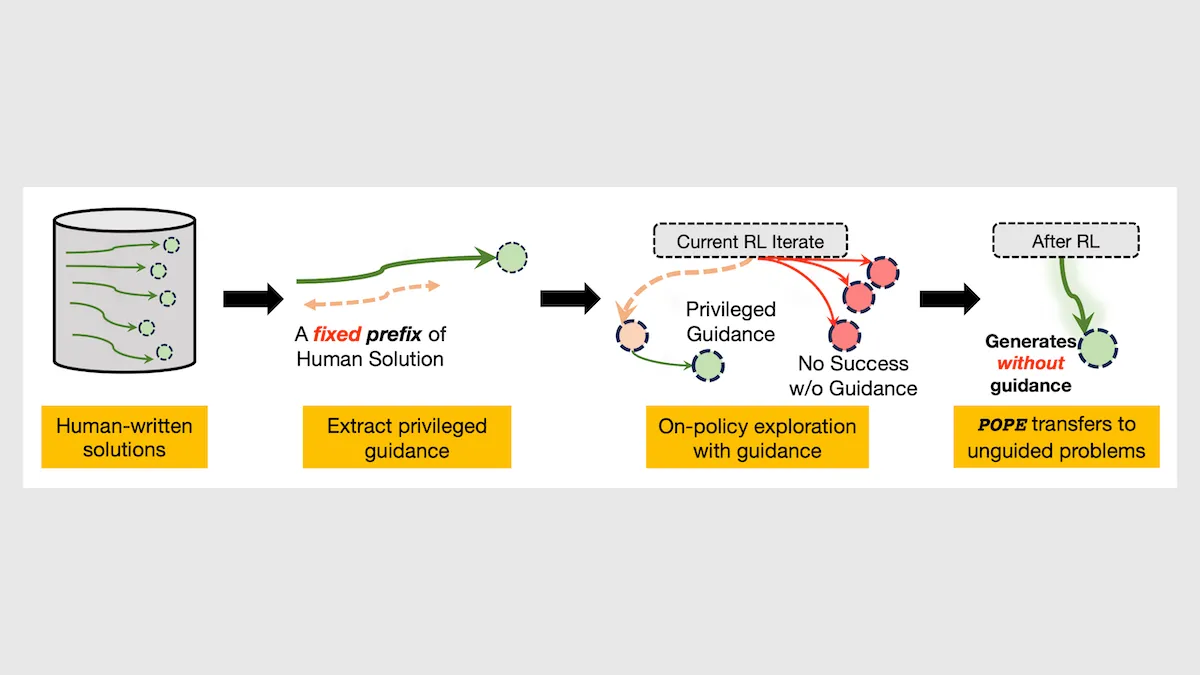
Reinforcement Learning With Hints: Privileged On-Policy Exploration (POPE) trains models to expand on partial solutions

Reinforcement learning can’t train a model to solve a difficult problem if the model doesn’t discover all the right steps.

June 19, 20263 min read
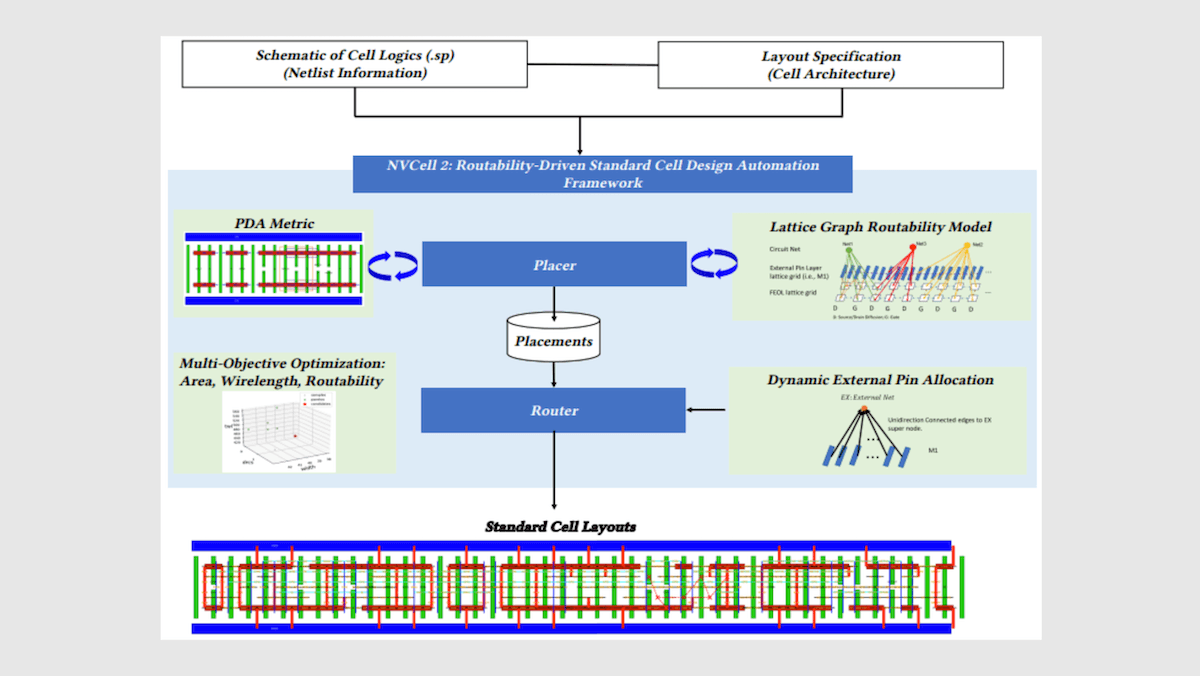
How Nvidia Uses AI to Design Chips: Chipmaker's models design circuits, verify designs, and test new layouts
Reinforcement Learning

How Nvidia Uses AI to Design Chips: Chipmaker's models design circuits, verify designs, and test new layouts

Nvidia’s chief scientist dreams of telling an AI model to design a new GPU, then skiing for a couple days while the system does the job.

May 8, 20263 min read
Faster Reinforcement Learning: New technique auto-selects training examples to speed up fine-tuning
Reinforcement Learning

Faster Reinforcement Learning: New technique auto-selects training examples to speed up fine-tuning

Fine-tuning large language models via reinforcement learning is computationally expensive, but researchers found a way to streamline the process.

September 24, 20252 min read
Robot Antelope Joins Herd: Chinese scientists disguise modified robot dog as antelope to study herd behavior
Reinforcement Learning

Robot Antelope Joins Herd: Chinese scientists disguise modified robot dog as antelope to study herd behavior

Researchers in China disguised a quadruped robot as a Tibetan antelope to help study the animals close-up.

August 27, 20252 min read
Robo-Football From Simulation to Reality: Reinforcement learning powers humanoid robots to play football
Reinforcement Learning

Robo-Football From Simulation to Reality: Reinforcement learning powers humanoid robots to play football

Humanoid robots can play football (known as soccer in the United States) in the real world, thanks to reinforcement learning.

March 27, 20243 min read
Robo-Football From Simulation to Reality: Reinforcement learning powers humanoid robots to play football
Reinforcement Learning

Robo-Football From Simulation to Reality: Reinforcement learning powers humanoid robots to play football

Humanoid robots can play football (known as soccer in the United States) in the real world, thanks to reinforcement learning.

March 27, 20243 min read
Learning Language by Exploration: Agent develops language skills through simulated exploration tasks
Reinforcement Learning

Learning Language by Exploration: Agent develops language skills through simulated exploration tasks

Machine learning models typically learn language by training on tasks like predicting the next word in a given text. Researchers trained a language model in a less focused, more human-like way.

March 13, 20243 min read
Learning Language by Exploration: Agent develops language skills through simulated exploration tasks
Reinforcement Learning

Learning Language by Exploration: Agent develops language skills through simulated exploration tasks

Machine learning models typically learn language by training on tasks like predicting the next word in a given text. Researchers trained a language model in a less focused, more human-like way.

March 13, 20243 min read
AI Builds Better Sorting Algorithms: AlphaDev, a new system for high-speed sorting of lists and numbers
Reinforcement Learning

AI Builds Better Sorting Algorithms: AlphaDev, a new system for high-speed sorting of lists and numbers

Online sorting algorithms run trillions of times a day to organize lists according to users’ interests. New work found faster alternatives. Daniel J. Mankowitz and colleagues at Google developed AlphaDev, a system that learned to generate algorithms that sort three...

November 15, 20233 min read
AI Builds Better Sorting Algorithms: AlphaDev, a new system for high-speed sorting of lists and numbers
Reinforcement Learning

AI Builds Better Sorting Algorithms: AlphaDev, a new system for high-speed sorting of lists and numbers

Online sorting algorithms run trillions of times a day to organize lists according to users’ interests. New work found faster alternatives. Daniel J. Mankowitz and colleagues at Google developed AlphaDev, a system that learned to generate algorithms that sort three...

November 15, 20233 min read
Stratego Master: DeepNash, the RL system that plays Stratego like a master
Reinforcement Learning

Stratego Master: DeepNash, the RL system that plays Stratego like a master

Reinforcement learning agents have mastered games like Go that provide complete information about the state of the game to players. They’ve also excelled at Texas Hold ’Em poker, which provides incomplete information, as few cards are revealed.

July 26, 20233 min read
Stratego Master: DeepNash, the RL system that plays Stratego like a master
Reinforcement Learning

Stratego Master: DeepNash, the RL system that plays Stratego like a master

Reinforcement learning agents have mastered games like Go that provide complete information about the state of the game to players. They’ve also excelled at Texas Hold ’Em poker, which provides incomplete information, as few cards are revealed.

July 26, 20233 min read
Bug Finder: A system that provides feedback with near human-level accuracy
Reinforcement Learning

Bug Finder: A system that provides feedback with near human-level accuracy

One challenge to making online education available worldwide is evaluating an immense volume of student work. Especially difficult is evaluating interactive computer programming assignments such as coding a game.

July 5, 20233 min read
Bug Finder: A system that provides feedback with near human-level accuracy
Reinforcement Learning

Bug Finder: A system that provides feedback with near human-level accuracy

One challenge to making online education available worldwide is evaluating an immense volume of student work. Especially difficult is evaluating interactive computer programming assignments such as coding a game.

July 5, 20233 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox