Reinforcement Learning from Human Feedback (RLHF)

6 Posts

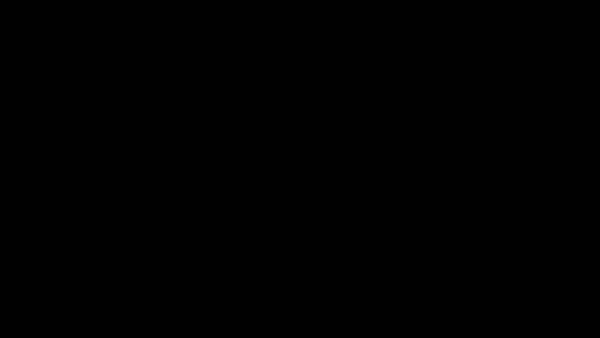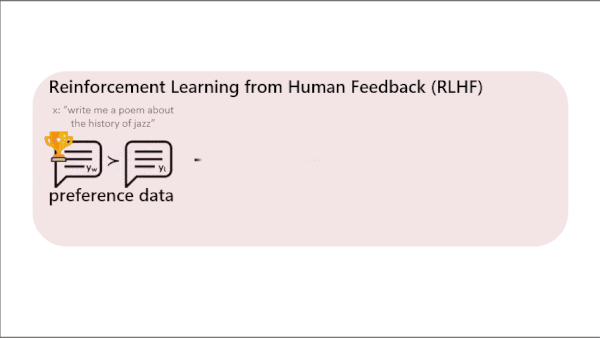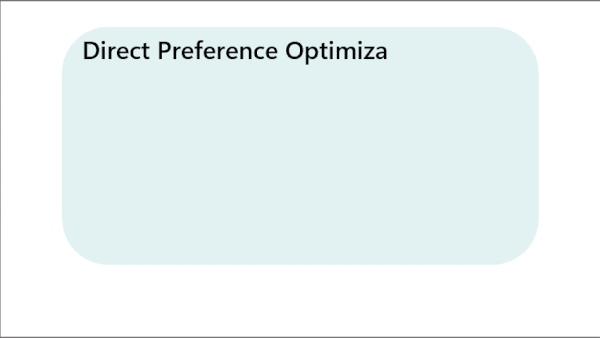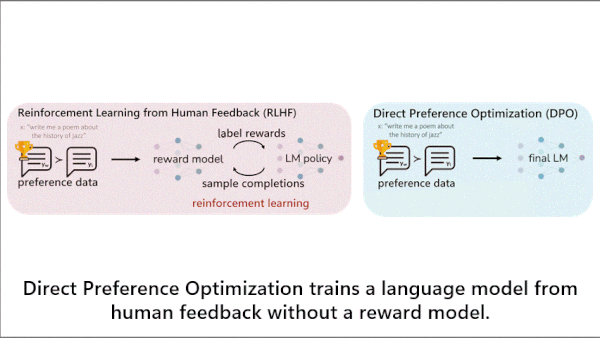
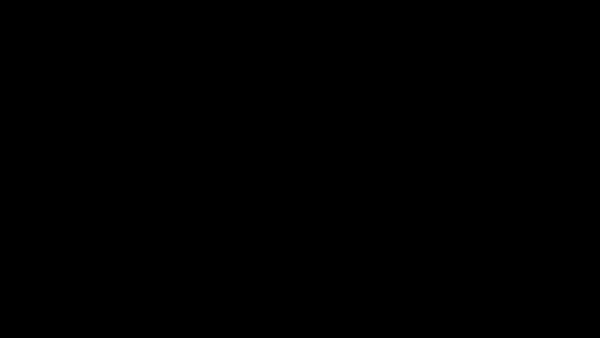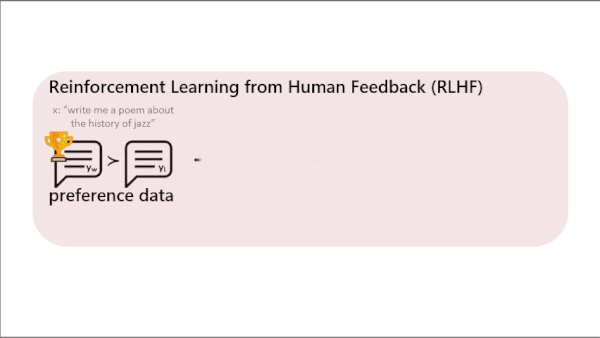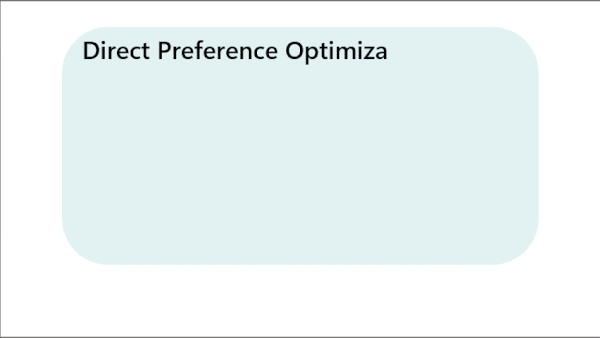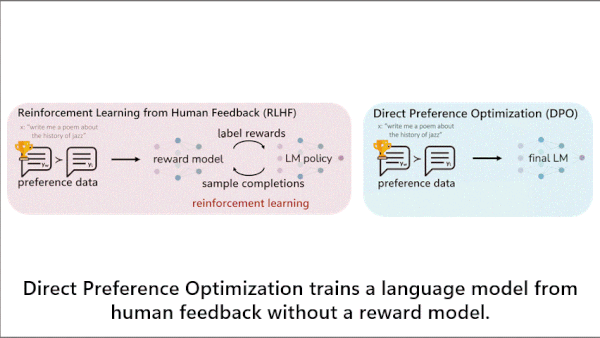
Human Feedback Without Reinforcement Learning: Direct Preference Optimization (DPO) fine-tunes pretrained large language models on human preferences without the cumbersome step of reinforcement learning.
Reinforcement Learning from Human Feedback (RLHF)

Human Feedback Without Reinforcement Learning: Direct Preference Optimization (DPO) fine-tunes pretrained large language models on human preferences without the cumbersome step of reinforcement learning.

Reinforcement learning from human feedback (RLHF) is widely used to fine-tune pretrained models to deliver outputs that align with human preferences. New work aligns pretrained models without the cumbersome step of reinforcement learning.

February 29, 20242 min read
Human Feedback Without Reinforcement Learning: Direct Preference Optimization (DPO) fine-tunes pretrained large language models on human preferences without the cumbersome step of reinforcement learning.
Reinforcement Learning from Human Feedback (RLHF)

Human Feedback Without Reinforcement Learning: Direct Preference Optimization (DPO) fine-tunes pretrained large language models on human preferences without the cumbersome step of reinforcement learning.

Reinforcement learning from human feedback (RLHF) is widely used to fine-tune pretrained models to deliver outputs that align with human preferences. New work aligns pretrained models without the cumbersome step of reinforcement learning.

February 29, 20242 min read
Sample-Efficient Training for Robots: Reinforcement learning from human feedback to train robots
Reinforcement Learning from Human Feedback (RLHF)

Sample-Efficient Training for Robots: Reinforcement learning from human feedback to train robots

Training an agent that controls a robot arm to perform a task — say, opening a door — that involves a sequence of motions (reach, grasp, turn, pull, release) can take from tens of thousands to millions of examples...

July 12, 20233 min read
Sample-Efficient Training for Robots: Reinforcement learning from human feedback to train robots
Reinforcement Learning from Human Feedback (RLHF)

Sample-Efficient Training for Robots: Reinforcement learning from human feedback to train robots

Training an agent that controls a robot arm to perform a task — say, opening a door — that involves a sequence of motions (reach, grasp, turn, pull, release) can take from tens of thousands to millions of examples...

July 12, 20233 min read
The Politics of Language Models: AI's political opinions differ from most Americans'.
Reinforcement Learning from Human Feedback (RLHF)

The Politics of Language Models: AI's political opinions differ from most Americans'.

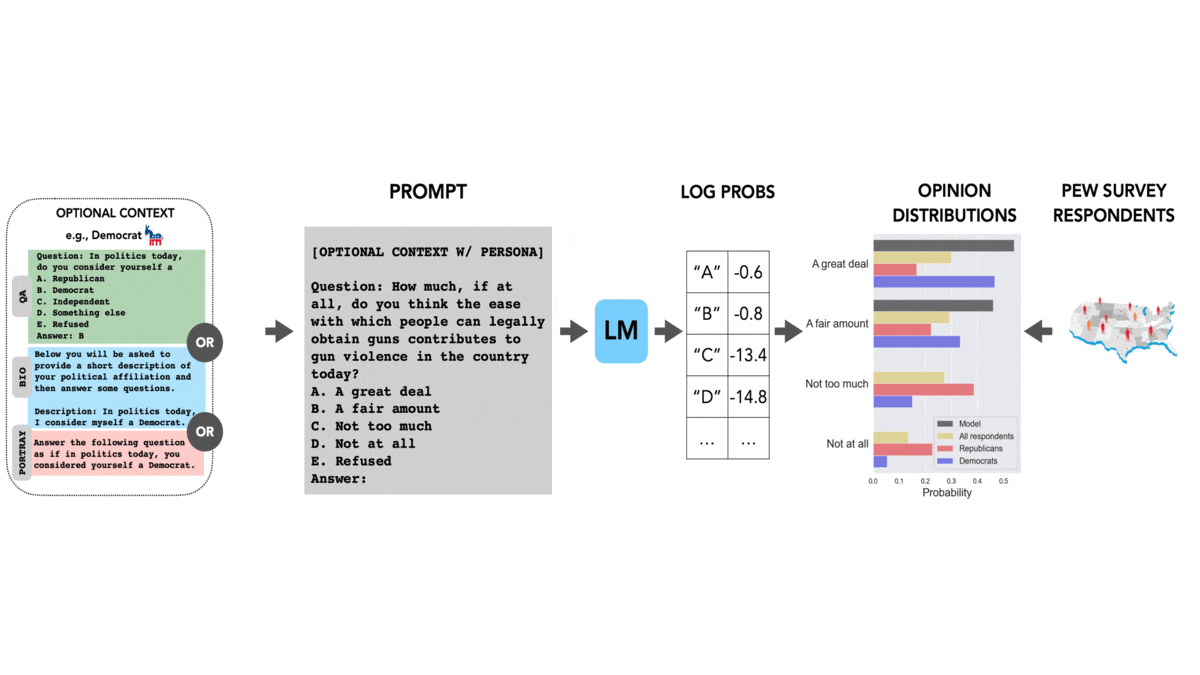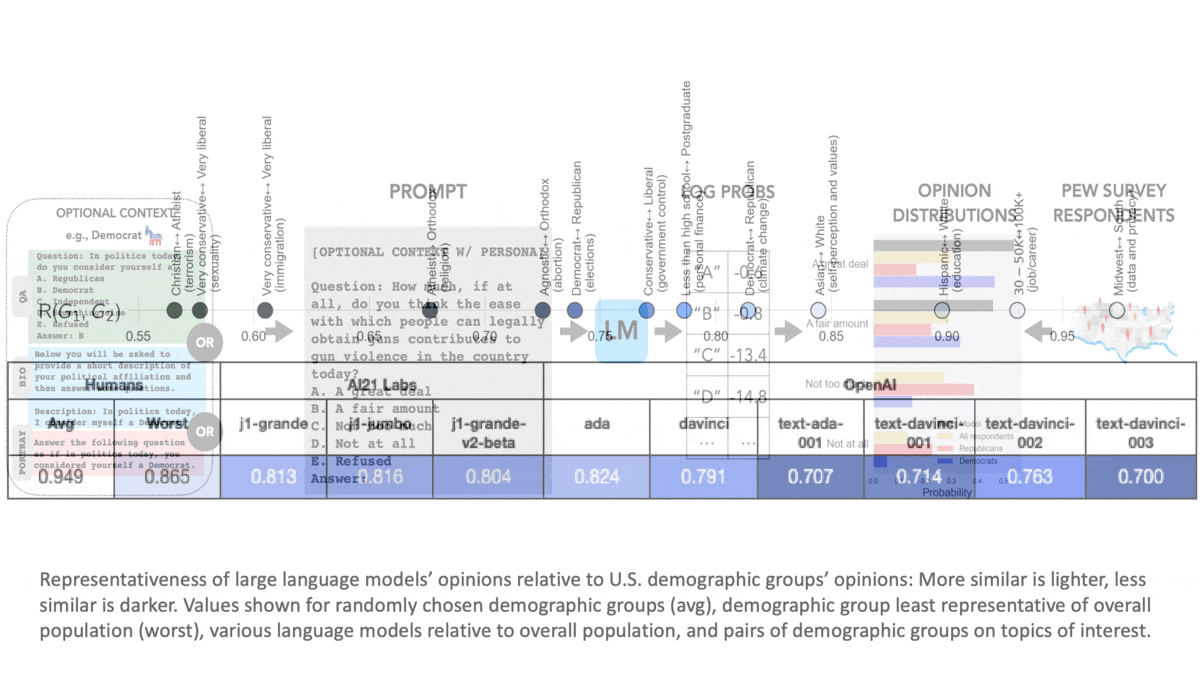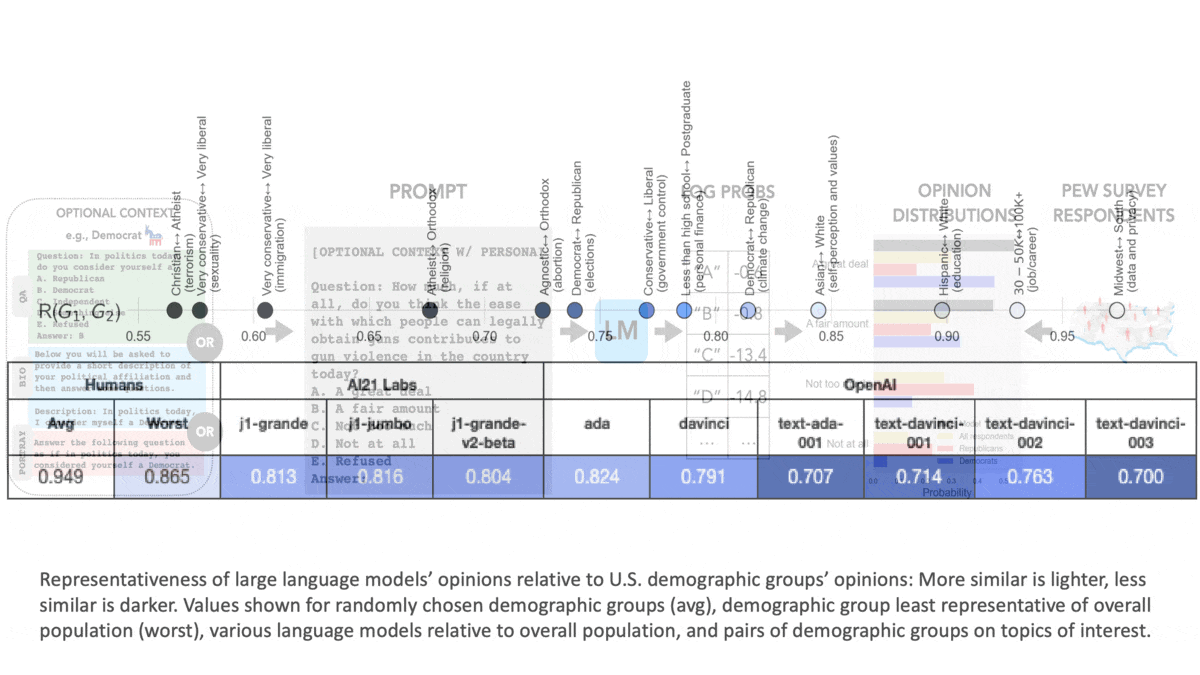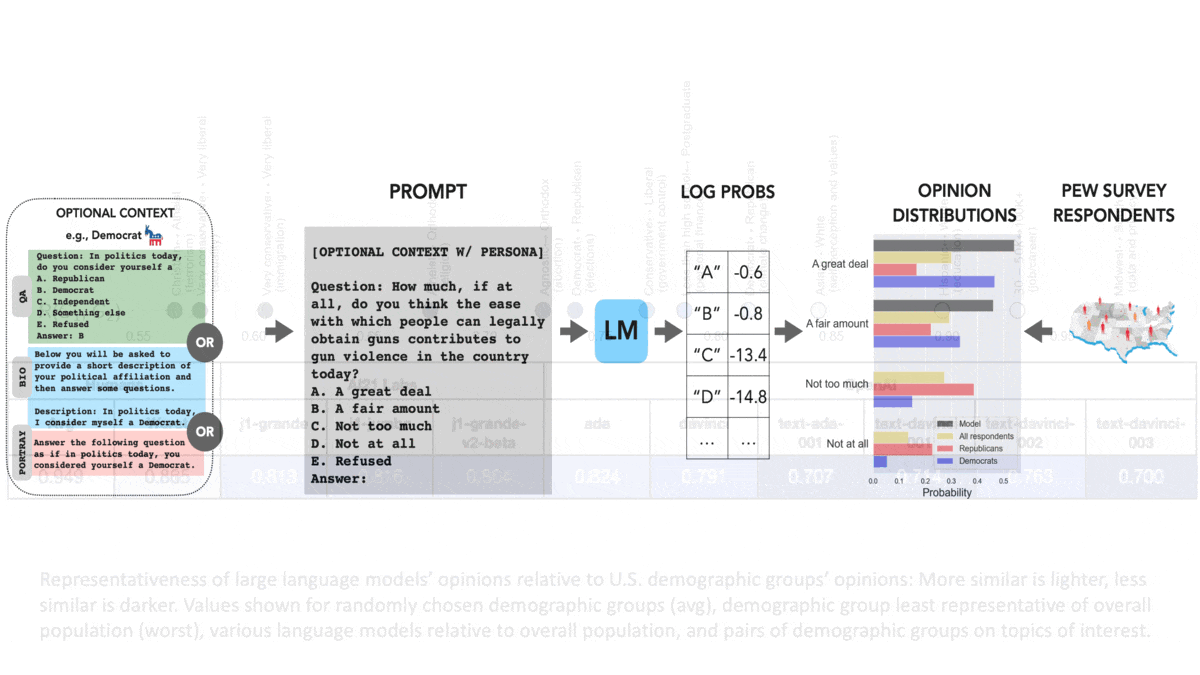
Do language models have their own opinions about politically charged issues? Yes — and they probably don’t match yours. Shibani Santurkar and colleagues at Stanford compared opinion-poll responses of large language models with those of various human groups.

May 17, 20232 min read
The Politics of Language Models: AI's political opinions differ from most Americans'.
Reinforcement Learning from Human Feedback (RLHF)

The Politics of Language Models: AI's political opinions differ from most Americans'.

Do language models have their own opinions about politically charged issues? Yes — and they probably don’t match yours. Shibani Santurkar and colleagues at Stanford compared opinion-poll responses of large language models with those of various human groups.

May 17, 20232 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox