
Mixture of Experts (MoE)

4 Posts

Efficiency Experts: Mixture of Experts Makes Language Models More Efficient
Mixture of Experts (MoE)

Efficiency Experts: Mixture of Experts Makes Language Models More Efficient

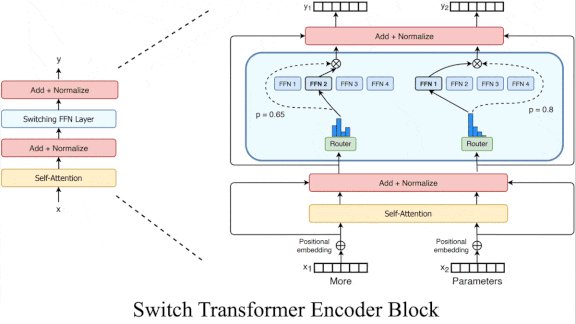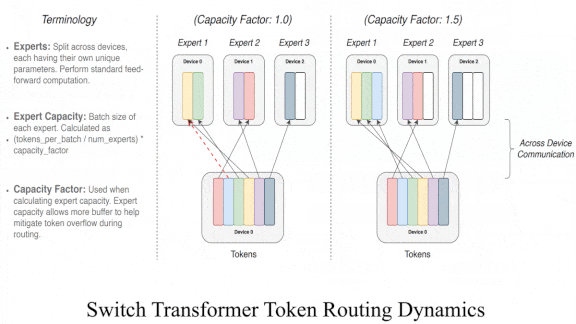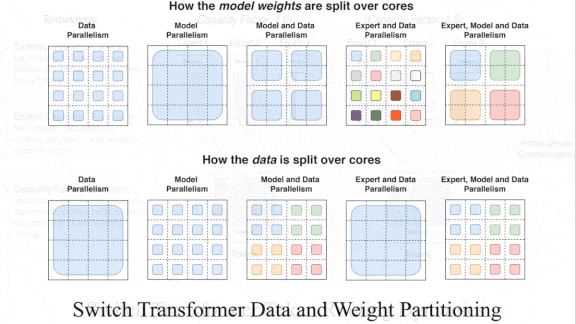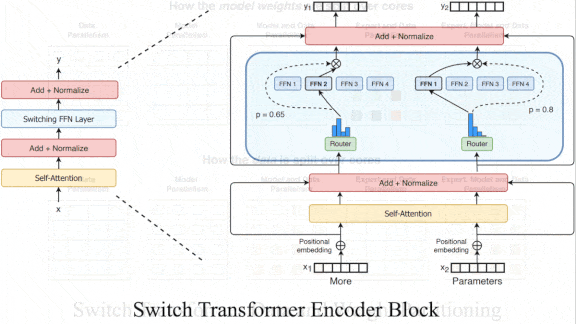
The emerging generation of trillion-parameter language models take significant computation to train. Activating only a portion of the network at a time can cut the requirement dramatically and still achieve exceptional results.

April 27, 20223 min read
Efficiency Experts: Mixture of Experts Makes Language Models More Efficient
Mixture of Experts (MoE)

Efficiency Experts: Mixture of Experts Makes Language Models More Efficient

The emerging generation of trillion-parameter language models take significant computation to train. Activating only a portion of the network at a time can cut the requirement dramatically and still achieve exceptional results.

April 27, 20223 min read
Bigger, Faster Transformers: Increasing parameters without slowing down transformers
Mixture of Experts (MoE)

Bigger, Faster Transformers: Increasing parameters without slowing down transformers

Performance in language tasks rises with the size of the model — yet, as a model’s parameter count rises, so does the time it takes to render output. New work pumps up the number of parameters without slowing down the network.

February 24, 20212 min read
Bigger, Faster Transformers: Increasing parameters without slowing down transformers
Mixture of Experts (MoE)

Bigger, Faster Transformers: Increasing parameters without slowing down transformers

Performance in language tasks rises with the size of the model — yet, as a model’s parameter count rises, so does the time it takes to render output. New work pumps up the number of parameters without slowing down the network.

February 24, 20212 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox