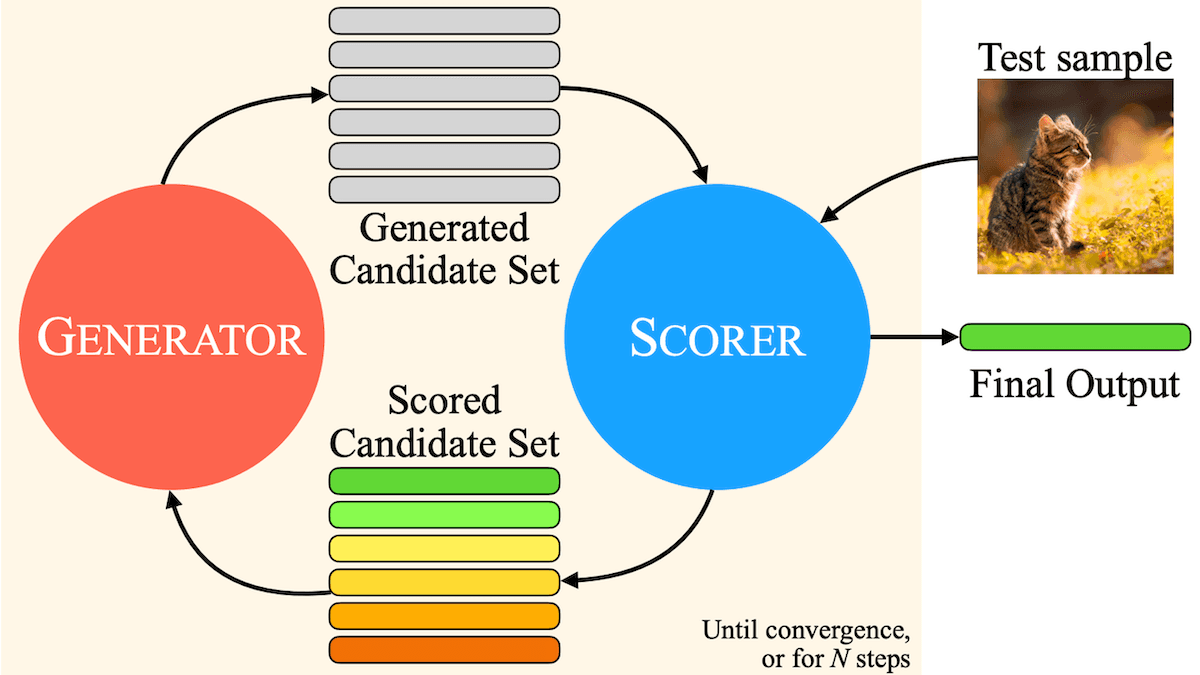
Text-Only LLM Goes Multimodal: LLMs learn to caption images, video, and audio without further training
Large Multimodal Models (LMMs)

Text-Only LLM Goes Multimodal: LLMs learn to caption images, video, and audio without further training

Large language models excel at processing text but can’t interpret images, video, or audio directly without further training on those media types. Researchers devised a way to overcome this limitation.
April 23, 20252 min read
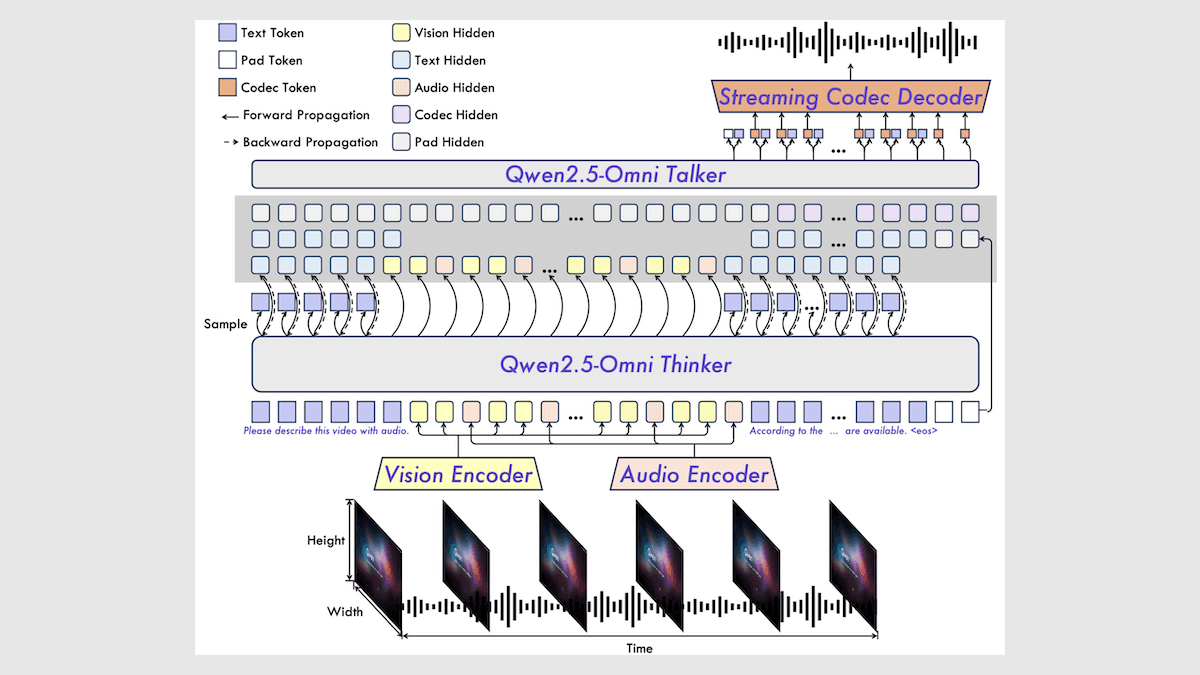
Better Multimodal Performance With Open Weights: Qwen2.5-Omni 7B raises the bar for small multimodal models
Large Multimodal Models (LMMs)

Better Multimodal Performance With Open Weights: Qwen2.5-Omni 7B raises the bar for small multimodal models

Alibaba’s latest open-weights system raises the bar for multimodal tasks in a relatively small model.

April 9, 20253 min read
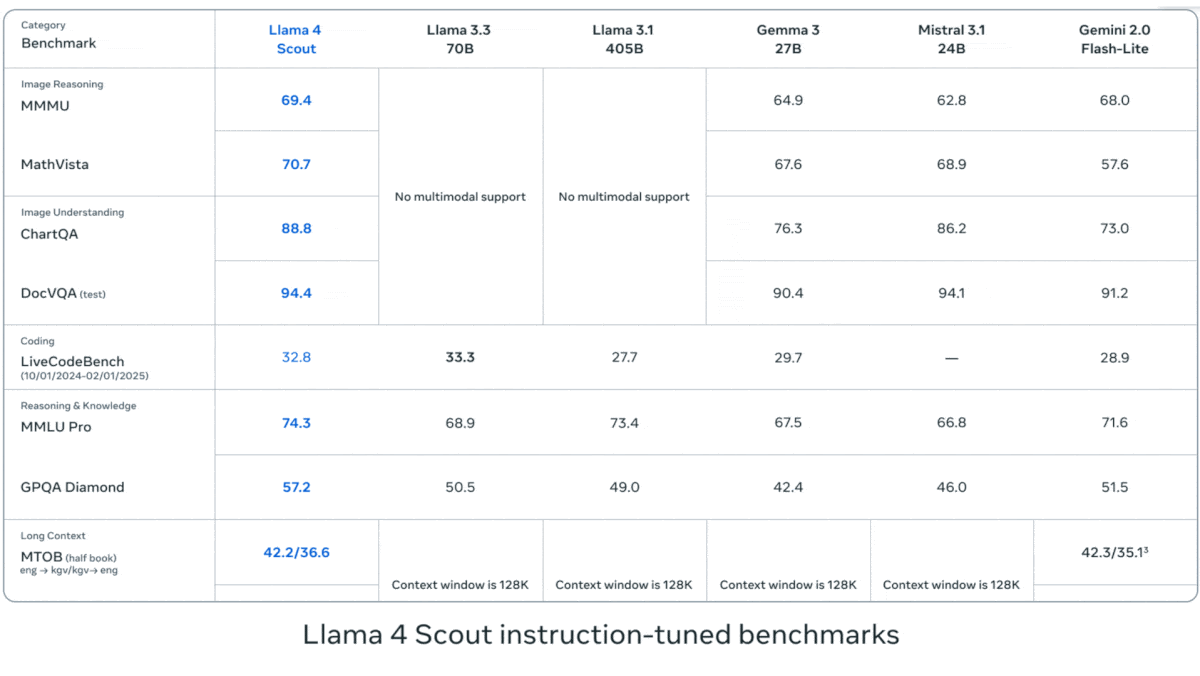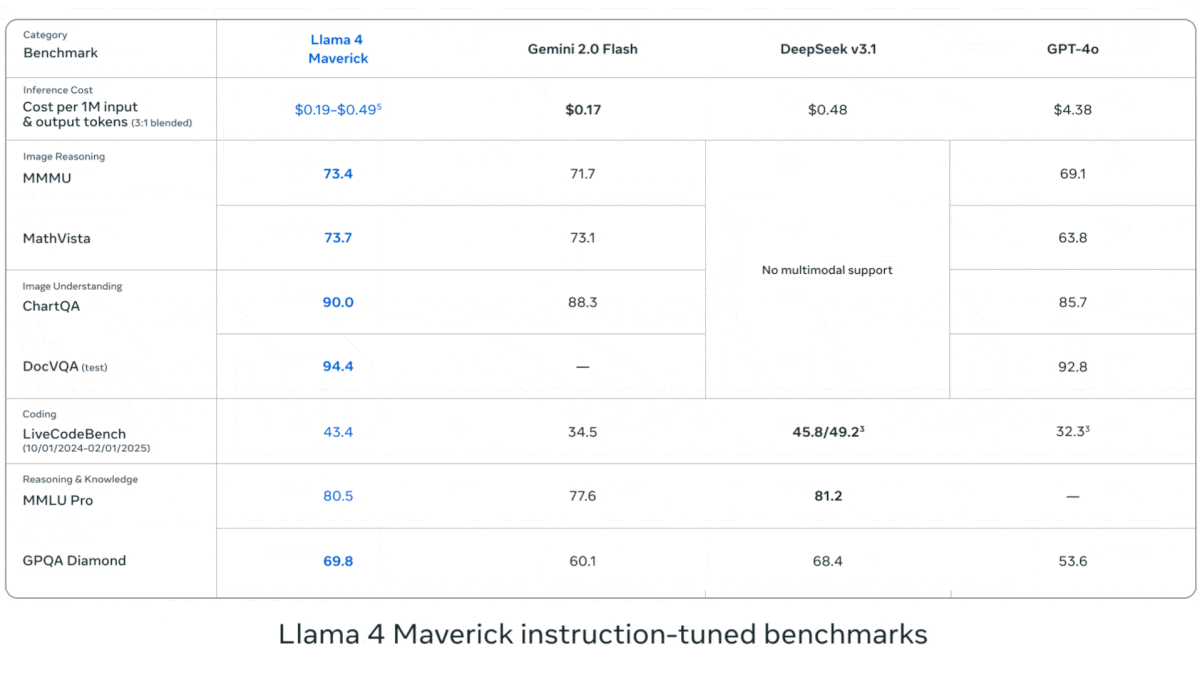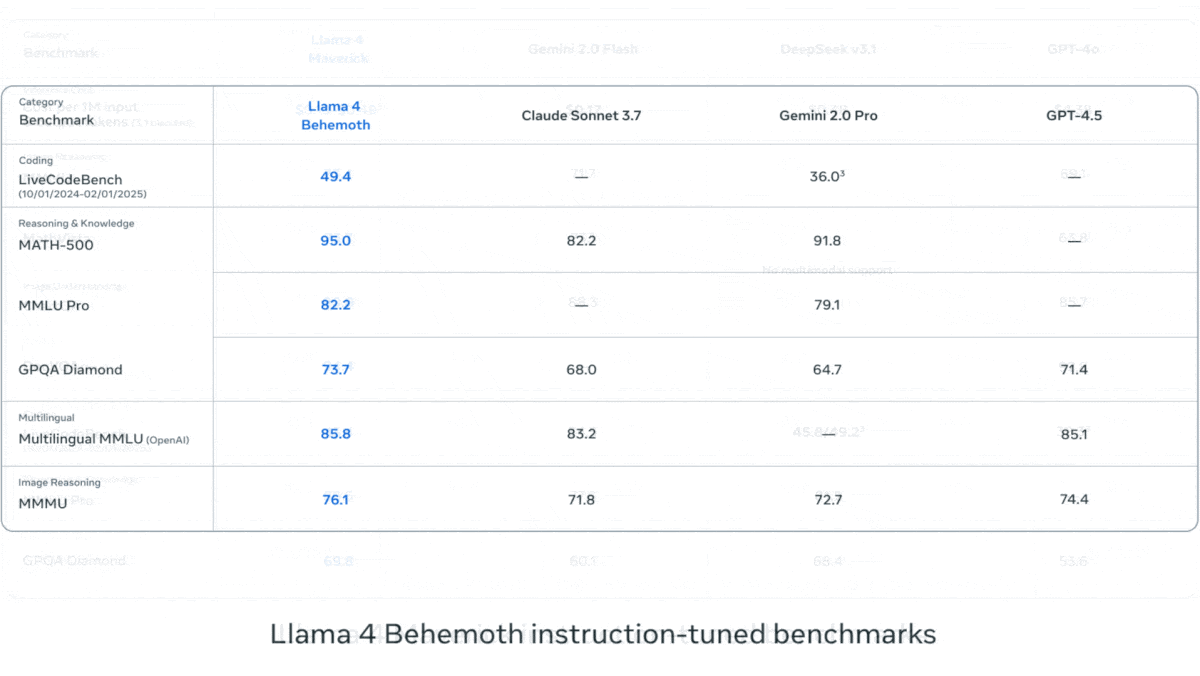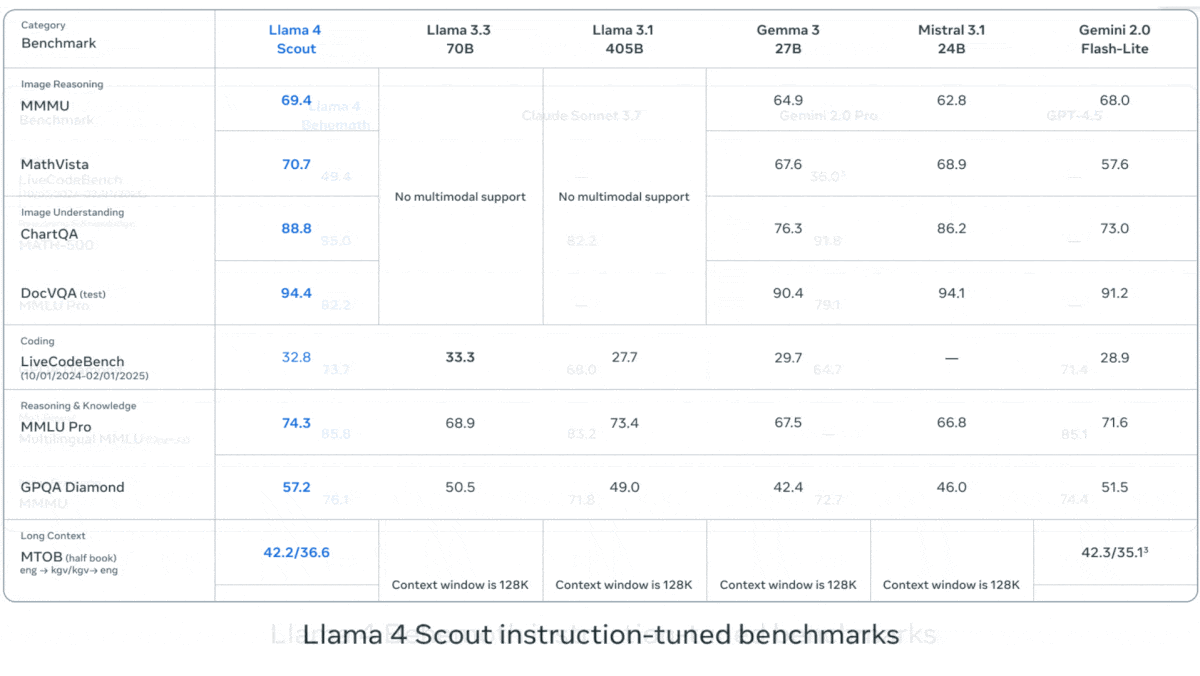
Llama’s Mixture of Vision-Language Experts: Meta releases Llama 4 models, claims edge over AI competitors
Large Multimodal Models (LMMs)

Llama’s Mixture of Vision-Language Experts: Meta releases Llama 4 models, claims edge over AI competitors

Meta updated its popular open-weights models, claiming performance superior to closed competitors in three size classes.

April 9, 20253 min read
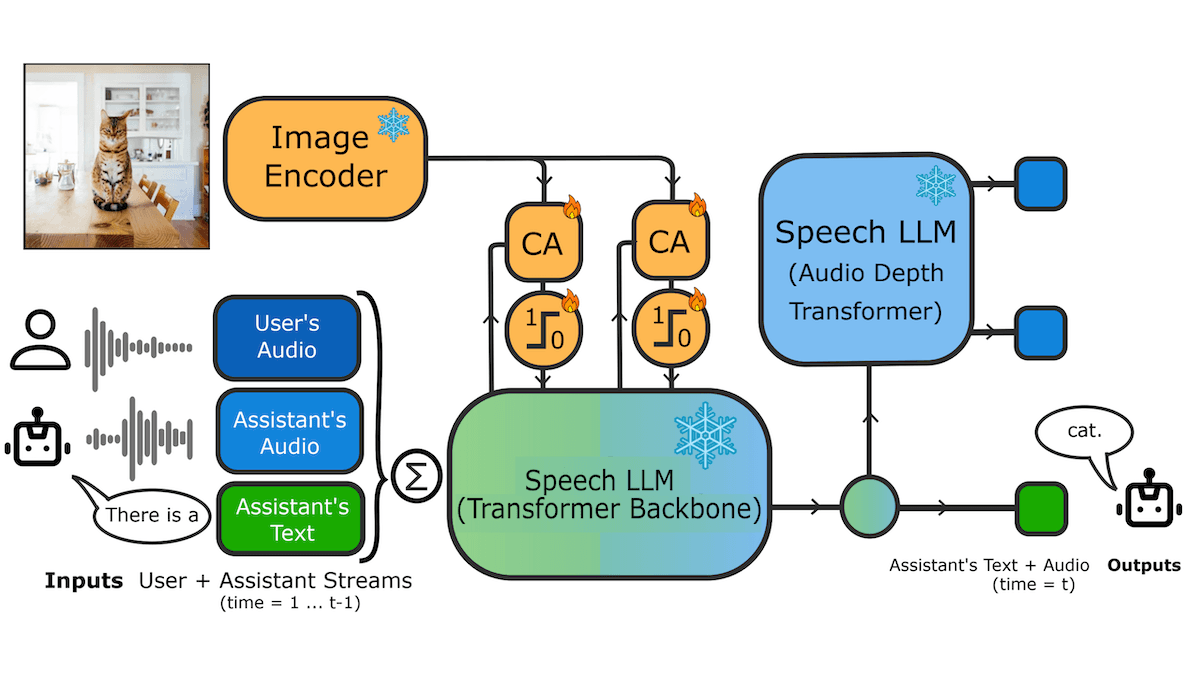
Interactive Voice-to-Voice With Vision: MoshiVis adds image understanding to voice-first conversations
Large Multimodal Models (LMMs)

Interactive Voice-to-Voice With Vision: MoshiVis adds image understanding to voice-first conversations

Researchers updated the highly responsive Moshi voice-to-voice model to discuss visual input.

April 2, 20253 min read
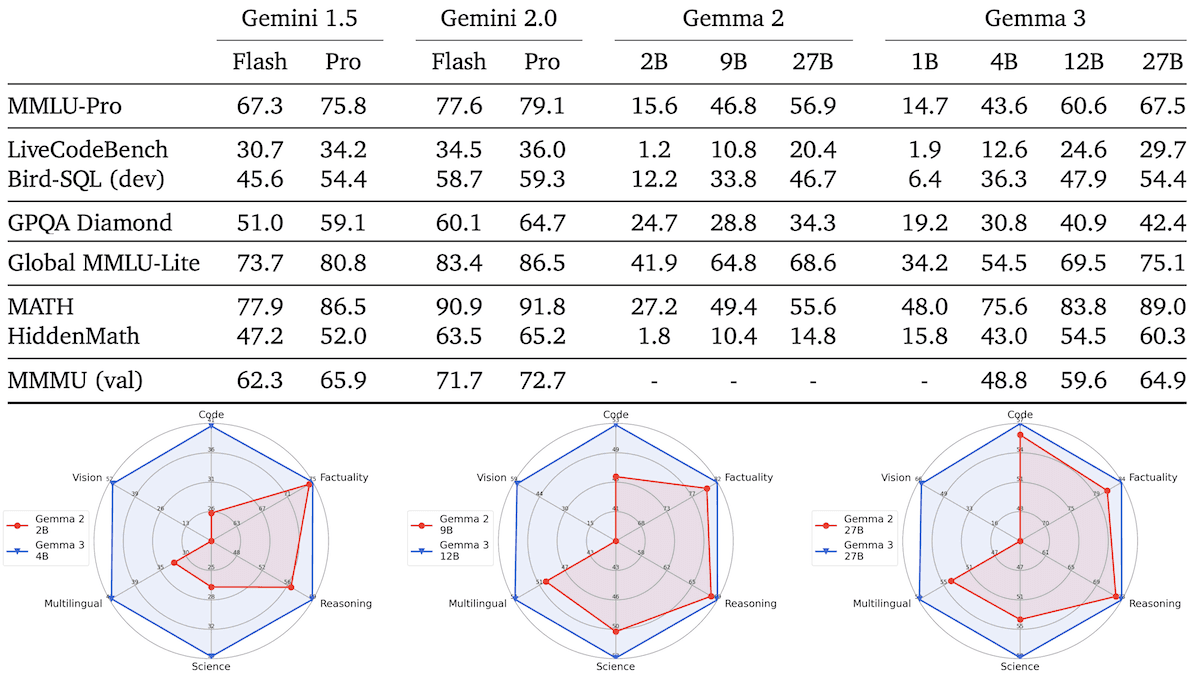
Vision-Language, Compact and Open: Google releases Gemma 3 vision-language models with open weights
Large Multimodal Models (LMMs)

Vision-Language, Compact and Open: Google releases Gemma 3 vision-language models with open weights

Google updated its open-weights family of large language models to include versions that handle image and video inputs.

March 26, 20253 min read
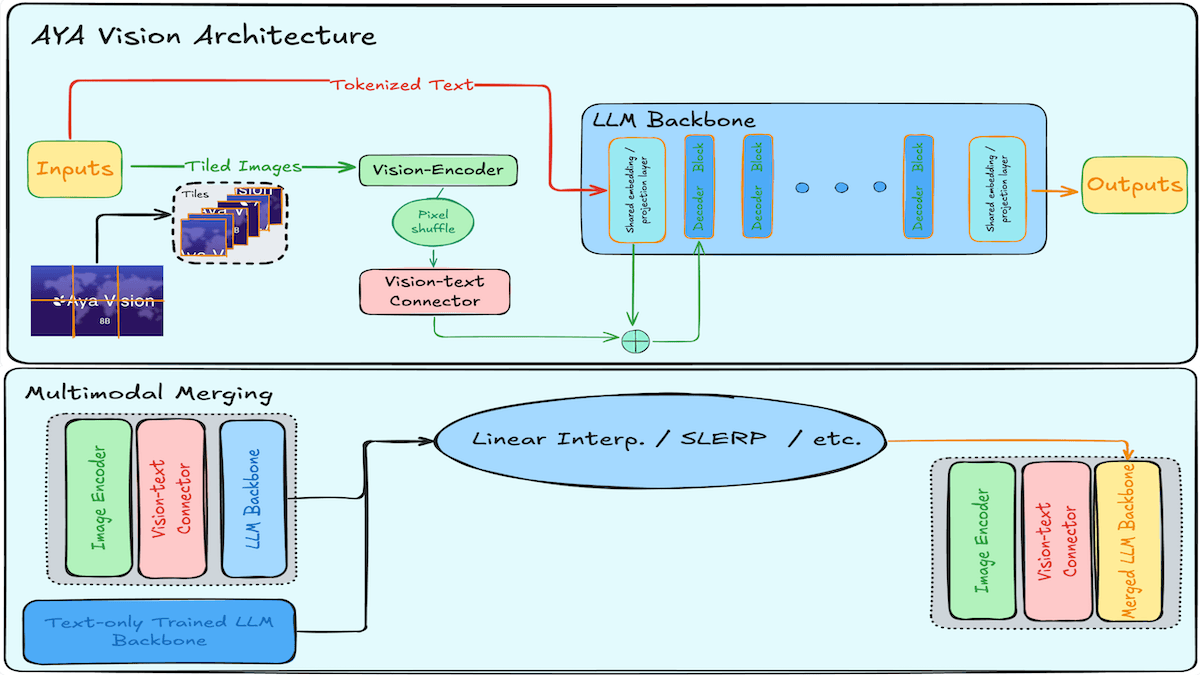
Equally Fluent in Many Languages: Cohere’s Aya Vision beats multilingual rivals in text & image understanding
Large Multimodal Models (LMMs)

Equally Fluent in Many Languages: Cohere’s Aya Vision beats multilingual rivals in text & image understanding

Multilingual AI models often suffer uneven performance across languages, especially in multimodal tasks. A pair of lean models counters this trend with consistent understanding of text and images across major languages.

March 19, 20253 min read
Equally Fluent in Many Languages: Cohere’s Aya Vision beats multilingual rivals in text & image understanding
Large Multimodal Models (LMMs)

Equally Fluent in Many Languages: Cohere’s Aya Vision beats multilingual rivals in text & image understanding

Multilingual AI models often suffer uneven performance across languages, especially in multimodal tasks. A pair of lean models counters this trend with consistent understanding of text and images across major languages.

March 19, 20253 min read
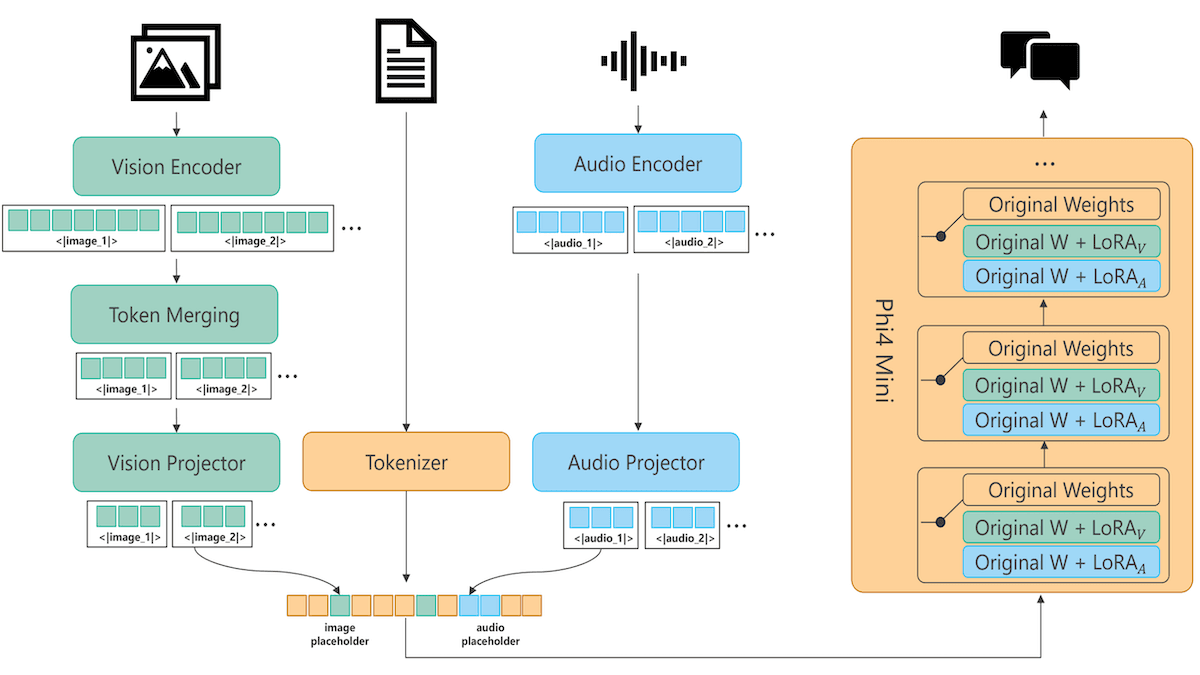
Microsoft Tackles Voice-In, Text-Out: Microsoft’s Phi-4 Multimodal model can process text, images, and speech simultaneously
Large Multimodal Models (LMMs)

Microsoft Tackles Voice-In, Text-Out: Microsoft’s Phi-4 Multimodal model can process text, images, and speech simultaneously

Microsoft debuted its first official large language model that responds to spoken input.

March 12, 20253 min read
Microsoft Tackles Voice-In, Text-Out: Microsoft’s Phi-4 Multimodal model can process text, images, and speech simultaneously
Large Multimodal Models (LMMs)

Microsoft Tackles Voice-In, Text-Out: Microsoft’s Phi-4 Multimodal model can process text, images, and speech simultaneously

Microsoft debuted its first official large language model that responds to spoken input.

March 12, 20253 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox