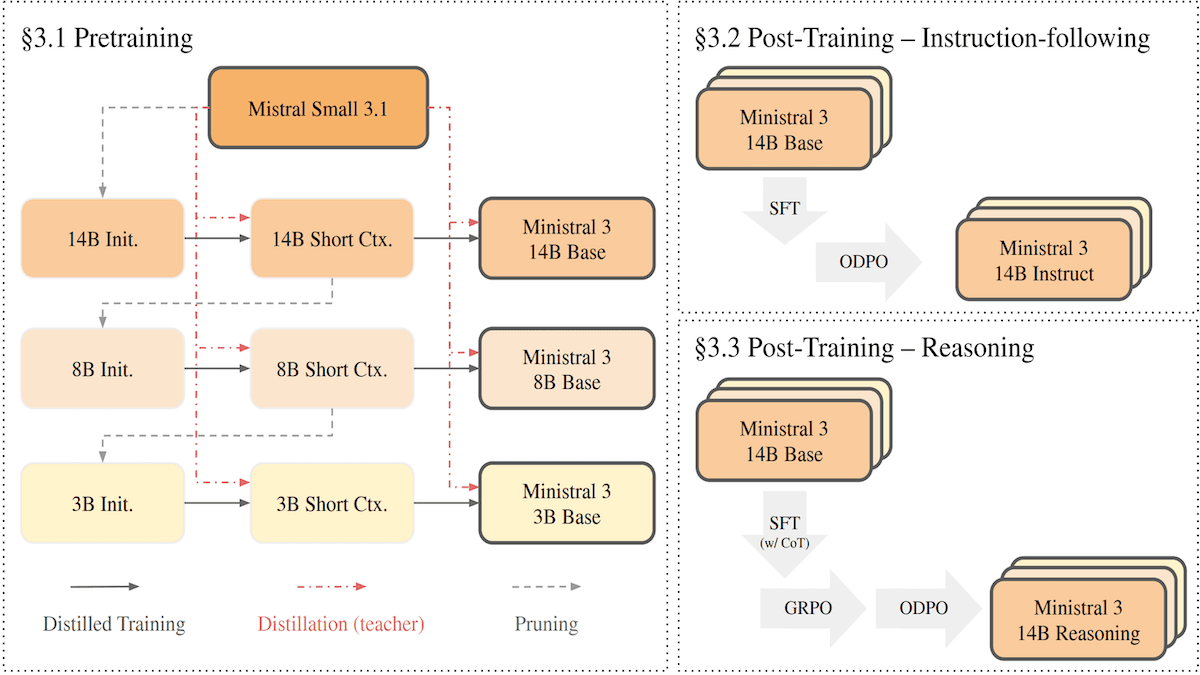
Recipe for Smaller, Capable Models: Mistral uses cascade distillation on Mistral 3 to build Ministral family
Large Multimodal Models (LMMs)

Recipe for Smaller, Capable Models: Mistral uses cascade distillation on Mistral 3 to build Ministral family

Mistral compressed Mistral Small 3.1 into much smaller versions, yielding a family of relatively small, open-weights, vision-language models that perform better by some measures than competing models of similar size. The method combines pruning and distillation.

February 6, 20263 min read
Kimi K2.5 Creates Its Own Workforce: Moonshot AI takes the open model crown with vision updates, aided by subagents
Large Multimodal Models (LMMs)

Kimi K2.5 Creates Its Own Workforce: Moonshot AI takes the open model crown with vision updates, aided by subagents

An open source vision-language model unleashes minion agents that enable it to perform tasks more quickly and effectively.

February 6, 20263 min read
Refining Words in Pictures: Z.ai’s GLM-Image blends transformer and diffusion architectures for better text in images
Large Multimodal Models (LMMs)

Refining Words in Pictures: Z.ai’s GLM-Image blends transformer and diffusion architectures for better text in images

Image generators often mangle text. An open-weights model outperforms open and proprietary competitors in text rendering.

January 30, 20263 min read
Multimodal Models for Biomedicine by Pengtao Xie: Pengtao Xie of UC-San Diego on why medical models need to visualize tiny chemicals and large organs
Large Multimodal Models (LMMs)

Multimodal Models for Biomedicine by Pengtao Xie: Pengtao Xie of UC-San Diego on why medical models need to visualize tiny chemicals and large organs

Over the past few years, we have seen rapid progress in models that jointly reason over text, images, sequences, graphs, and time series. Yet in biomedical settings, these capabilities often remain fragmented, brittle, or difficult to interpret.

January 2, 20262 min read
From Prediction to Action by Tanmay Gupta: Tanmay Gupta of the Allen Institute on building AI for long-horizon tasks
Large Multimodal Models (LMMs)

From Prediction to Action by Tanmay Gupta: Tanmay Gupta of the Allen Institute on building AI for long-horizon tasks

AI research in 2026 should confront a simple but transformative realization: Models that predict are not the same as systems that act. The latter is what we actually need.

January 2, 20263 min read
Adapting LLMs to Any Sort of Data: SEMI (Sample-Efficient Modality Integration) tackles new domains with few-shot examples
Large Multimodal Models (LMMs)

Adapting LLMs to Any Sort of Data: SEMI (Sample-Efficient Modality Integration) tackles new domains with few-shot examples

Enabling a pretrained large language model to process a data type other than text (say, images), possibly in a specialized domain (say, radiology), typically requires thousands to millions of examples that pair the other data (perhaps x-rays) with text.

December 17, 20253 min read
Disney Teams Up With OpenAI: OpenAI’s Sora video generator will include Disney characters, with fan videos on Disney+
Large Multimodal Models (LMMs)

Disney Teams Up With OpenAI: OpenAI’s Sora video generator will include Disney characters, with fan videos on Disney+

Disney, the entertainment conglomerate that owns Marvel, Pixar, Lucasfilm and its own animated classics from 101 Dalmatians to Zootopia, licensed OpenAI to use its characters in generated videos.

December 17, 20253 min read
Coherent, Interactive Worlds: Runway’s GWM-1 models generate videos with consistent physics for robots and entertainment
Large Multimodal Models (LMMs)

Coherent, Interactive Worlds: Runway’s GWM-1 models generate videos with consistent physics for robots and entertainment

Runway’s GWM-1 family of video-generation models respond to user input in real time while producing scenes that remain consistent regardless of the camera’s position.

December 17, 20253 min read
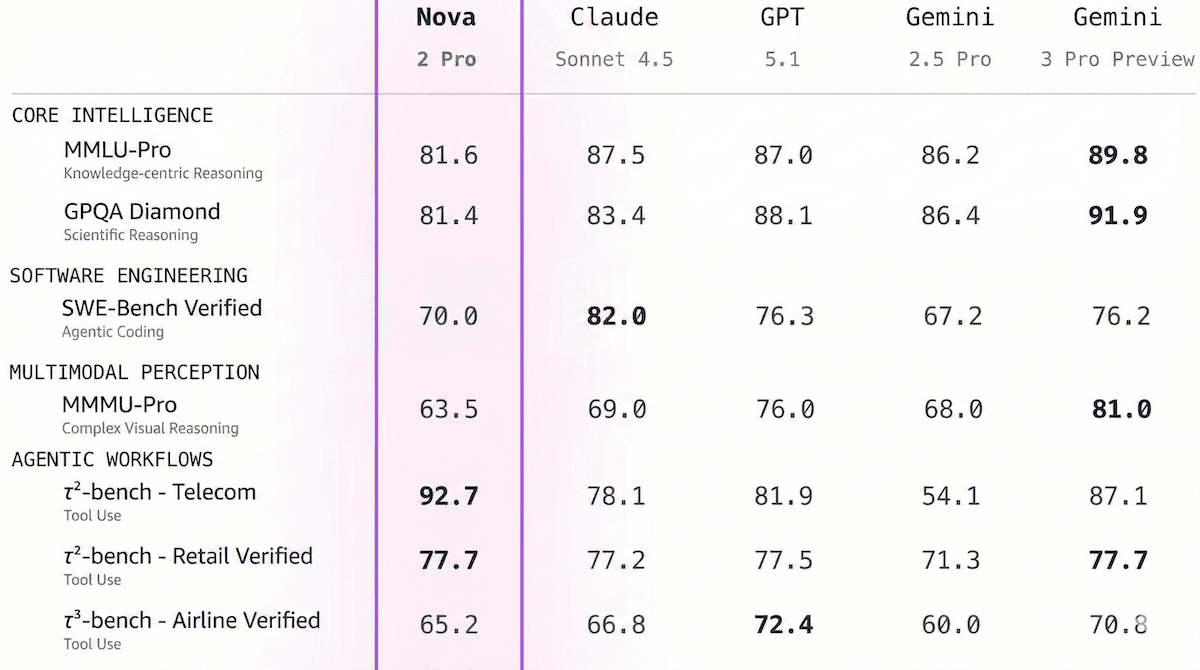
Amazon Steps Forward: Nova 2 family boosts cost-effective performance, adds new agentic features
Large Multimodal Models (LMMs)

Amazon Steps Forward: Nova 2 family boosts cost-effective performance, adds new agentic features

Amazon raised the competitive profile of its foundation models and added services for custom model training and an agent platform for browser automation.

December 10, 20253 min read
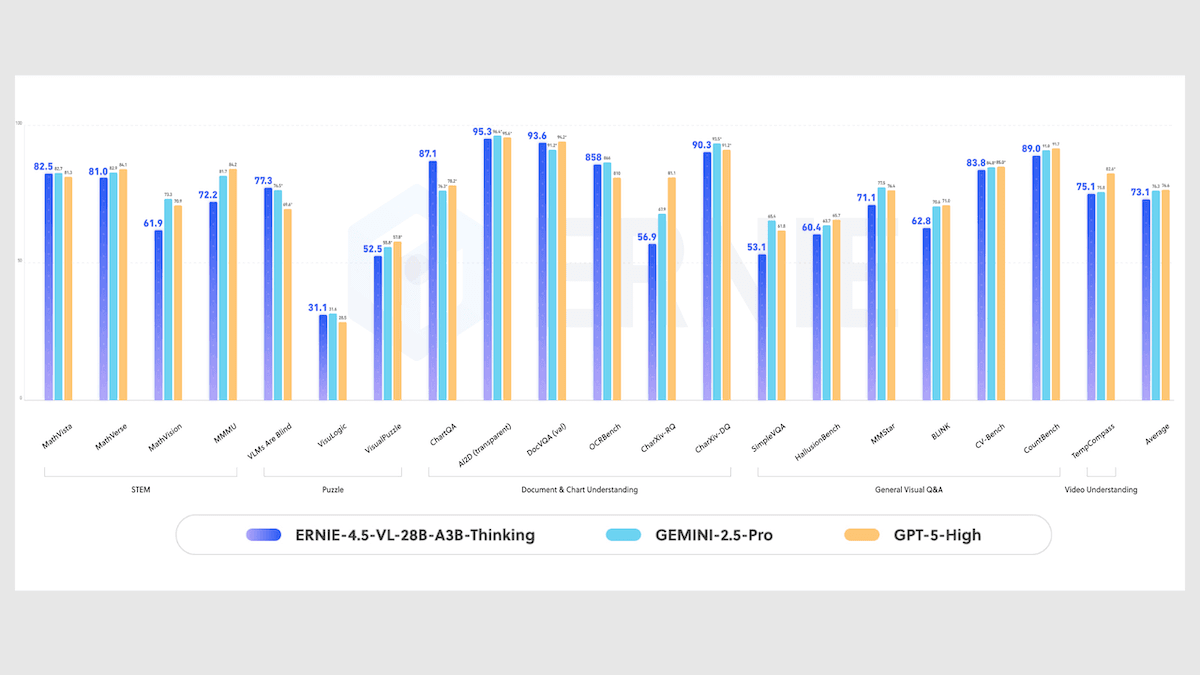
Baidu’s Multimodal Bids: Giant Ernie 5 natively generates multiple media; Ernie-4.5-VL-28B-A3B-Thinking tops Vision-Language metrics
Large Multimodal Models (LMMs)

Baidu’s Multimodal Bids: Giant Ernie 5 natively generates multiple media; Ernie-4.5-VL-28B-A3B-Thinking tops Vision-Language metrics

Baidu debuted two models: a lightweight, open-weights, vision-language model and a giant, proprietary, multimodal model built to take on U.S. competitors.

December 3, 20253 min read
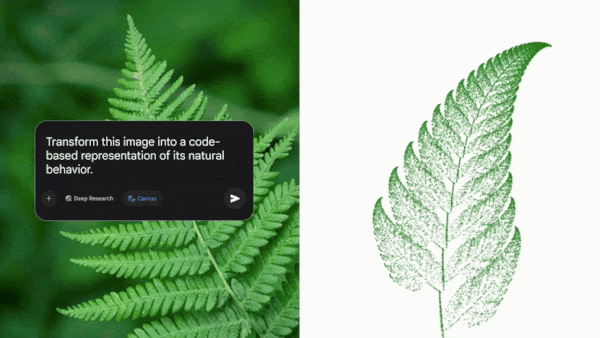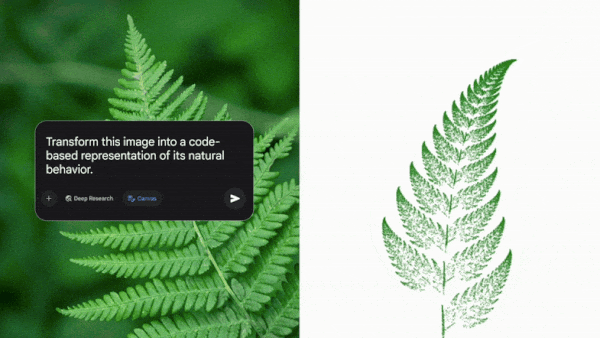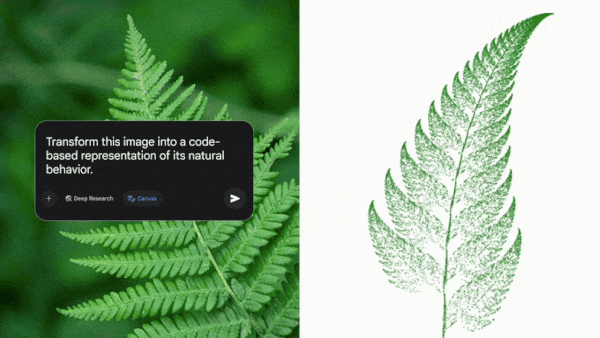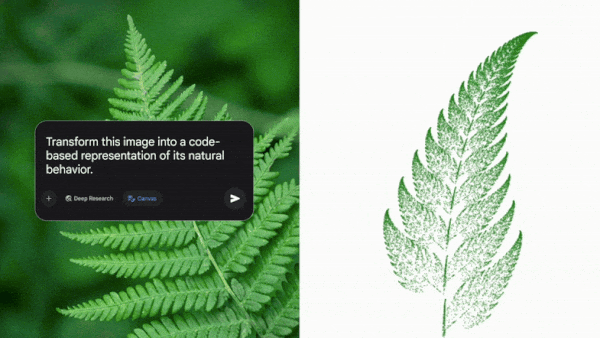
Google Dominates Arena Leaderboards (For the Moment): Gemini 3 Pro and Nano Banana Pro boast best-in-class multimodal reasoning and image generation
Large Multimodal Models (LMMs)

Google Dominates Arena Leaderboards (For the Moment): Gemini 3 Pro and Nano Banana Pro boast best-in-class multimodal reasoning and image generation

Google introduced Gemini 3 Pro and Nano Banana Pro, its flagship vision-language and image-generation models, and deployed them to billions of users worldwide.

November 26, 20254 min read
Qwen3 Goes Big (and Smaller): Alibaba expands Qwen3 family with a 1 trillion-parameter Max model, open-weights Qwen3-VL, and the Qwen3-Omni voice model
Large Multimodal Models (LMMs)

Qwen3 Goes Big (and Smaller): Alibaba expands Qwen3 family with a 1 trillion-parameter Max model, open-weights Qwen3-VL, and the Qwen3-Omni voice model

Alibaba rounded out the Qwen3 family with its biggest large language model to date as well as smaller models that process text, images, video, and/or audio.

October 8, 20253 min read
Google I/O Overdrive: Google’s new AI offerings include Veo 3 video generator, lightweight Gemma 3n, updates to Gemini Pro and Ultra, and more
Large Multimodal Models (LMMs)

Google I/O Overdrive: Google’s new AI offerings include Veo 3 video generator, lightweight Gemma 3n, updates to Gemini Pro and Ultra, and more

Google revamped its roster of models, closed and open, and added more AI-powered features to its existing products.

May 28, 20253 min read
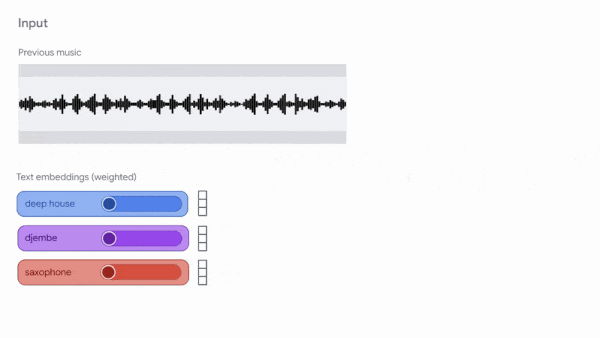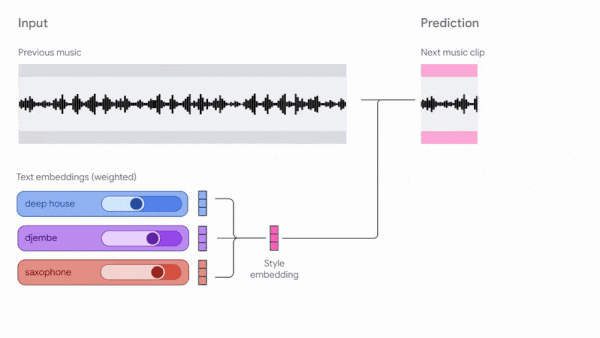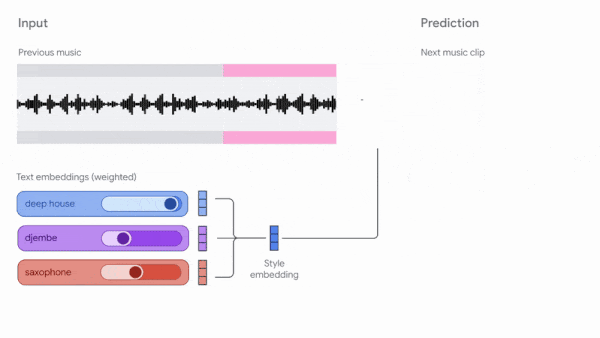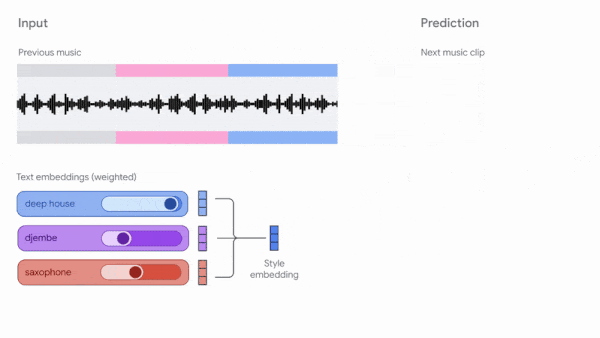
Music Generation for Pros: Google upgrades its AI music tools for professional use
Large Multimodal Models (LMMs)

Music Generation for Pros: Google upgrades its AI music tools for professional use

Google refreshed its experimental tools for composers and producers.

April 30, 20252 min read
New Image Generator for OpenAI API: OpenAI launches API access to GPT Image 1, ChatGPT’s viral image generator
Large Multimodal Models (LMMs)

New Image Generator for OpenAI API: OpenAI launches API access to GPT Image 1, ChatGPT’s viral image generator

ChatGPT’s image generator is available via API.

April 30, 20252 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox