Large Multimodal Models

12 Posts

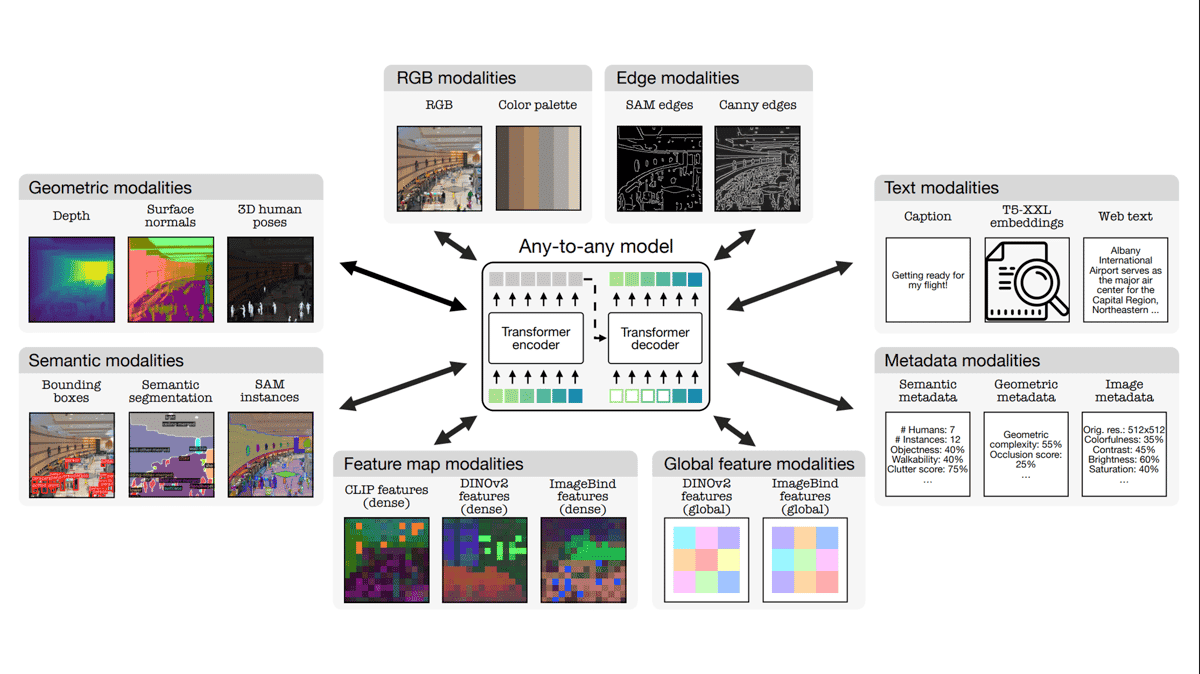
Multimodal to the Max: 4M-21 multimodal model excels in handling diverse input and output types
Large Multimodal Models

Multimodal to the Max: 4M-21 multimodal model excels in handling diverse input and output types

Researchers introduced a model that handles an unprecedented number of input and output types, including many related to performing computer vision tasks.
August 28, 20243 min read
Multimodal to the Max: 4M-21 multimodal model excels in handling diverse input and output types
Large Multimodal Models

Multimodal to the Max: 4M-21 multimodal model excels in handling diverse input and output types

Researchers introduced a model that handles an unprecedented number of input and output types, including many related to performing computer vision tasks.
August 28, 20243 min read
AI Leadership Makes for a Difficult Balance Sheet: OpenAI faces financial growing pains, spending double its revenue
Large Multimodal Models

AI Leadership Makes for a Difficult Balance Sheet: OpenAI faces financial growing pains, spending double its revenue

OpenAI may be spending roughly twice as much money as it’s bringing in, a sign of the financial pressures of blazing the trail in commercial applications of AI.

August 15, 20242 min read
AI Leadership Makes for a Difficult Balance Sheet: OpenAI faces financial growing pains, spending double its revenue
Large Multimodal Models

AI Leadership Makes for a Difficult Balance Sheet: OpenAI faces financial growing pains, spending double its revenue

OpenAI may be spending roughly twice as much money as it’s bringing in, a sign of the financial pressures of blazing the trail in commercial applications of AI.

August 15, 20242 min read
2 Million Tokens of Context & More: Google’s I/O developers’ conference reveals new AI models, features, and upgrades.
Large Multimodal Models

2 Million Tokens of Context & More: Google’s I/O developers’ conference reveals new AI models, features, and upgrades.

Google’s annual I/O developers’ conference brought a plethora of updates and new models. 

May 22, 20243 min read
2 Million Tokens of Context & More: Google’s I/O developers’ conference reveals new AI models, features, and upgrades.
Large Multimodal Models

2 Million Tokens of Context & More: Google’s I/O developers’ conference reveals new AI models, features, and upgrades.

Google’s annual I/O developers’ conference brought a plethora of updates and new models. 

May 22, 20243 min read
Faster, Cheaper Multimodality: All about GPT-4o, OpenAI’s latest multimodal model
Large Multimodal Models

Faster, Cheaper Multimodality: All about GPT-4o, OpenAI’s latest multimodal model

OpenAI’s latest model raises the bar for models that can work with common media types in any combination.

May 22, 20243 min read
Faster, Cheaper Multimodality: All about GPT-4o, OpenAI’s latest multimodal model
Large Multimodal Models

Faster, Cheaper Multimodality: All about GPT-4o, OpenAI’s latest multimodal model

OpenAI’s latest model raises the bar for models that can work with common media types in any combination.

May 22, 20243 min read
Anthropic Ups the Ante: Anthropic introduces Claude 3, a new trio of multimodal models.
Large Multimodal Models

Anthropic Ups the Ante: Anthropic introduces Claude 3, a new trio of multimodal models.

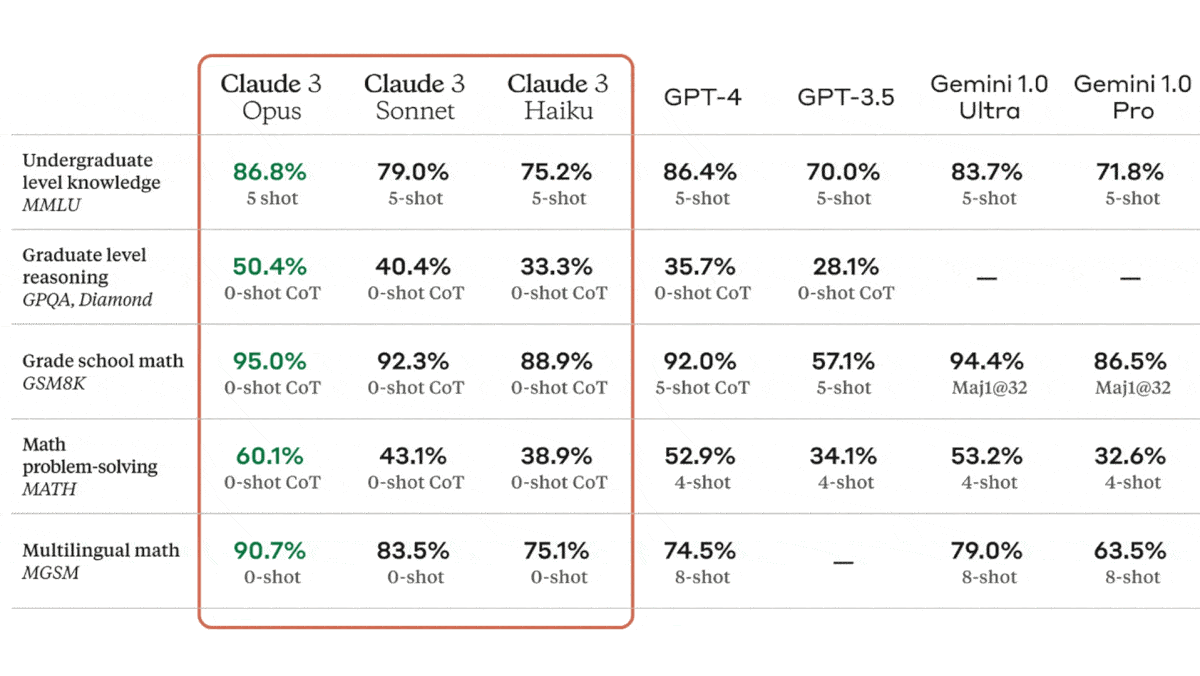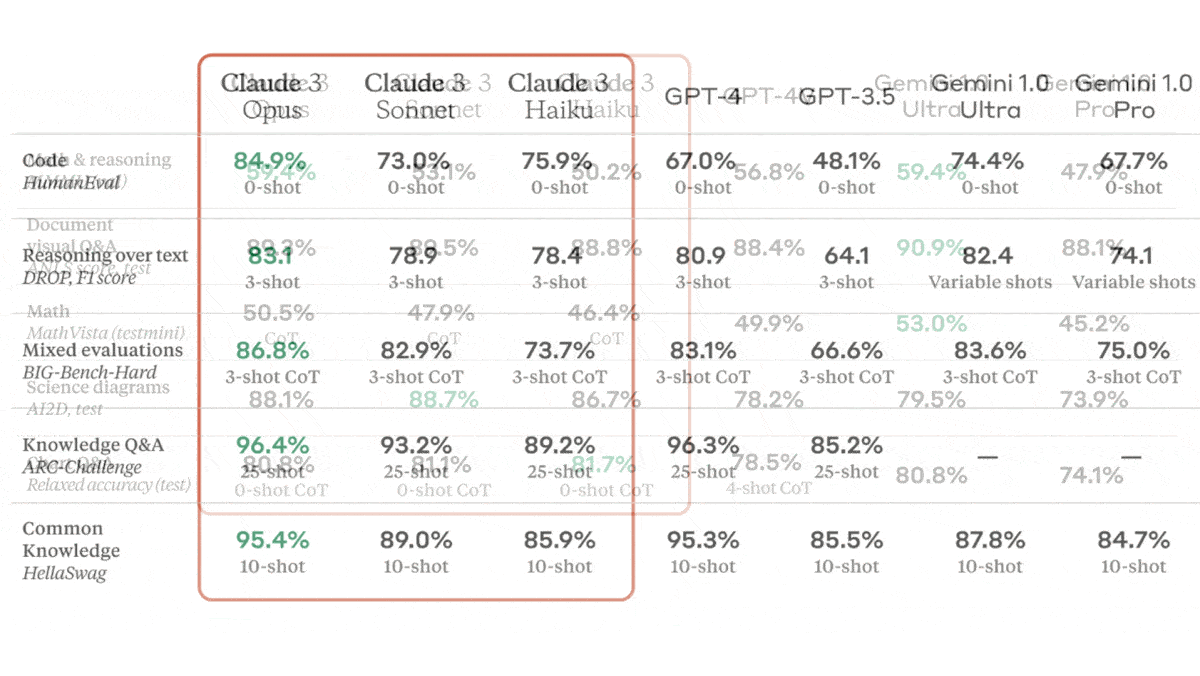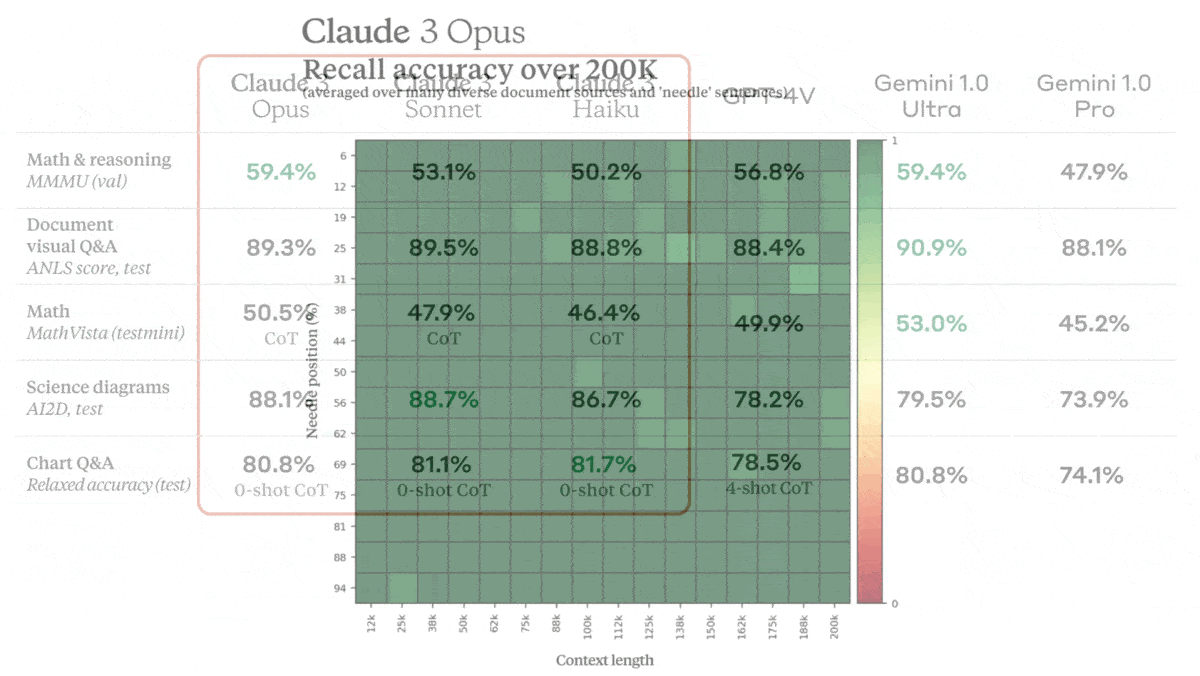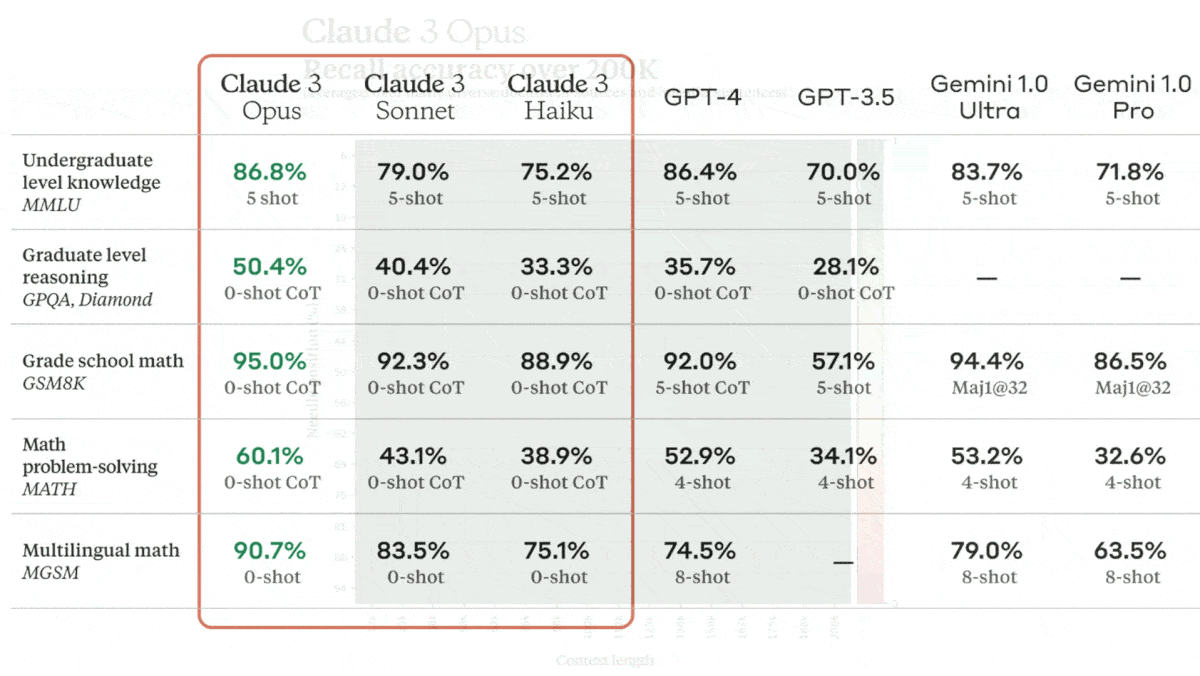
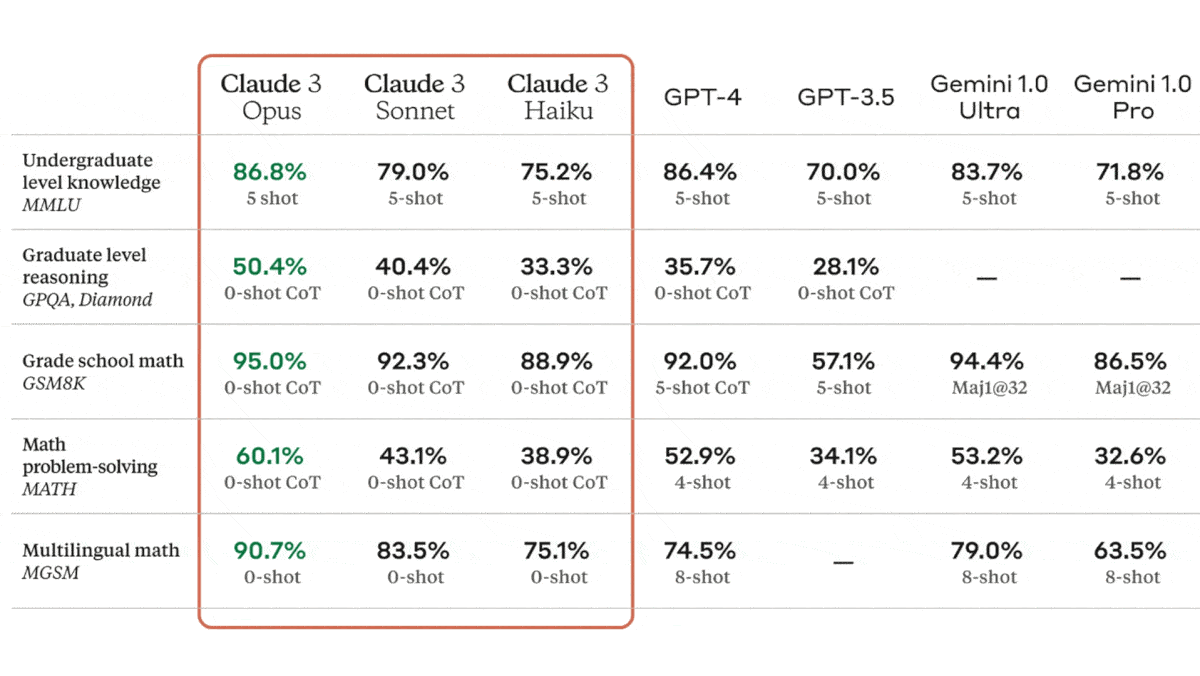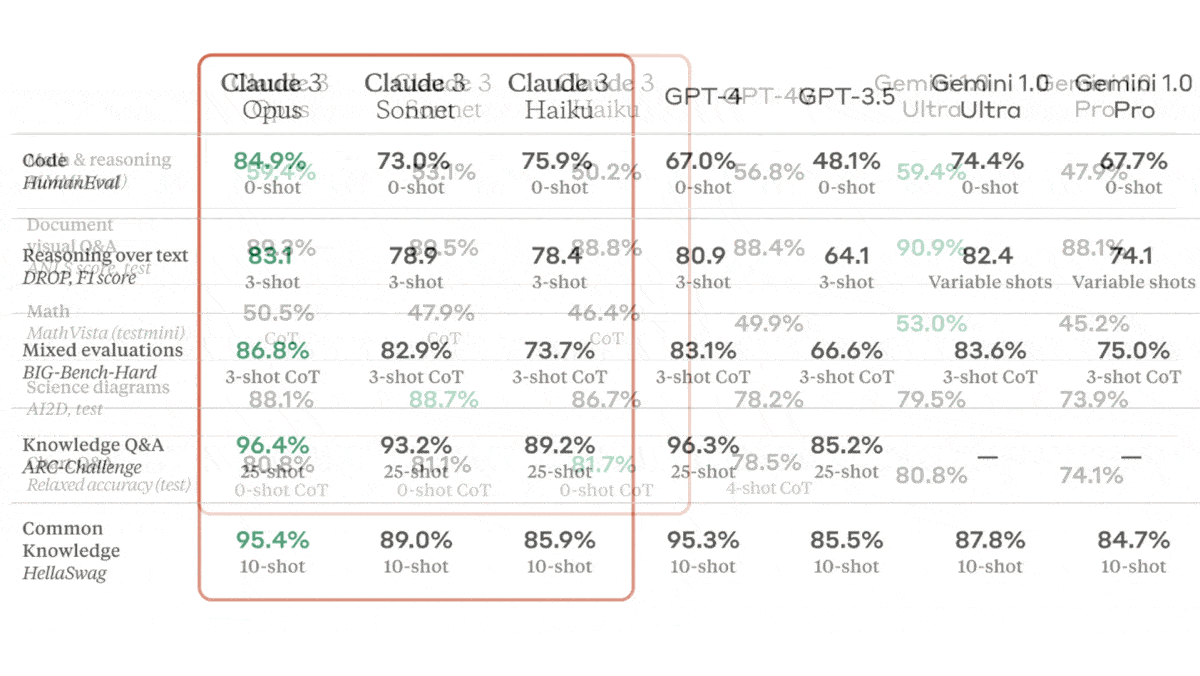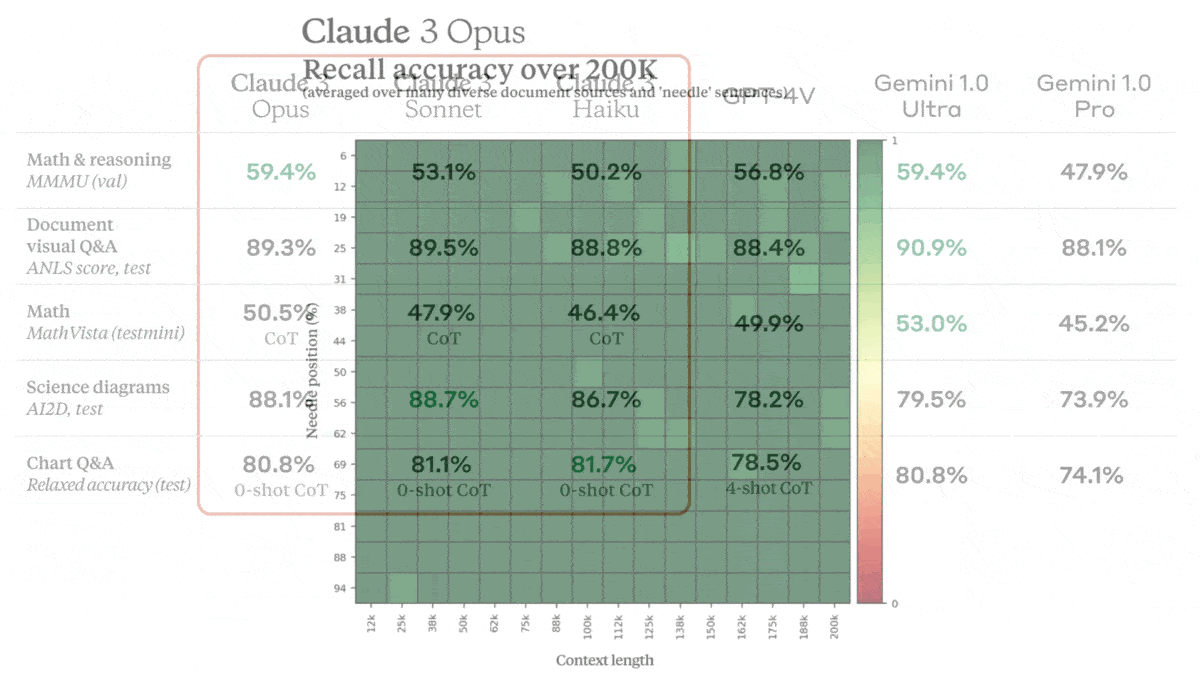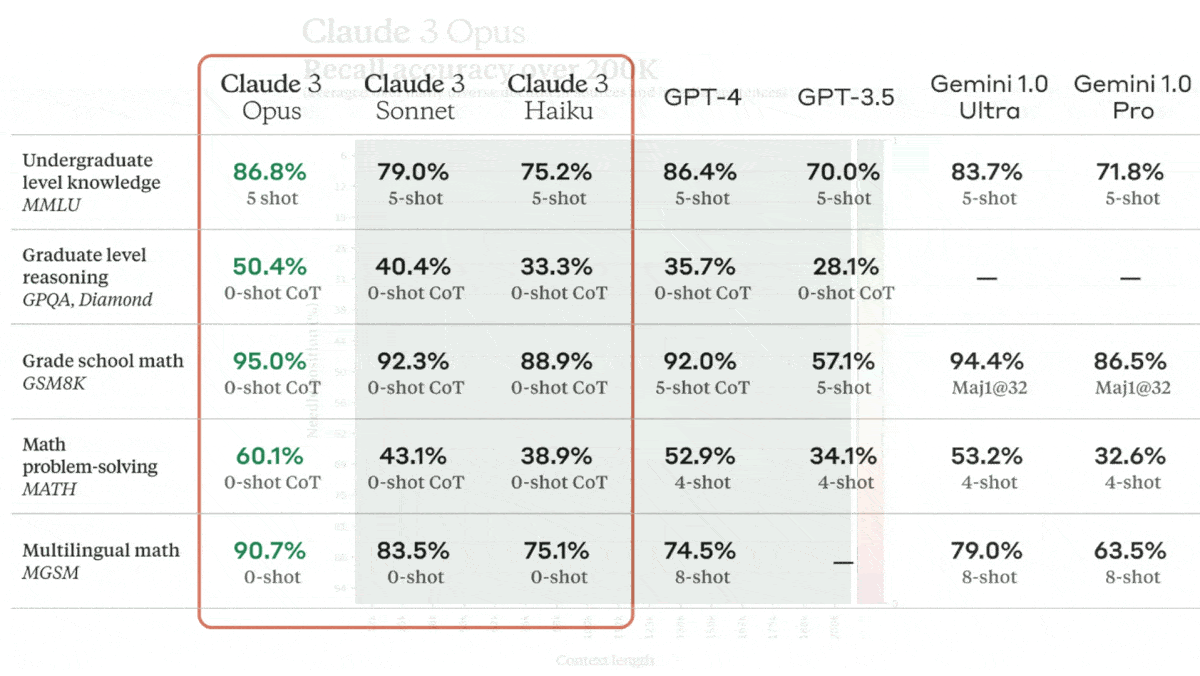
Anthropic announced a suite of large multimodal models that set new states of the art in key benchmarks.

March 13, 20243 min read
Anthropic Ups the Ante: Anthropic introduces Claude 3, a new trio of multimodal models.
Large Multimodal Models

Anthropic Ups the Ante: Anthropic introduces Claude 3, a new trio of multimodal models.

Anthropic announced a suite of large multimodal models that set new states of the art in key benchmarks.

March 13, 20243 min read
Text or Images, Input or Output: GILL, an innovative approach to multimodal model training
Large Multimodal Models

Text or Images, Input or Output: GILL, an innovative approach to multimodal model training

GPT-4V introduced a large multimodal model that generates text from images and, with help from DALL-E 3, generates images from text. However, OpenAI hasn’t fully explained how it built the system. A separate group of researchers described their own method.

January 10, 20243 min read
Text or Images, Input or Output: GILL, an innovative approach to multimodal model training
Large Multimodal Models

Text or Images, Input or Output: GILL, an innovative approach to multimodal model training

GPT-4V introduced a large multimodal model that generates text from images and, with help from DALL-E 3, generates images from text. However, OpenAI hasn’t fully explained how it built the system. A separate group of researchers described their own method.

January 10, 20243 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox