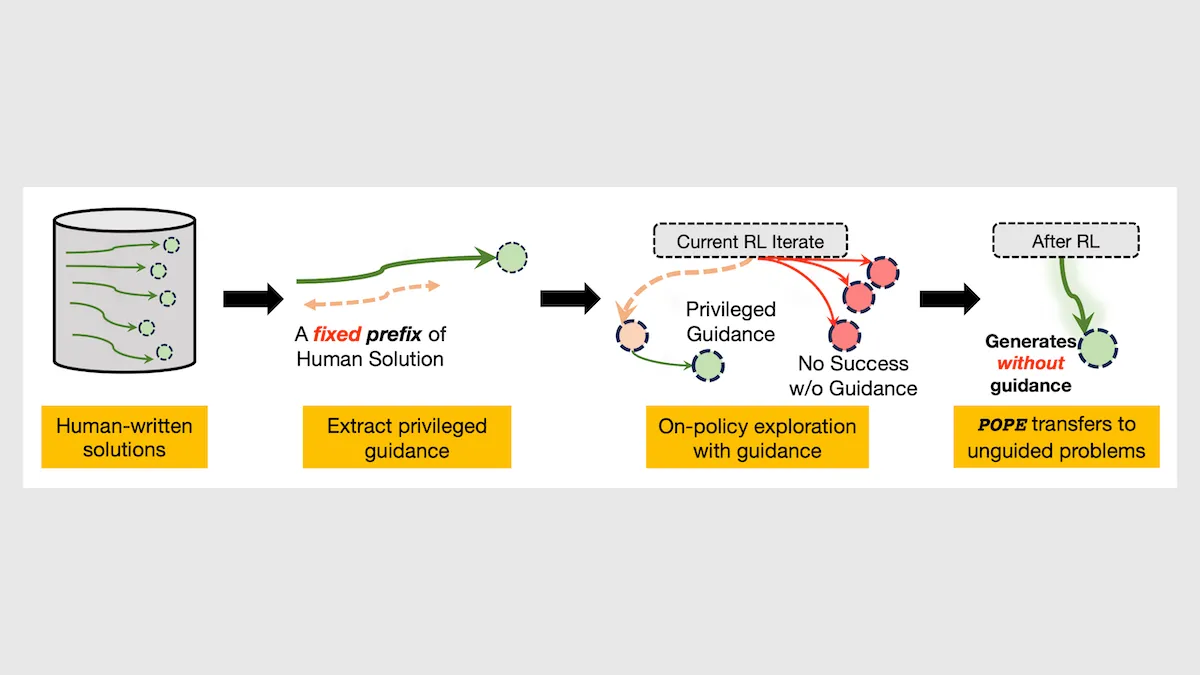
Reinforcement Learning With Hints: Privileged On-Policy Exploration (POPE) trains models to expand on partial solutions
Reinforcement learning can’t train a model to solve a difficult problem if the model doesn’t discover all the right steps.
6 Posts

Reinforcement learning can’t train a model to solve a difficult problem if the model doesn’t discover all the right steps.

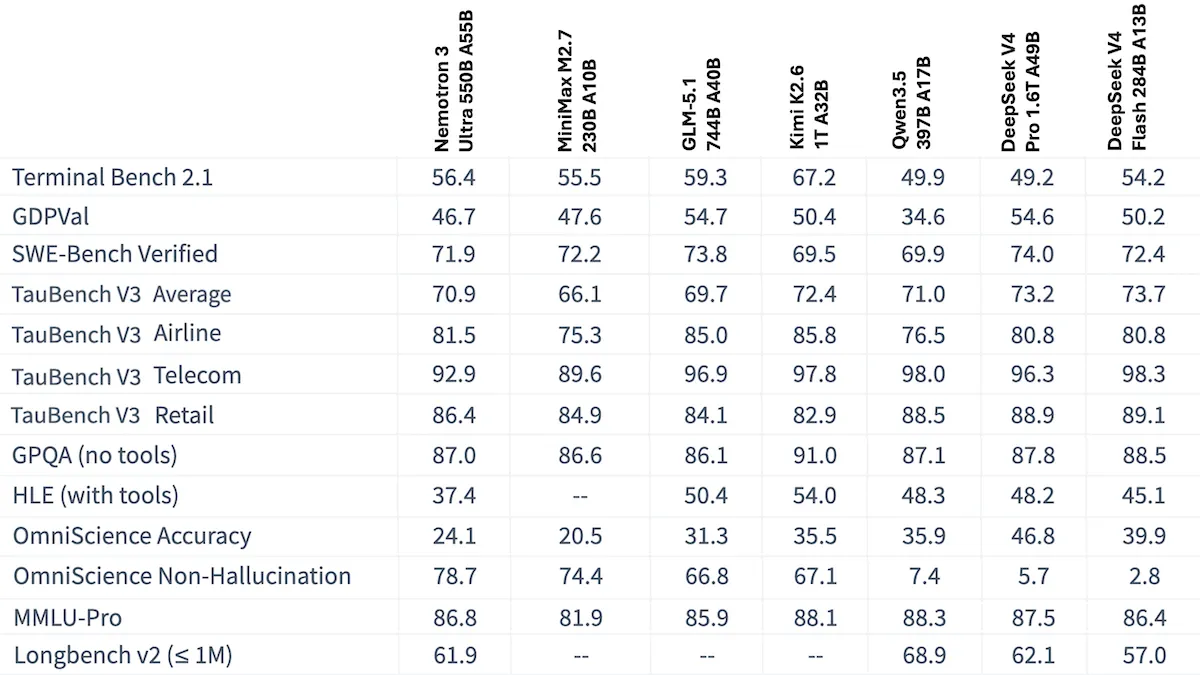
Nvidia’s largest-yet model is among the best-performing from a developer based in the U.S. and among the most open developed by anyone.

SWE-bench, a family of benchmarks that focuses on an LLM’s ability to fix software bugs, is giving way to new tests that evaluate agent software-engineering performance in more challenging ways.

Before Anthropic pulled its latest Claude models from circulation, even professional testers couldn’t readily tell whether they were getting a Mythos-class model or a lesser version under the same name.

Over the last two weeks, both the U.S. Government and Anthropic took significant actions that demonstrated their power to control access to AI by restricting what others can do with frontier models.

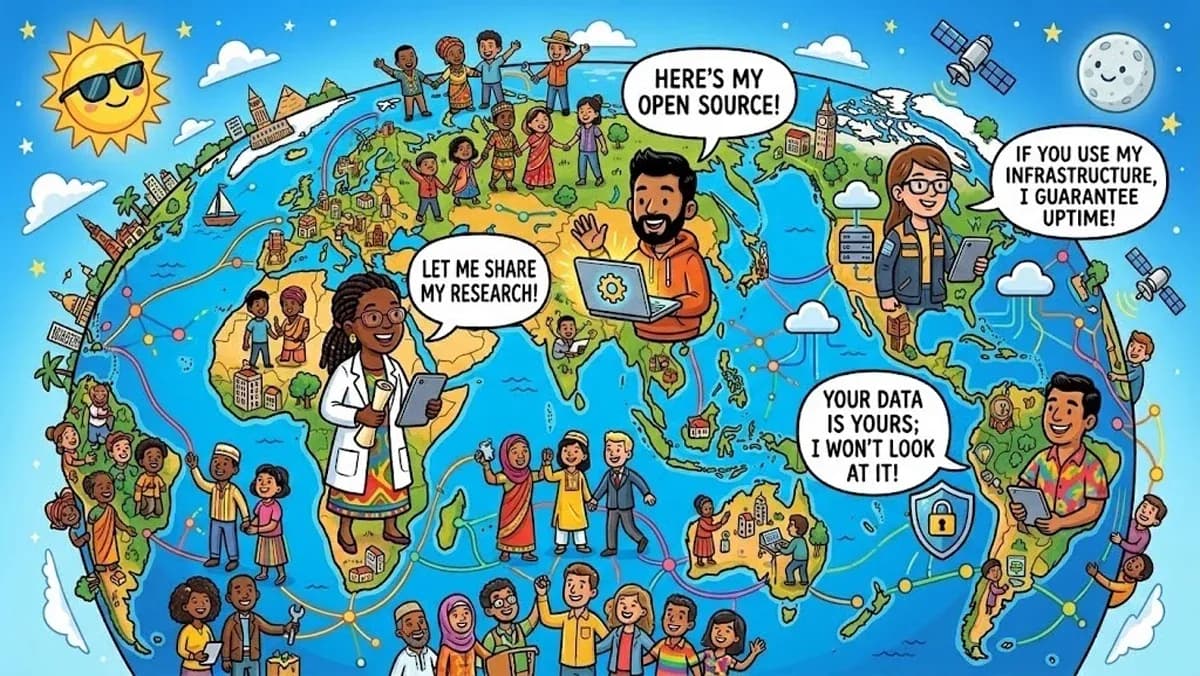
The Batch AI News and Insights: Over the last two weeks, both the U.S. Government and Anthropic took significant actions that demonstrated their power to control access to AI by restricting what others can do with frontier models.
Stay updated with weekly AI News and Insights delivered to your inbox