ImageNet

32 Posts

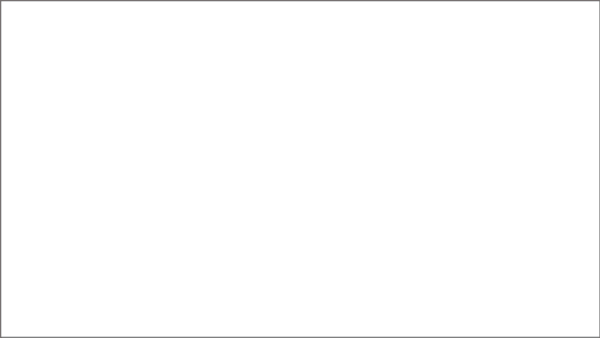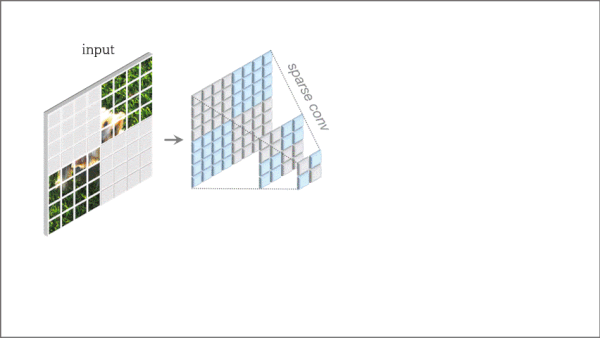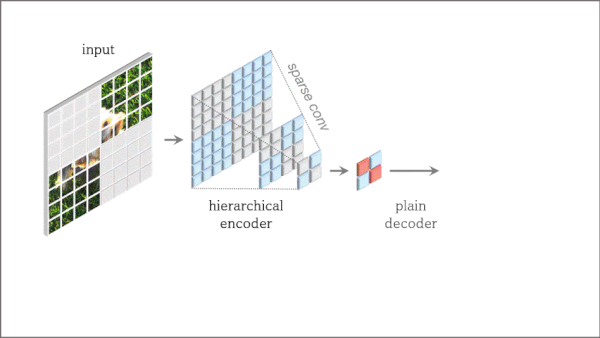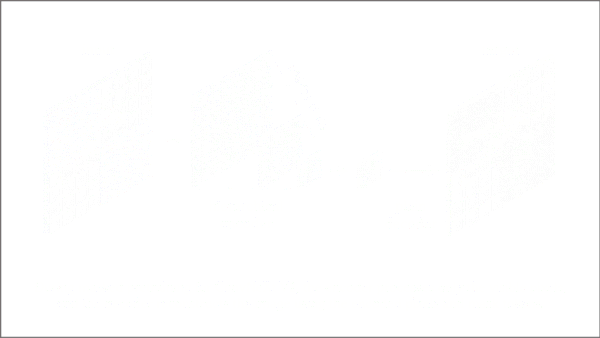
Masked Pretraining for CNNs: ConvNeXt V2, the new model family that boosts ConvNet performance
ImageNet

Masked Pretraining for CNNs: ConvNeXt V2, the new model family that boosts ConvNet performance

Vision transformers have bested convolutional neural networks (CNNs) in a number of key vision tasks. Have CNNs hit their limit? New research suggests otherwise.

September 13, 20232 min read
Masked Pretraining for CNNs: ConvNeXt V2, the new model family that boosts ConvNet performance
ImageNet

Masked Pretraining for CNNs: ConvNeXt V2, the new model family that boosts ConvNet performance

Vision transformers have bested convolutional neural networks (CNNs) in a number of key vision tasks. Have CNNs hit their limit? New research suggests otherwise.

September 13, 20232 min read
Vision Transformers Made Manageable: FlexiViT, the vision transformer that allows users to specify the patch size
ImageNet

Vision Transformers Made Manageable: FlexiViT, the vision transformer that allows users to specify the patch size

Vision transformers typically process images in patches of fixed size. Smaller patches yield higher accuracy but require more computation. A new training method lets AI engineers adjust the tradeoff.

August 23, 20232 min read
Vision Transformers Made Manageable: FlexiViT, the vision transformer that allows users to specify the patch size
ImageNet

Vision Transformers Made Manageable: FlexiViT, the vision transformer that allows users to specify the patch size

Vision transformers typically process images in patches of fixed size. Smaller patches yield higher accuracy but require more computation. A new training method lets AI engineers adjust the tradeoff.

August 23, 20232 min read
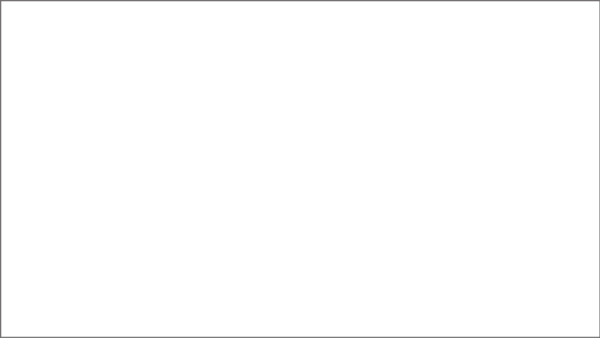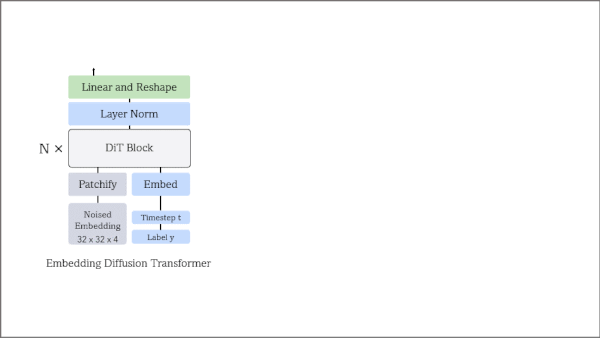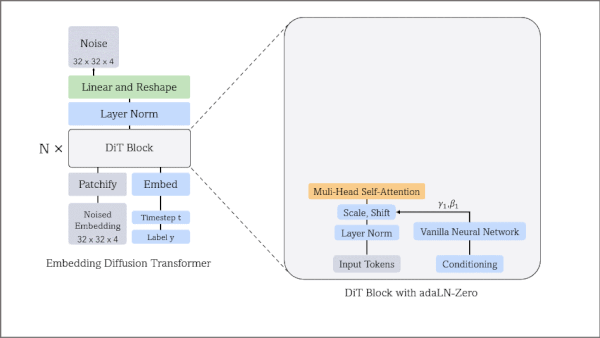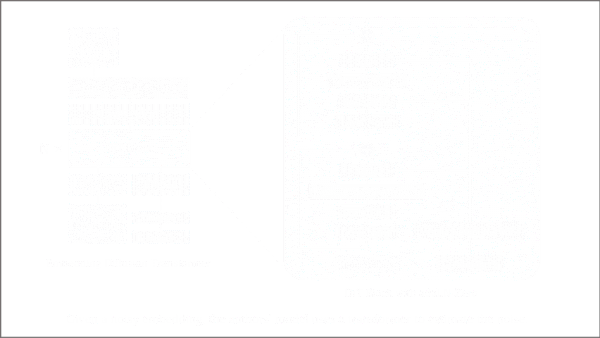
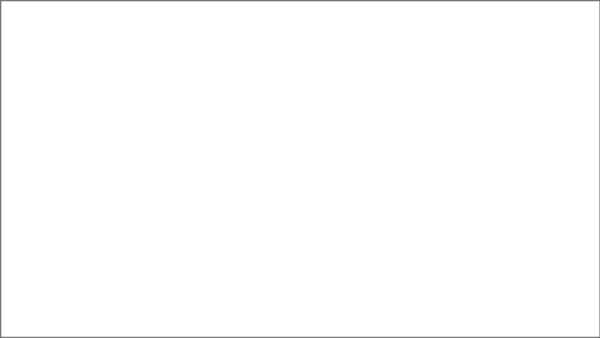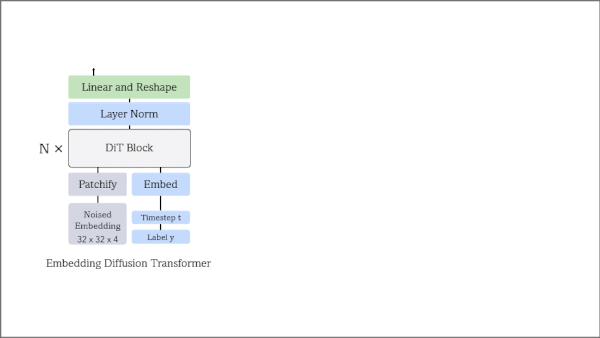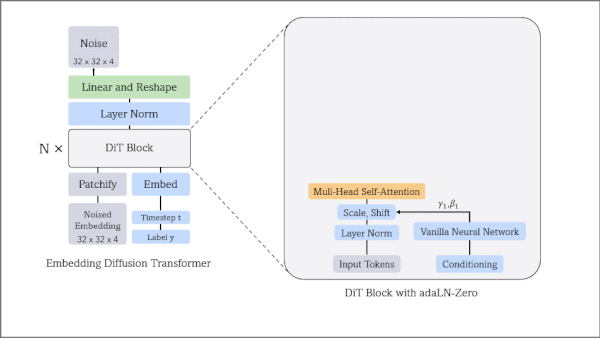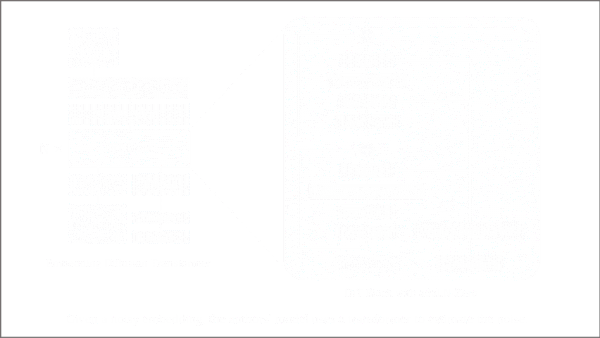
Diffusion Transformed: A new class of diffusion models based on the transformer architecture
ImageNet

Diffusion Transformed: A new class of diffusion models based on the transformer architecture

A tweak to diffusion models, which are responsible for most of the recent excitement about AI-generated images, enables them to produce more realistic output.

August 9, 20232 min read
Diffusion Transformed: A new class of diffusion models based on the transformer architecture
ImageNet

Diffusion Transformed: A new class of diffusion models based on the transformer architecture

A tweak to diffusion models, which are responsible for most of the recent excitement about AI-generated images, enables them to produce more realistic output.

August 9, 20232 min read
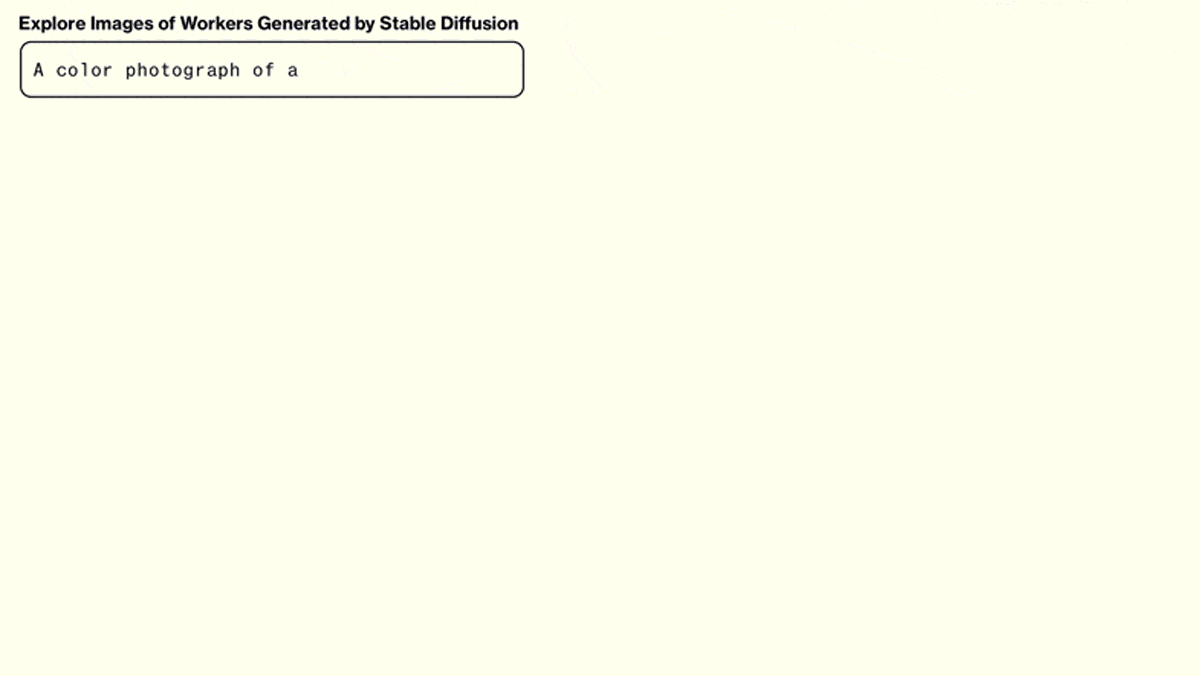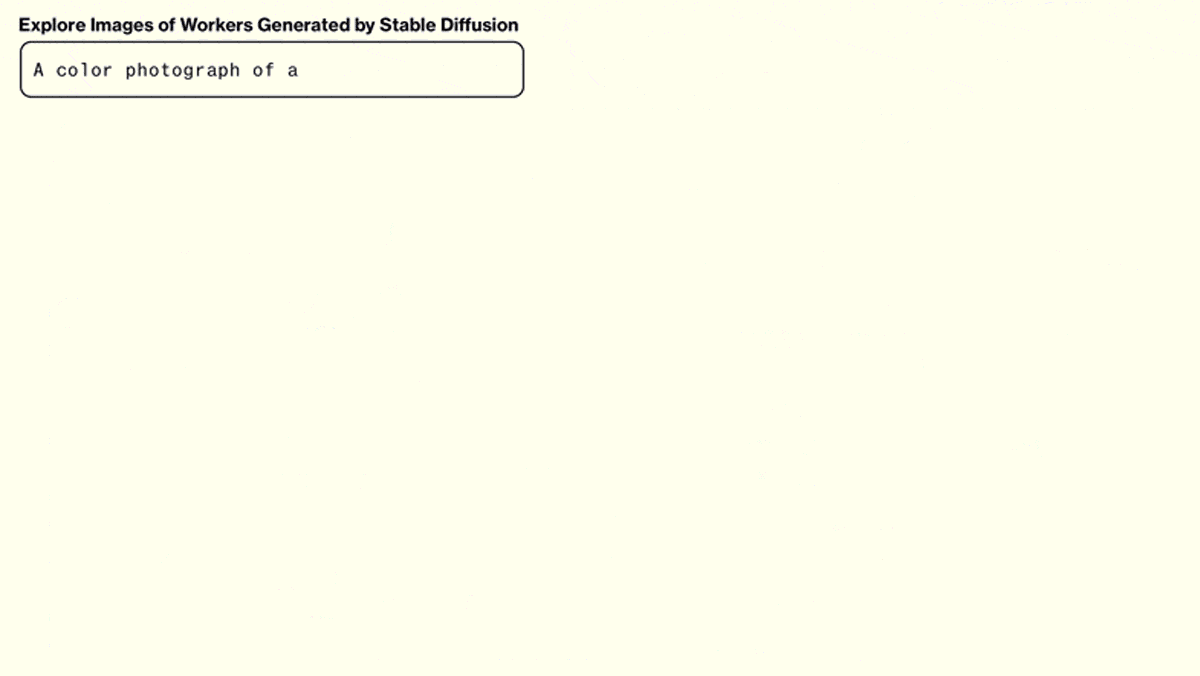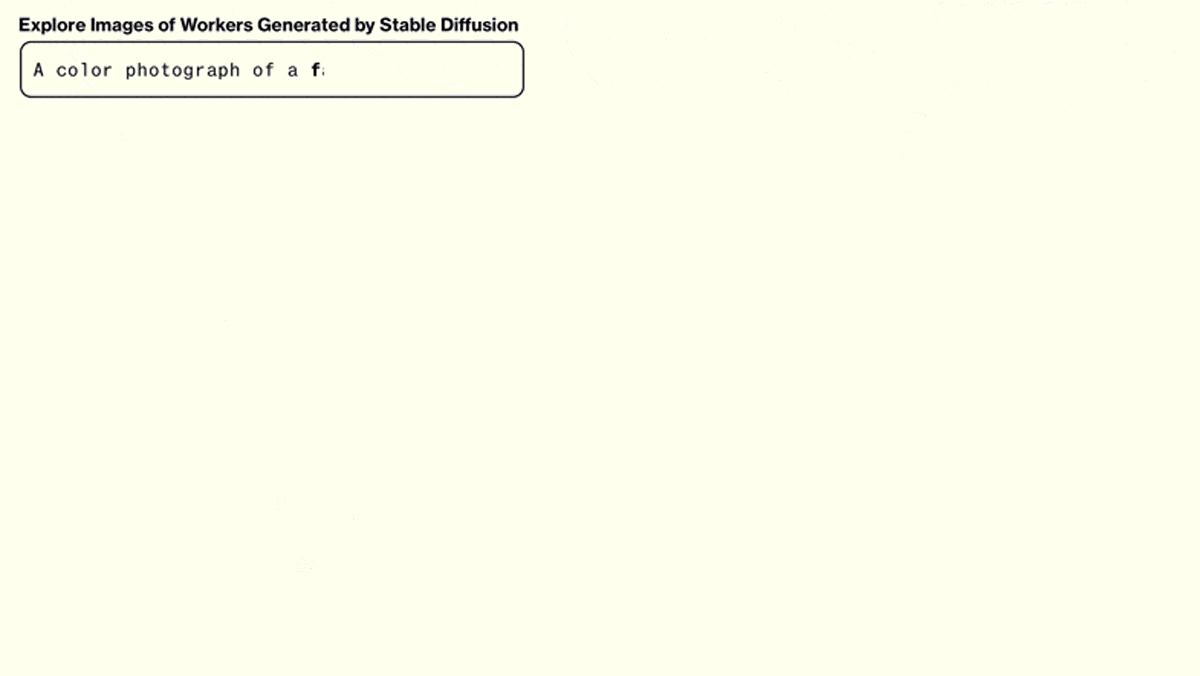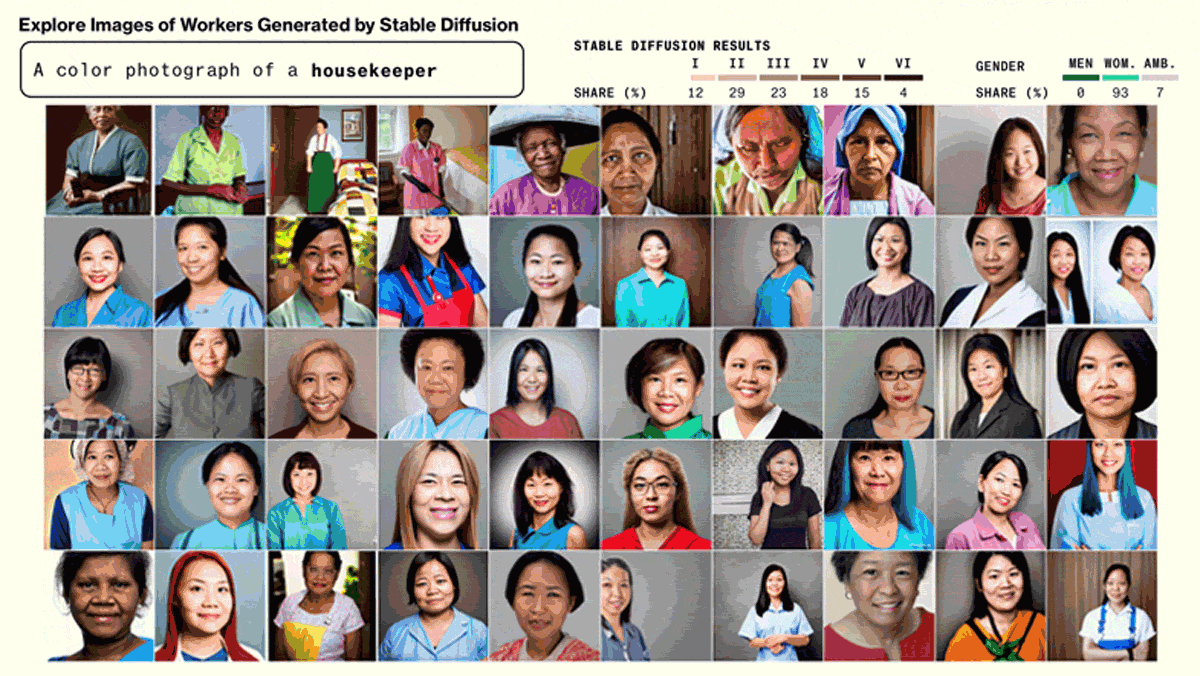
Stable Biases: Stable Diffusion may amplify biases in its training data.
ImageNet

Stable Biases: Stable Diffusion may amplify biases in its training data.

Stable Diffusion may amplify biases in its training data in ways that promote deeply ingrained social stereotypes.

July 12, 20233 min read
Stable Biases: Stable Diffusion may amplify biases in its training data.
ImageNet

Stable Biases: Stable Diffusion may amplify biases in its training data.

Stable Diffusion may amplify biases in its training data in ways that promote deeply ingrained social stereotypes.

July 12, 20233 min read
Cookbook for Vision Transformers: A Formula for Training Vision Transformers
ImageNet

Cookbook for Vision Transformers: A Formula for Training Vision Transformers

Vision Transformers (ViTs) are overtaking convolutional neural networks (CNN) in many vision tasks, but procedures for training them are still tailored for CNNs. New research investigated how various training ingredients affect ViT performance.

September 28, 20222 min read
Cookbook for Vision Transformers: A Formula for Training Vision Transformers
ImageNet

Cookbook for Vision Transformers: A Formula for Training Vision Transformers

Vision Transformers (ViTs) are overtaking convolutional neural networks (CNN) in many vision tasks, but procedures for training them are still tailored for CNNs. New research investigated how various training ingredients affect ViT performance.

September 28, 20222 min read
Abeba Birhane: Clean up web datasets
ImageNet

Abeba Birhane: Clean up web datasets

From language to vision models, deep neural networks are marked by improved performance, higher efficiency, and better generalizations. Yet, these systems are also marked by perpetuation of bias and injustice.

December 29, 20213 min read
Abeba Birhane: Clean up web datasets
ImageNet

Abeba Birhane: Clean up web datasets

From language to vision models, deep neural networks are marked by improved performance, higher efficiency, and better generalizations. Yet, these systems are also marked by perpetuation of bias and injustice.

December 29, 20213 min read
Transformer Speed-Up Sped Up: How to Speed Up Image Transformers
ImageNet

Transformer Speed-Up Sped Up: How to Speed Up Image Transformers

The transformer architecture is notoriously inefficient when processing long sequences — a problem in processing images, which are essentially long sequences of pixels. One way around this is to break up input images and process the pieces

October 13, 20211 min read
Transformer Speed-Up Sped Up: How to Speed Up Image Transformers
ImageNet

Transformer Speed-Up Sped Up: How to Speed Up Image Transformers

The transformer architecture is notoriously inefficient when processing long sequences — a problem in processing images, which are essentially long sequences of pixels. One way around this is to break up input images and process the pieces

October 13, 20211 min read
Labeling Errors Everywhere: Many deep learning datasets contain mislabeled data.
ImageNet

Labeling Errors Everywhere: Many deep learning datasets contain mislabeled data.

Key machine learning datasets are riddled with mistakes. Several benchmark datasets are shot through with incorrect labels. On average, 3.4 percent of examples in 10 commonly used datasets are mislabeled and the detrimental impact of such errors rises with model size.

April 14, 20212 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox