GPT-4V

4 Posts

Text or Images, Input or Output: GILL, an innovative approach to multimodal model training
GPT-4V

Text or Images, Input or Output: GILL, an innovative approach to multimodal model training

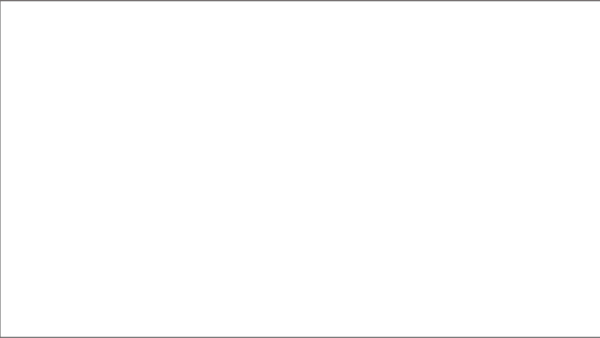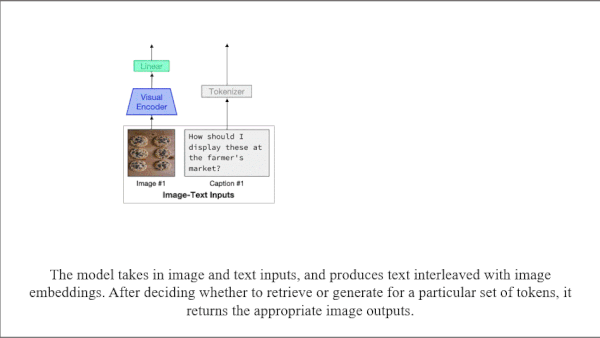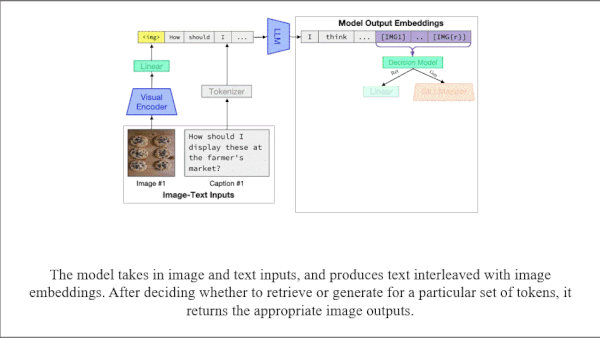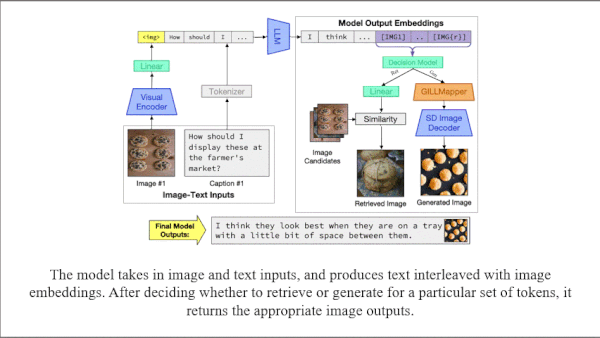
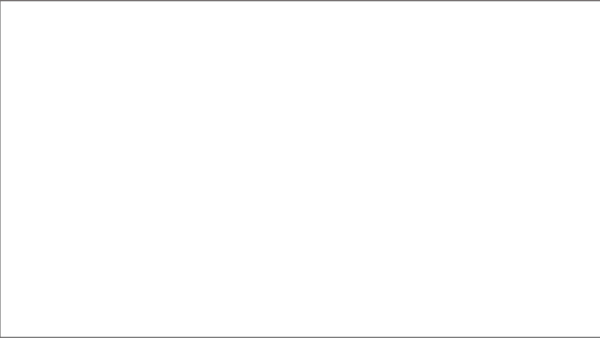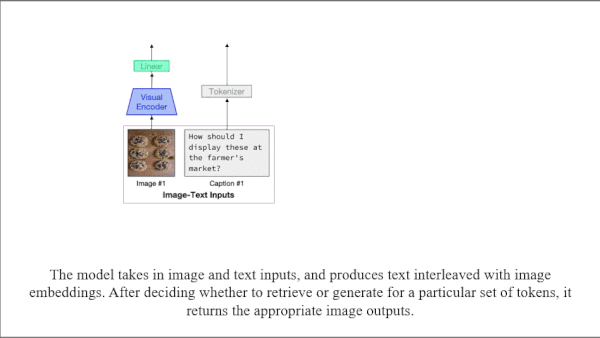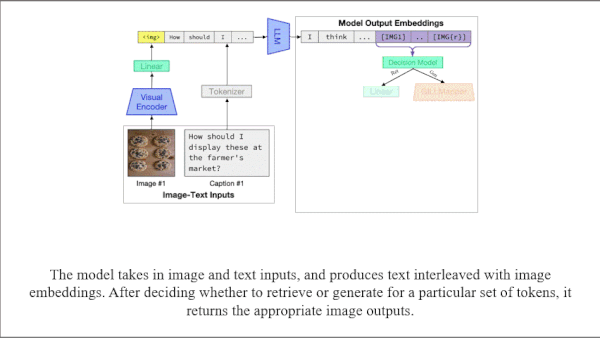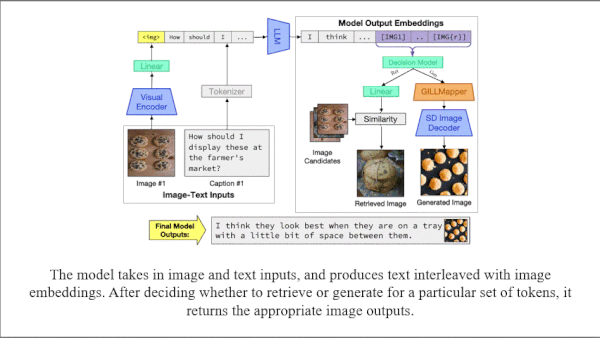
GPT-4V introduced a large multimodal model that generates text from images and, with help from DALL-E 3, generates images from text. However, OpenAI hasn’t fully explained how it built the system. A separate group of researchers described their own method.
January 10, 20243 min read
Text or Images, Input or Output: GILL, an innovative approach to multimodal model training
GPT-4V

Text or Images, Input or Output: GILL, an innovative approach to multimodal model training

GPT-4V introduced a large multimodal model that generates text from images and, with help from DALL-E 3, generates images from text. However, OpenAI hasn’t fully explained how it built the system. A separate group of researchers described their own method.

January 10, 20243 min read
GPT-4 Opens Its Eyes: Early insights into what OpenAI's GPT-4 with Vision can do
GPT-4V

GPT-4 Opens Its Eyes: Early insights into what OpenAI's GPT-4 with Vision can do

Few people have had a chance to try out OpenAI’s GPT-4 with Vision (GPT-4V), but many of those who have played with it expressed excitement. 

October 11, 20233 min read
GPT-4 Opens Its Eyes: Early insights into what OpenAI's GPT-4 with Vision can do
GPT-4V

GPT-4 Opens Its Eyes: Early insights into what OpenAI's GPT-4 with Vision can do

Few people have had a chance to try out OpenAI’s GPT-4 with Vision (GPT-4V), but many of those who have played with it expressed excitement. 

October 11, 20233 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox