Efficiency
Moderating the ML Roller Coaster: A technique to avoid double descent in AI
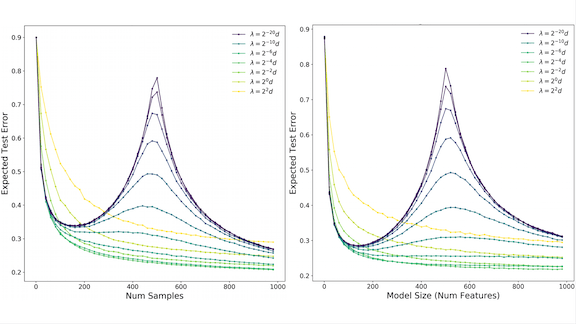
Wait a minute — we added training data, and our model’s performance got worse?! New research offers a way to avoid so-called double descent.

Wait a minute — we added training data, and our model’s performance got worse?! New research offers a way to avoid so-called double descent.
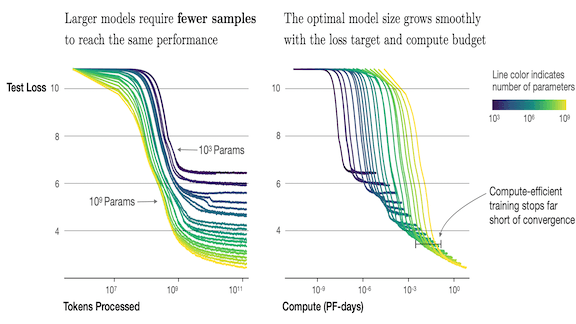
Last week we reported on a formula to determine model width and dataset size for optimal performance. A new paper contributes equations that optimize some training parameters.
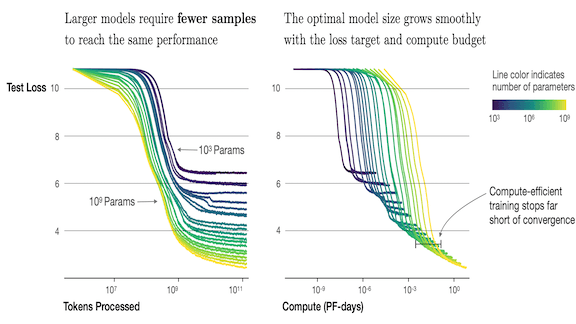
Last week we reported on a formula to determine model width and dataset size for optimal performance. A new paper contributes equations that optimize some training parameters.
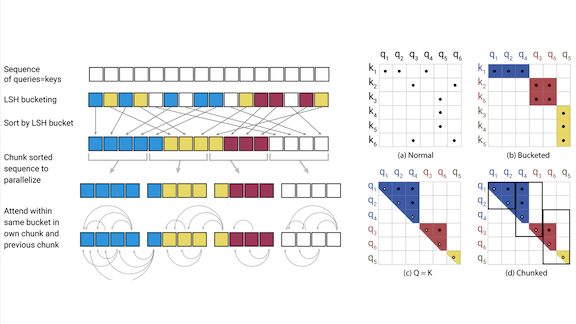
Transformer networks have revolutionized natural language processing, but they hog processor cycles and memory. New research demonstrates a more frugal variation.
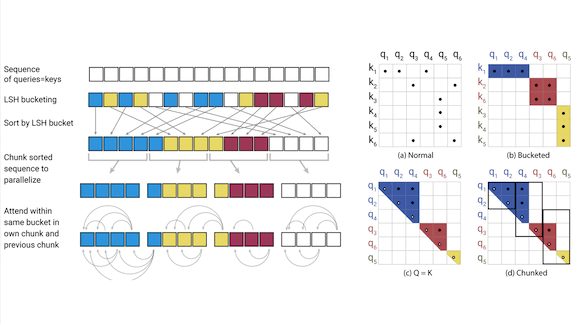
Transformer networks have revolutionized natural language processing, but they hog processor cycles and memory. New research demonstrates a more frugal variation.
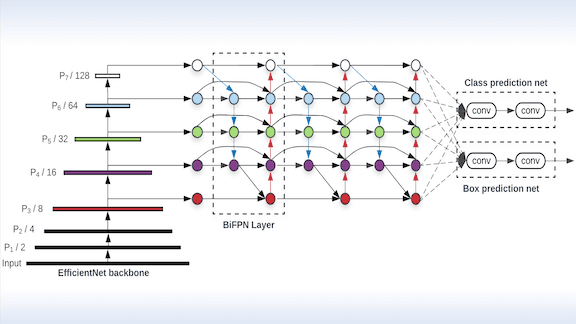
Researchers aiming to increase accuracy in object detection generally enlarge the network, but that approach also boosts computational cost. A novel architecture sets a new state of the art in accuracy while cutting the compute cycles required.

Researchers aiming to increase accuracy in object detection generally enlarge the network, but that approach also boosts computational cost. A novel architecture sets a new state of the art in accuracy while cutting the compute cycles required.
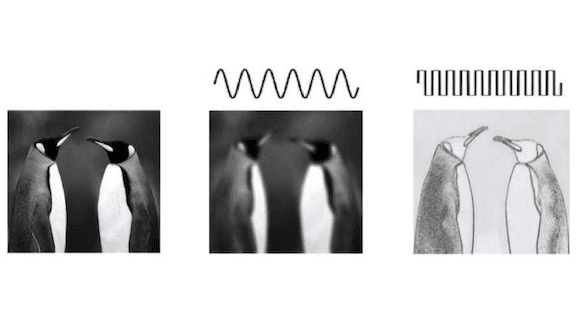
Looking at images, people see outlines before the details within them. A replacement for the traditional convolutional layer decomposes images based on this distinction between coarse and fine features.

Looking at images, people see outlines before the details within them. A replacement for the traditional convolutional layer decomposes images based on this distinction between coarse and fine features.

As neural networks have become more accurate, they’ve also ballooned in size and computational cost. That makes many state-of-the-art models impractical to run on phones and potentially smaller, less powerful devices.
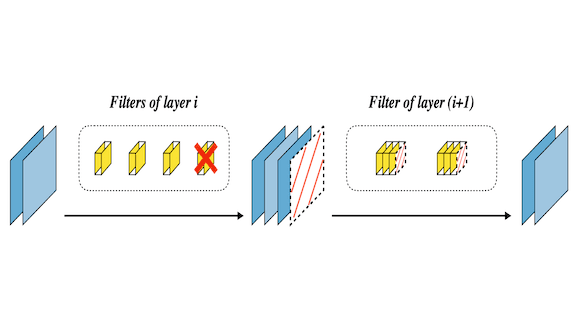
As neural networks have become more accurate, they’ve also ballooned in size and computational cost. That makes many state-of-the-art models impractical to run on phones and potentially smaller, less powerful devices.

Elon Musk has promised a fleet of autonomous Tesla taxis by 2020. The company reportedly purchased a computer vision startup to help meet that goal. Tesla acquired DeepScale, a Silicon Valley startup that rocesses computer vision on low-power electronics.

Elon Musk has promised a fleet of autonomous Tesla taxis by 2020. The company reportedly purchased a computer vision startup to help meet that goal. Tesla acquired DeepScale, a Silicon Valley startup that rocesses computer vision on low-power electronics.

Deep learning models can be unwieldy and often impractical to run on smaller devices without major modification. Researchers at Facebook AI Research found a way to compress neural networks with minimal sacrifice in accuracy.

Deep learning models can be unwieldy and often impractical to run on smaller devices without major modification. Researchers at Facebook AI Research found a way to compress neural networks with minimal sacrifice in accuracy.
Stay updated with weekly AI News and Insights delivered to your inbox