Direct Preference Optimization (DPO)

11 Posts

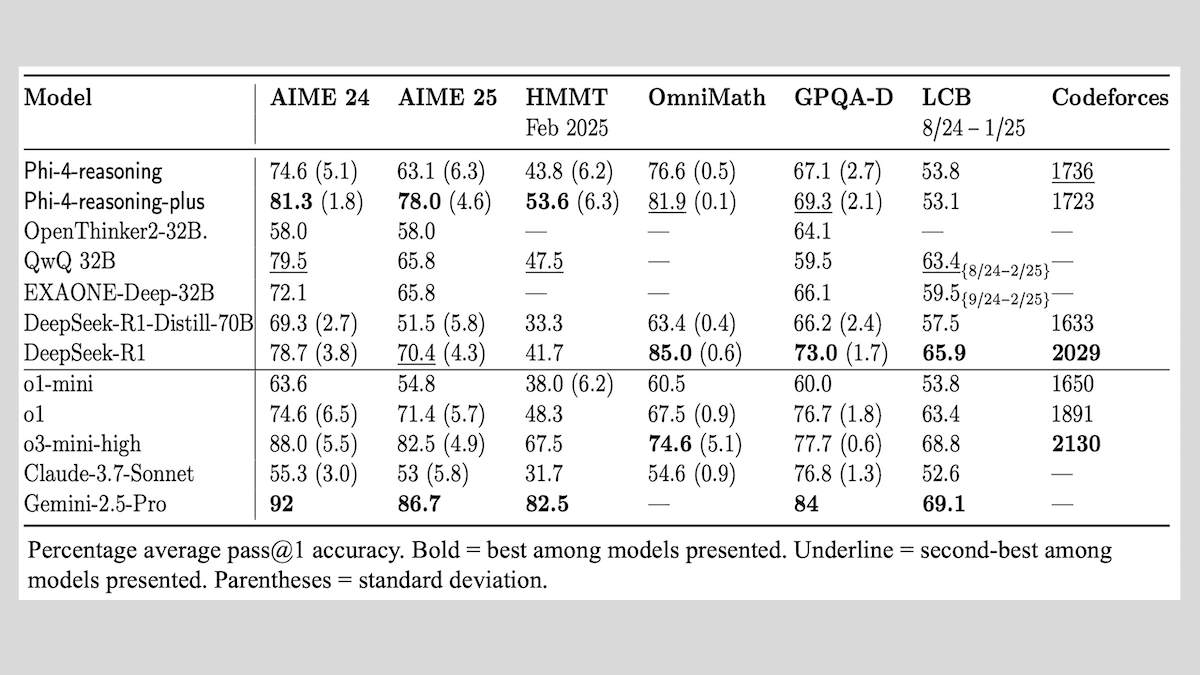
Reasoning Models With Recipes: Microsoft unveils training details for Phi-4-reasoning, Phi-4-reasoning-plus, and Phi-4-mini-reasoning
Direct Preference Optimization (DPO)

Reasoning Models With Recipes: Microsoft unveils training details for Phi-4-reasoning, Phi-4-reasoning-plus, and Phi-4-mini-reasoning

Microsoft published its latest recipe for training reasoning models, substantially expanding what is still a fairly small base of public knowledge.
May 14, 20253 min read
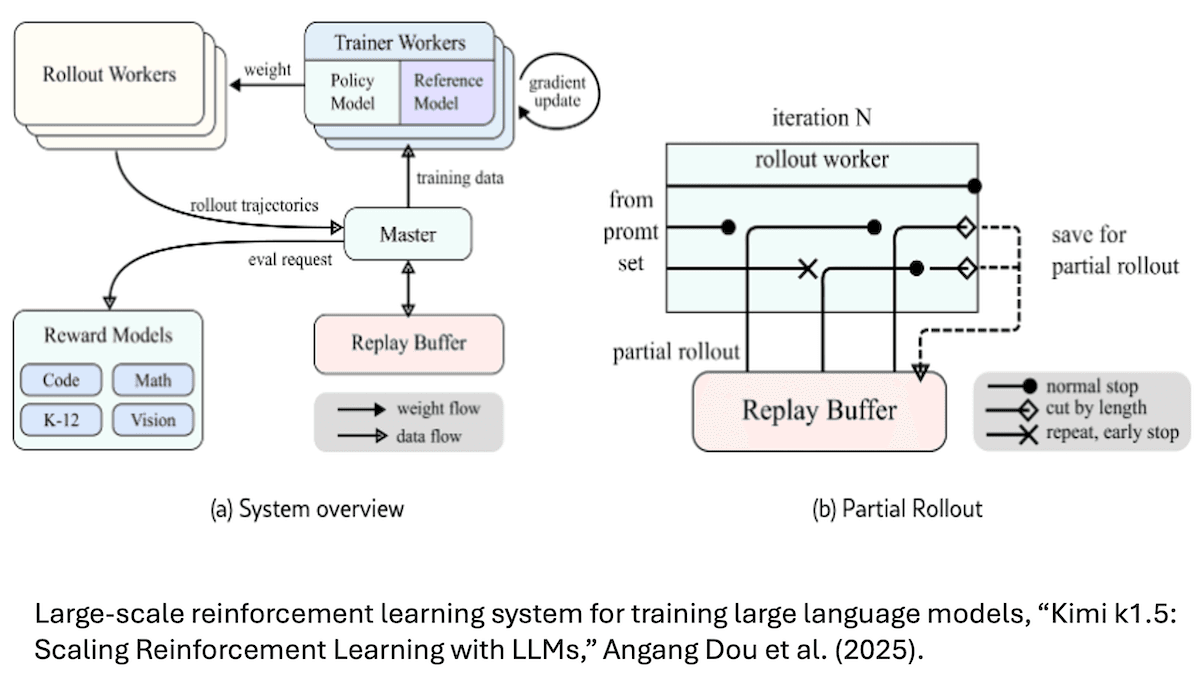
Reinforcement Learning Heats Up: How DeepSeek-R1 and Kimi k1.5 use reinforcement learning to improve reasoning
Direct Preference Optimization (DPO)

Reinforcement Learning Heats Up: How DeepSeek-R1 and Kimi k1.5 use reinforcement learning to improve reasoning

Reinforcement learning is emerging as an avenue for building large language models with advanced reasoning capabilities.

January 29, 20252 min read
Reinforcement Learning Heats Up: How DeepSeek-R1 and Kimi k1.5 use reinforcement learning to improve reasoning
Direct Preference Optimization (DPO)

Reinforcement Learning Heats Up: How DeepSeek-R1 and Kimi k1.5 use reinforcement learning to improve reasoning

Reinforcement learning is emerging as an avenue for building large language models with advanced reasoning capabilities.

January 29, 20252 min read
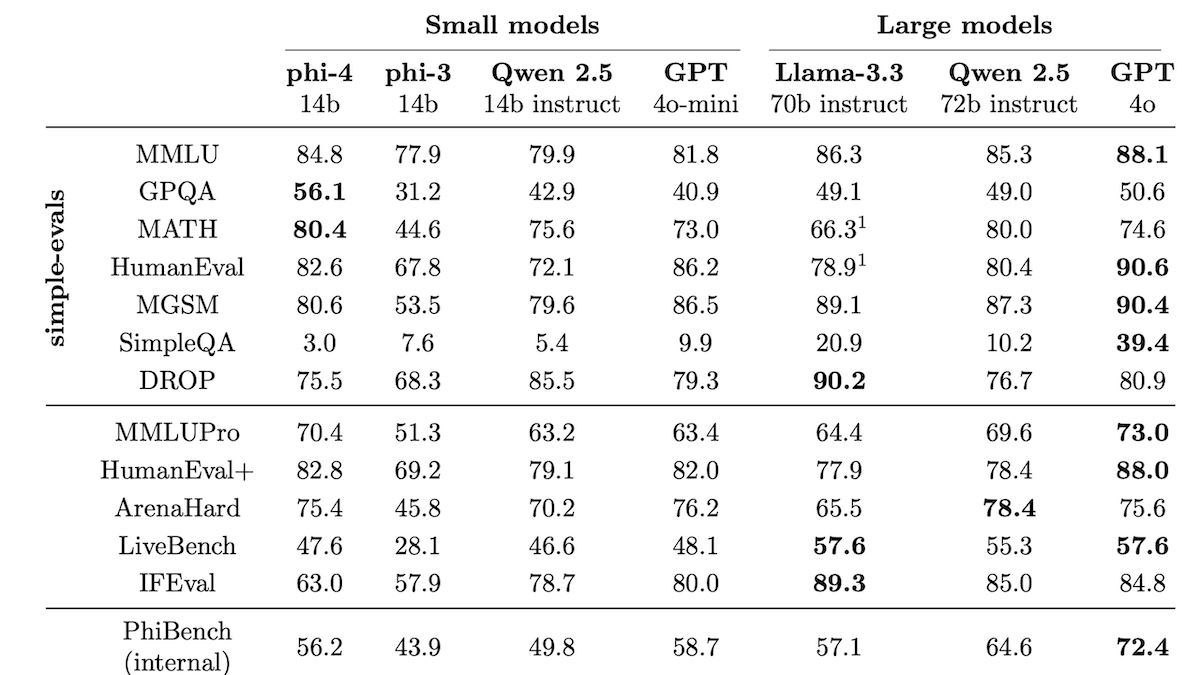
Phi-4 Beats Models Five Times Its Size: Microsoft’s Phi-4 blends synthetic and organic data to surpass larger models in math and reasoning benchmarks
Direct Preference Optimization (DPO)

Phi-4 Beats Models Five Times Its Size: Microsoft’s Phi-4 blends synthetic and organic data to surpass larger models in math and reasoning benchmarks

Microsoft updated its smallest model family with a single, surprisingly high-performance model.

December 18, 20243 min read
Phi-4 Beats Models Five Times Its Size: Microsoft’s Phi-4 learned from a blend of synthetic and organic data to surpass larger models in math and reasoning benchmarks
Direct Preference Optimization (DPO)

Phi-4 Beats Models Five Times Its Size: Microsoft’s Phi-4 learned from a blend of synthetic and organic data to surpass larger models in math and reasoning benchmarks

Microsoft updated its smallest model family with a single, surprisingly high-performance model.

December 18, 20243 min read
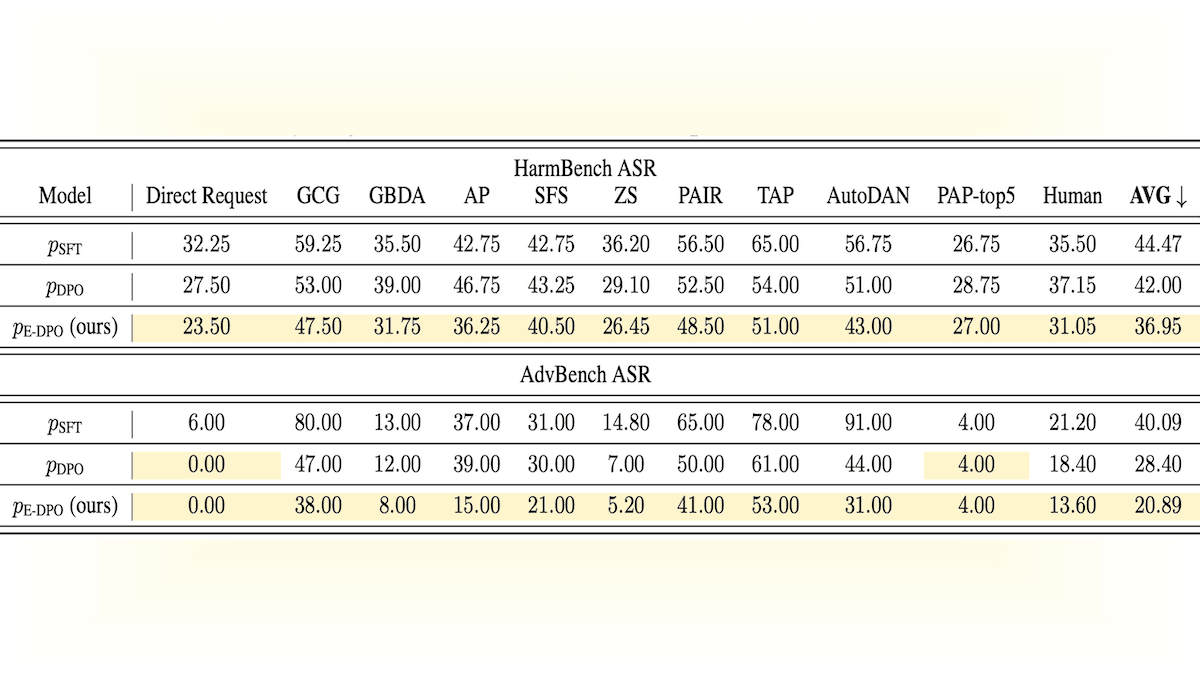
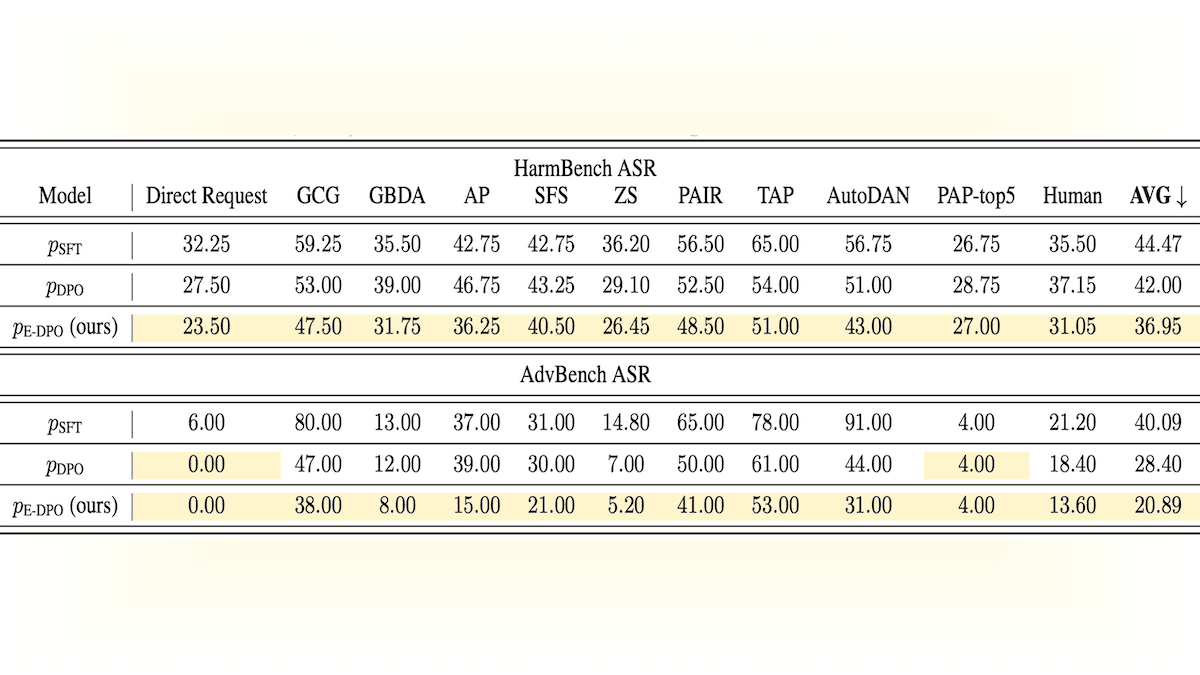
Breaking Jailbreaks: New E-DPO method strengthens defenses against jailbreak prompts
Direct Preference Optimization (DPO)

Breaking Jailbreaks: New E-DPO method strengthens defenses against jailbreak prompts

Jailbreak prompts can prod a large language model (LLM) to overstep built-in boundaries, leading it to do things like respond to queries it was trained to refuse to answer. Researchers devised a way to further boost the probability that LLMs will respond in ways that respect such limits.

December 4, 20242 min read
Breaking Jailbreaks: New E-DPO method strengthens defenses against jailbreak prompts
Direct Preference Optimization (DPO)

Breaking Jailbreaks: New E-DPO method strengthens defenses against jailbreak prompts

Jailbreak prompts can prod a large language model (LLM) to overstep built-in boundaries, leading it to do things like respond to queries it was trained to refuse to answer. Researchers devised a way to further boost the probability that LLMs will respond in ways that respect such limits.

December 4, 20242 min read
More Factual LLMs: FactTune, a method to fine-tune LLMs for factual accuracy without human feedback
Direct Preference Optimization (DPO)

More Factual LLMs: FactTune, a method to fine-tune LLMs for factual accuracy without human feedback

Large language models sometimes generate false statements. New work makes them more likely to produce factual output.

April 3, 20242 min read
More Factual LLMs: FactTune, a method to fine-tune LLMs for factual accuracy without human feedback
Direct Preference Optimization (DPO)

More Factual LLMs: FactTune, a method to fine-tune LLMs for factual accuracy without human feedback

Large language models sometimes generate false statements. New work makes them more likely to produce factual output.

April 3, 20242 min read
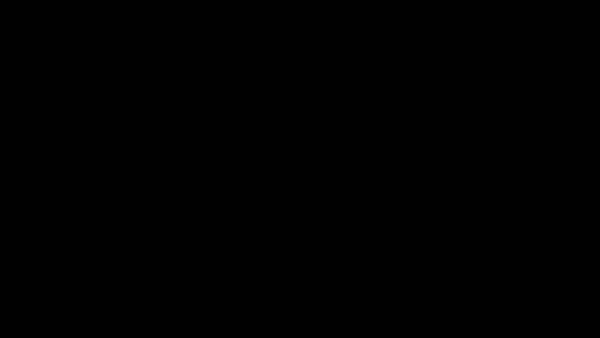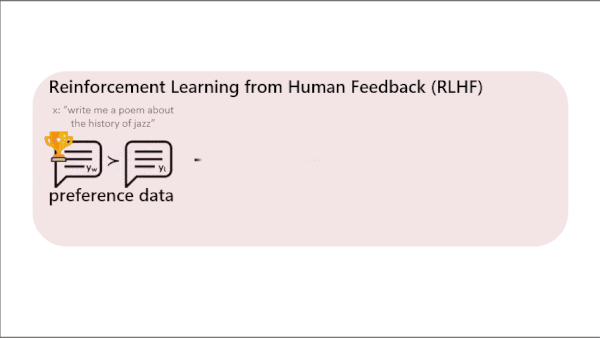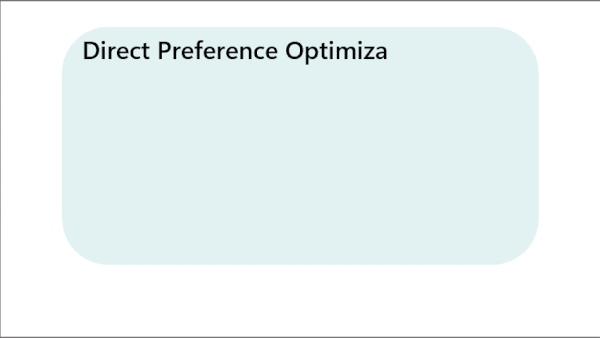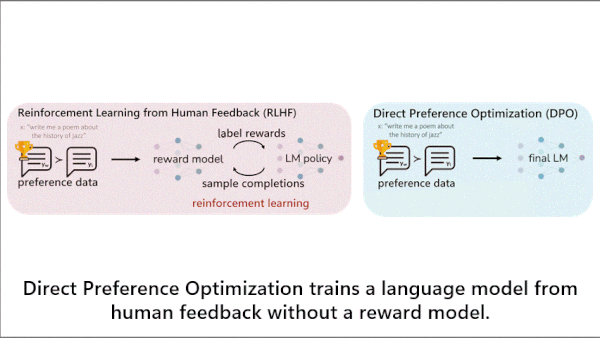
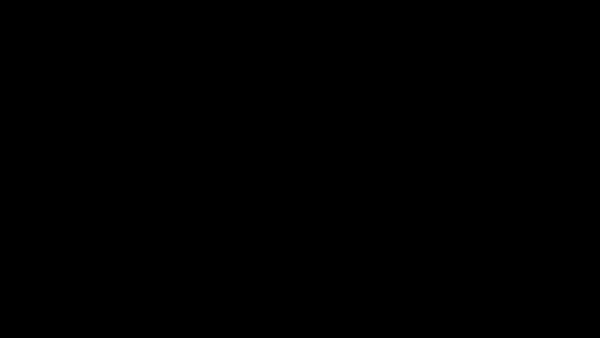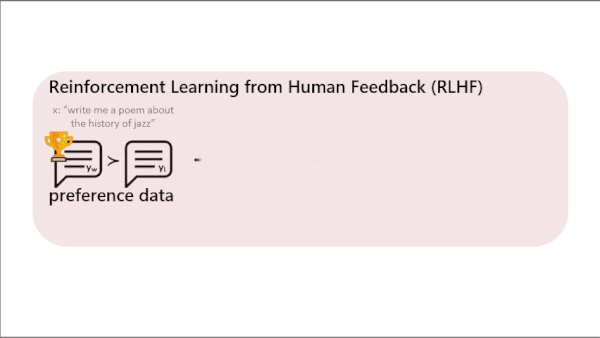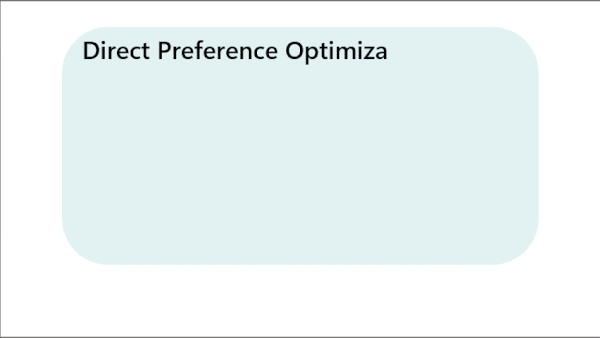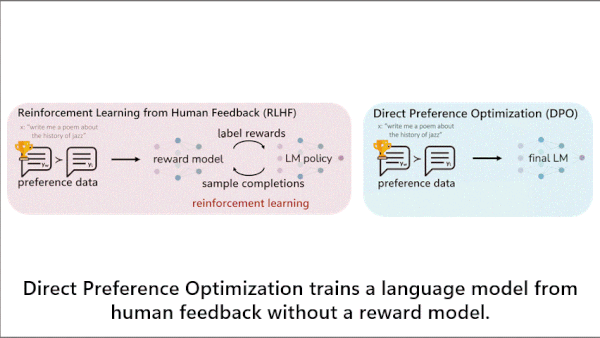
Human Feedback Without Reinforcement Learning: Direct Preference Optimization (DPO) fine-tunes pretrained large language models on human preferences without the cumbersome step of reinforcement learning.
Direct Preference Optimization (DPO)

Human Feedback Without Reinforcement Learning: Direct Preference Optimization (DPO) fine-tunes pretrained large language models on human preferences without the cumbersome step of reinforcement learning.

Reinforcement learning from human feedback (RLHF) is widely used to fine-tune pretrained models to deliver outputs that align with human preferences. New work aligns pretrained models without the cumbersome step of reinforcement learning.

February 29, 20242 min read
Human Feedback Without Reinforcement Learning: Direct Preference Optimization (DPO) fine-tunes pretrained large language models on human preferences without the cumbersome step of reinforcement learning.
Direct Preference Optimization (DPO)

Human Feedback Without Reinforcement Learning: Direct Preference Optimization (DPO) fine-tunes pretrained large language models on human preferences without the cumbersome step of reinforcement learning.

Reinforcement learning from human feedback (RLHF) is widely used to fine-tune pretrained models to deliver outputs that align with human preferences. New work aligns pretrained models without the cumbersome step of reinforcement learning.

February 29, 20242 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox