Computer Vision

51 Posts

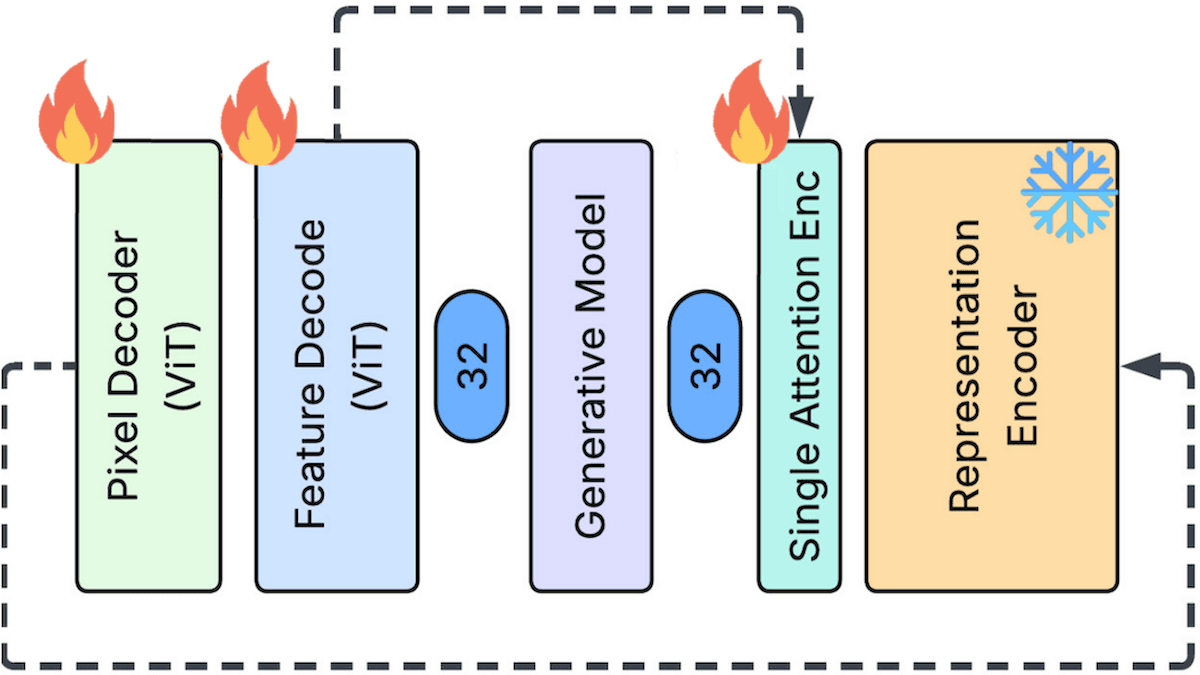
Lightning-Fast Diffusion Learning: Inside Feature Auto-Encoder, a diffusion image generator that shrinks embeddings for more speed
Computer Vision

Lightning-Fast Diffusion Learning: Inside Feature Auto-Encoder, a diffusion image generator that shrinks embeddings for more speed

Research shows that diffusion image generators can train somewhat faster if they learn to reconstruct embeddings from a pretrained encoder that’s built for vision tasks like classification, segmentation, and retrieval — not image generation.
March 16, 20263 min read
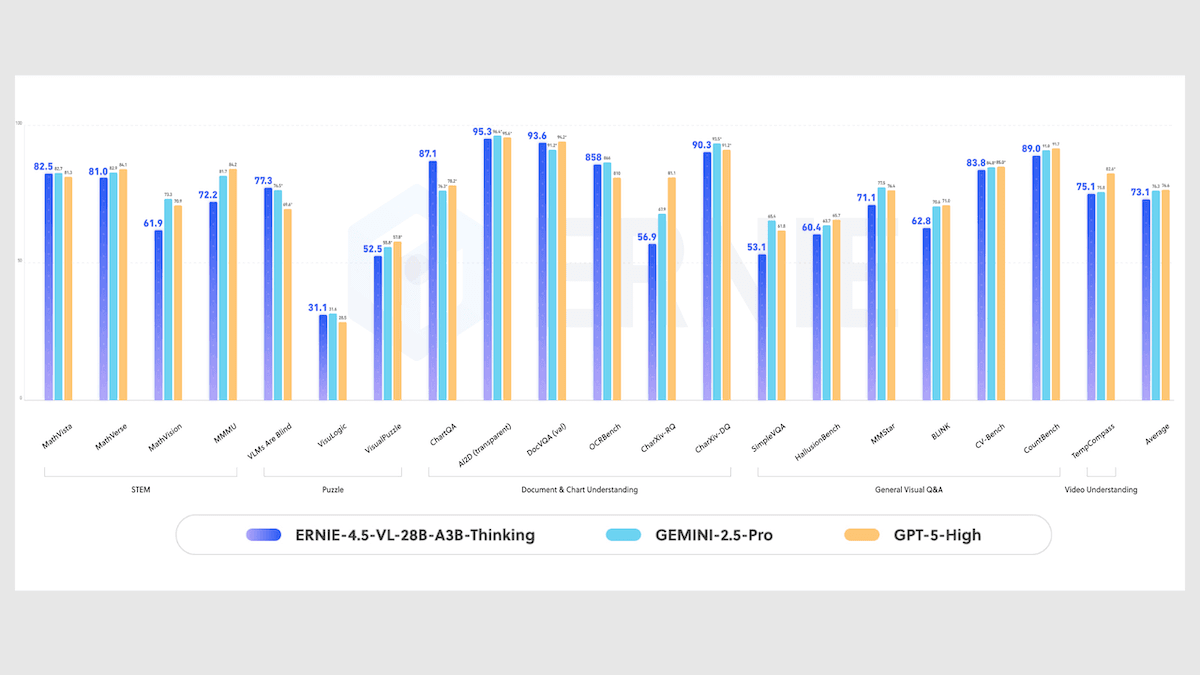
Baidu’s Multimodal Bids: Giant Ernie 5 natively generates multiple media; Ernie-4.5-VL-28B-A3B-Thinking tops Vision-Language metrics
Computer Vision

Baidu’s Multimodal Bids: Giant Ernie 5 natively generates multiple media; Ernie-4.5-VL-28B-A3B-Thinking tops Vision-Language metrics

Baidu debuted two models: a lightweight, open-weights, vision-language model and a giant, proprietary, multimodal model built to take on U.S. competitors.

December 3, 20253 min read
Generated, Editable Virtual Spaces: World Labs makes Marble world model public, adds Chisel editing tool
Computer Vision

Generated, Editable Virtual Spaces: World Labs makes Marble world model public, adds Chisel editing tool

Models that generate 3D spaces typically generate them as users move through them without generating a persistent world to be explored later. A new model produces 3D worlds that can be exported and modified.

December 3, 20252 min read
Open 3D Generation Pipeline: Meta’s SAM 3 image segmentation models can analyze and create bodies and other objects
Computer Vision

Open 3D Generation Pipeline: Meta’s SAM 3 image segmentation models can analyze and create bodies and other objects

Meta’s Segment Anything Model (SAM) image-segmentation model has evolved into an open-weights suite for generating 3D objects. SAM 3 segments images, SAM 3D turns the segments into 3D objects, and SAM 3D Body produces 3D objects of any people among the segments. You can experiment with all three.

December 3, 20253 min read
Earth Modeled in 10-Meter Squares: Google’s AlphaEarth Foundations tracks the whole planet’s climate, land use, potential for disasters, in detail and at scale
Computer Vision

Earth Modeled in 10-Meter Squares: Google’s AlphaEarth Foundations tracks the whole planet’s climate, land use, potential for disasters, in detail and at scale

Researchers built a model that integrates satellite imagery and other sensor readings across the entire surface of the Earth to reveal patterns of climate, land use, and other features.

October 1, 20253 min read
Better Image Processing Through Self-Supervised Learning: Meta’s DINOv3 gets an updated loss term and improved vision performance
Computer Vision

Better Image Processing Through Self-Supervised Learning: Meta’s DINOv3 gets an updated loss term and improved vision performance

DINOv2 showed that a vision transformer pretrained on unlabeled images could produce embeddings that are useful for a wide variety of tasks. Now it has been updated to improve the performance of its embeddings in segmentation and other vision tasks.

August 27, 20253 min read
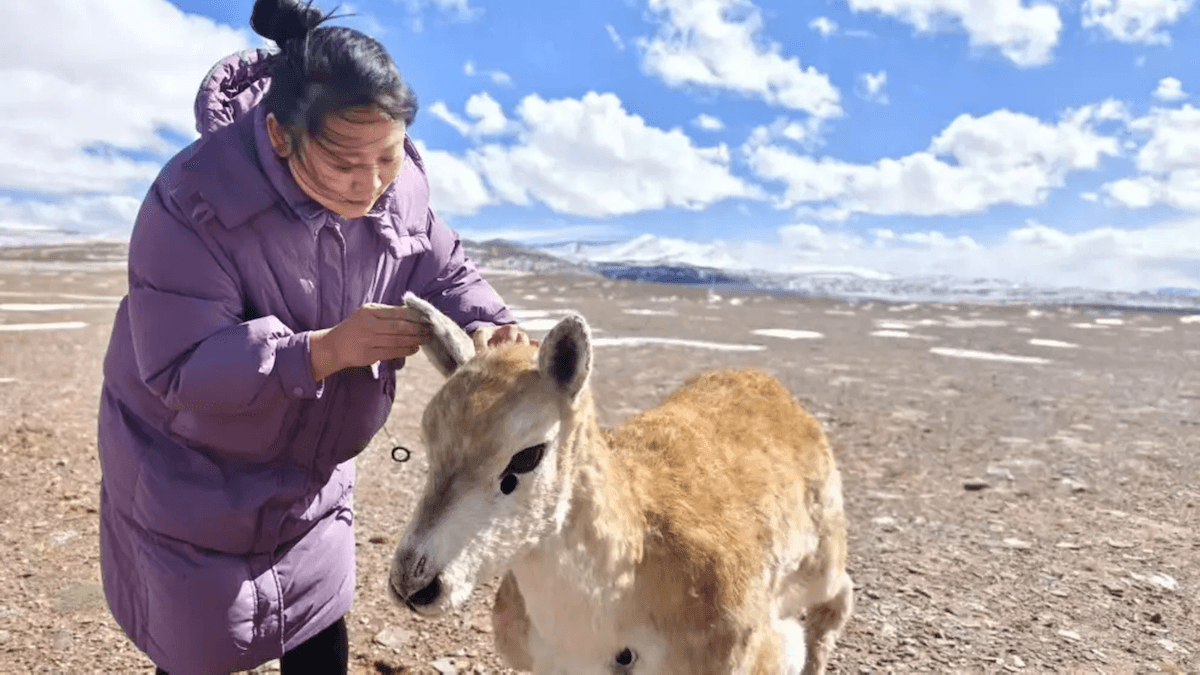
Robot Antelope Joins Herd: Chinese scientists disguise modified robot dog as antelope to study herd behavior
Computer Vision

Robot Antelope Joins Herd: Chinese scientists disguise modified robot dog as antelope to study herd behavior

Researchers in China disguised a quadruped robot as a Tibetan antelope to help study the animals close-up.

August 27, 20252 min read
Proactive AI Assistance for Phones: Inside Magic Cue, Google’s new AI assistant for Pixel 10
Computer Vision

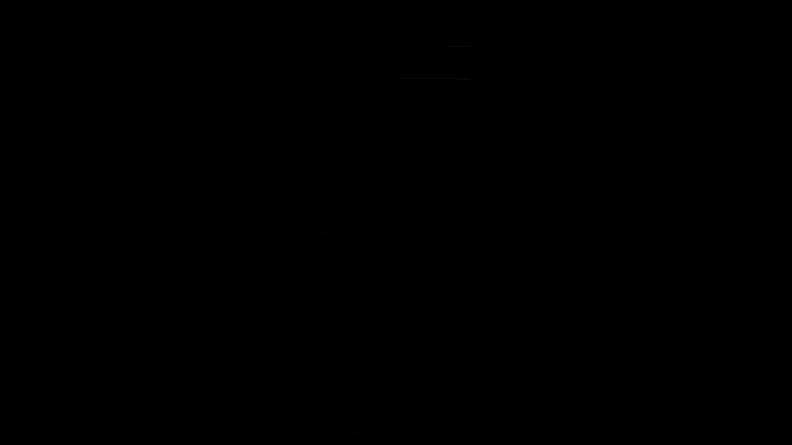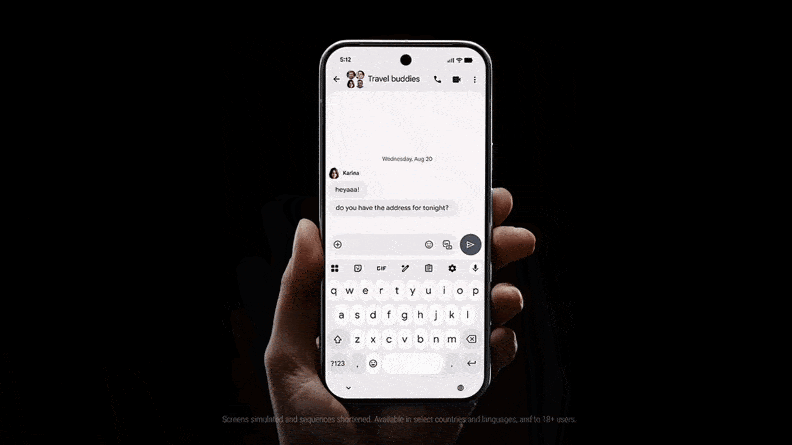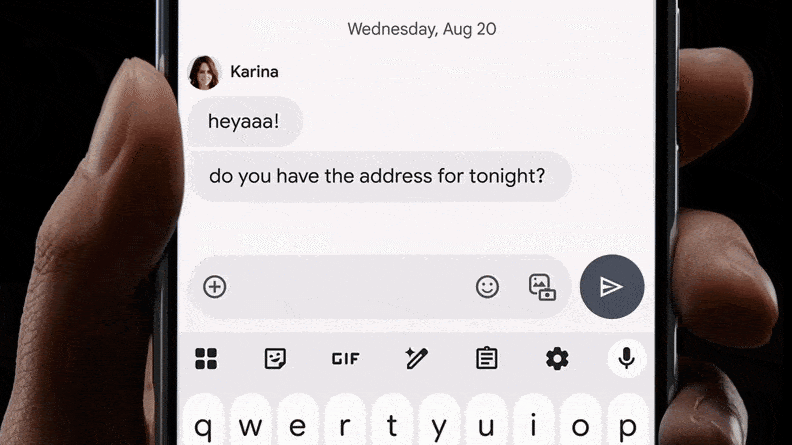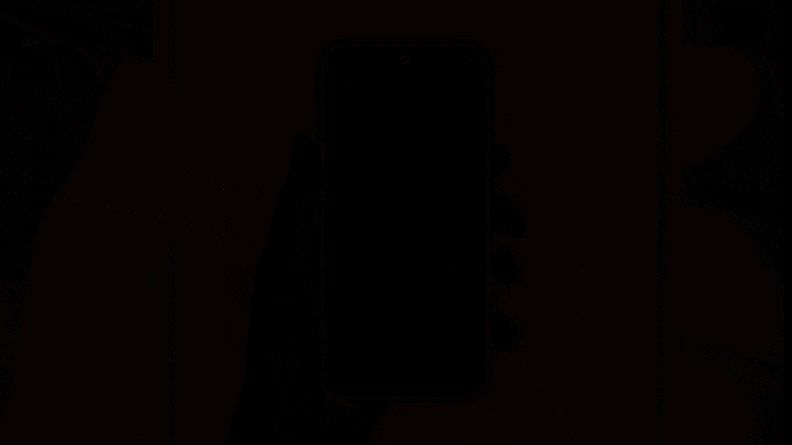
Proactive AI Assistance for Phones: Inside Magic Cue, Google’s new AI assistant for Pixel 10

Google’s latest smartphone sports an AI assistant that anticipates the user’s needs and presents helpful information without prompting.

August 27, 20252 min read
Robot Surgeon Cuts and Clips: Doctors at Stanford, Johns Hopkins, and Optosurgical operate on animal organs without human intervention
Computer Vision

Robot Surgeon Cuts and Clips: Doctors at Stanford, Johns Hopkins, and Optosurgical operate on animal organs without human intervention

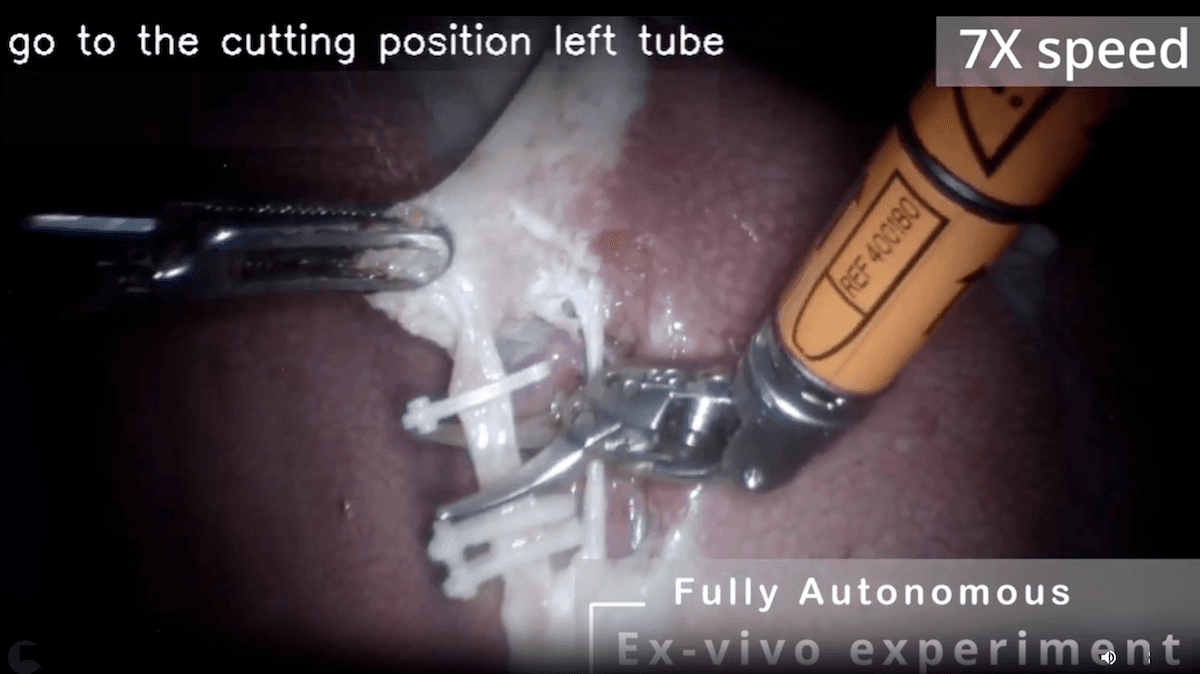
An autonomous robot performed intricate surgical operations without human intervention.

August 6, 20254 min read
Inside Walmart’s AI App Factory: Walmart’s Element platform for industrial-scale AI app development — a progress report
Computer Vision

Inside Walmart’s AI App Factory: Walmart’s Element platform for industrial-scale AI app development — a progress report

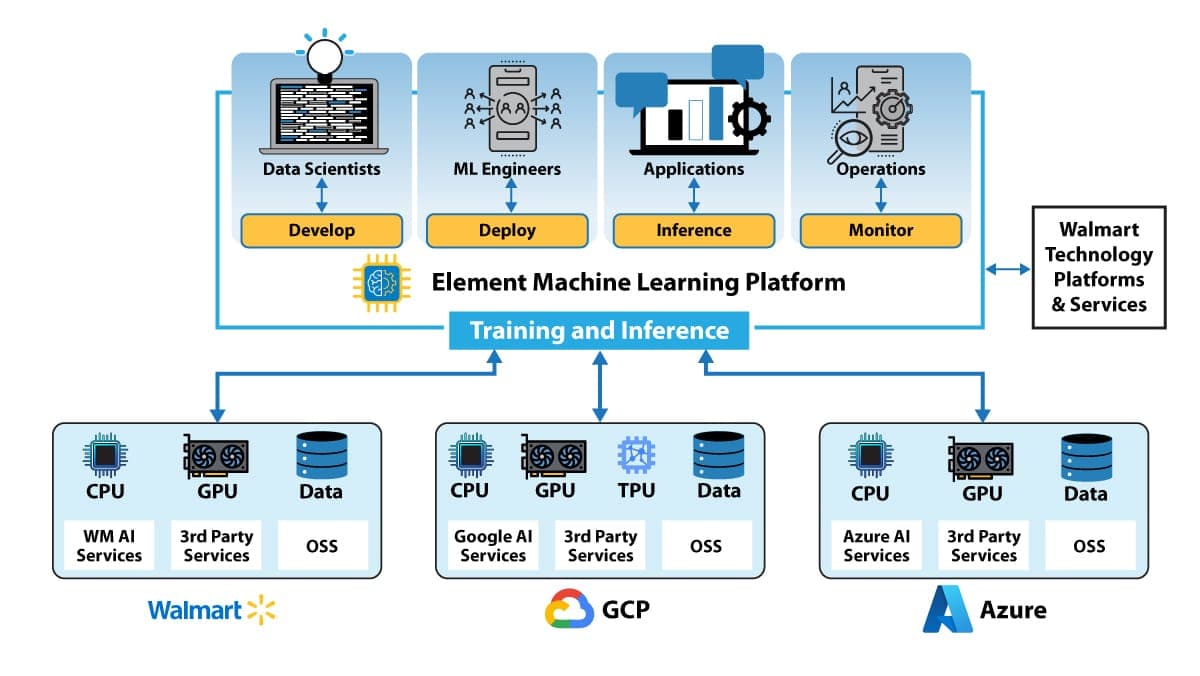
The world’s biggest retailer by revenue revealed new details about its cloud- and model-agnostic AI application development platform.

July 9, 20252 min read
Robotic Beehive For Healthier Bees: Beewise’s robotic beehive uses AI to save pollinators.
Computer Vision

Robotic Beehive For Healthier Bees: Beewise’s robotic beehive uses AI to save pollinators.

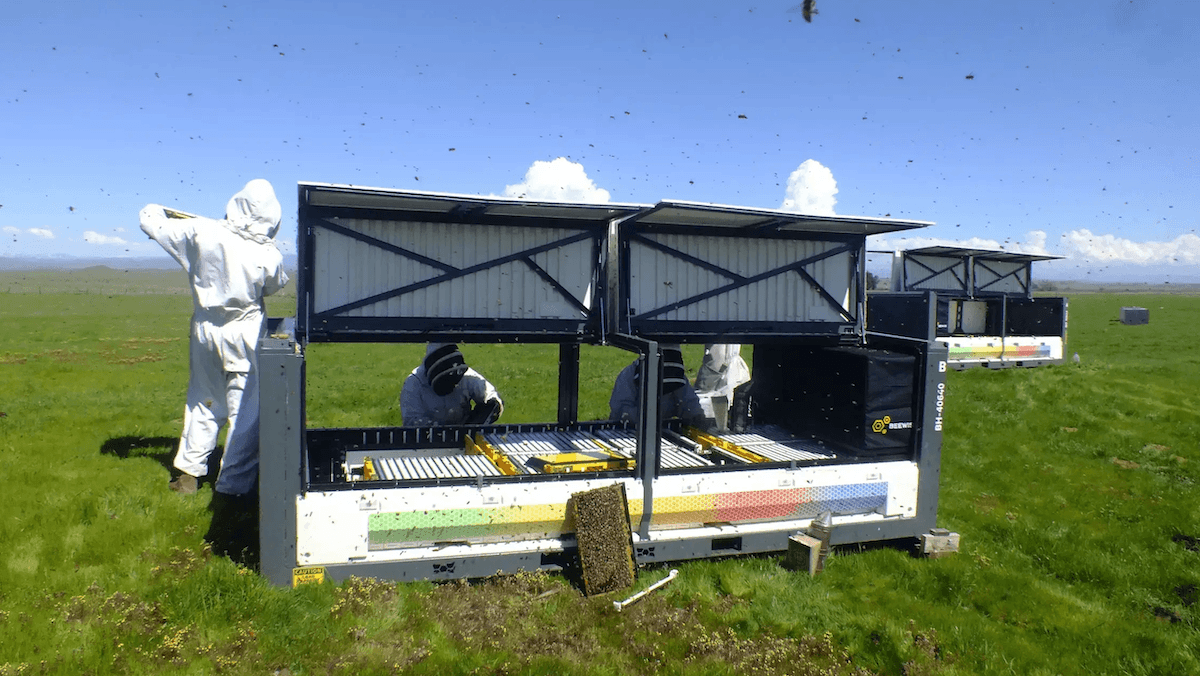
An automated beehive uses computer vision and robotics to help keep bees healthy and crops pollinated.

July 9, 20252 min read
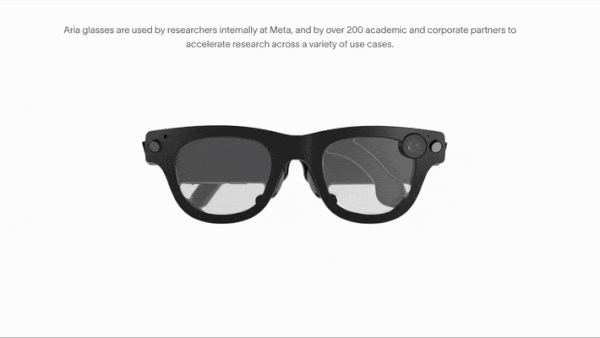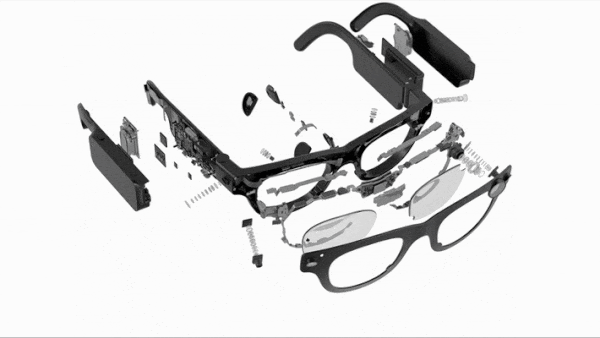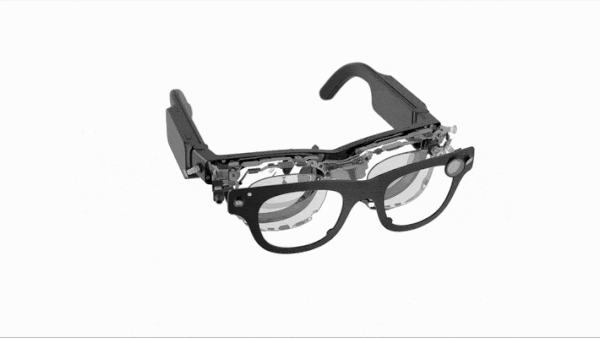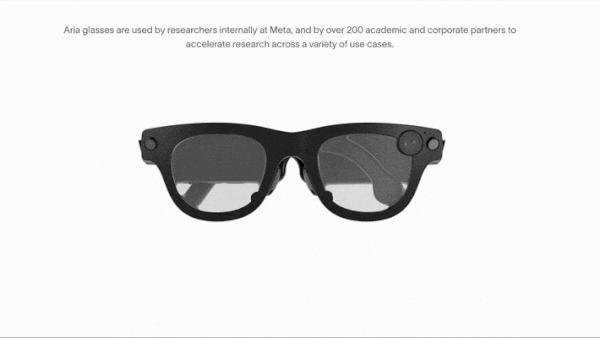
Meta’s Smart Glasses Come Into Focus: Meta reveals further details of Aria Gen 2 smart glasses for multisensory AI research
Computer Vision

Meta’s Smart Glasses Come Into Focus: Meta reveals further details of Aria Gen 2 smart glasses for multisensory AI research

Meta revealed new details about its latest Aria eyeglasses, which aim to give AI models a streaming, multisensory, human perspective.

July 2, 20253 min read
Human Action in 3D: Stanford researchers use generated video to animate 3D interactions without motion capture
Computer Vision

Human Action in 3D: Stanford researchers use generated video to animate 3D interactions without motion capture

AI systems designed to generate animated 3D scenes that include active human characters have been limited by a shortage of training data, such as matched 3D scenes and human motion-capture examples. Generated video clips can get the job done without motion capture.

April 2, 20253 min read
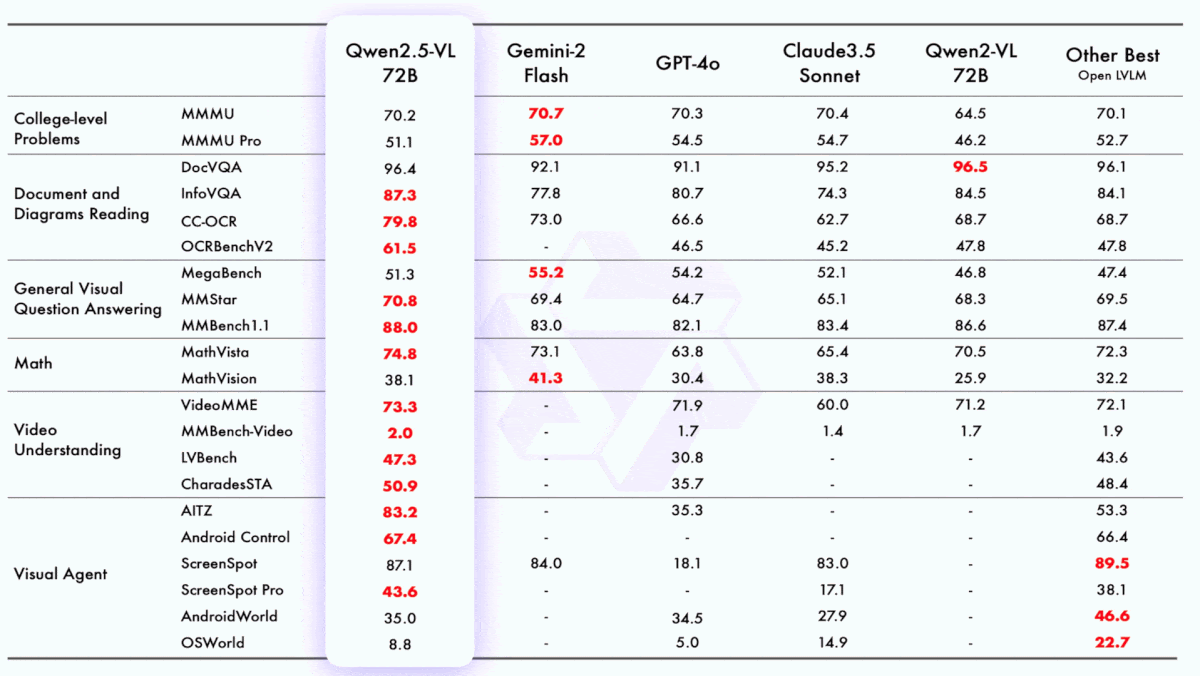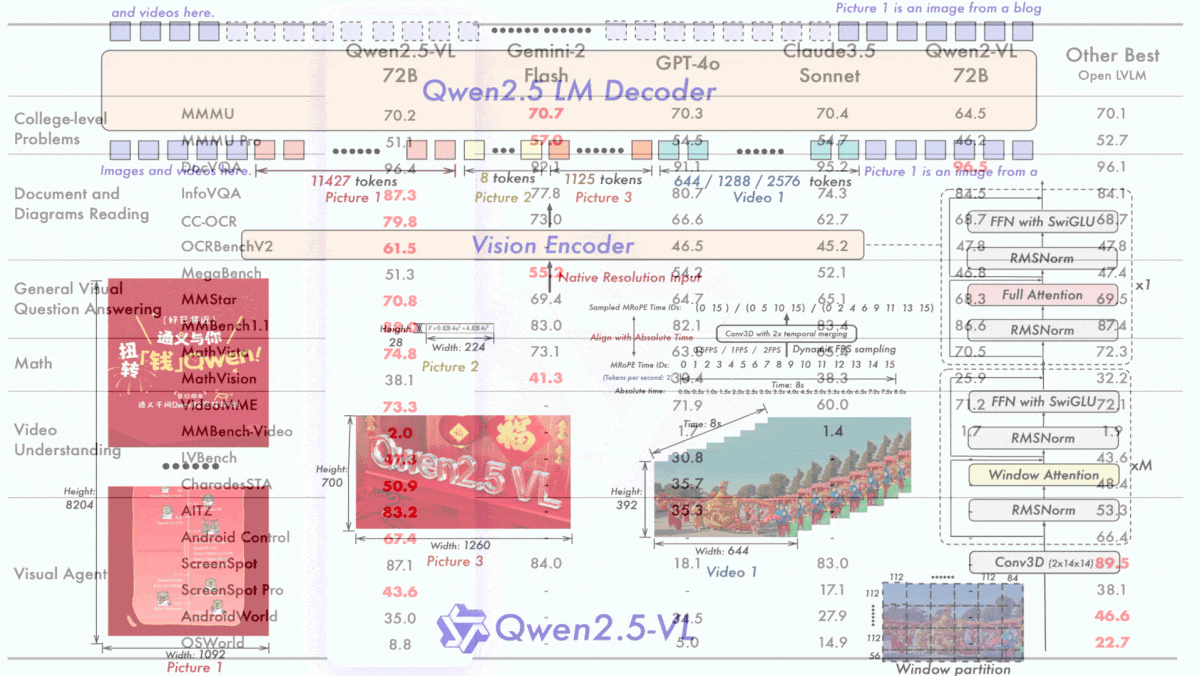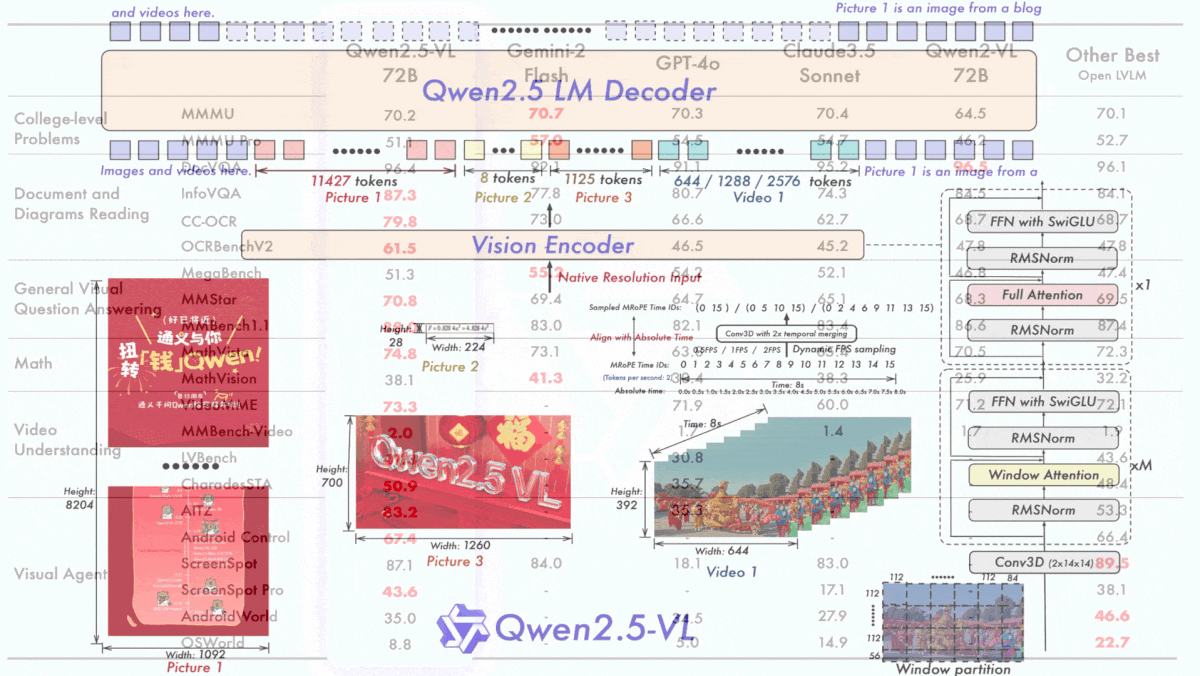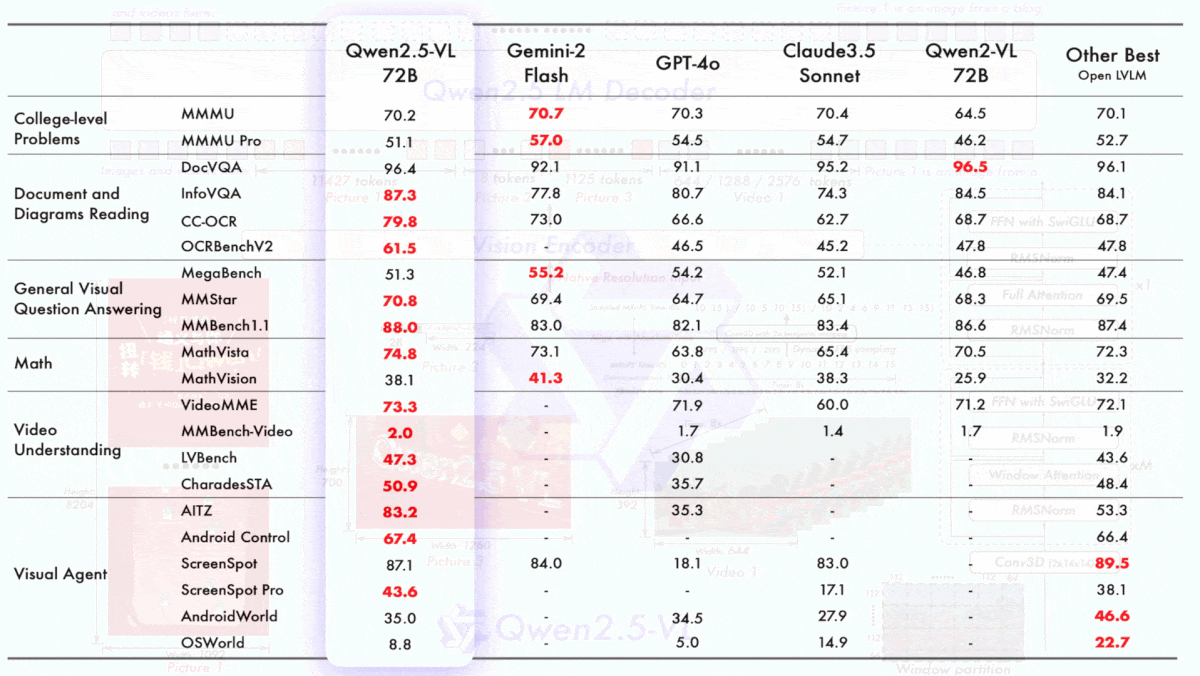
Alibaba’s Answer to DeepSeek: Alibaba debuts Qwen2.5-VL, a powerful family of open vision-language models
Computer Vision

Alibaba’s Answer to DeepSeek: Alibaba debuts Qwen2.5-VL, a powerful family of open vision-language models

While Hangzhou’s DeepSeek flexed its muscles, Chinese tech giant Alibaba vied for the spotlight with new open vision-language models.

February 12, 20253 min read
Alibaba’s Answer to DeepSeek: Alibaba debuts Qwen2.5-VL, a powerful family of open vision-language models
Computer Vision

Alibaba’s Answer to DeepSeek: Alibaba debuts Qwen2.5-VL, a powerful family of open vision-language models

While Hangzhou’s DeepSeek flexed its muscles, Chinese tech giant Alibaba vied for the spotlight with new open vision-language models.

February 12, 20253 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox