CLIP

26 Posts

Different Media, Similar Embeddings: ImageBind, the AI model that binds data from seven data types at once
CLIP

Different Media, Similar Embeddings: ImageBind, the AI model that binds data from seven data types at once

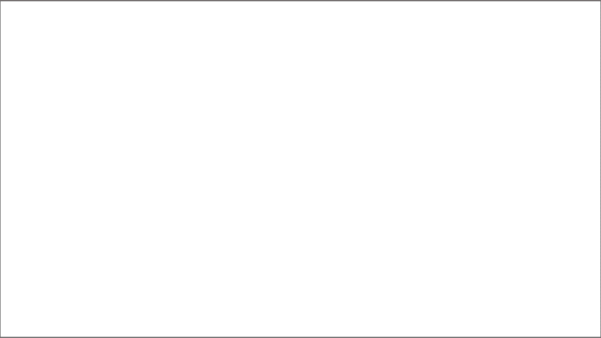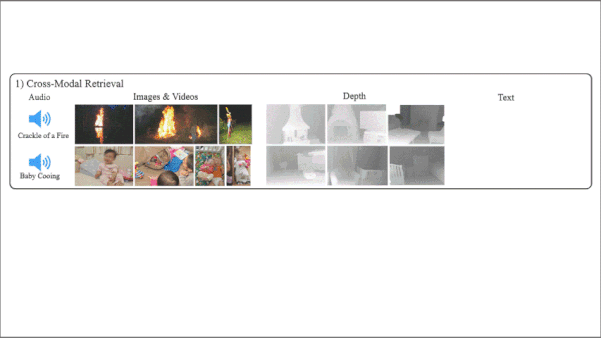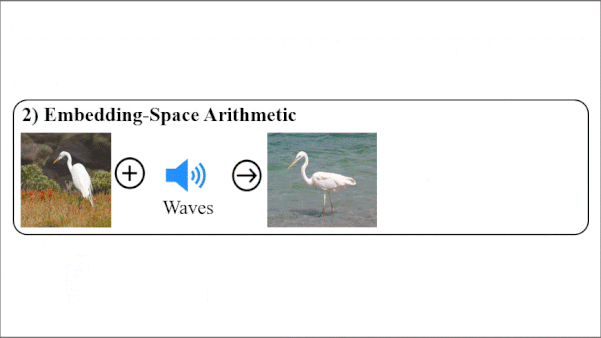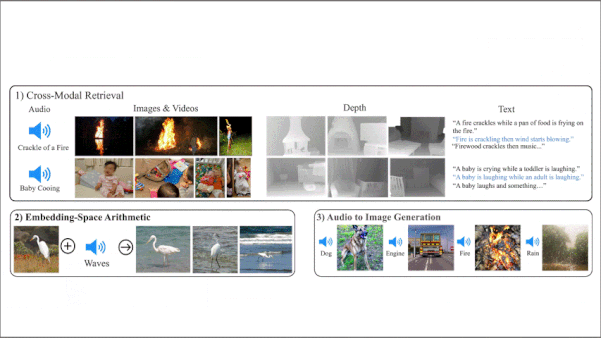
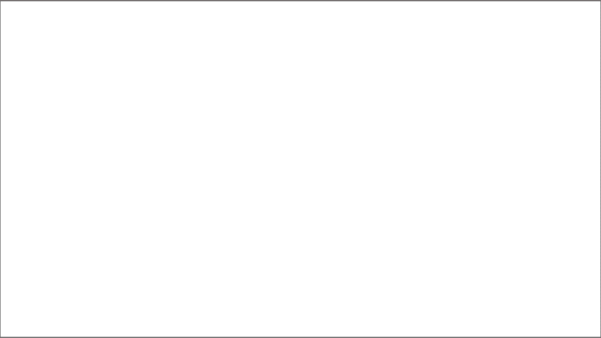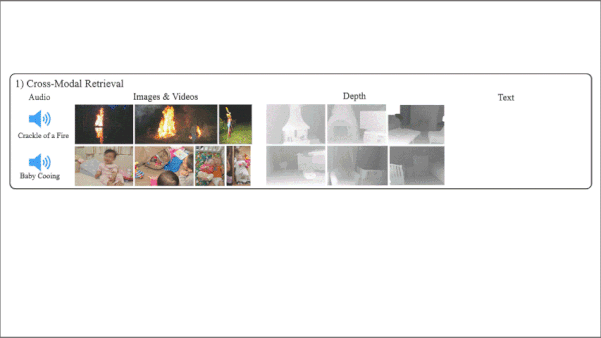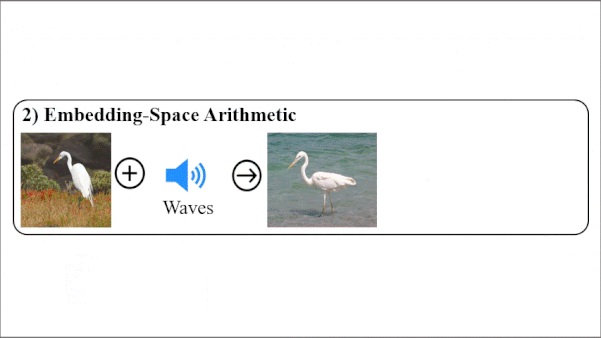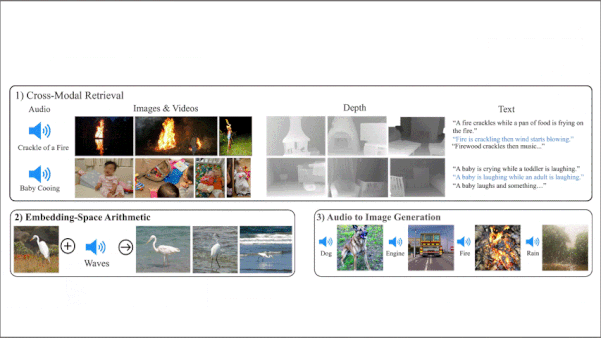
The ability of OpenAI’s CLIP to produce similar embeddings of a text phrase and a matching image opened up applications like classifying images according to labels that weren’t in the training set. A new model extends this capability to seven data types.
September 6, 20232 min read
Different Media, Similar Embeddings: ImageBind, the AI model that binds data from seven data types at once
CLIP

Different Media, Similar Embeddings: ImageBind, the AI model that binds data from seven data types at once

The ability of OpenAI’s CLIP to produce similar embeddings of a text phrase and a matching image opened up applications like classifying images according to labels that weren’t in the training set. A new model extends this capability to seven data types.
September 6, 20232 min read
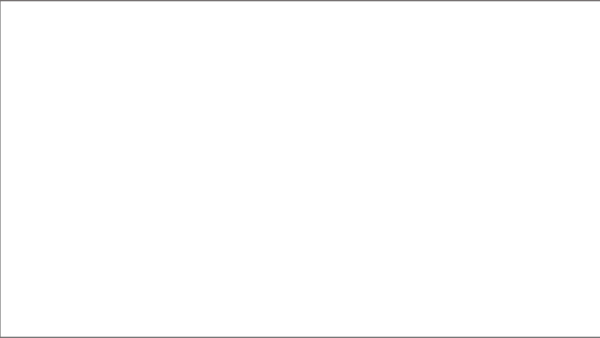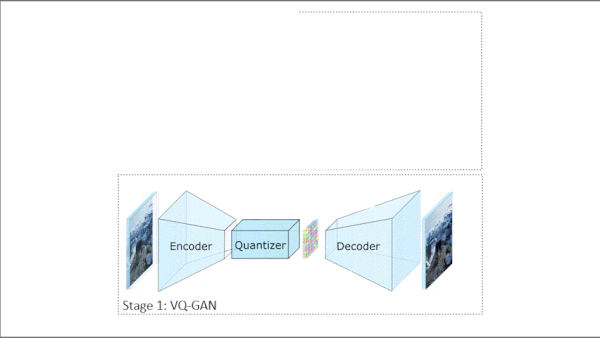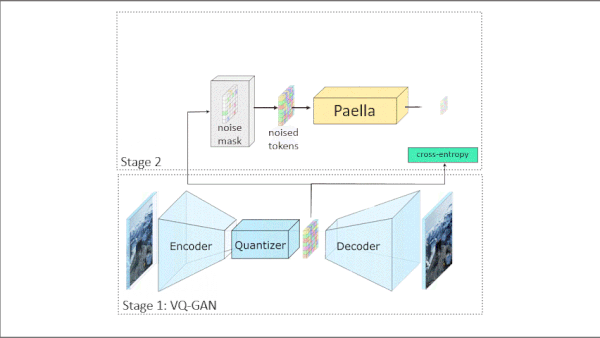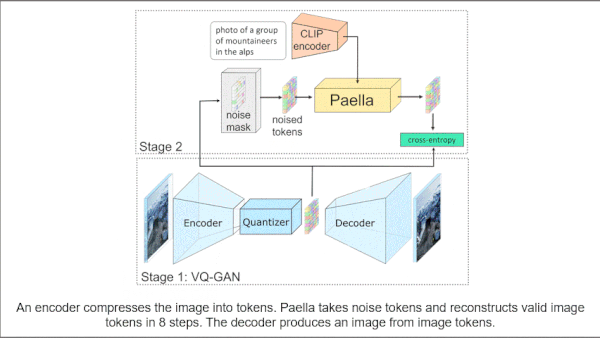
Like Diffusion but Faster: The Paella model for fast image generation, explained
CLIP

Like Diffusion but Faster: The Paella model for fast image generation, explained

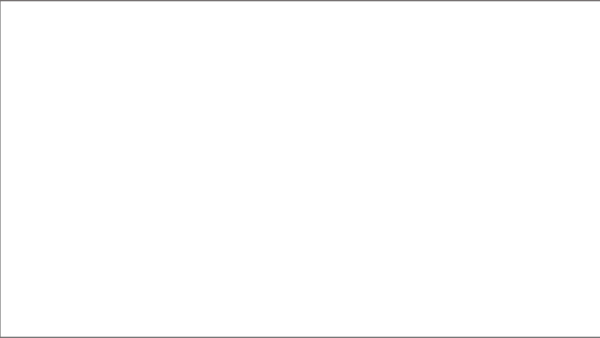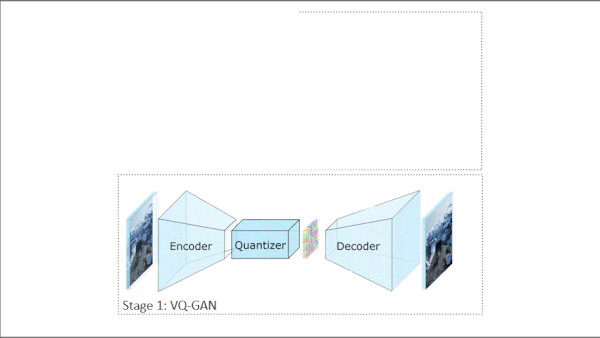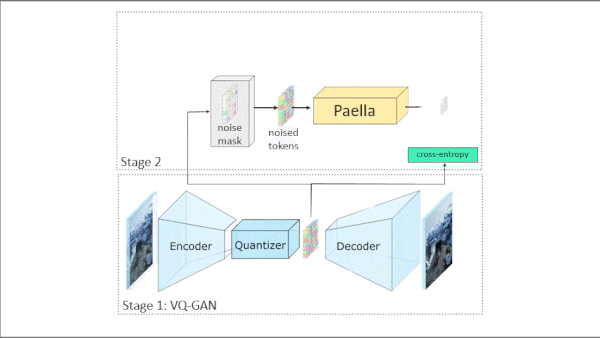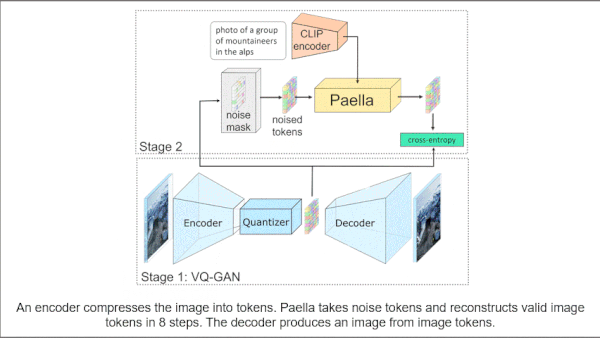
The ability to generate realistic images without waiting would unlock applications from engineering to entertainment and beyond. New work takes a step in that direction.

June 14, 20232 min read
Like Diffusion but Faster: The Paella model for fast image generation, explained
CLIP

Like Diffusion but Faster: The Paella model for fast image generation, explained

The ability to generate realistic images without waiting would unlock applications from engineering to entertainment and beyond. New work takes a step in that direction.

June 14, 20232 min read
Text-Driven Video Alteration: Gen-1 uses text prompts to modify videos.
CLIP

Text-Driven Video Alteration: Gen-1 uses text prompts to modify videos.

On the heels of systems that generate video directly from text, new work uses text to adjust the imagery in existing videos. Researchers unveiled Gen-1...

March 8, 20233 min read
Text-Driven Video Alteration: Gen-1 uses text prompts to modify videos.
CLIP

Text-Driven Video Alteration: Gen-1 uses text prompts to modify videos.

On the heels of systems that generate video directly from text, new work uses text to adjust the imagery in existing videos. Researchers unveiled Gen-1...

March 8, 20233 min read
Ensemble Models Simplified: New Machine Learning Research Simplifies Ensembles
CLIP

Ensemble Models Simplified: New Machine Learning Research Simplifies Ensembles

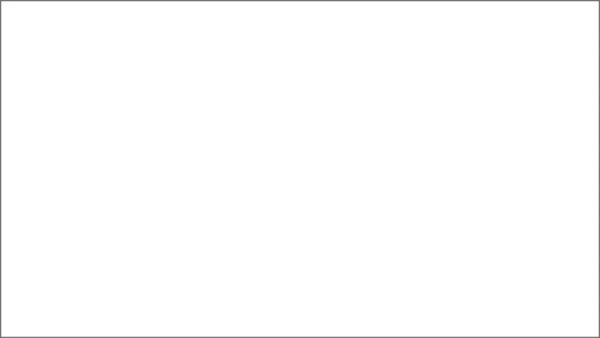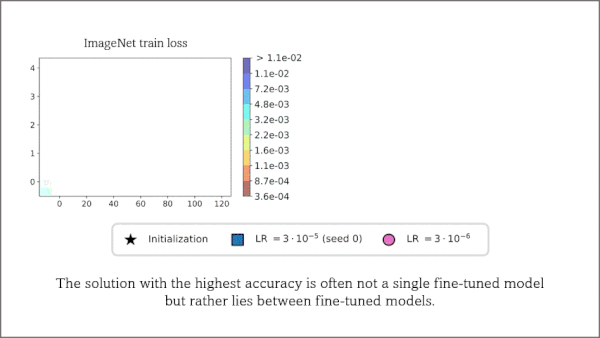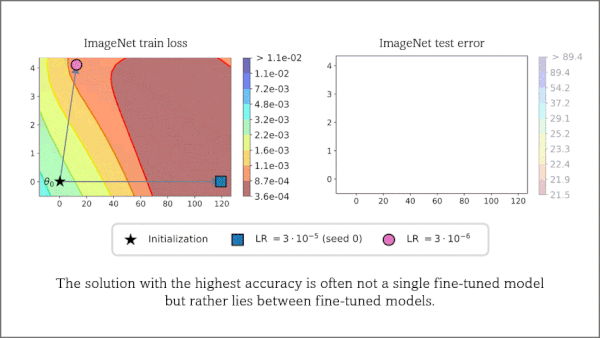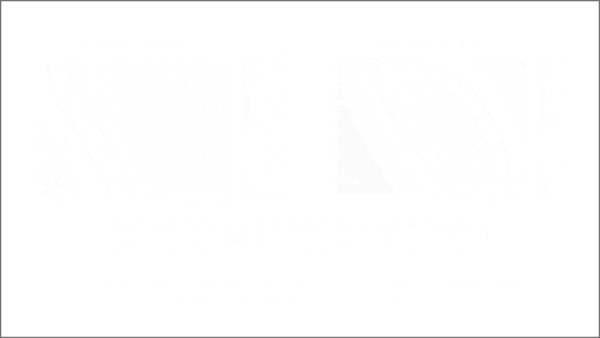
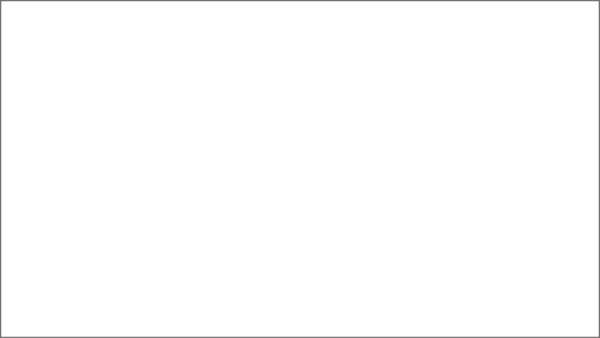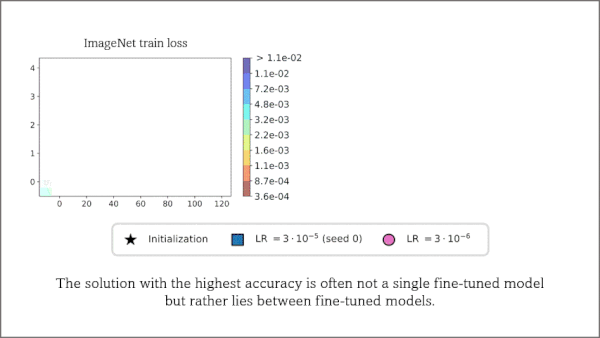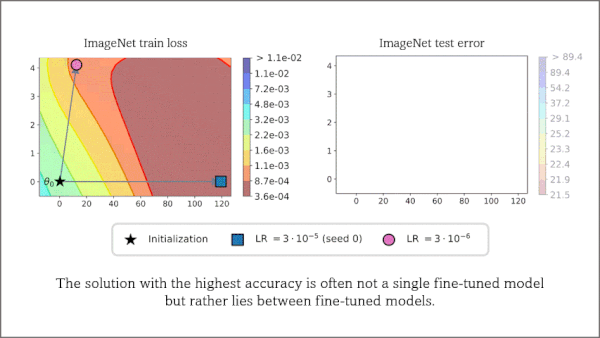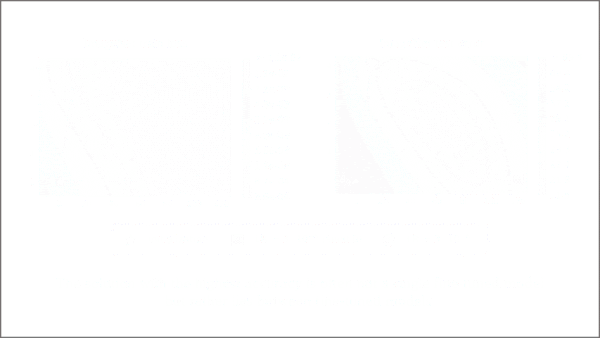
A CLIP model whose weights were the mean of an ensemble of fine-tuned models performed as well as the ensemble and better than its best-performing constituent.

August 17, 20222 min read
Ensemble Models Simplified: New Machine Learning Research Simplifies Ensembles
CLIP

Ensemble Models Simplified: New Machine Learning Research Simplifies Ensembles

A CLIP model whose weights were the mean of an ensemble of fine-tuned models performed as well as the ensemble and better than its best-performing constituent.

August 17, 20222 min read
Text-to-Image Goes Viral: Inside Craiyon, Formerly Known as DALL·E Mini
CLIP

Text-to-Image Goes Viral: Inside Craiyon, Formerly Known as DALL·E Mini

A homebrew re-creation of OpenAI’s DALL·E model is the latest internet sensation. Craiyon has been generating around 50,000 user-prompted images daily, thanks to its ability to produce visual mashups like Darth Vader ice fishing and photorealistic Pokemon characters.

July 13, 20221 min read
Text-to-Image Goes Viral: Inside Craiyon, Formerly Known as DALL·E Mini
CLIP

Text-to-Image Goes Viral: Inside Craiyon, Formerly Known as DALL·E Mini

A homebrew re-creation of OpenAI’s DALL·E model is the latest internet sensation. Craiyon has been generating around 50,000 user-prompted images daily, thanks to its ability to produce visual mashups like Darth Vader ice fishing and photorealistic Pokemon characters.

July 13, 20221 min read
Yale Song: Foundation models for vision
CLIP

Yale Song: Foundation models for vision

Large models pretrained on immense quantities of text have been proven to provide strong foundations for solving specialized language tasks. My biggest hope for AI in 2022 is...

December 29, 20212 min read
Yale Song: Foundation models for vision
CLIP

Yale Song: Foundation models for vision

Large models pretrained on immense quantities of text have been proven to provide strong foundations for solving specialized language tasks. My biggest hope for AI in 2022 is...

December 29, 20212 min read
Multimodal AI Takes Off: Multimodal Models, such as CLIP and DALL·E, are taking over AI.
CLIP

Multimodal AI Takes Off: Multimodal Models, such as CLIP and DALL·E, are taking over AI.

While models like GPT-3 and EfficientNet, which work on text and images respectively, are responsible for some of deep learning’s highest-profile successes, approaches that find relationships between text and images made impressive

December 22, 20211 min read
Multimodal AI Takes Off: Multimodal Models, such as CLIP and DALL·E, are taking over AI.
CLIP

Multimodal AI Takes Off: Multimodal Models, such as CLIP and DALL·E, are taking over AI.

While models like GPT-3 and EfficientNet, which work on text and images respectively, are responsible for some of deep learning’s highest-profile successes, approaches that find relationships between text and images made impressive

December 22, 20211 min read
Artistry Is Obsolete: Is AI Making Human Artists Obsolete?
CLIP

Artistry Is Obsolete: Is AI Making Human Artists Obsolete?

Is human creativity being replaced by the synthetic equivalent? The fear: AI is cranking out increasingly sophisticated visual, musical, and literary works. AI-generated media will flood the market, squeezing out human artists and depriving the world of their creativity.

October 27, 20212 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox