Adversarial Attacks

26 Posts

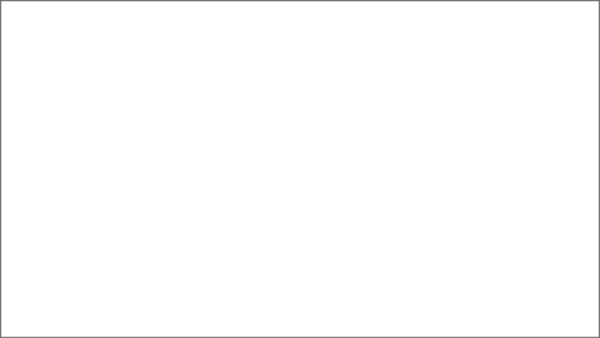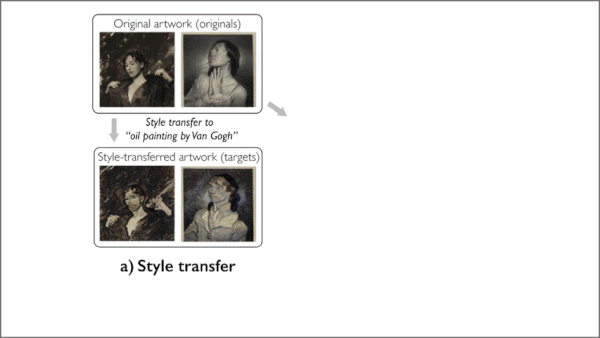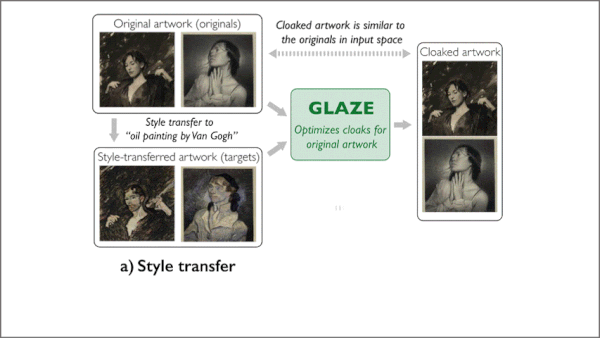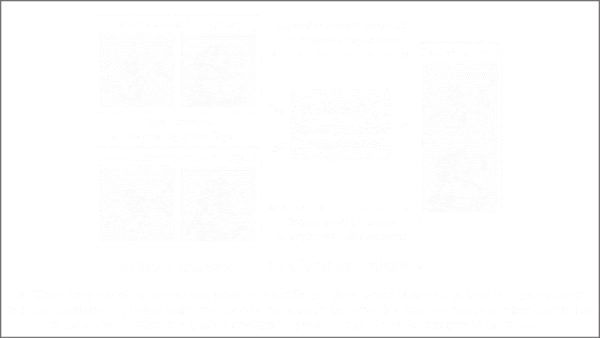
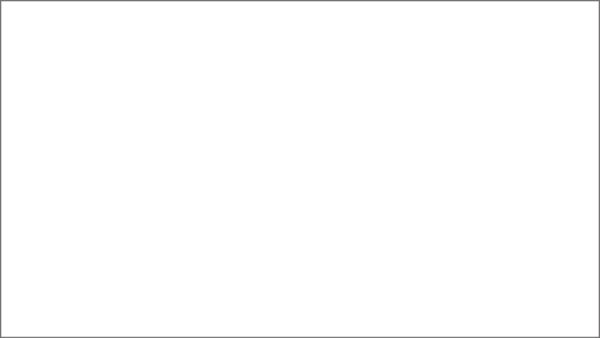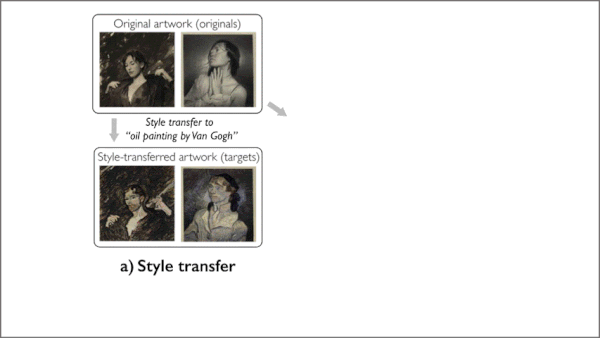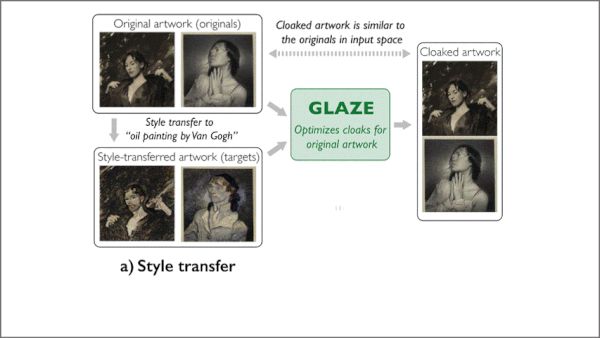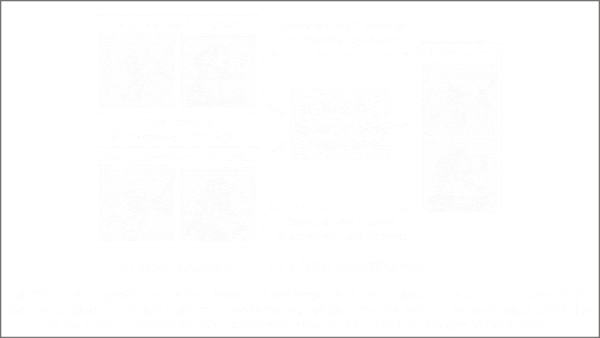
Don’t Steal My Style: Glaze tool prevents AI from learning an artist's style.
Adversarial Attacks

Don’t Steal My Style: Glaze tool prevents AI from learning an artist's style.

Asked to produce “a landscape by Thomas Kinkade,” a text-to-image generator fine-tuned on the pastoral painter’s work can mimic his style in seconds, often for pennies. A new technique aims to make it harder for algorithms to mimic an artist’s style.
May 10, 20233 min read
Don’t Steal My Style: Glaze tool prevents AI from learning an artist's style.
Adversarial Attacks

Don’t Steal My Style: Glaze tool prevents AI from learning an artist's style.

Asked to produce “a landscape by Thomas Kinkade,” a text-to-image generator fine-tuned on the pastoral painter’s work can mimic his style in seconds, often for pennies. A new technique aims to make it harder for algorithms to mimic an artist’s style.

May 10, 20233 min read
Champion Model Is No Go: Adversarial AI Beats Master KataGo Algorithm
Adversarial Attacks

Champion Model Is No Go: Adversarial AI Beats Master KataGo Algorithm

A new algorithm defeated a championship-winning Go model using moves that even a middling human player could counter. Researchers trained a model to defeat KataGo, an open source Go-playing system that has beaten top human players.

November 23, 20222 min read
Champion Model Is No Go: Adversarial AI Beats Master KataGo Algorithm
Adversarial Attacks

Champion Model Is No Go: Adversarial AI Beats Master KataGo Algorithm

A new algorithm defeated a championship-winning Go model using moves that even a middling human player could counter. Researchers trained a model to defeat KataGo, an open source Go-playing system that has beaten top human players.

November 23, 20222 min read
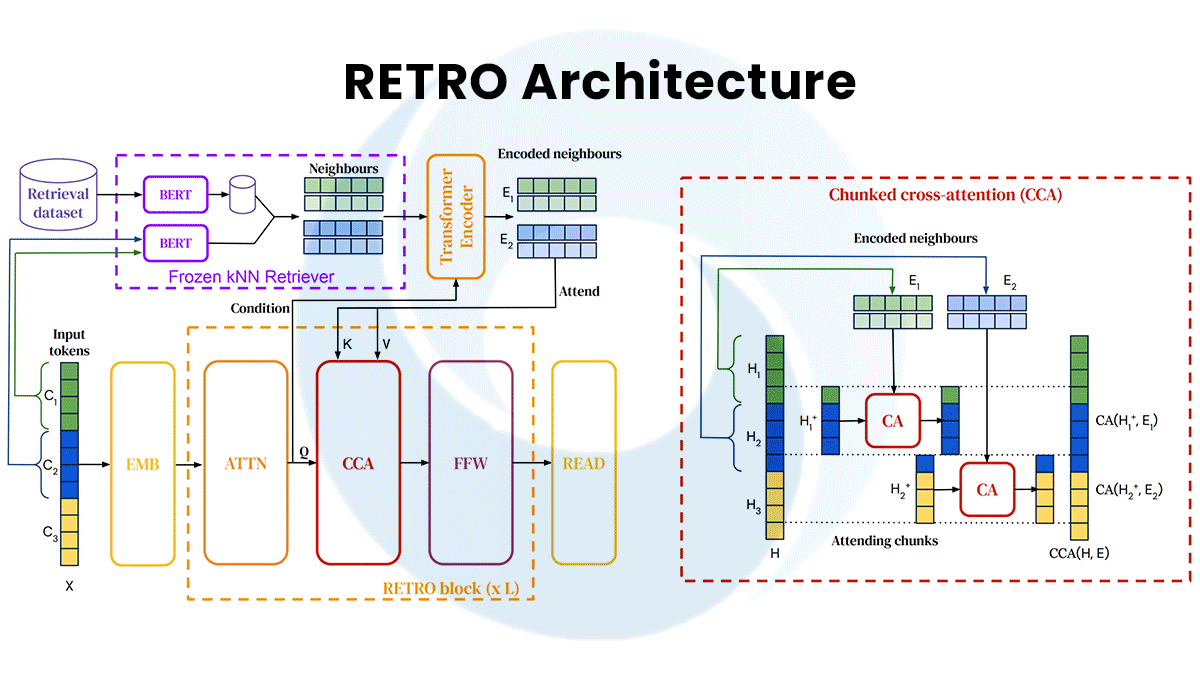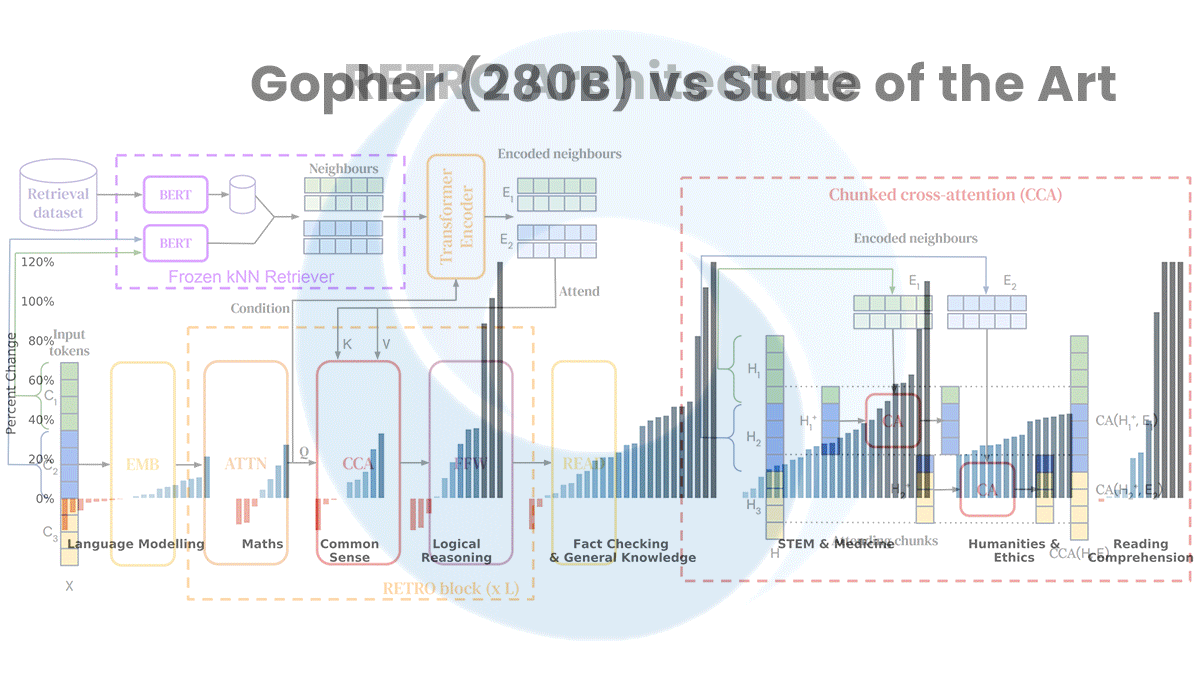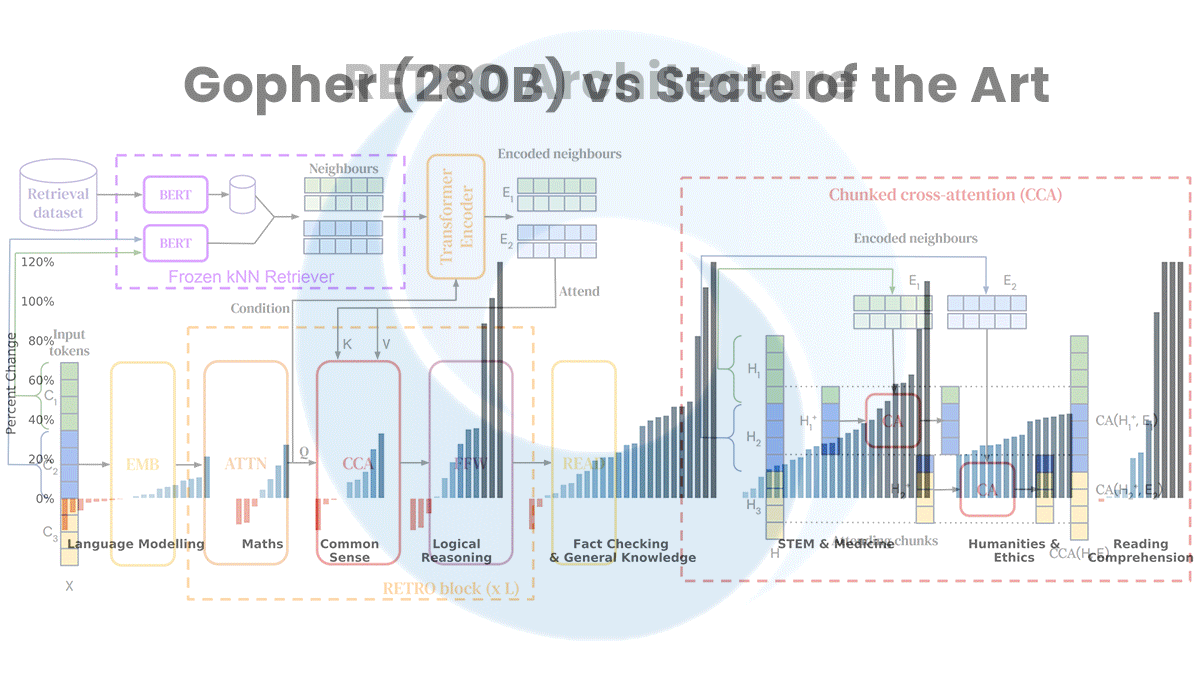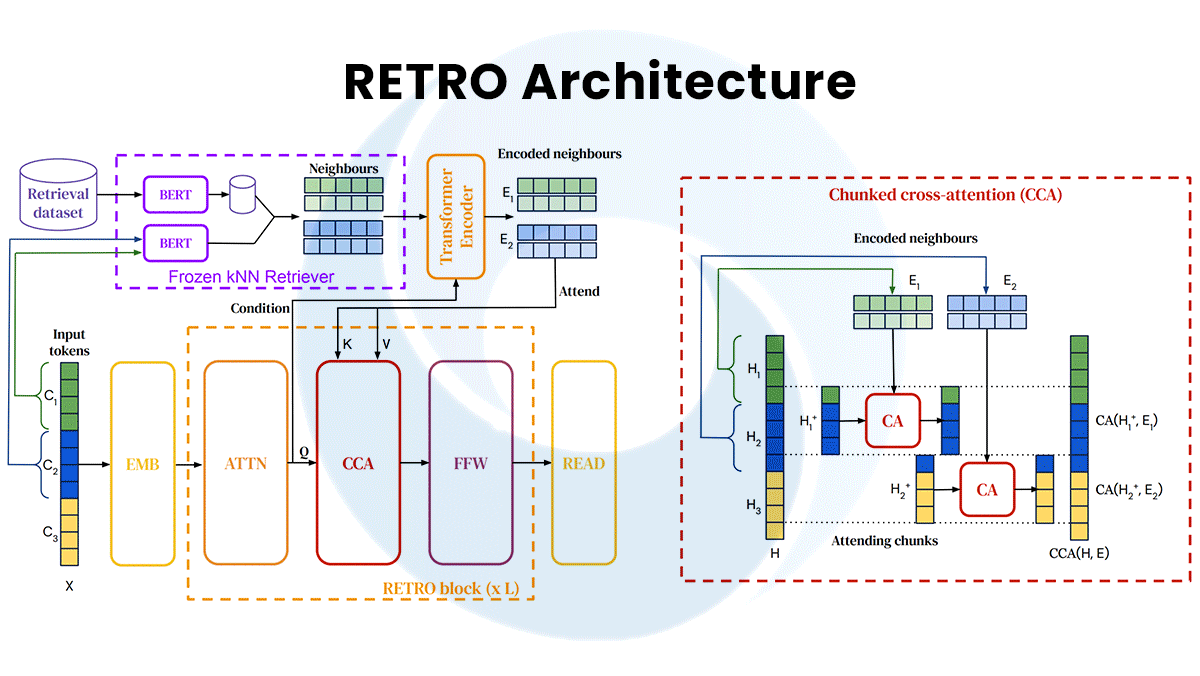
Large Language Models Shrink: Gopher and RETRO prove lean language models can push boundaries.
Adversarial Attacks

Large Language Models Shrink: Gopher and RETRO prove lean language models can push boundaries.

DeepMind released three papers that push the boundaries — and examine the issues — of large language models.

December 15, 20212 min read
Large Language Models Shrink: Gopher and RETRO prove lean language models can push boundaries.
Adversarial Attacks

Large Language Models Shrink: Gopher and RETRO prove lean language models can push boundaries.

DeepMind released three papers that push the boundaries — and examine the issues — of large language models.

December 15, 20212 min read
A Privacy Threat Revealed: How researchers cracked InstaHide for computer vision.
Adversarial Attacks

A Privacy Threat Revealed: How researchers cracked InstaHide for computer vision.

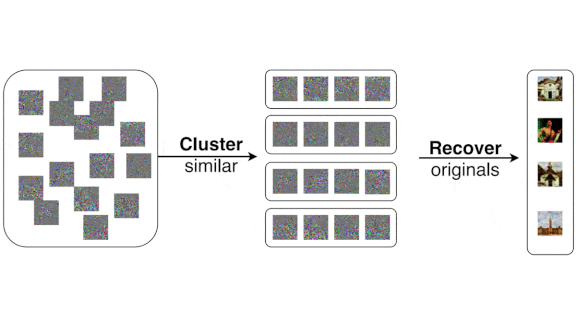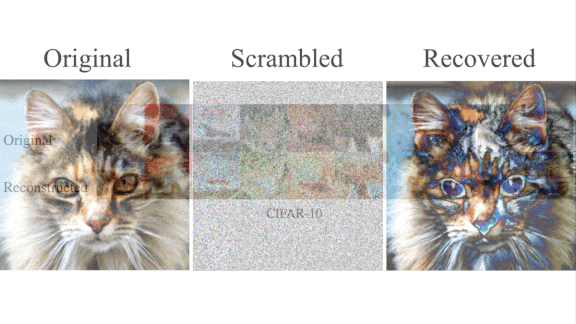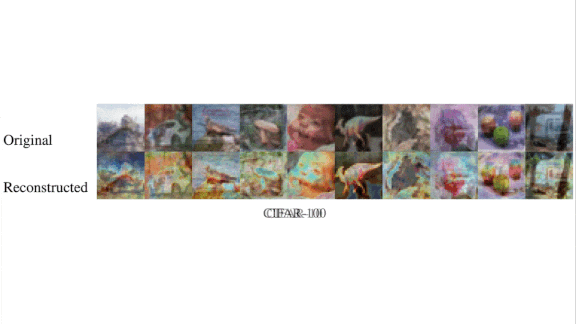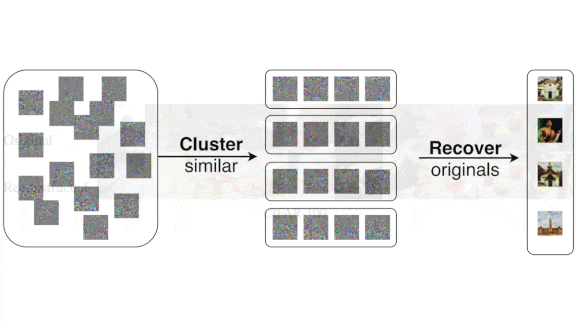
With access to a trained model, an attacker can use a reconstruction attack to approximate its training data. A method called InstaHide recently won acclaim for promising to make such examples unrecognizable to human eyes while retaining their utility for training.

February 3, 20212 min read
A Privacy Threat Revealed: How researchers cracked InstaHide for computer vision.
Adversarial Attacks

A Privacy Threat Revealed: How researchers cracked InstaHide for computer vision.

With access to a trained model, an attacker can use a reconstruction attack to approximate its training data. A method called InstaHide recently won acclaim for promising to make such examples unrecognizable to human eyes while retaining their utility for training.

February 3, 20212 min read
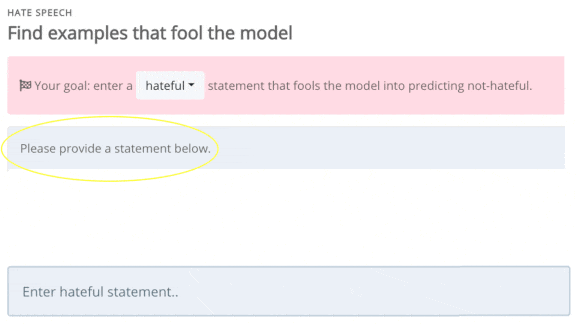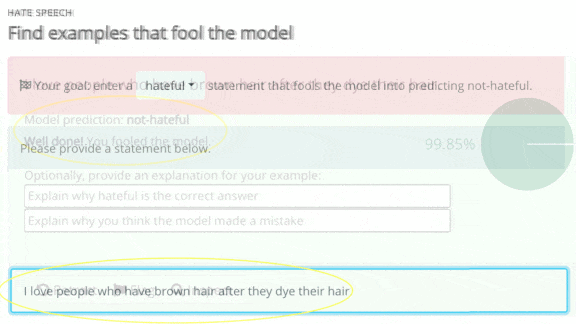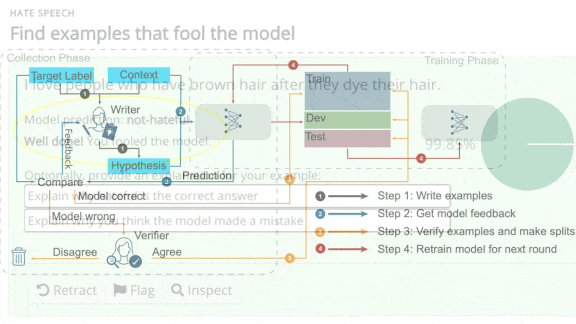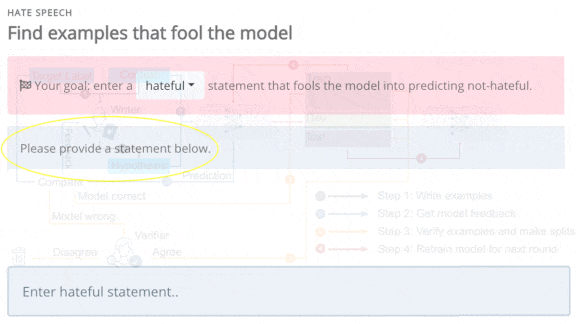
Dynamic Benchmarks: A platform for fooling language models
Adversarial Attacks

Dynamic Benchmarks: A platform for fooling language models

Benchmarks provide a scientific basis for evaluating model performance, but they don’t necessarily map well to human cognitive abilities. Facebook aims to close the gap through a dynamic benchmarking method that keeps humans in the loop.

October 14, 20202 min read
Dynamic Benchmarks: A platform for fooling language models
Adversarial Attacks

Dynamic Benchmarks: A platform for fooling language models

Benchmarks provide a scientific basis for evaluating model performance, but they don’t necessarily map well to human cognitive abilities. Facebook aims to close the gap through a dynamic benchmarking method that keeps humans in the loop.

October 14, 20202 min read
The Telltale Artifact: A technique for detecting GAN-generated deepfakes
Adversarial Attacks

The Telltale Artifact: A technique for detecting GAN-generated deepfakes

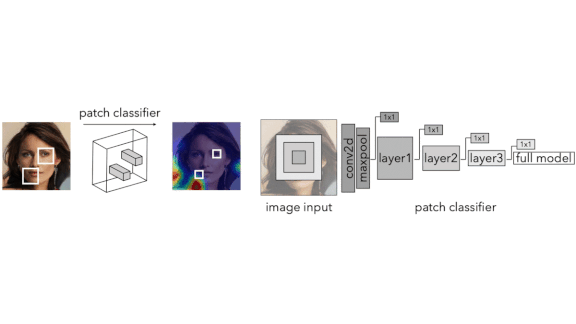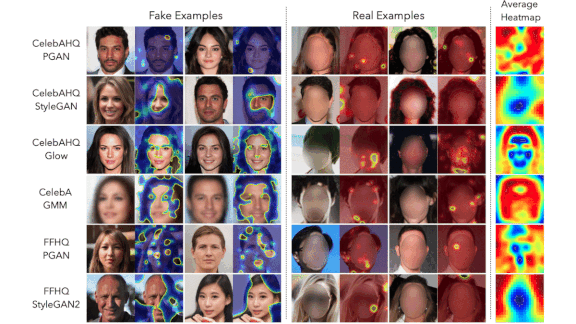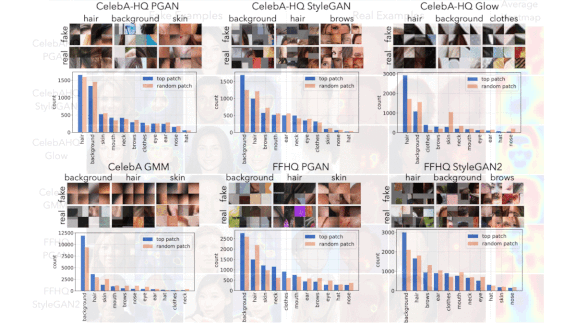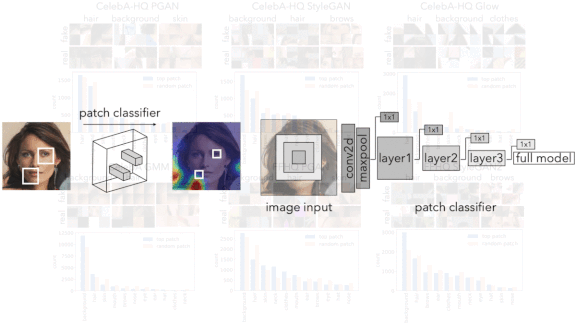
Deepfakes have gone mainstream, allowing celebrities to star in commercials without setting foot in a film studio. A new method helps determine whether such endorsements — and other images produced by generative adversarial networks — are authentic.

September 30, 20202 min read
The Telltale Artifact: A technique for detecting GAN-generated deepfakes
Adversarial Attacks

The Telltale Artifact: A technique for detecting GAN-generated deepfakes

Deepfakes have gone mainstream, allowing celebrities to star in commercials without setting foot in a film studio. A new method helps determine whether such endorsements — and other images produced by generative adversarial networks — are authentic.

September 30, 20202 min read
Hidden in Plain Sight: Researchers make clothes that fool face recognition.
Adversarial Attacks

Hidden in Plain Sight: Researchers make clothes that fool face recognition.

With the rise of AI-driven surveillance, anonymity is in fashion. Researchers are working on clothing that evades face recognition systems and designed a t-shirt that tricks a variety of object detection models into failing to spot people.

August 12, 20202 min read
Hidden in Plain Sight: Researchers make clothes that fool face recognition.
Adversarial Attacks

Hidden in Plain Sight: Researchers make clothes that fool face recognition.

With the rise of AI-driven surveillance, anonymity is in fashion. Researchers are working on clothing that evades face recognition systems and designed a t-shirt that tricks a variety of object detection models into failing to spot people.

August 12, 20202 min read
When Models Take Shortcuts: The causes of shortcut learning in neural networks
Adversarial Attacks

When Models Take Shortcuts: The causes of shortcut learning in neural networks

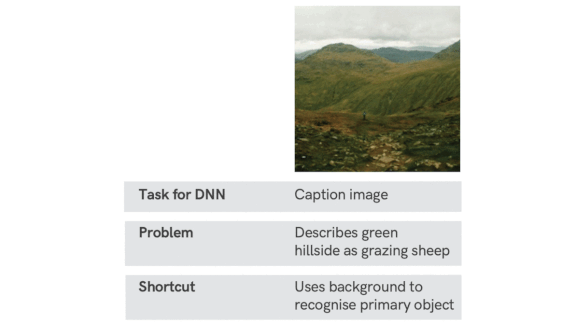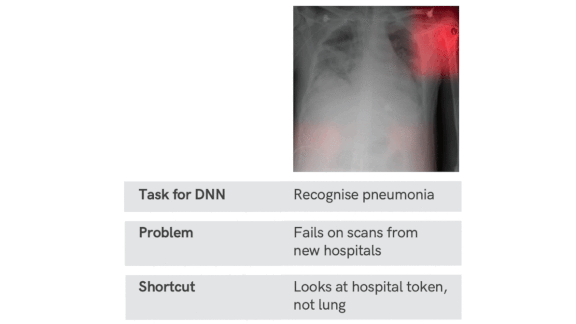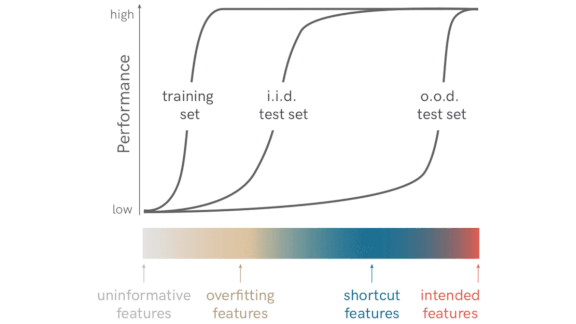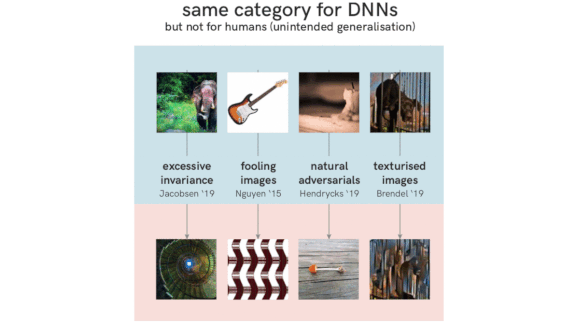
Neuroscientists once thought they could train rats to navigate mazes by color. Rats don’t perceive colors at all. Instead, they rely on the distinct odors of different colors of paint. New work finds that neural networks are prone to this sort of misalignment between training goals and learning.

June 3, 20202 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox