Abeba Birhane: Clean up web datasets
Vision

Abeba Birhane: Clean up web datasets

From language to vision models, deep neural networks are marked by improved performance, higher efficiency, and better generalizations. Yet, these systems are also marked by perpetuation of bias and injustice.

December 29, 20213 min read
Abeba Birhane: Clean up web datasets
Vision

Abeba Birhane: Clean up web datasets

From language to vision models, deep neural networks are marked by improved performance, higher efficiency, and better generalizations. Yet, these systems are also marked by perpetuation of bias and injustice.

December 29, 20213 min read
Voices for the Voiceless: Generative AI models are creating voices for Hollywood and video games.
Vision

Voices for the Voiceless: Generative AI models are creating voices for Hollywood and video games.

Musicians and filmmakers adopted AI as a standard part of the audio-production toolbox. What happened: Professional media makers embraced neural networks that generate new sounds and modify old ones. Voice actors bristled.

December 22, 20212 min read
Voices for the Voiceless: Generative AI models are creating voices for Hollywood and video games.
Vision

Voices for the Voiceless: Generative AI models are creating voices for Hollywood and video games.

Musicians and filmmakers adopted AI as a standard part of the audio-production toolbox. What happened: Professional media makers embraced neural networks that generate new sounds and modify old ones. Voice actors bristled.

December 22, 20212 min read
Transformers Take Over: Transformers Applied to Vision, Language, Video, and More
Vision

Transformers Take Over: Transformers Applied to Vision, Language, Video, and More

In 2021, transformers were harnessed to discover drugs, recognize speech, and paint pictures — and much more.

December 22, 20212 min read
Transformers Take Over: Transformers Applied to Vision, Language, Video, and More
Vision

Transformers Take Over: Transformers Applied to Vision, Language, Video, and More

In 2021, transformers were harnessed to discover drugs, recognize speech, and paint pictures — and much more.

December 22, 20212 min read
Multimodal AI Takes Off: Multimodal Models, such as CLIP and DALL·E, are taking over AI.
Vision

Multimodal AI Takes Off: Multimodal Models, such as CLIP and DALL·E, are taking over AI.

While models like GPT-3 and EfficientNet, which work on text and images respectively, are responsible for some of deep learning’s highest-profile successes, approaches that find relationships between text and images made impressive

December 22, 20211 min read
Multimodal AI Takes Off: Multimodal Models, such as CLIP and DALL·E, are taking over AI.
Vision

Multimodal AI Takes Off: Multimodal Models, such as CLIP and DALL·E, are taking over AI.

While models like GPT-3 and EfficientNet, which work on text and images respectively, are responsible for some of deep learning’s highest-profile successes, approaches that find relationships between text and images made impressive

December 22, 20211 min read
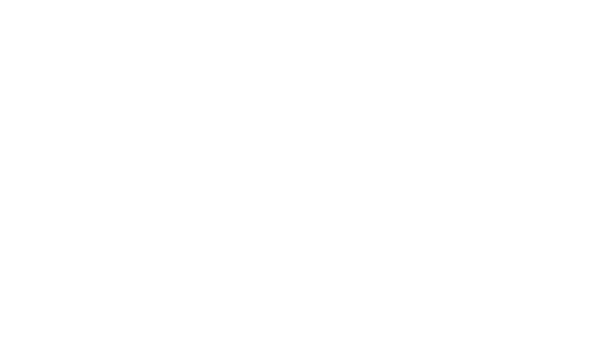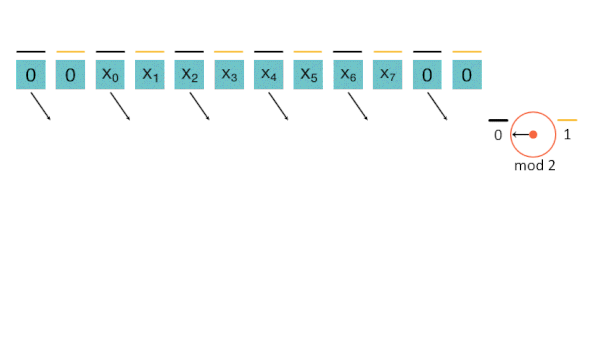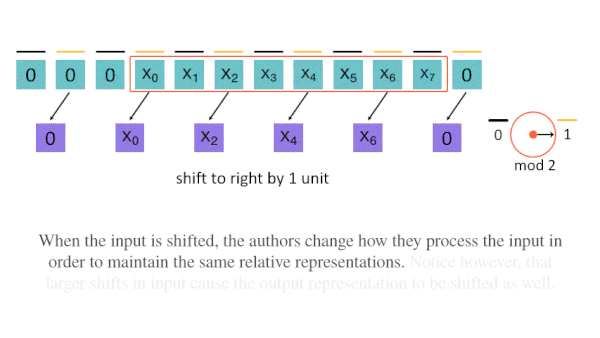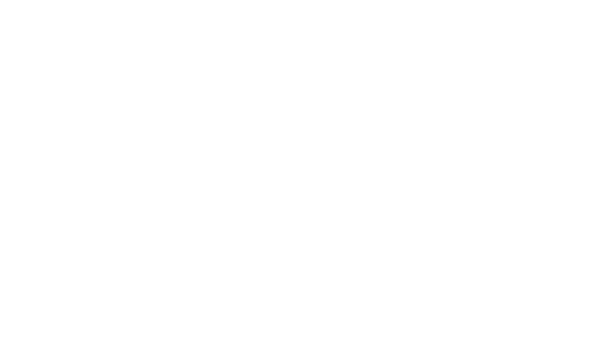
Image Transformations Unmasked: CNNs for vision that aren't fooled by changing backgrounds.
Vision

Image Transformations Unmasked: CNNs for vision that aren't fooled by changing backgrounds.

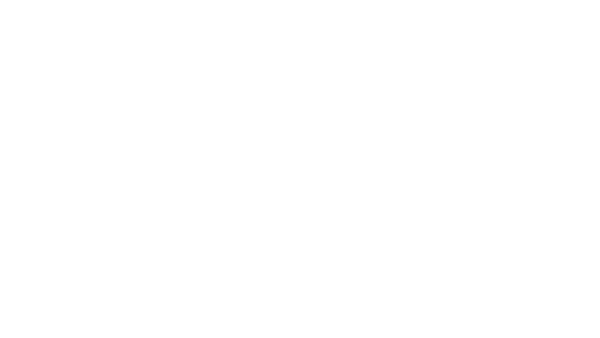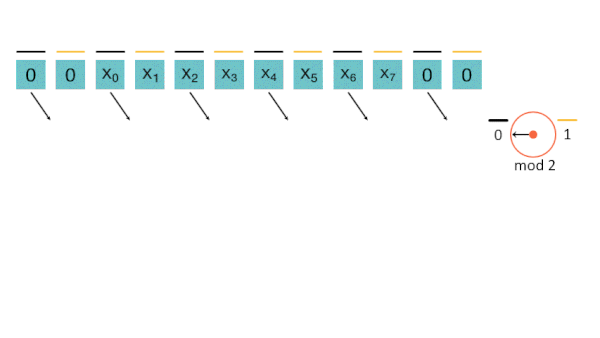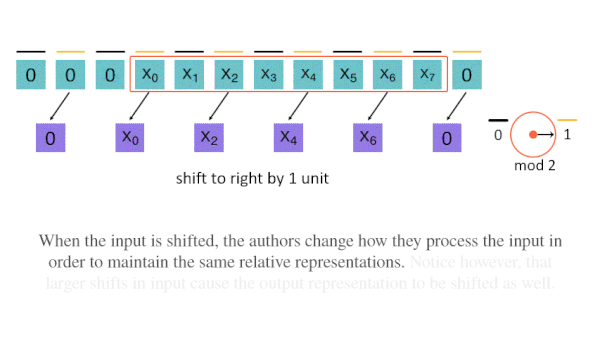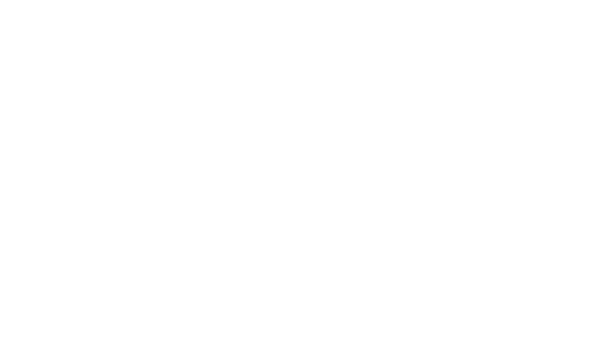
If you change an image by moving its subject within the frame, a well trained convolutional neural network may not recognize the fundamental similarity between the two versions. New research aims to make CNN wise to such alterations.

December 15, 20212 min read
Image Transformations Unmasked: CNNs for vision that aren't fooled by changing backgrounds.
Vision

Image Transformations Unmasked: CNNs for vision that aren't fooled by changing backgrounds.

If you change an image by moving its subject within the frame, a well trained convolutional neural network may not recognize the fundamental similarity between the two versions. New research aims to make CNN wise to such alterations.

December 15, 20212 min read
AI Goes Underground: Computer Vision From SewerAI Classifies Defective Pipes
Vision

AI Goes Underground: Computer Vision From SewerAI Classifies Defective Pipes

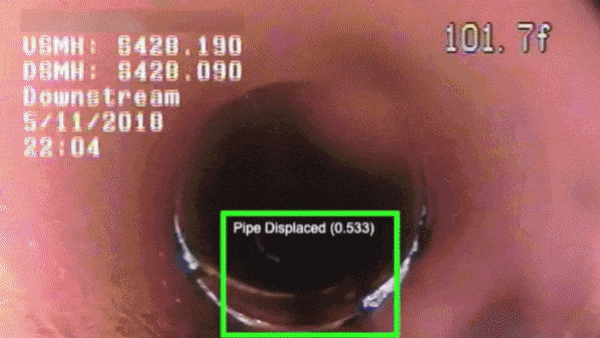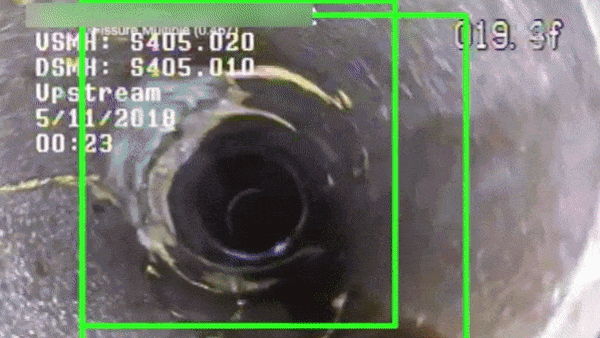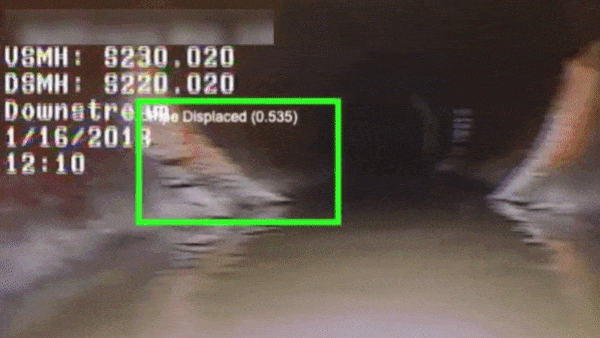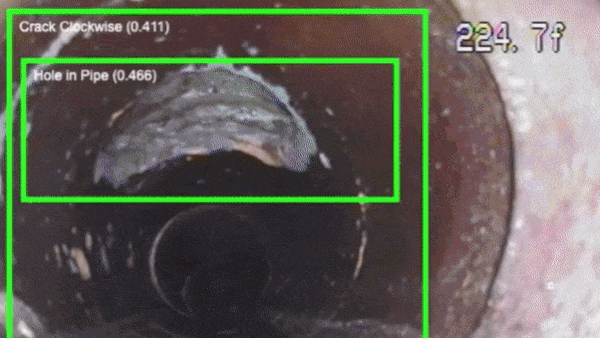
A system from California startup SewerAI analyzes videos of underground pipes to prioritize those in need of repair.

December 1, 20211 min read
AI Goes Underground: Computer Vision From SewerAI Classifies Defective Pipes
Vision

AI Goes Underground: Computer Vision From SewerAI Classifies Defective Pipes

A system from California startup SewerAI analyzes videos of underground pipes to prioritize those in need of repair.

December 1, 20211 min read
Deep Learning for Deep Frying: White Castle Uses Robots to Cook French Fries
Vision

Deep Learning for Deep Frying: White Castle Uses Robots to Cook French Fries

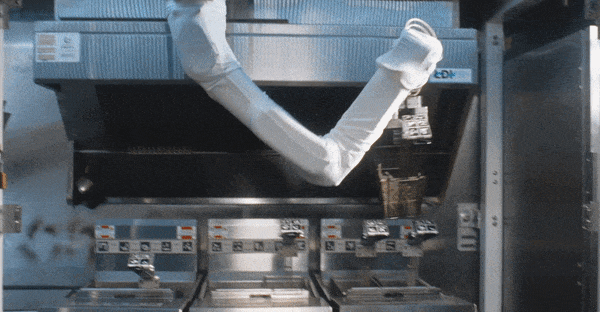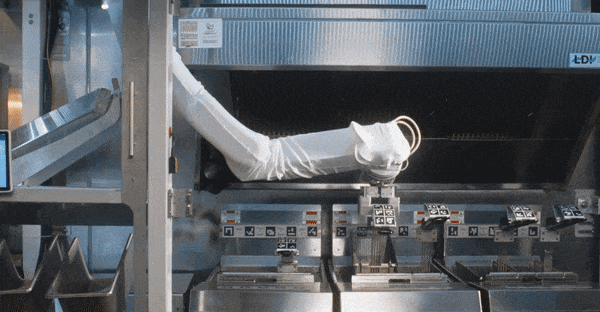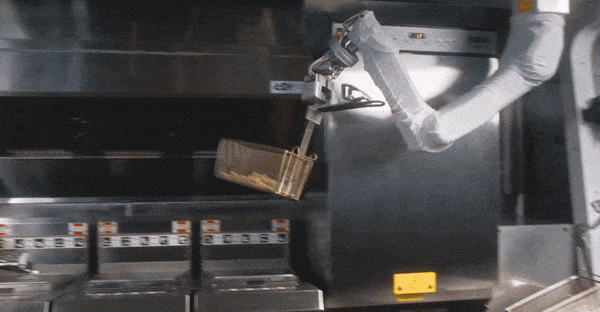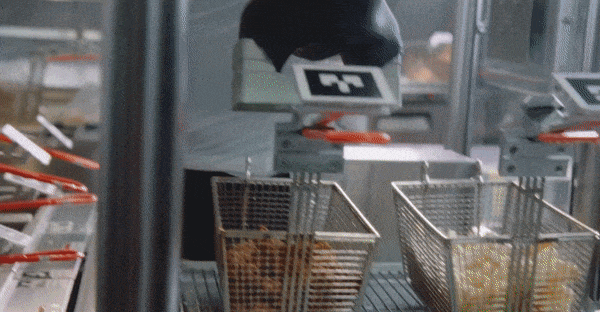
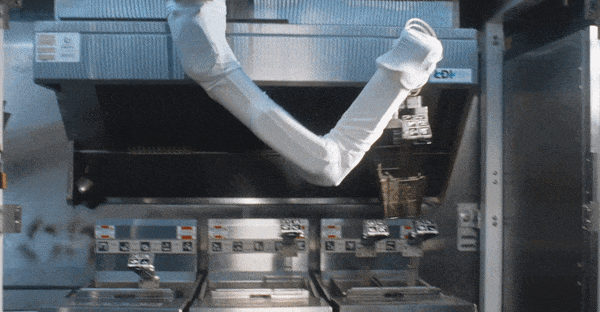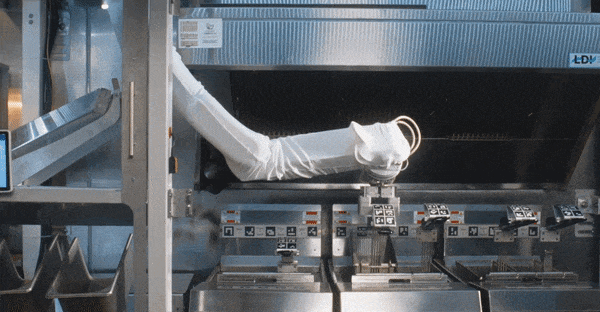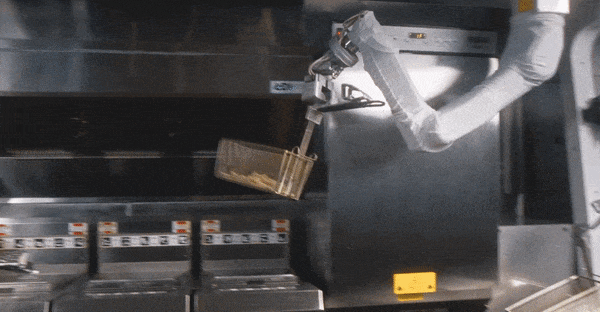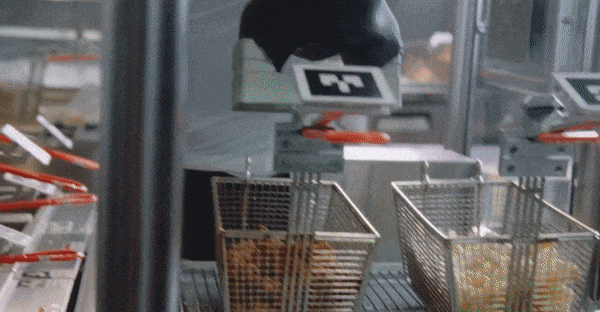
Flippy 2, a robotic fry station from California-based Miso Robotics, has been newly deployed in a Chicago White Castle location.

November 24, 20212 min read
Deep Learning for Deep Frying: White Castle Uses Robots to Cook French Fries
Vision

Deep Learning for Deep Frying: White Castle Uses Robots to Cook French Fries

Flippy 2, a robotic fry station from California-based Miso Robotics, has been newly deployed in a Chicago White Castle location.

November 24, 20212 min read
Who Can Afford to Train AI?: Cost of AI is Too Expensive for Many Small Companies
Vision

Who Can Afford to Train AI?: Cost of AI is Too Expensive for Many Small Companies

The cost of training top-performing machine learning models has grown beyond the reach of smaller companies.

November 17, 20212 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox