Vision Transformer
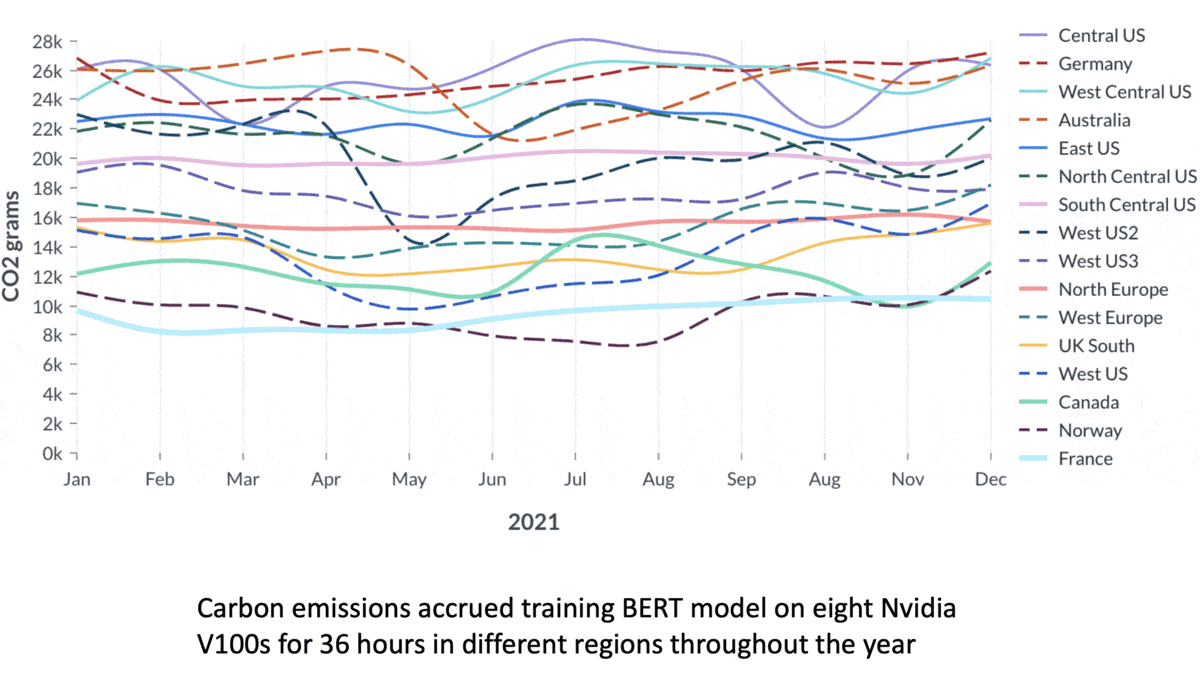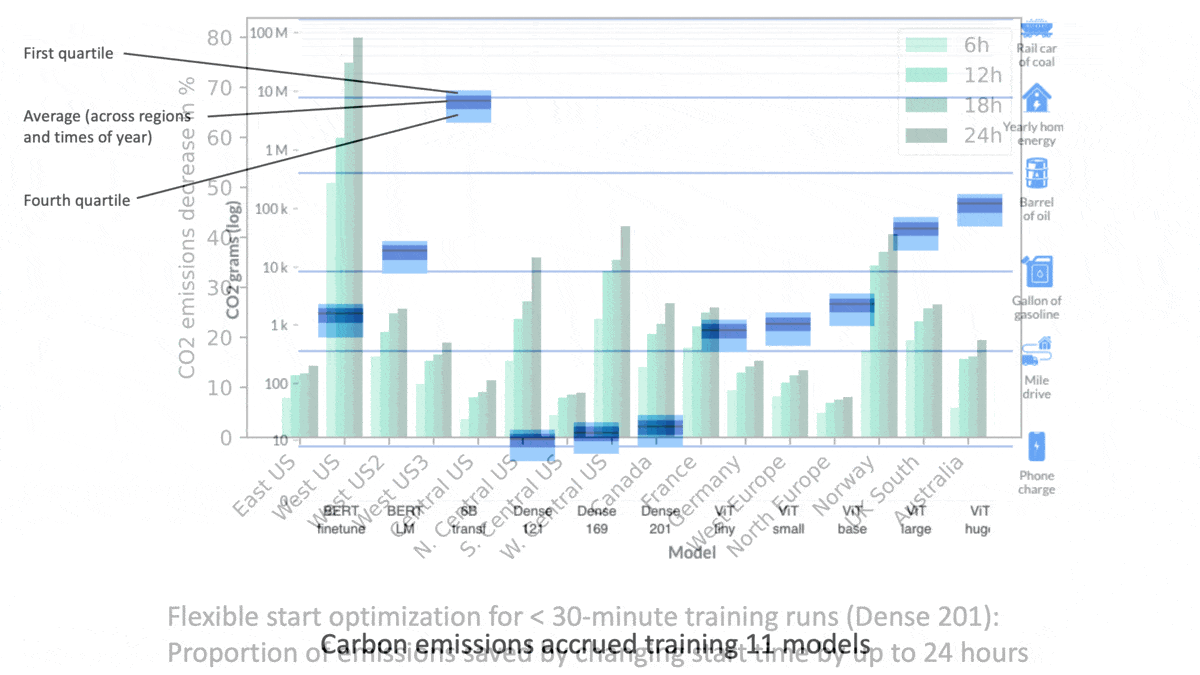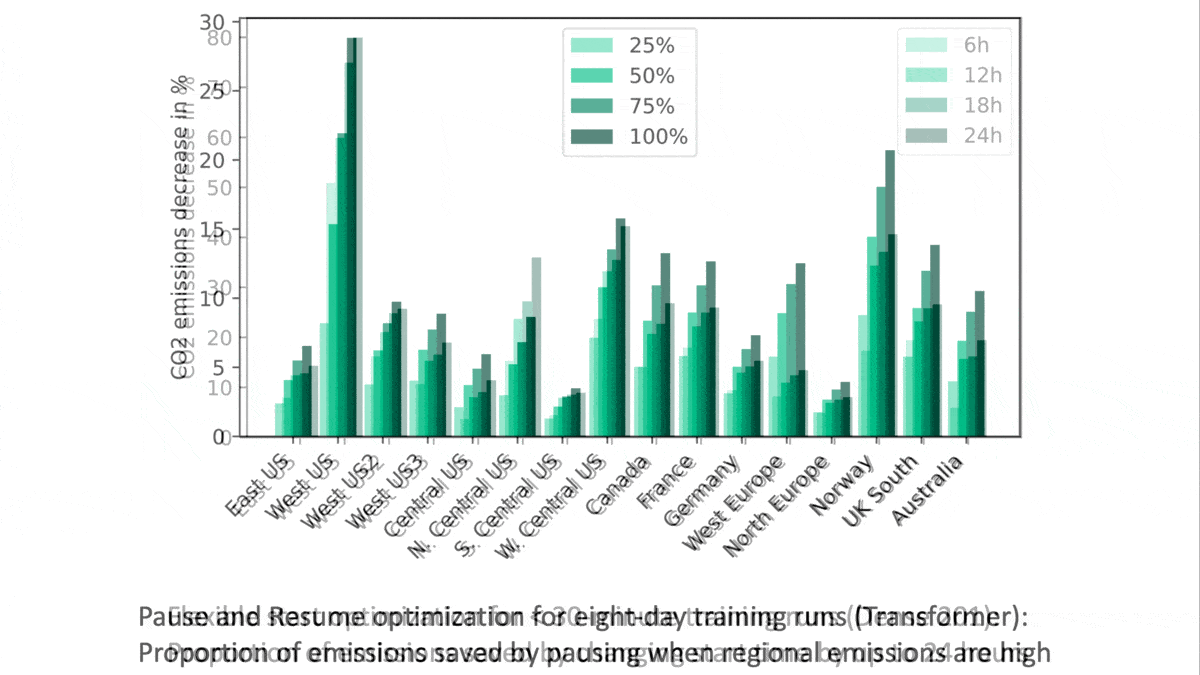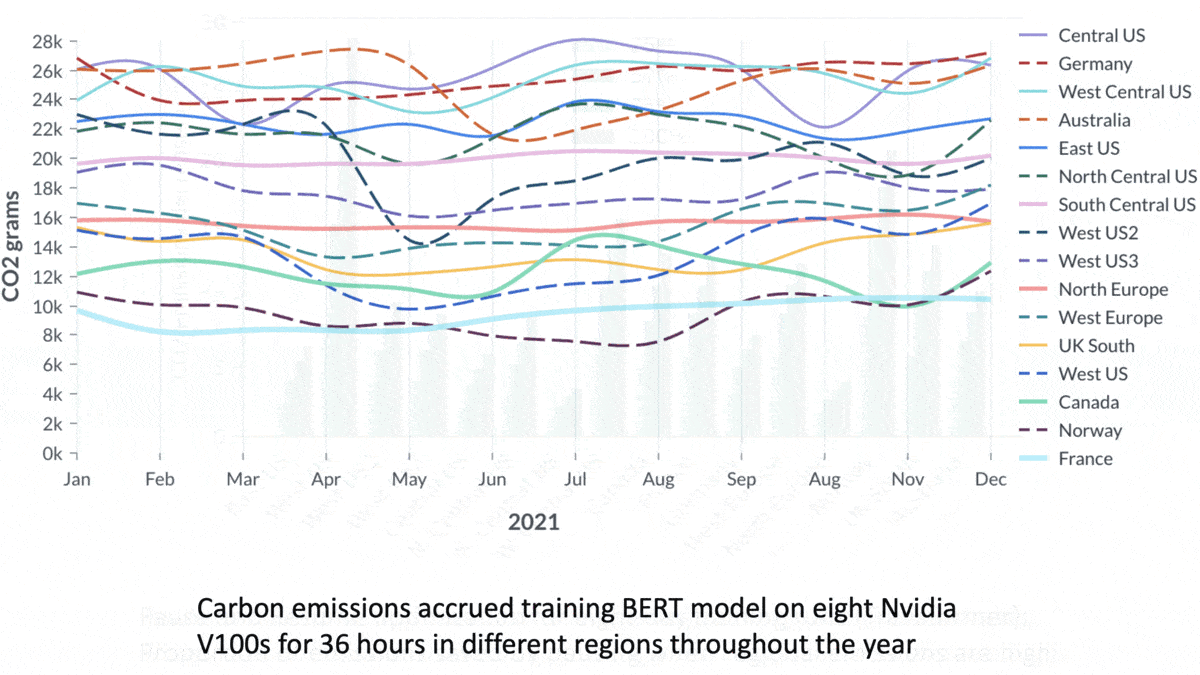
Cutting the Carbon Cost of Training: A New Tool Helps NLP Models Lower Their Gas Emissions
You can reduce your model’s carbon emissions by being choosy about when and where you train it.

You can reduce your model’s carbon emissions by being choosy about when and where you train it.

Researchers have shown that it’s possible to train a computer vision model effectively on around 66 percent of the pixels in each training image. New work used 25 percent, saving computation and boosting performance to boot.
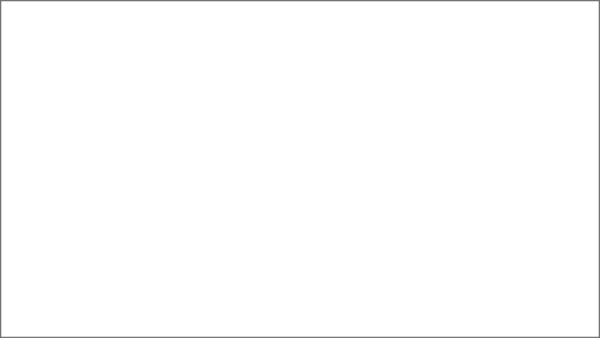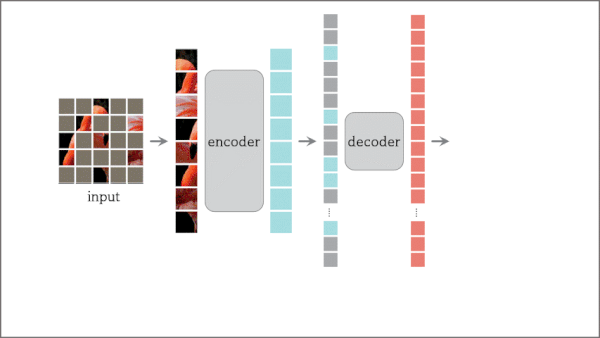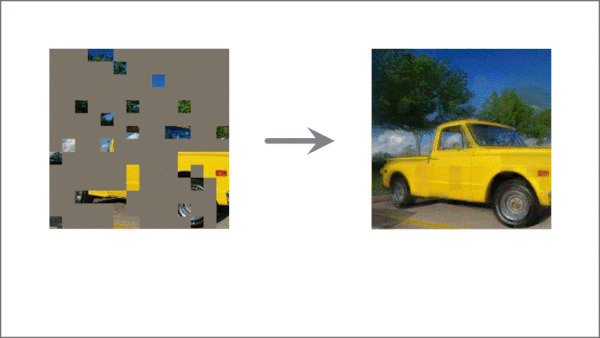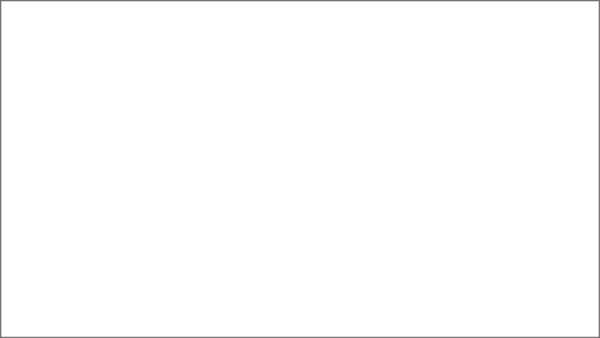
Researchers have shown that it’s possible to train a computer vision model effectively on around 66 percent of the pixels in each training image. New work used 25 percent, saving computation and boosting performance to boot.

Vision Transformer and models like it use a lot of computation and memory when processing images. New work modifies these architectures to run more efficiently while adopting helpful properties from convolutions.

Vision Transformer and models like it use a lot of computation and memory when processing images. New work modifies these architectures to run more efficiently while adopting helpful properties from convolutions.

Vision Transformer (ViT) outperformed convolutional neural networks in image classification, but it required more training data. New work enabled ViT and its variants to outperform other architectures with less training data.
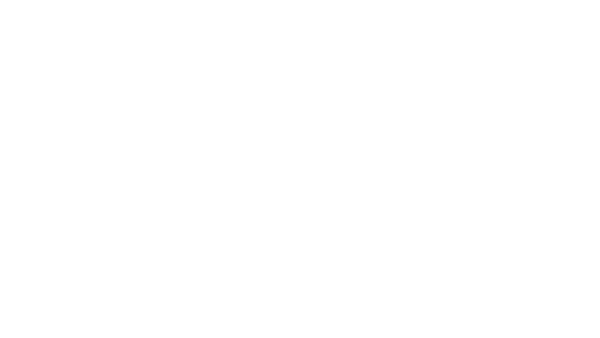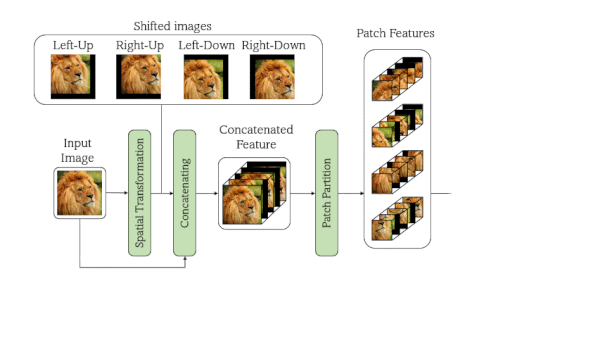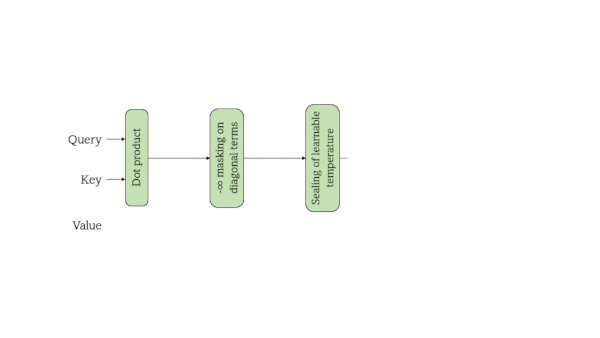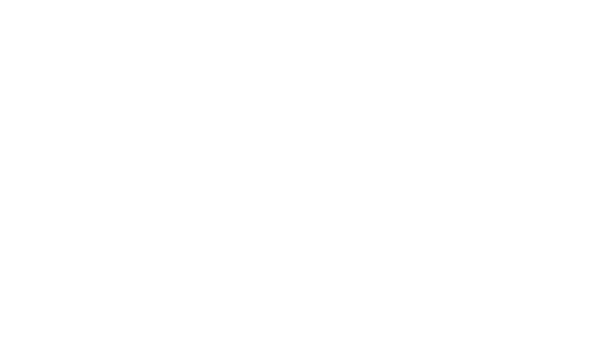
Vision Transformer (ViT) outperformed convolutional neural networks in image classification, but it required more training data. New work enabled ViT and its variants to outperform other architectures with less training data.
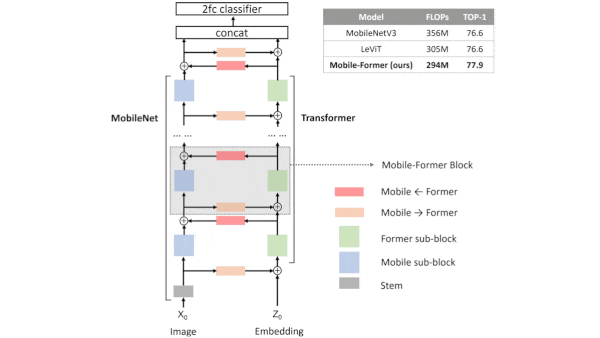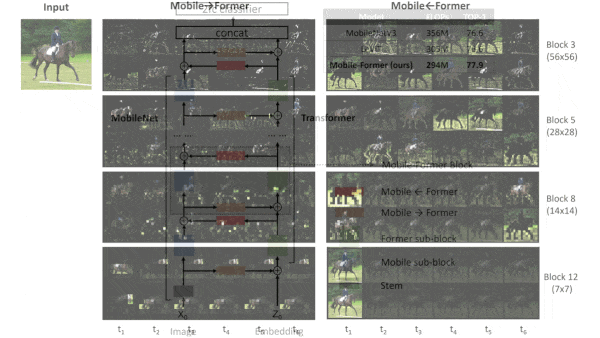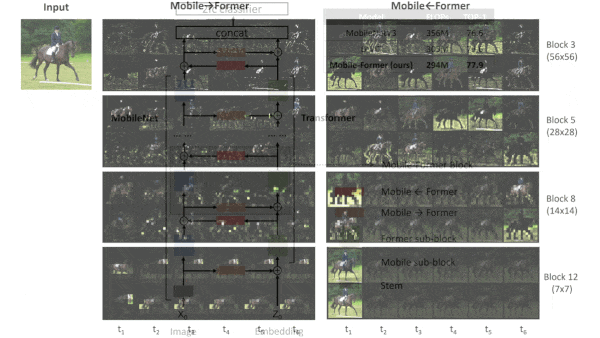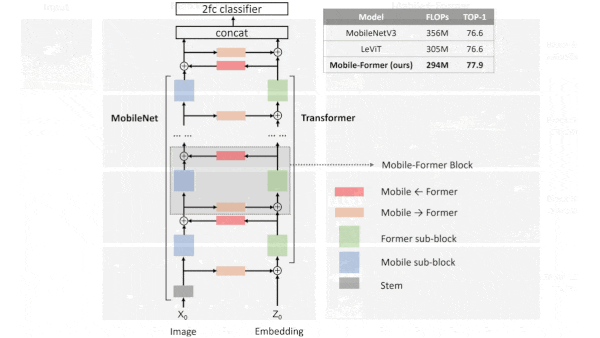
Equipment that relies on computer vision while unplugged — mobile phones, drones, satellites, autonomous cars — need power-efficient models. A new architecture set a record for accuracy per computation.

Equipment that relies on computer vision while unplugged — mobile phones, drones, satellites, autonomous cars — need power-efficient models. A new architecture set a record for accuracy per computation.
Stay updated with weekly AI News and Insights delivered to your inbox