Transformer Speed-Up Sped Up: How to Speed Up Image Transformers
Transformer

Transformer Speed-Up Sped Up: How to Speed Up Image Transformers

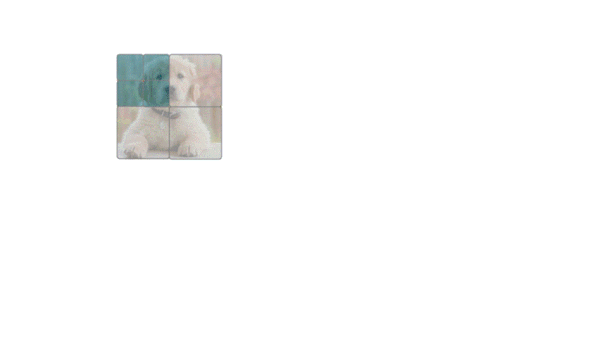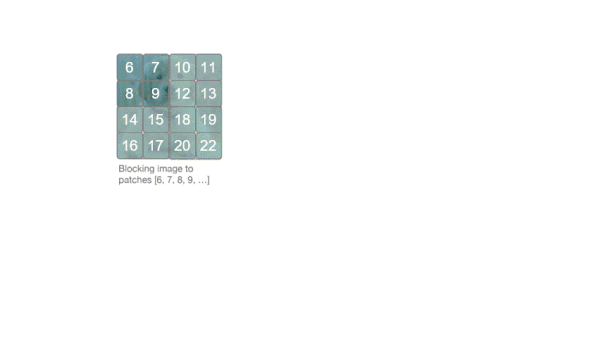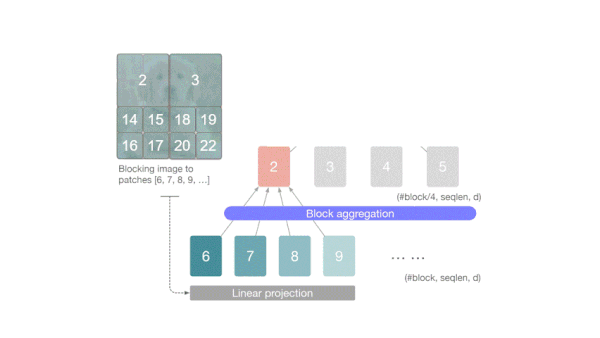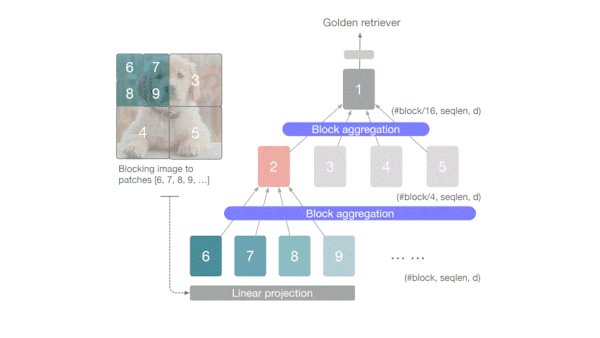
The transformer architecture is notoriously inefficient when processing long sequences — a problem in processing images, which are essentially long sequences of pixels. One way around this is to break up input images and process the pieces
October 13, 20211 min read
Search Goes Multimodal: Google Upgrades its Search Algorithm with Multimodal AI
Transformer

Search Goes Multimodal: Google Upgrades its Search Algorithm with Multimodal AI

Google will upgrade its search engine with a new model that tracks the relationships between words, images, and, in time, videos — the first fruit of its latest research into multimodal machine learning and multilingual language modeling.

October 13, 20212 min read
Transformer Speed-Up Sped Up: How to Speed Up Image Transformers
Transformer

Transformer Speed-Up Sped Up: How to Speed Up Image Transformers

The transformer architecture is notoriously inefficient when processing long sequences — a problem in processing images, which are essentially long sequences of pixels. One way around this is to break up input images and process the pieces
October 13, 20211 min read
Perceptrons Are All You Need: Google Brain's Multi-Layer Perceptron Rivals Transformers
Transformer

Perceptrons Are All You Need: Google Brain's Multi-Layer Perceptron Rivals Transformers

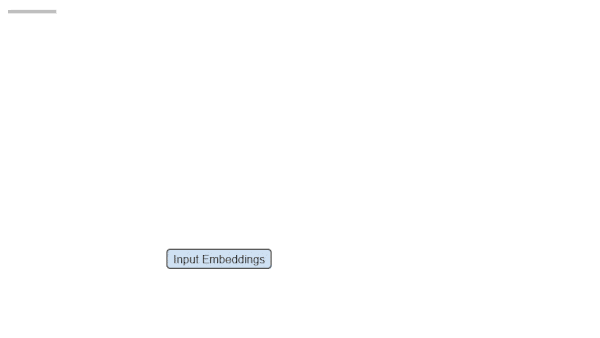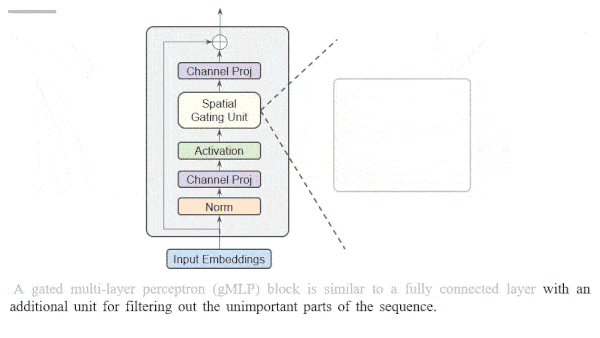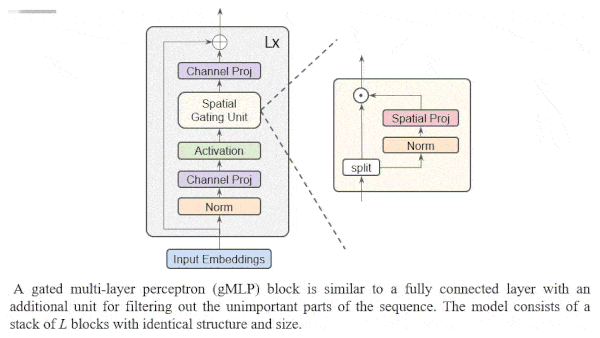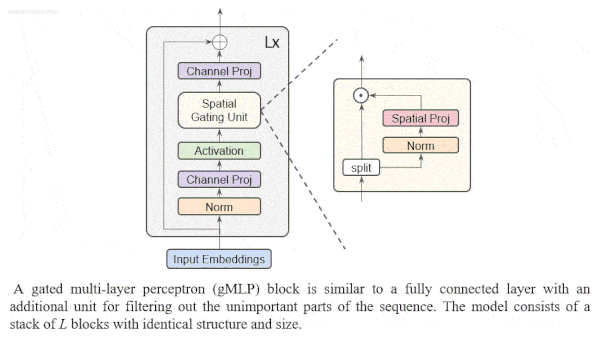
The paper that introduced the transformer famously declared, “Attention is all you need.” To the contrary, new work shows you may not need transformer-style attention at all.What’s new: Hanxiao Liu and colleagues at Google

September 8, 20212 min read
Perceptrons Are All You Need: Google Brain's Multi-Layer Perceptron Rivals Transformers
Transformer

Perceptrons Are All You Need: Google Brain's Multi-Layer Perceptron Rivals Transformers

The paper that introduced the transformer famously declared, “Attention is all you need.” To the contrary, new work shows you may not need transformer-style attention at all.What’s new: Hanxiao Liu and colleagues at Google

September 8, 20212 min read
Ask Me in a Different Way: Prompt Engineering Improves Few-Shot Learning Results
Transformer

Ask Me in a Different Way: Prompt Engineering Improves Few-Shot Learning Results

Pretrained language models like GPT-3 have shown notable proficiency in few-shot learning. Given a prompt that includes a few example questions and answers (the shots) plus an unanswered question (the task), such models can generate an accurate answer.

September 1, 20212 min read
Ask Me in a Different Way: Prompt Engineering Improves Few-Shot Learning Results
Transformer

Ask Me in a Different Way: Prompt Engineering Improves Few-Shot Learning Results

Pretrained language models like GPT-3 have shown notable proficiency in few-shot learning. Given a prompt that includes a few example questions and answers (the shots) plus an unanswered question (the task), such models can generate an accurate answer.

September 1, 20212 min read
Weak Foundations Make Weak Models: Foundation AI Models Pass Flaws to Fine-Tuned Variants
Transformer

Weak Foundations Make Weak Models: Foundation AI Models Pass Flaws to Fine-Tuned Variants

A new study examines a major strain of recent research: huge models pretrained on immense quantities of uncurated, unlabeled data and then fine-tuned on a smaller, curated corpus.

August 25, 20212 min read
Weak Foundations Make Weak Models: Foundation AI Models Pass Flaws to Fine-Tuned Variants
Transformer

Weak Foundations Make Weak Models: Foundation AI Models Pass Flaws to Fine-Tuned Variants

A new study examines a major strain of recent research: huge models pretrained on immense quantities of uncurated, unlabeled data and then fine-tuned on a smaller, curated corpus.

August 25, 20212 min read
Sharper Attention: NLP transformer technique for more Efficient token usage.
Transformer

Sharper Attention: NLP transformer technique for more Efficient token usage.

Self-attention enables transformer networks to track relationships between distant tokens — such as text characters — in long sequences, but the computational resources required grow quadratically with input size.

August 11, 20212 min read
Sharper Attention: NLP transformer technique for more Efficient token usage.
Transformer

Sharper Attention: NLP transformer technique for more Efficient token usage.

Self-attention enables transformer networks to track relationships between distant tokens — such as text characters — in long sequences, but the computational resources required grow quadratically with input size.

August 11, 20212 min read
Transformers Are Smarter Than You Think: Language transformers can do math, vision, and logic.
Transformer

Transformers Are Smarter Than You Think: Language transformers can do math, vision, and logic.

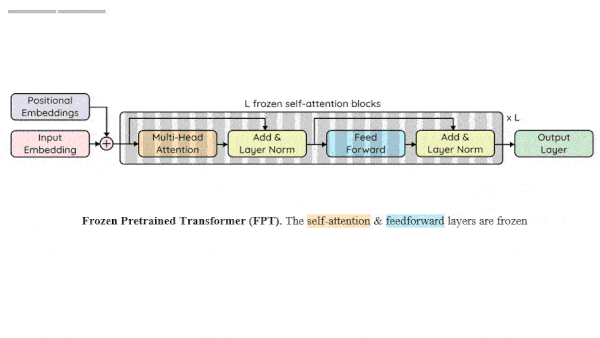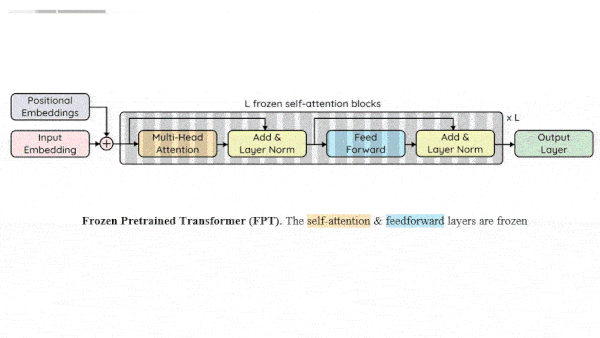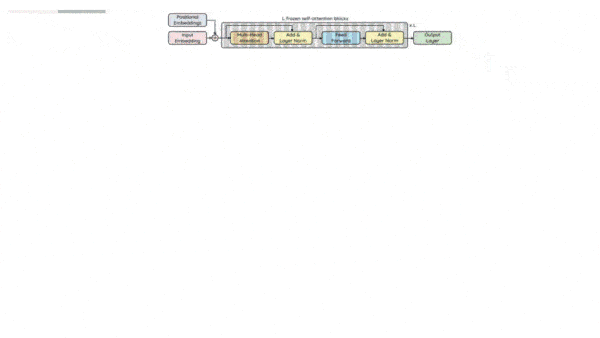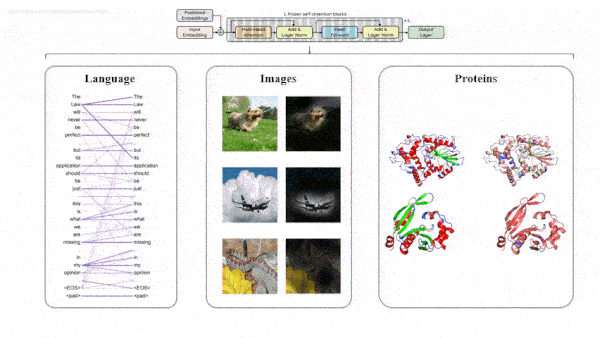
The transformer architecture has shown an uncanny ability to model not only language but also images and proteins. New research found that it can apply what it learns from the first domain to the others.

July 28, 20212 min read
Transformers Are Smarter Than You Think: Language transformers can do math, vision, and logic.
Transformer

Transformers Are Smarter Than You Think: Language transformers can do math, vision, and logic.

The transformer architecture has shown an uncanny ability to model not only language but also images and proteins. New research found that it can apply what it learns from the first domain to the others.

July 28, 20212 min read
I Know It When I See It: Zero-shot detection for objects not in training data.
Transformer

I Know It When I See It: Zero-shot detection for objects not in training data.

Object detectors typically detect only items that were labeled in their training data. A new method liberates them to locate and recognize a much wider variety of objects.

July 14, 20212 min read
I Know It When I See It: Zero-shot detection for objects not in training data.
Transformer

I Know It When I See It: Zero-shot detection for objects not in training data.

Object detectors typically detect only items that were labeled in their training data. A new method liberates them to locate and recognize a much wider variety of objects.

July 14, 20212 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox