Helpful Neighbors: A research summary of the kNN-LM language model
Machine Learning Research

Helpful Neighbors: A research summary of the kNN-LM language model

School teachers may not like to hear this, but sometimes you get the best answer by peeking at your neighbor’s paper. A new language model framework peeks at the training data for context when making a prediction.
January 29, 20202 min read
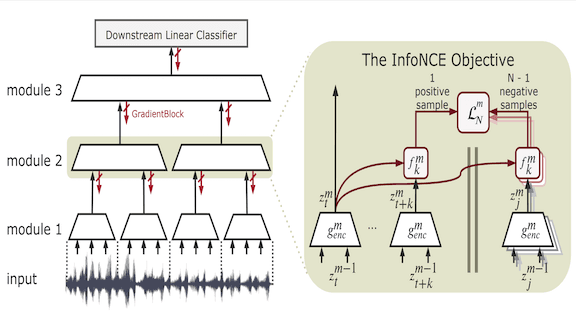
Better Than Backprop: Greedy InfoMax trains AI without end-to-end backpropagation.
Machine Learning Research

Better Than Backprop: Greedy InfoMax trains AI without end-to-end backpropagation.

End-to-end backpropagation and labeled data are the peanut butter and chocolate of deep learning. However, recent work suggests that neither is necessary to train effective neural networks to represent complex data.

January 22, 20202 min read
Better Than Backprop: Greedy InfoMax trains AI without end-to-end backpropagation.
Machine Learning Research

Better Than Backprop: Greedy InfoMax trains AI without end-to-end backpropagation.

End-to-end backpropagation and labeled data are the peanut butter and chocolate of deep learning. However, recent work suggests that neither is necessary to train effective neural networks to represent complex data.

January 22, 20202 min read
Upgrading Softmax: Mixtape is a faster way to avoid the softmax bottleneck.
Machine Learning Research

Upgrading Softmax: Mixtape is a faster way to avoid the softmax bottleneck.

Softmax commonly computes probabilities in a classifier’s output layer. But softmax isn’t always accurate in complex tasks — say, in a natural-language task, when the length of word vectors is much smaller than the number of words in the vocabulary.

January 22, 20202 min read
Upgrading Softmax: Mixtape is a faster way to avoid the softmax bottleneck.
Machine Learning Research

Upgrading Softmax: Mixtape is a faster way to avoid the softmax bottleneck.

Softmax commonly computes probabilities in a classifier’s output layer. But softmax isn’t always accurate in complex tasks — say, in a natural-language task, when the length of word vectors is much smaller than the number of words in the vocabulary.

January 22, 20202 min read
Neural Networks Study Math: A sequence to sequence model for solving math problems.
Machine Learning Research

Neural Networks Study Math: A sequence to sequence model for solving math problems.

In tasks that involve generating natural language, neural networks often map an input sequence of words to an output sequence of words. Facebook researchers used a similar technique on sequences of mathematical symbols, training a model to map math problems to math solutions.

January 15, 20202 min read
Two-Way Winner: MuZero AI masters both video games and board games.
Machine Learning Research

Two-Way Winner: MuZero AI masters both video games and board games.

AlphaGo Zero demonstrates superhuman performance playing Go, chess, and shogi. Models like R2D2 do the same playing classic Atari titles. A new approach to deep reinforcement learning is the first to achieve state-of-the-art results playing both board and video games.

January 15, 20202 min read
Neural Networks Study Math: A sequence to sequence model for solving math problems.
Machine Learning Research

Neural Networks Study Math: A sequence to sequence model for solving math problems.

In tasks that involve generating natural language, neural networks often map an input sequence of words to an output sequence of words. Facebook researchers used a similar technique on sequences of mathematical symbols, training a model to map math problems to math solutions.

January 15, 20202 min read
Two-Way Winner: MuZero AI masters both video games and board games.
Machine Learning Research

Two-Way Winner: MuZero AI masters both video games and board games.

AlphaGo Zero demonstrates superhuman performance playing Go, chess, and shogi. Models like R2D2 do the same playing classic Atari titles. A new approach to deep reinforcement learning is the first to achieve state-of-the-art results playing both board and video games.

January 15, 20202 min read
Easy on the Eyes: More accurate object detection with EfficientDet
Machine Learning Research

Easy on the Eyes: More accurate object detection with EfficientDet

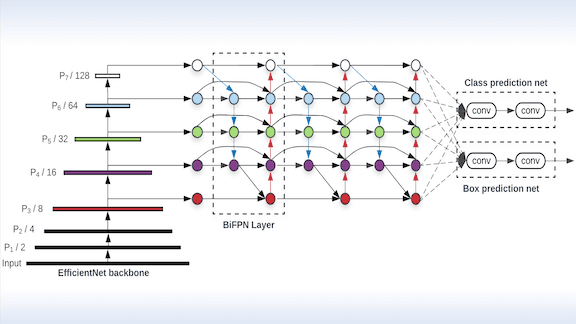
Researchers aiming to increase accuracy in object detection generally enlarge the network, but that approach also boosts computational cost. A novel architecture sets a new state of the art in accuracy while cutting the compute cycles required.

January 8, 20202 min read
Easy on the Eyes: More accurate object detection with EfficientDet
Machine Learning Research

Easy on the Eyes: More accurate object detection with EfficientDet

Researchers aiming to increase accuracy in object detection generally enlarge the network, but that approach also boosts computational cost. A novel architecture sets a new state of the art in accuracy while cutting the compute cycles required.

January 8, 20202 min read
Language Modeling on One GPU: Single-headed attention competes with transformers.
Machine Learning Research

Language Modeling on One GPU: Single-headed attention competes with transformers.

The latest large, pretrained language models rely on trendy layers based on transformer networks. New research shows that these newfangled layers may not be necessary.

January 8, 20202 min read
Language Modeling on One GPU: Single-headed attention competes with transformers.
Machine Learning Research

Language Modeling on One GPU: Single-headed attention competes with transformers.

The latest large, pretrained language models rely on trendy layers based on transformer networks. New research shows that these newfangled layers may not be necessary.

January 8, 20202 min read
Different Skills From Different Demos: Implicit reinforcement without interaction at scale, explained
Machine Learning Research

Different Skills From Different Demos: Implicit reinforcement without interaction at scale, explained

Reinforcement learning trains models by trial and error. In batch reinforcement learning (BRL), models learn by observing many demonstrations by a variety of actors. But what if one doctor is handier with a scalpel while another excels at suturing?

December 18, 20192 min read
Different Skills From Different Demos: Implicit reinforcement without interaction at scale, explained
Machine Learning Research

Different Skills From Different Demos: Implicit reinforcement without interaction at scale, explained

Reinforcement learning trains models by trial and error. In batch reinforcement learning (BRL), models learn by observing many demonstrations by a variety of actors. But what if one doctor is handier with a scalpel while another excels at suturing?

December 18, 20192 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox