More Thinking Solves Harder Problems: AI Can Learn From Simple Tasks to Solve Hard Problems
Machine Learning Research

More Thinking Solves Harder Problems: AI Can Learn From Simple Tasks to Solve Hard Problems

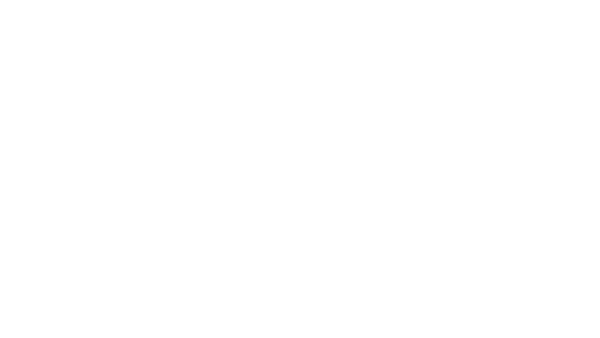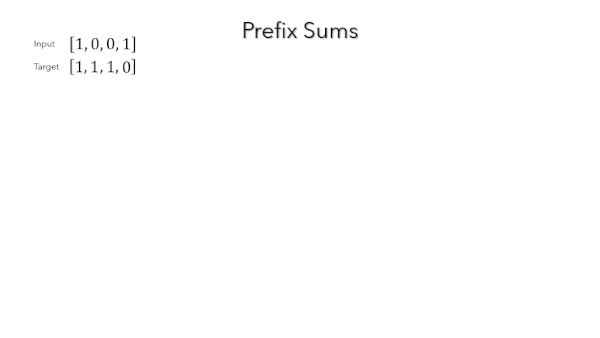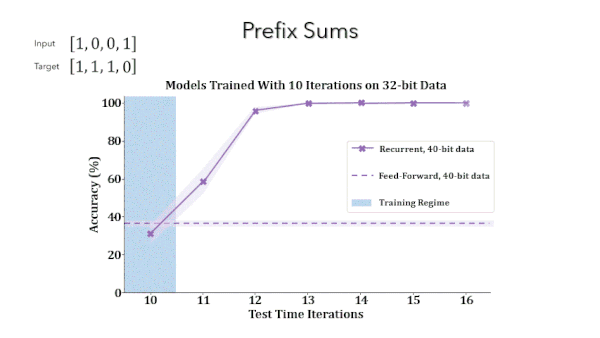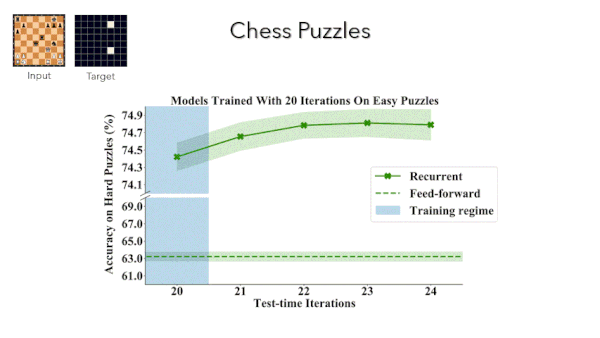
In machine learning, an easy task and a more difficult version of the same task — say, a maze that covers a smaller or larger area — often are learned separately.

September 29, 20212 min read
AI With a Sense of Style: Style Transfer Method Produces Consistent Output in Successive Video Frames
Machine Learning Research

AI With a Sense of Style: Style Transfer Method Produces Consistent Output in Successive Video Frames

The process known as image-to-image style transfer — mapping, say, the character of a painting’s brushstrokes onto a photo — can render inconsistent results. When they apply the styles of different artists to the same target

September 22, 20213 min read
AI With a Sense of Style: Style Transfer Method Produces Consistent Output in Successive Video Frames
Machine Learning Research

AI With a Sense of Style: Style Transfer Method Produces Consistent Output in Successive Video Frames

The process known as image-to-image style transfer — mapping, say, the character of a painting’s brushstrokes onto a photo — can render inconsistent results. When they apply the styles of different artists to the same target

September 22, 20213 min read
Team Players: Football-Playing AI Blends Individual and Group Skills
Machine Learning Research

Team Players: Football-Playing AI Blends Individual and Group Skills

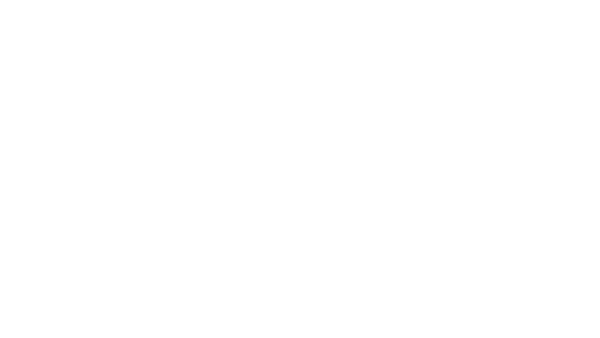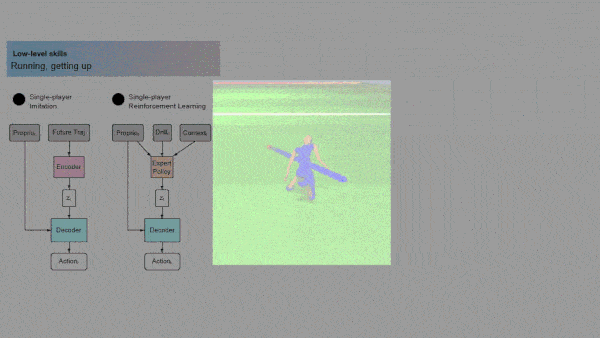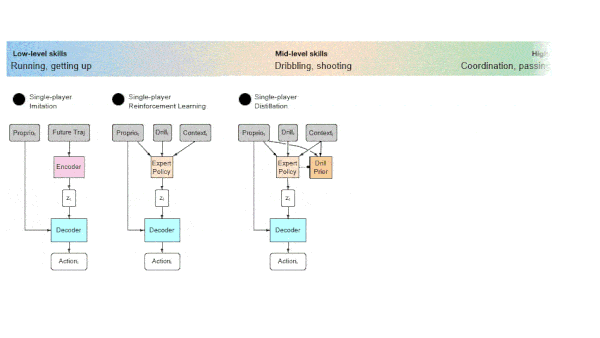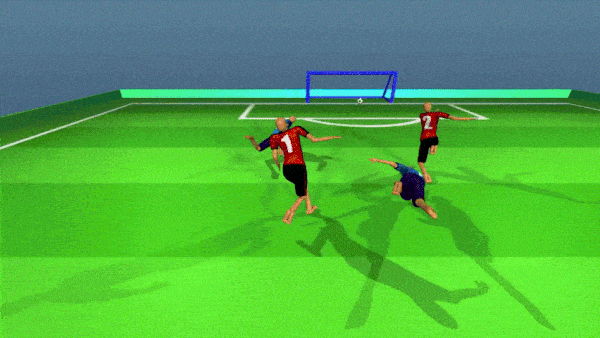
Playing a team sport involves a fluid blend of individual and group skills. Researchers integrated both types of action into realistic humanoid agents that play football (known as soccer in the U.S.).

September 15, 20212 min read
Team Players: Football-Playing AI Blends Individual and Group Skills
Machine Learning Research

Team Players: Football-Playing AI Blends Individual and Group Skills

Playing a team sport involves a fluid blend of individual and group skills. Researchers integrated both types of action into realistic humanoid agents that play football (known as soccer in the U.S.).

September 15, 20212 min read
Perceptrons Are All You Need: Google Brain's Multi-Layer Perceptron Rivals Transformers
Machine Learning Research

Perceptrons Are All You Need: Google Brain's Multi-Layer Perceptron Rivals Transformers

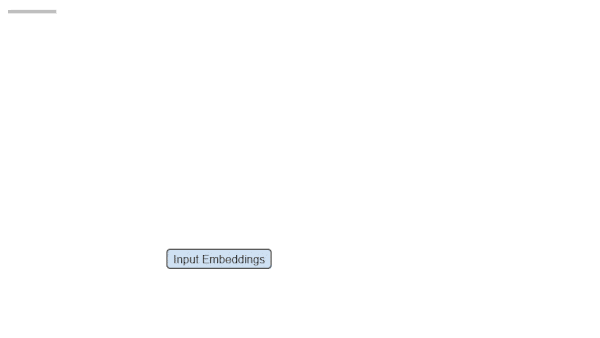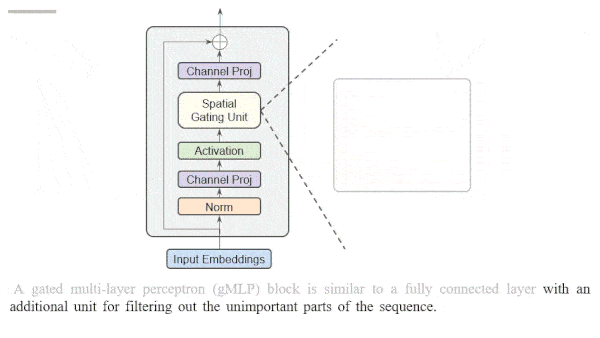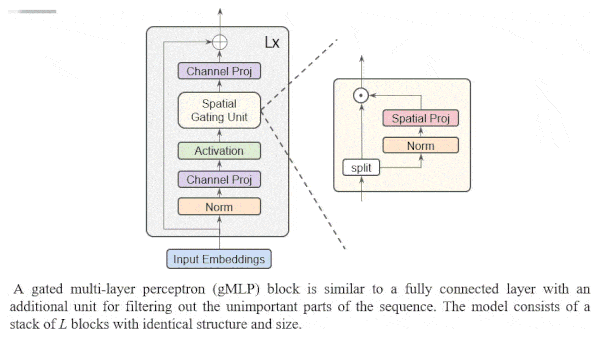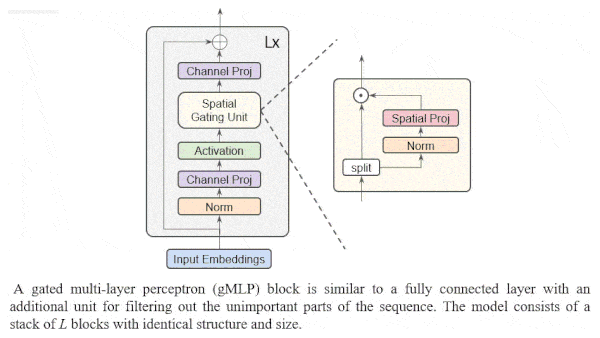
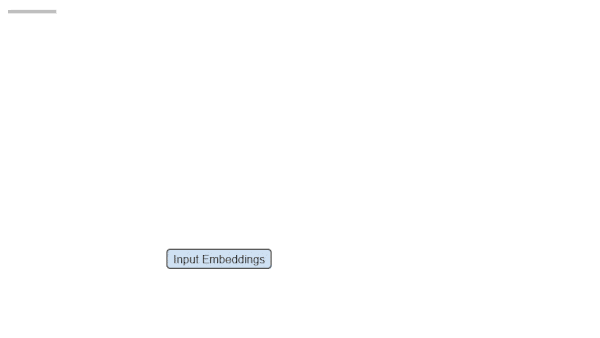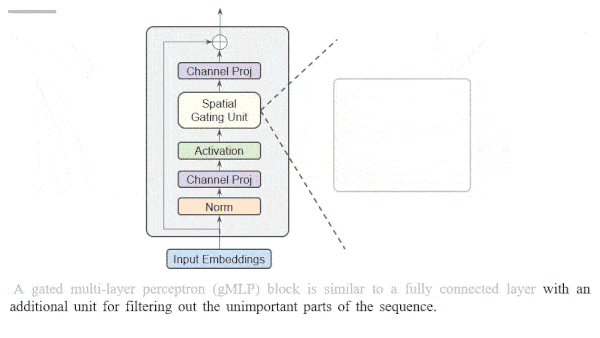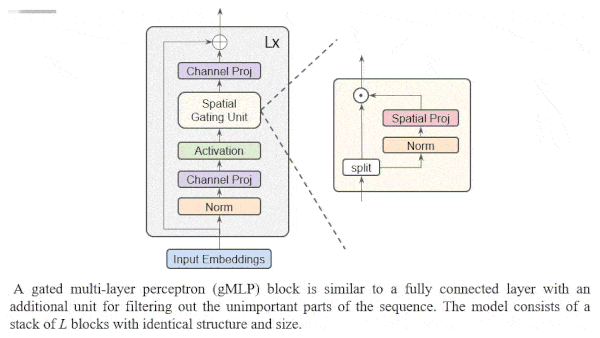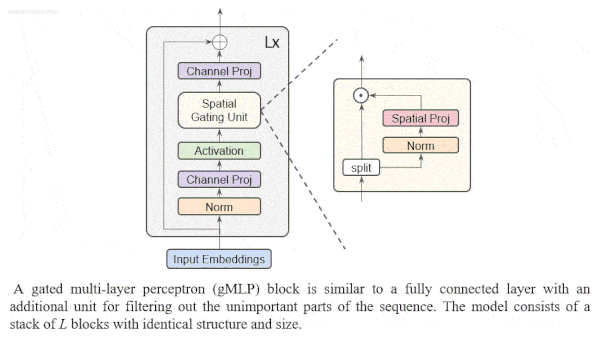
The paper that introduced the transformer famously declared, “Attention is all you need.” To the contrary, new work shows you may not need transformer-style attention at all.What’s new: Hanxiao Liu and colleagues at Google

September 8, 20212 min read
Perceptrons Are All You Need: Google Brain's Multi-Layer Perceptron Rivals Transformers
Machine Learning Research

Perceptrons Are All You Need: Google Brain's Multi-Layer Perceptron Rivals Transformers

The paper that introduced the transformer famously declared, “Attention is all you need.” To the contrary, new work shows you may not need transformer-style attention at all.What’s new: Hanxiao Liu and colleagues at Google

September 8, 20212 min read
Ask Me in a Different Way: Prompt Engineering Improves Few-Shot Learning Results
Machine Learning Research

Ask Me in a Different Way: Prompt Engineering Improves Few-Shot Learning Results

Pretrained language models like GPT-3 have shown notable proficiency in few-shot learning. Given a prompt that includes a few example questions and answers (the shots) plus an unanswered question (the task), such models can generate an accurate answer.

September 1, 20212 min read
Ask Me in a Different Way: Prompt Engineering Improves Few-Shot Learning Results
Machine Learning Research

Ask Me in a Different Way: Prompt Engineering Improves Few-Shot Learning Results

Pretrained language models like GPT-3 have shown notable proficiency in few-shot learning. Given a prompt that includes a few example questions and answers (the shots) plus an unanswered question (the task), such models can generate an accurate answer.

September 1, 20212 min read
Weak Foundations Make Weak Models: Foundation AI Models Pass Flaws to Fine-Tuned Variants
Machine Learning Research

Weak Foundations Make Weak Models: Foundation AI Models Pass Flaws to Fine-Tuned Variants

A new study examines a major strain of recent research: huge models pretrained on immense quantities of uncurated, unlabeled data and then fine-tuned on a smaller, curated corpus.

August 25, 20212 min read
Weak Foundations Make Weak Models: Foundation AI Models Pass Flaws to Fine-Tuned Variants
Machine Learning Research

Weak Foundations Make Weak Models: Foundation AI Models Pass Flaws to Fine-Tuned Variants

A new study examines a major strain of recent research: huge models pretrained on immense quantities of uncurated, unlabeled data and then fine-tuned on a smaller, curated corpus.

August 25, 20212 min read
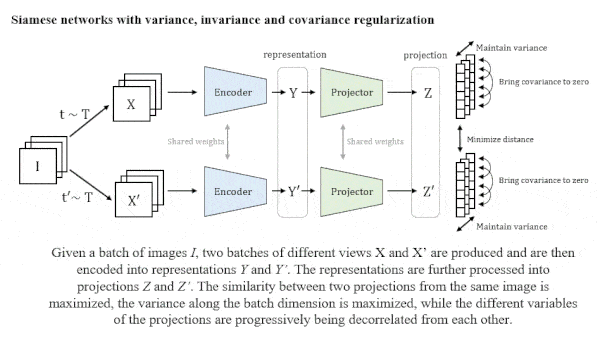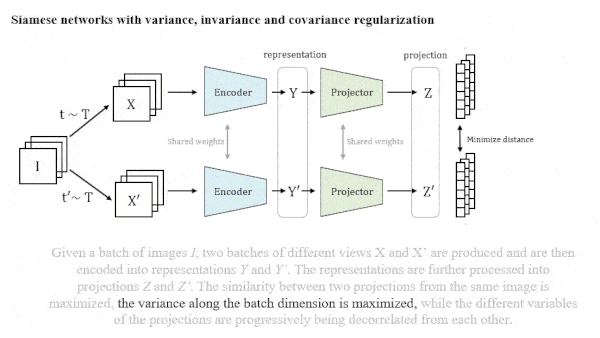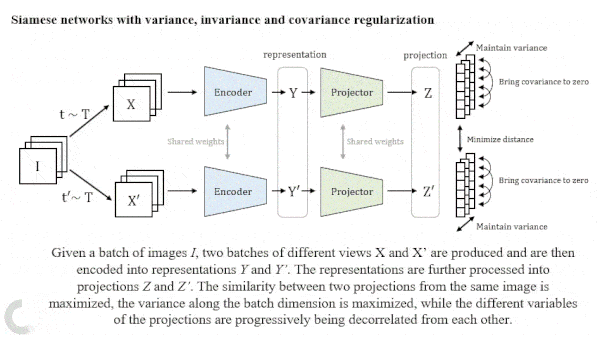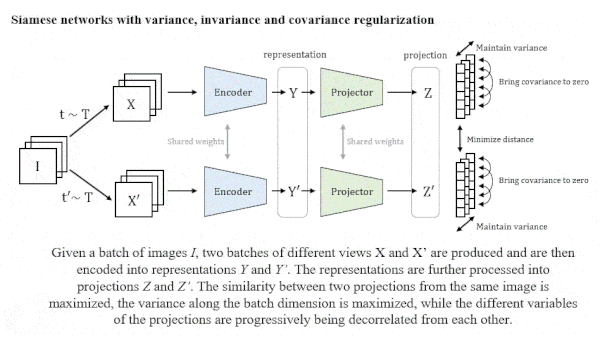
More Reliable Pretraining: Pretraining Method Helps AI Learn Useful Representations
Machine Learning Research

More Reliable Pretraining: Pretraining Method Helps AI Learn Useful Representations

Pretraining methods generate basic representations for later fine-tuning, but they’re prone to certain issues that can throw them off-kilter. New work proposes a solution.

August 25, 20212 min read
More Reliable Pretraining: Pretraining Method Helps AI Learn Useful Representations
Machine Learning Research

More Reliable Pretraining: Pretraining Method Helps AI Learn Useful Representations

Pretraining methods generate basic representations for later fine-tuning, but they’re prone to certain issues that can throw them off-kilter. New work proposes a solution.

August 25, 20212 min read
Solve RL With This One Weird Trick: How to get better performance from reinforcement learning.
Machine Learning Research

Solve RL With This One Weird Trick: How to get better performance from reinforcement learning.

The previous state-of-the-art model for playing vintage Atari games took advantage of a number of advances in reinforcement learning (RL). The new champion is a basic RL architecture plus a trick borrowed from image generation.

August 18, 20212 min read
Solve RL With This One Weird Trick: How to get better performance from reinforcement learning.
Machine Learning Research

Solve RL With This One Weird Trick: How to get better performance from reinforcement learning.

The previous state-of-the-art model for playing vintage Atari games took advantage of a number of advances in reinforcement learning (RL). The new champion is a basic RL architecture plus a trick borrowed from image generation.

August 18, 20212 min read

Subscribe to The Batch

Stay updated with weekly AI News and Insights delivered to your inbox