Generative AI
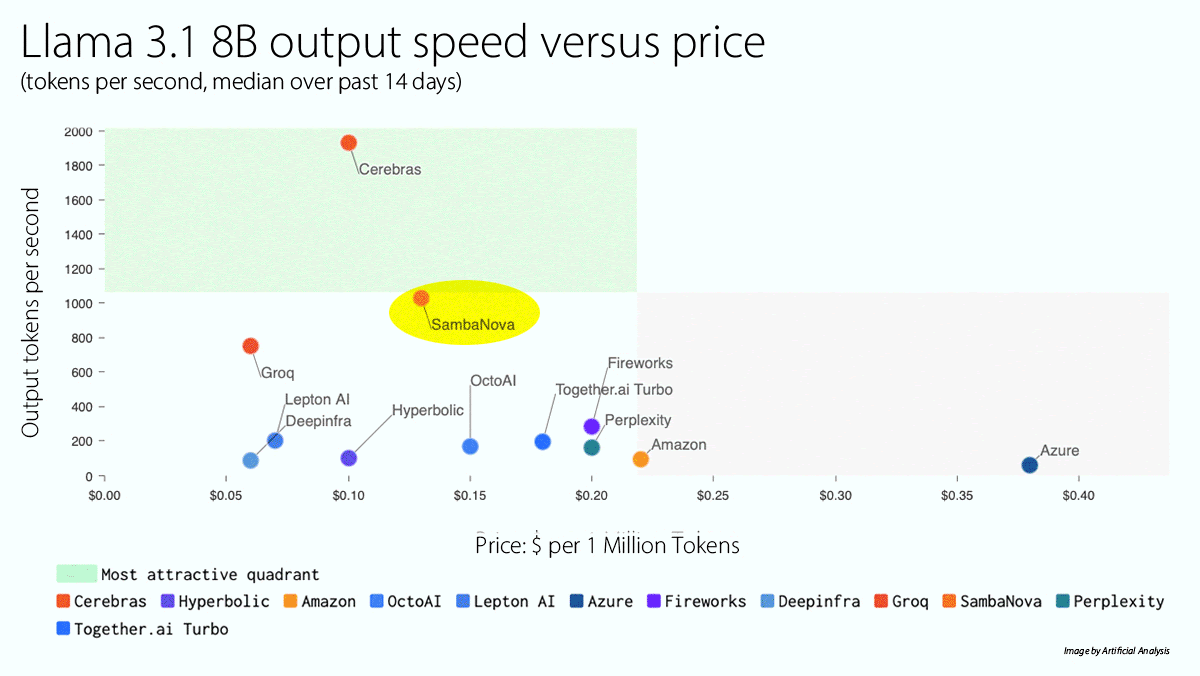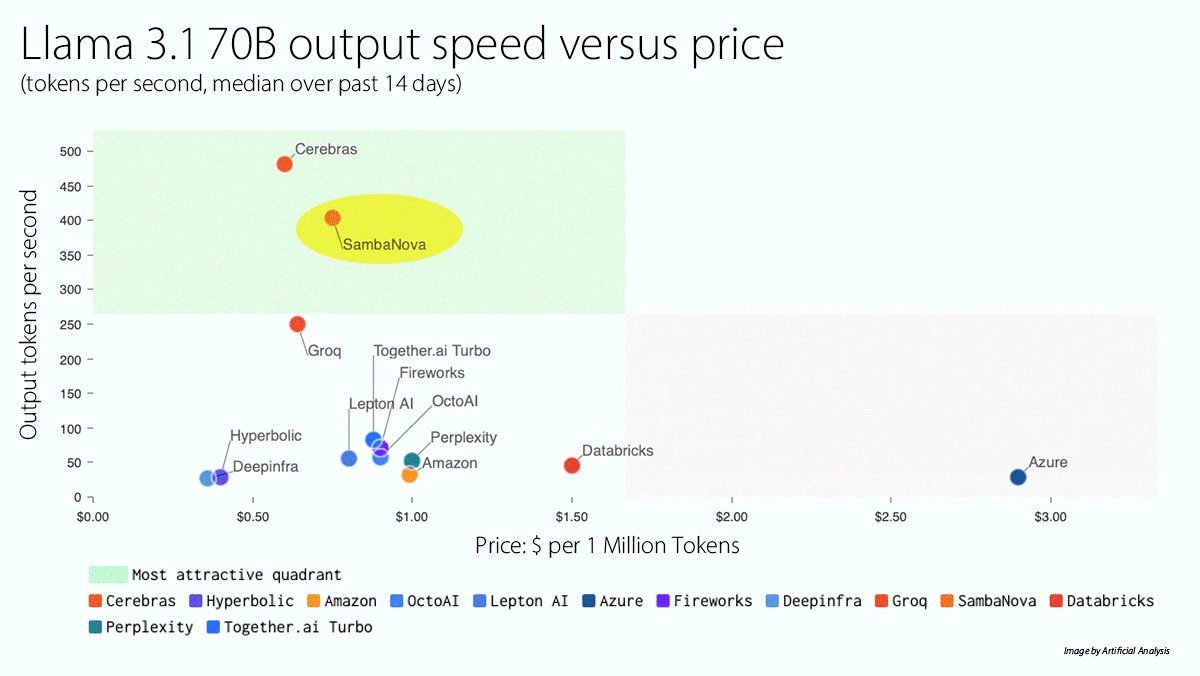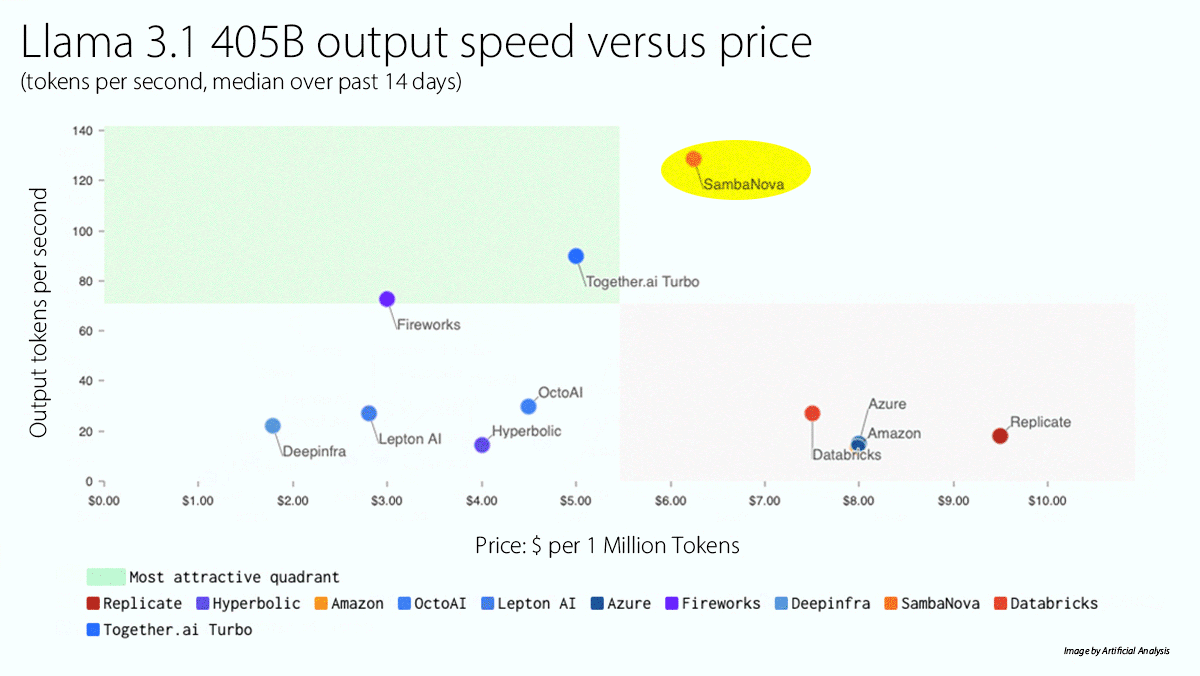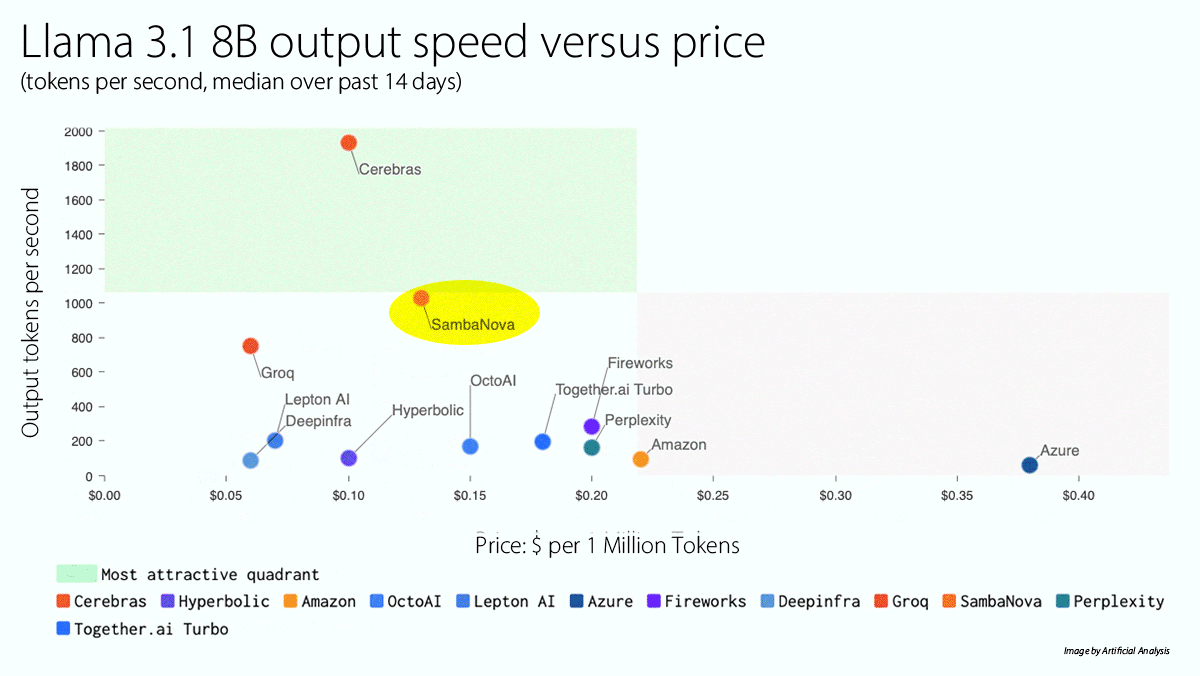
High Gear for Llama 3.1 405B: SambaNova boosts Llama 3.1 performance with fast, free access to largest model
SambaNova raised the speed limit for access to the largest model in the Llama 3.1 family — and it’s free.

SambaNova raised the speed limit for access to the largest model in the Llama 3.1 family — and it’s free.

SambaNova raised the speed limit for access to the largest model in the Llama 3.1 family — and it’s free.

Preliminary versions of OpenAI’s new model family were trained explicitly to think step-by-step, yielding outstanding marks in math, science, and coding — but users can’t see their reasoning steps.
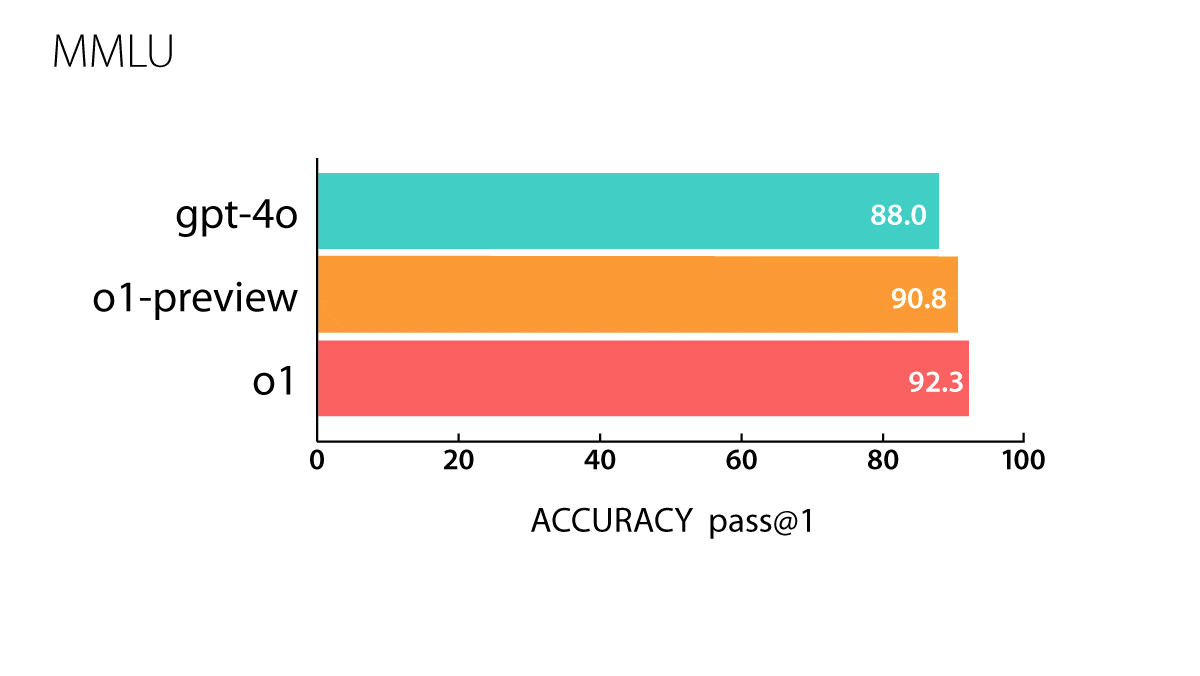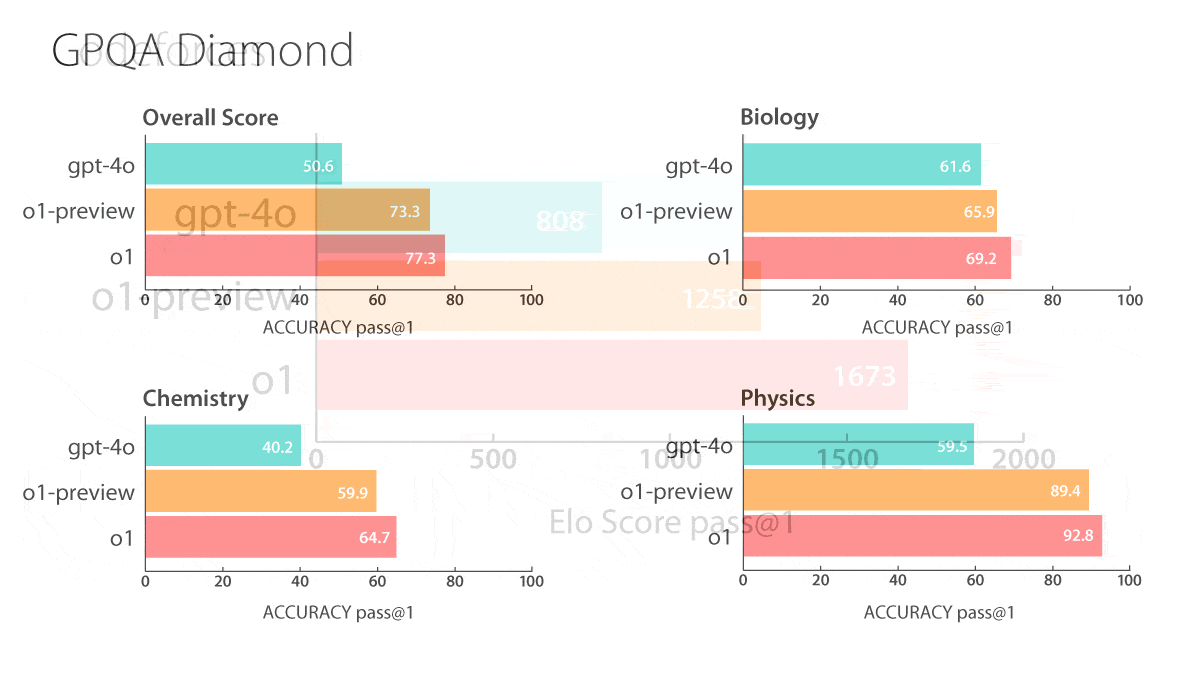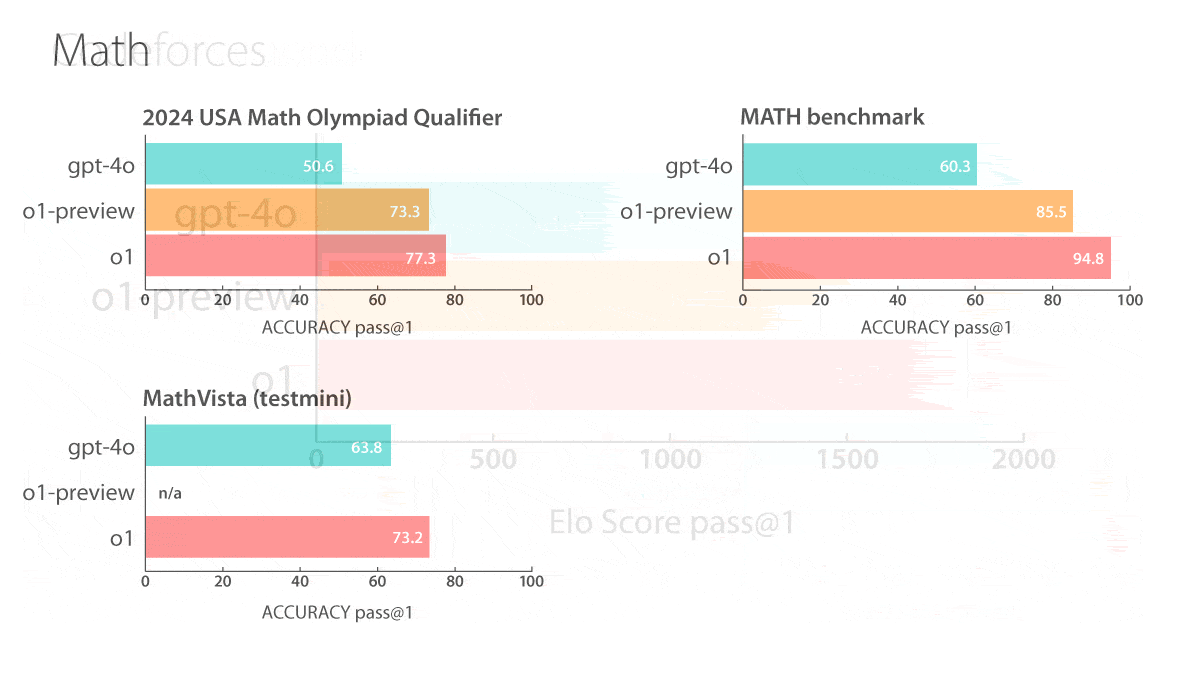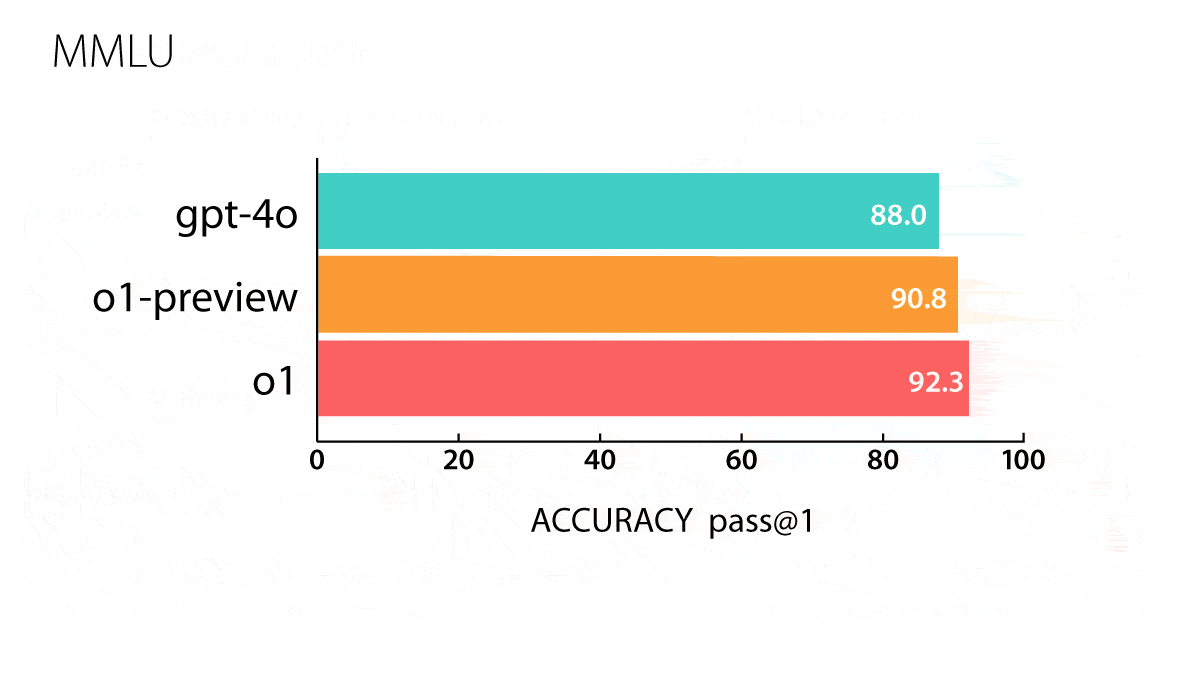
Preliminary versions of OpenAI’s new model family were trained explicitly to think step-by-step, yielding outstanding marks in math, science, and coding — but users can’t see their reasoning steps.

Traditionally, building 3D meshes for gaming, animation, product design, architecture, and the like has been labor-intensive. Now the ability to generate 3D meshes from a single image is widely available.
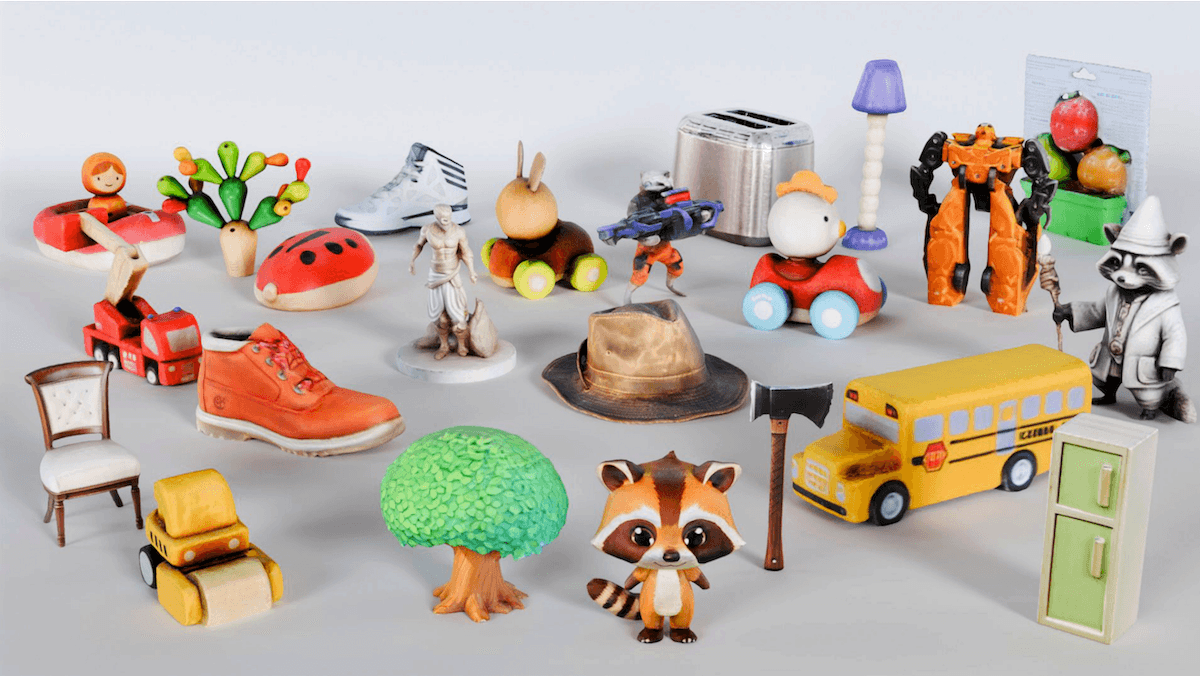
Traditionally, building 3D meshes for gaming, animation, product design, architecture, and the like has been labor-intensive. Now the ability to generate 3D meshes from a single image is widely available.
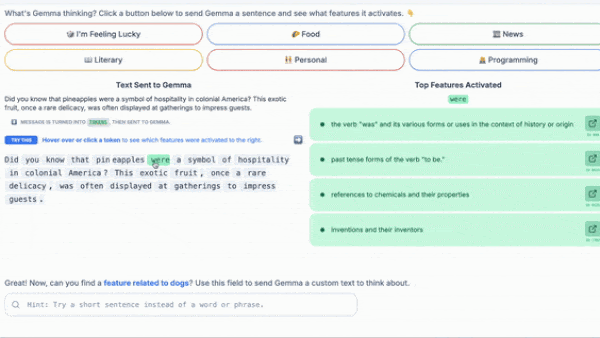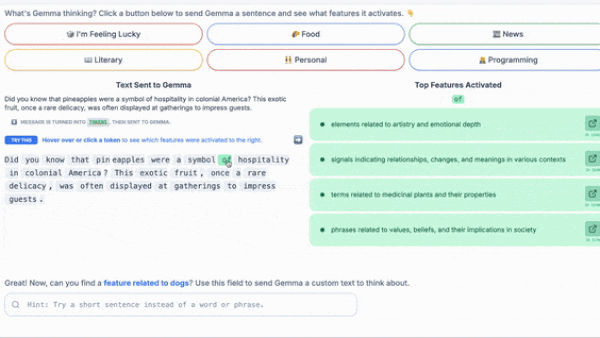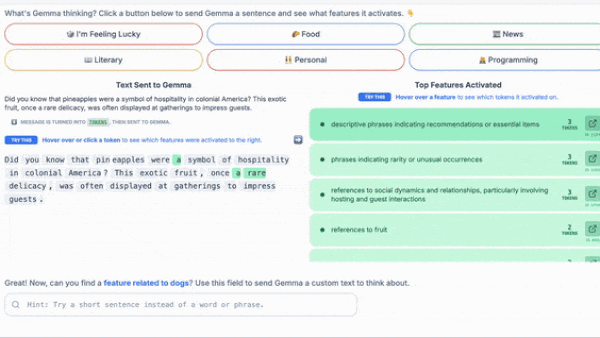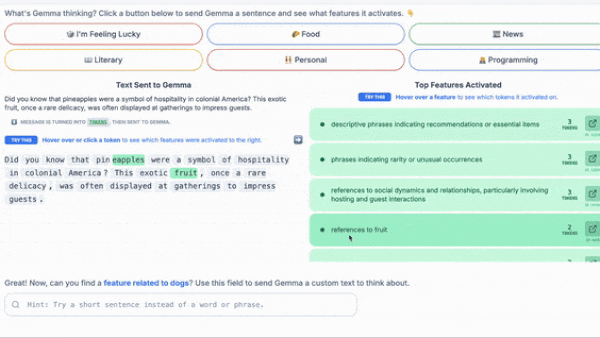
Researchers have probed the inner workings of individual layers of large language models. A new tool applies this approach to all layers.

Researchers have probed the inner workings of individual layers of large language models. A new tool applies this approach to all layers.

A new model generates tokens faster than current transformers, especially when processing long inputs.
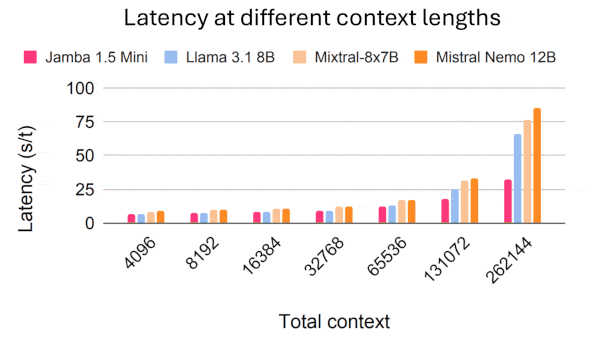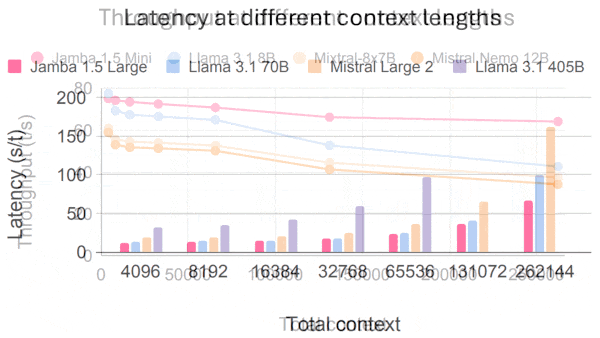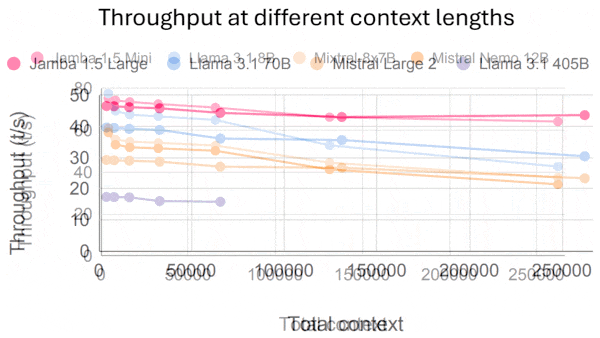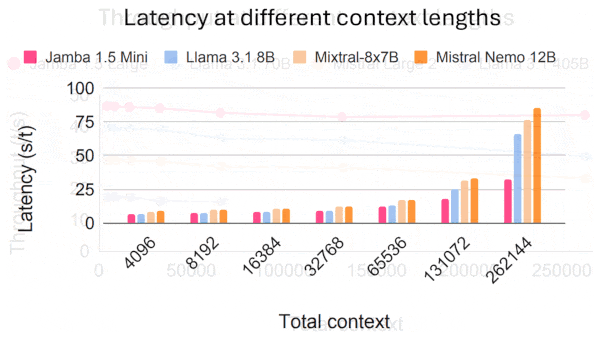
A new model generates tokens faster than current transformers, especially when processing long inputs.

An agentic coding assistant boosted the state of the art in an important benchmark by more than 30 percent.
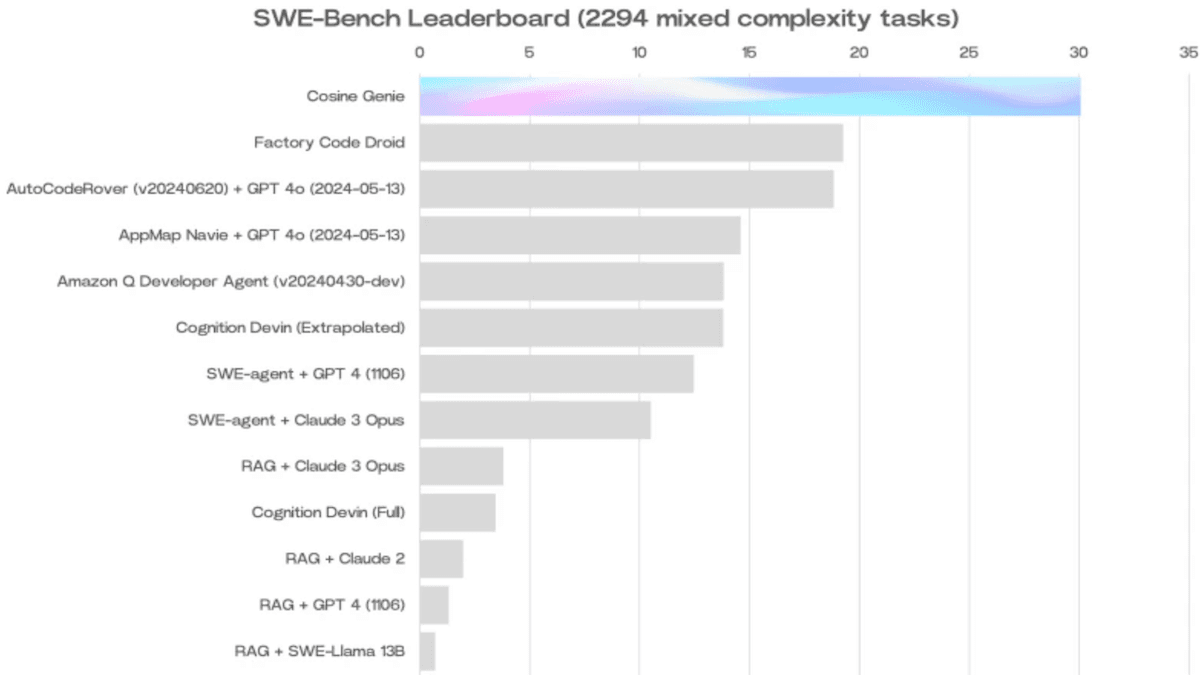
An agentic coding assistant boosted the state of the art in an important benchmark by more than 30 percent.

When training vision-language models, developers often remove lower-quality examples from the training set. But keeping only the highest-quality examples may not be ideal, researchers found.

When training vision-language models, developers often remove lower-quality examples from the training set. But keeping only the highest-quality examples may not be ideal, researchers found.

Alibaba followed up its open-weights Qwen2 large language models with specialized variations.
Stay updated with weekly AI News and Insights delivered to your inbox