
Facebook
Convolution Revolution
Looking at images, people see outlines before the details within them. A replacement for the traditional convolutional layer decomposes images based on this distinction between coarse and fine features.

Looking at images, people see outlines before the details within them. A replacement for the traditional convolutional layer decomposes images based on this distinction between coarse and fine features.

A word-embedding model typically learns vector representations from a large, general-purpose corpus like Google News. But to make the resulting vectors useful in a specialized domain, they must be fine-tuned on a smaller, domain-specific dataset. Researchers offer a more accurate method.
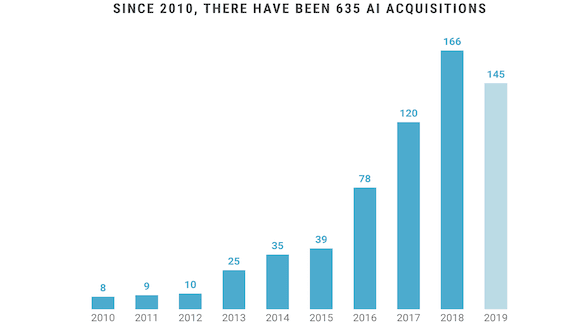
AI startups are being scooped up at an accelerating pace, many by companies outside the tech sphere. A report by CB Insights shows that, as of August, 2019 was on track to surpass last year’s record number of AI startup acquisitions.
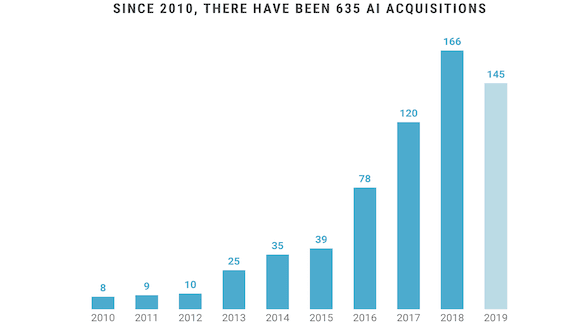
AI startups are being scooped up at an accelerating pace, many by companies outside the tech sphere. A report by CB Insights shows that, as of August, 2019 was on track to surpass last year’s record number of AI startup acquisitions.

Watson set a high bar for language understanding in 2011, when it famously whipped human competitors in the televised trivia game show Jeopardy! IBM’s special-purpose AI required around $1 billion. Research suggests that today’s best language models can accomplish similar tasks right off the shelf.
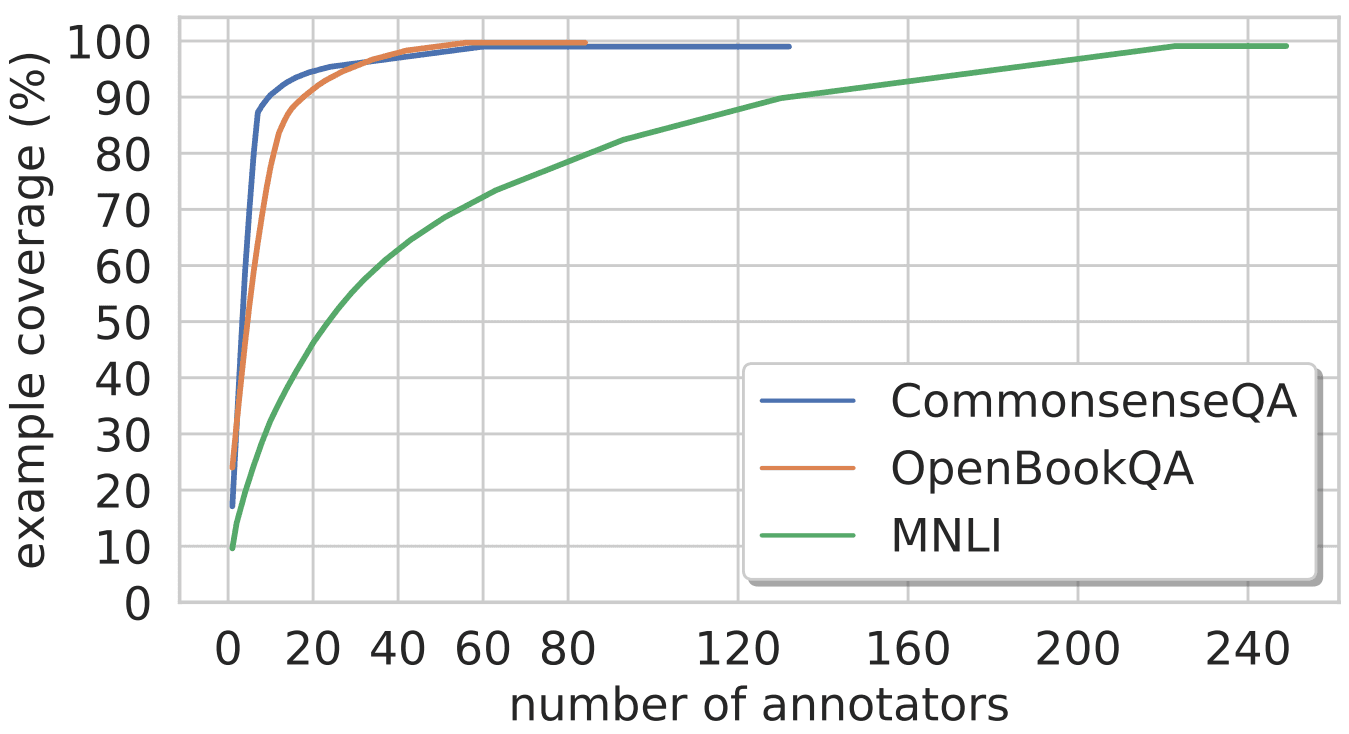
Watson set a high bar for language understanding in 2011, when it famously whipped human competitors in the televised trivia game show Jeopardy! IBM’s special-purpose AI required around $1 billion. Research suggests that today’s best language models can accomplish similar tasks right off the shelf.

Deep learning models can be unwieldy and often impractical to run on smaller devices without major modification. Researchers at Facebook AI Research found a way to compress neural networks with minimal sacrifice in accuracy.

Deep learning models can be unwieldy and often impractical to run on smaller devices without major modification. Researchers at Facebook AI Research found a way to compress neural networks with minimal sacrifice in accuracy.
Less than a month after XLNet overtook BERT, the pole position in natural language understanding changed hands again. RoBERTa is an improved BERT pretraining recipe that beats its forbear, becoming the new state-of-the-art language model — for the moment.
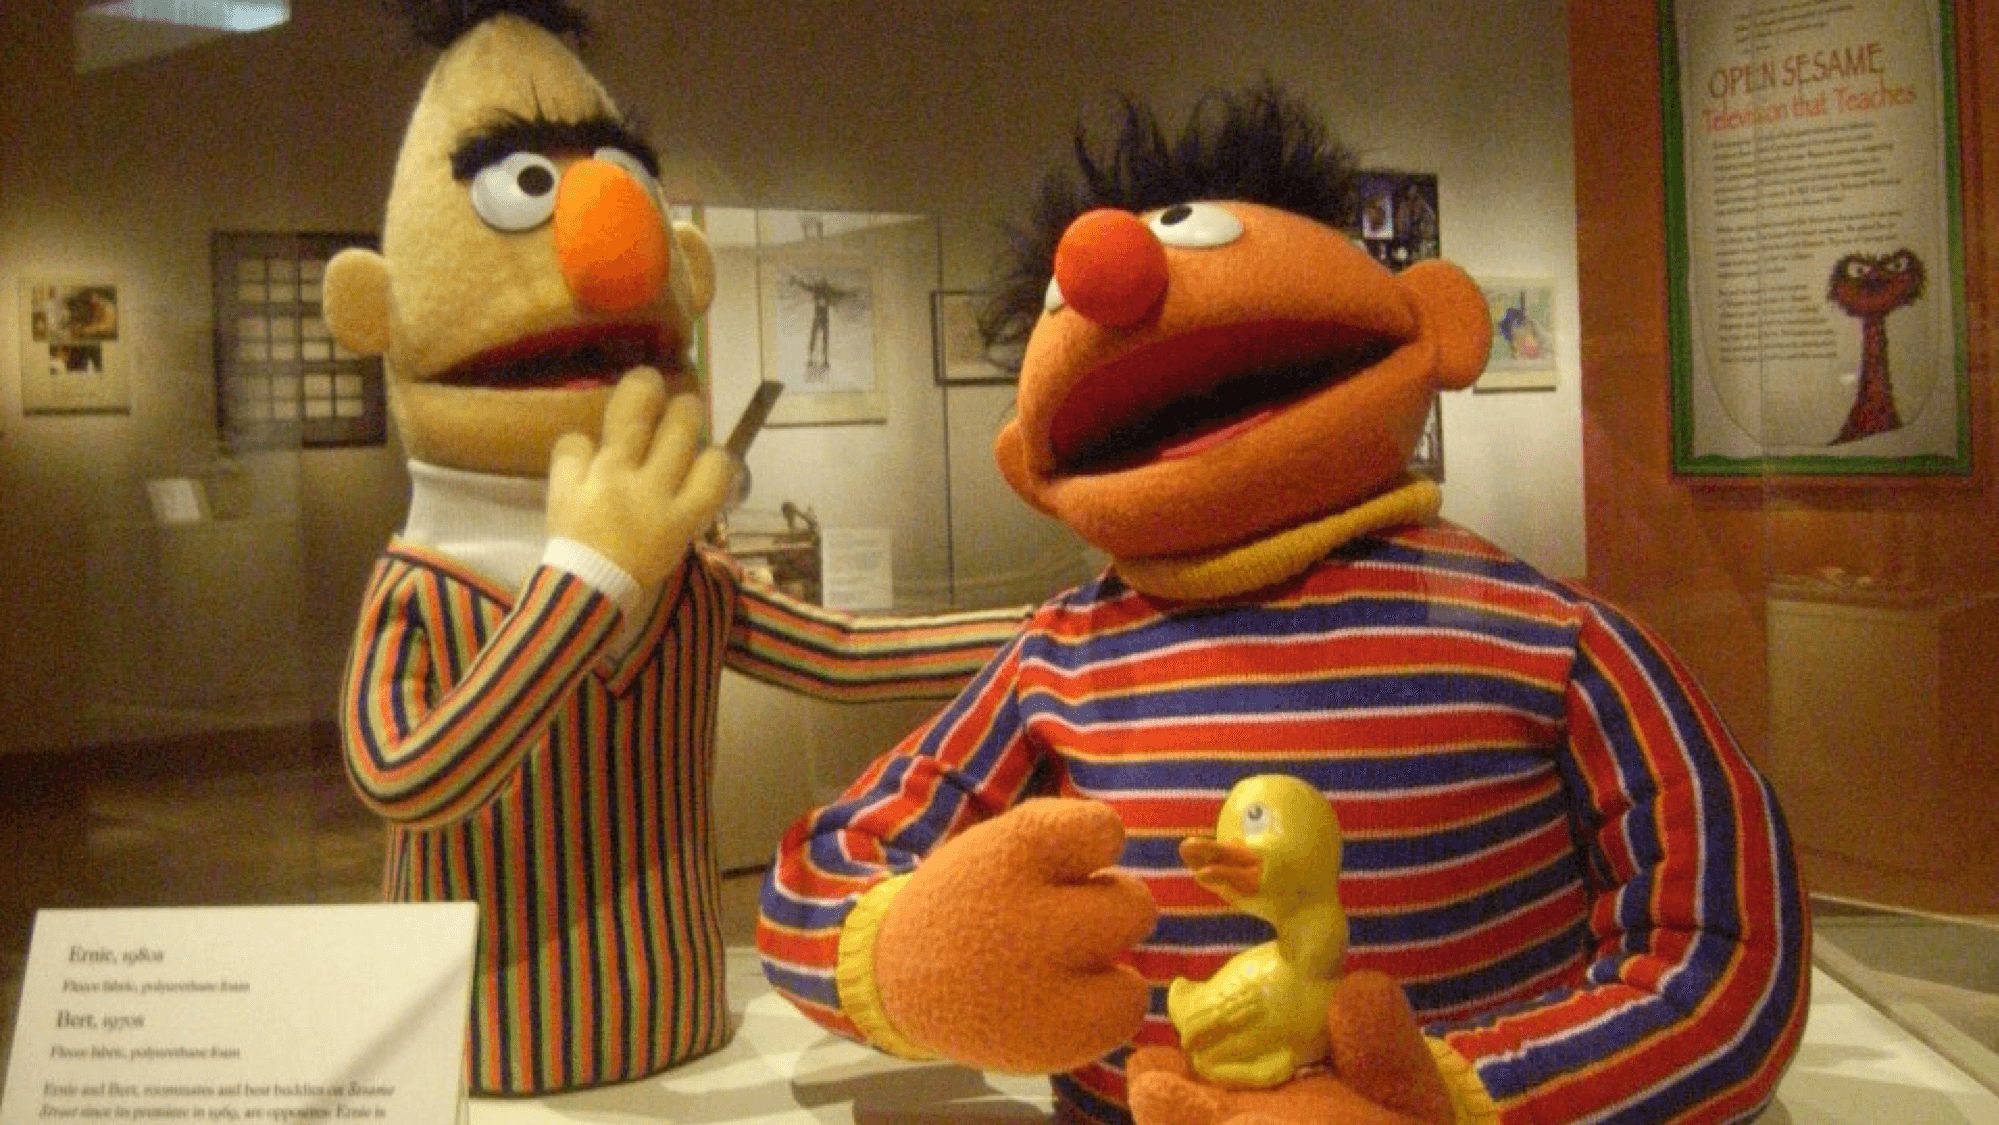
Less than a month after XLNet overtook BERT, the pole position in natural language understanding changed hands again. RoBERTa is an improved BERT pretraining recipe that beats its forbear, becoming the new state-of-the-art language model — for the moment.
Stay updated with weekly AI News and Insights delivered to your inbox