
Datasets
Bias By the Book: Researchers find bias in influential NLP dataset BookCorpus.
Researchers found serious flaws in an influential language dataset, highlighting the need for better documentation of data used in machine learning.

Researchers found serious flaws in an influential language dataset, highlighting the need for better documentation of data used in machine learning.

The U.S. government aims to turbocharge biomedical AI research. The National Institutes of Health, which invests $41.7 billion annually in medical research, announced a program called Bridge to Artificial Intelligence (Bridge2AI) to promote machine learning in human biology and medicine.
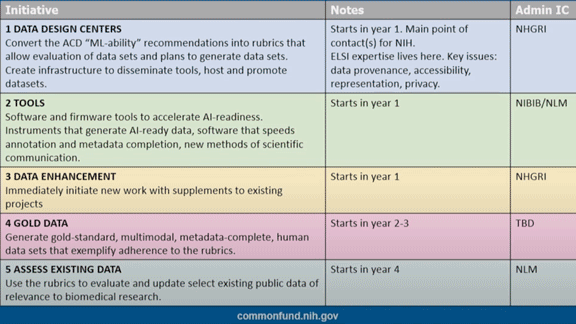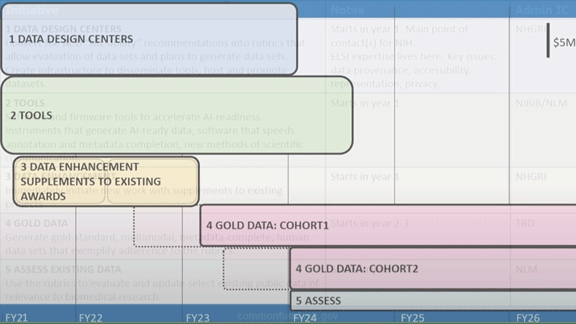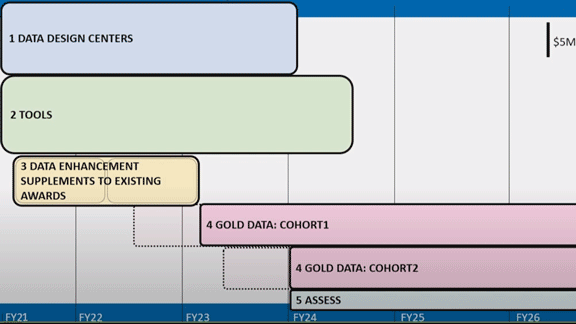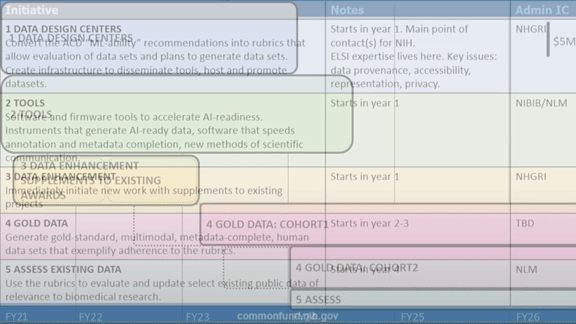
The U.S. government aims to turbocharge biomedical AI research. The National Institutes of Health, which invests $41.7 billion annually in medical research, announced a program called Bridge to Artificial Intelligence (Bridge2AI) to promote machine learning in human biology and medicine.

Key machine learning datasets are riddled with mistakes. Several benchmark datasets are shot through with incorrect labels. On average, 3.4 percent of examples in 10 commonly used datasets are mislabeled and the detrimental impact of such errors rises with model size.
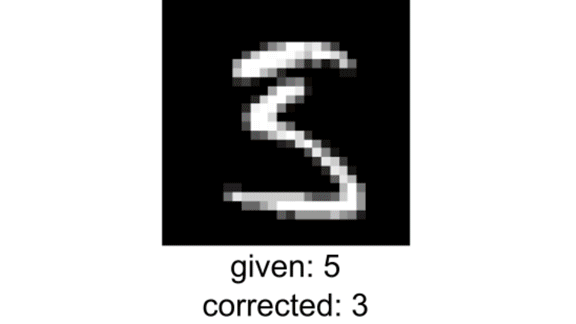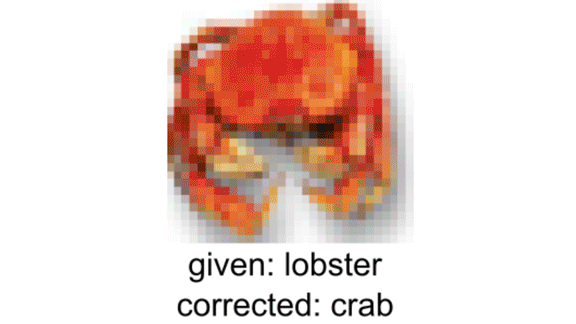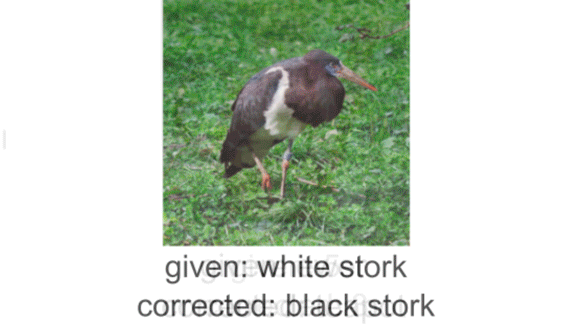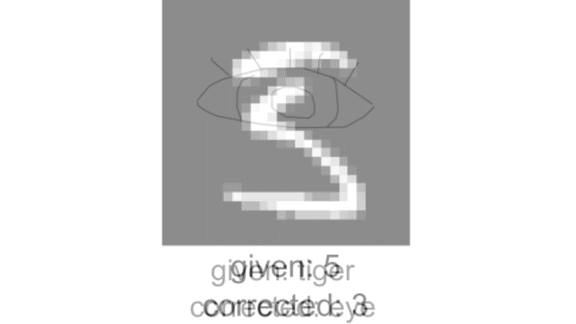
Key machine learning datasets are riddled with mistakes. Several benchmark datasets are shot through with incorrect labels. On average, 3.4 percent of examples in 10 commonly used datasets are mislabeled and the detrimental impact of such errors rises with model size.
ImageNet now comes with privacy protection.What’s new: The team that manages the machine learning community’s go-to image dataset blurred all the human faces pictured in it and tested how models trained on the modified images on a variety of image recognition tasks.
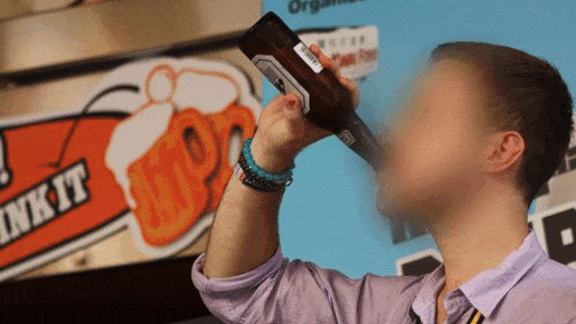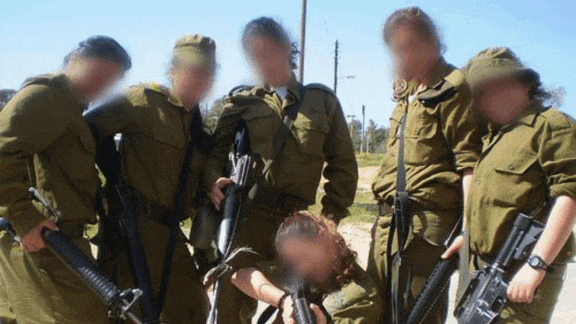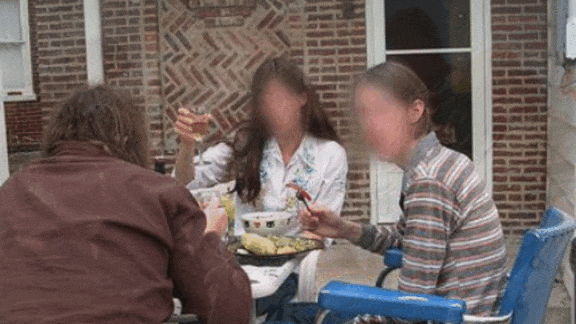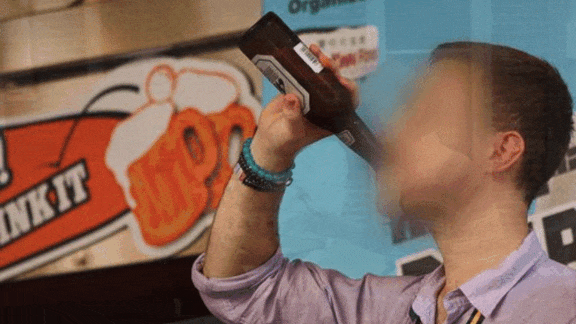
ImageNet now comes with privacy protection.What’s new: The team that manages the machine learning community’s go-to image dataset blurred all the human faces pictured in it and tested how models trained on the modified images on a variety of image recognition tasks.
A new website calls out AI research that may not lend itself to being reproduced. Papers Without Code maintains a directory of AI systems that researchers tried but failed to reproduce.

A new website calls out AI research that may not lend itself to being reproduced. Papers Without Code maintains a directory of AI systems that researchers tried but failed to reproduce.

It’s commonly assumed that models pretrained to achieve high performance on ImageNet will perform better on other visual tasks after fine-tuning. But is it always true? A new study reached surprising conclusions.
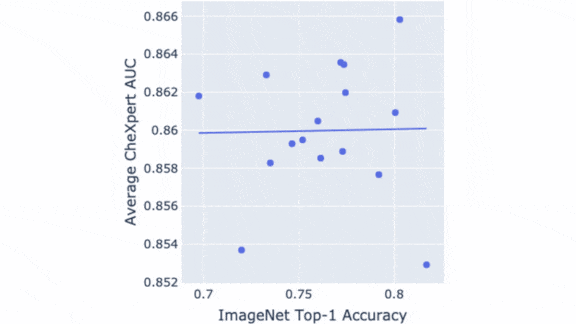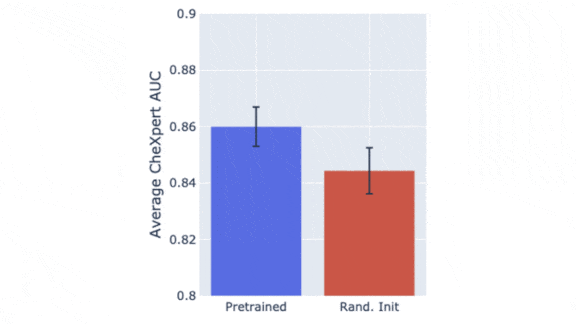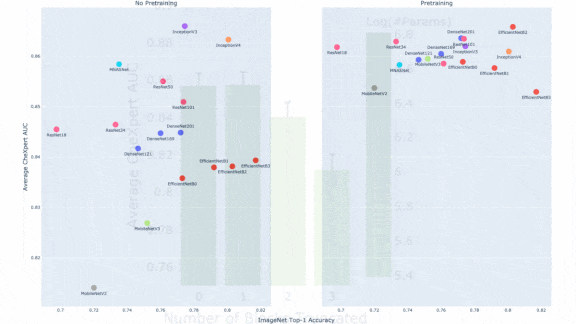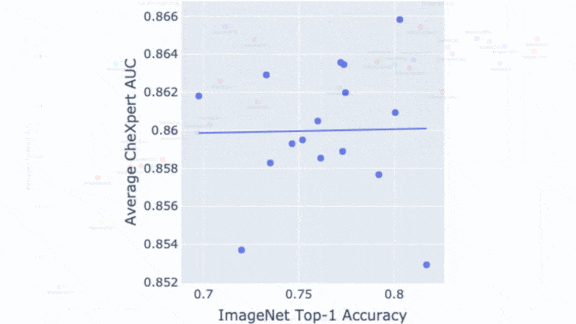
It’s commonly assumed that models pretrained to achieve high performance on ImageNet will perform better on other visual tasks after fine-tuning. But is it always true? A new study reached surprising conclusions.

Datasets for training face recognition models have ballooned in size — while slipping in quality and respect for privacy. In a survey of 130 datasets compiled over the last four decades, researchers traced how the need for increasing quantities of data led researchers to relax their standards.

Datasets for training face recognition models have ballooned in size — while slipping in quality and respect for privacy. In a survey of 130 datasets compiled over the last four decades, researchers traced how the need for increasing quantities of data led researchers to relax their standards.

The same models trained on the same data may show the same performance in the lab, and yet respond very differently to data they haven’t seen before. New work finds this inconsistency to be pervasive.
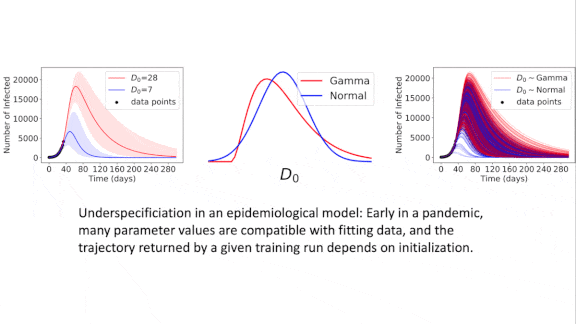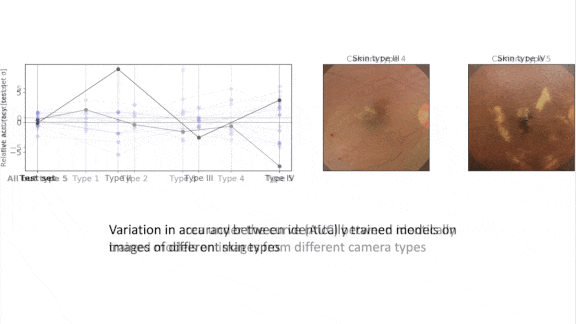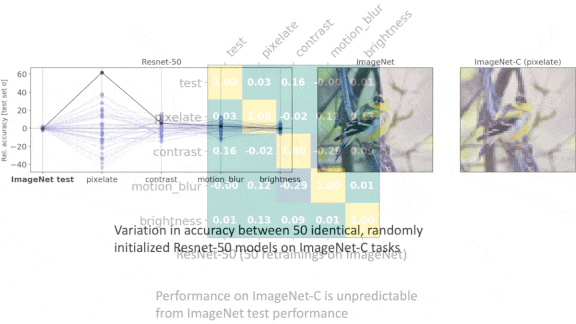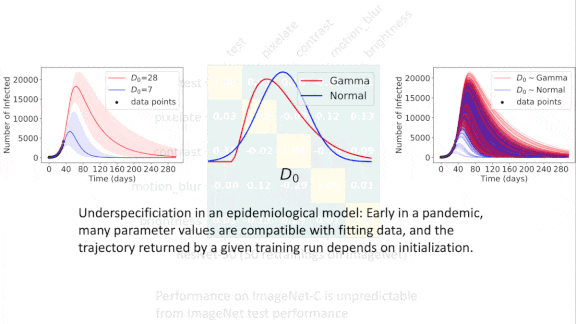
The same models trained on the same data may show the same performance in the lab, and yet respond very differently to data they haven’t seen before. New work finds this inconsistency to be pervasive.
Stay updated with weekly AI News and Insights delivered to your inbox